HugeGraph Architecture Overview
Full-Stack Components
The HugeGraph ecosystem combines a graph database, graph computing engines, graph AI, and a toolchain with distinct responsibilities. HugeGraph Server provides OLTP graph database services; HugeGraph-Computer and Vermeer are independent OLAP engines; HugeGraph-AI provides graph AI capabilities. Toolchain clients, import tools, visualization, and operations tools provide entry points for applications and operators.
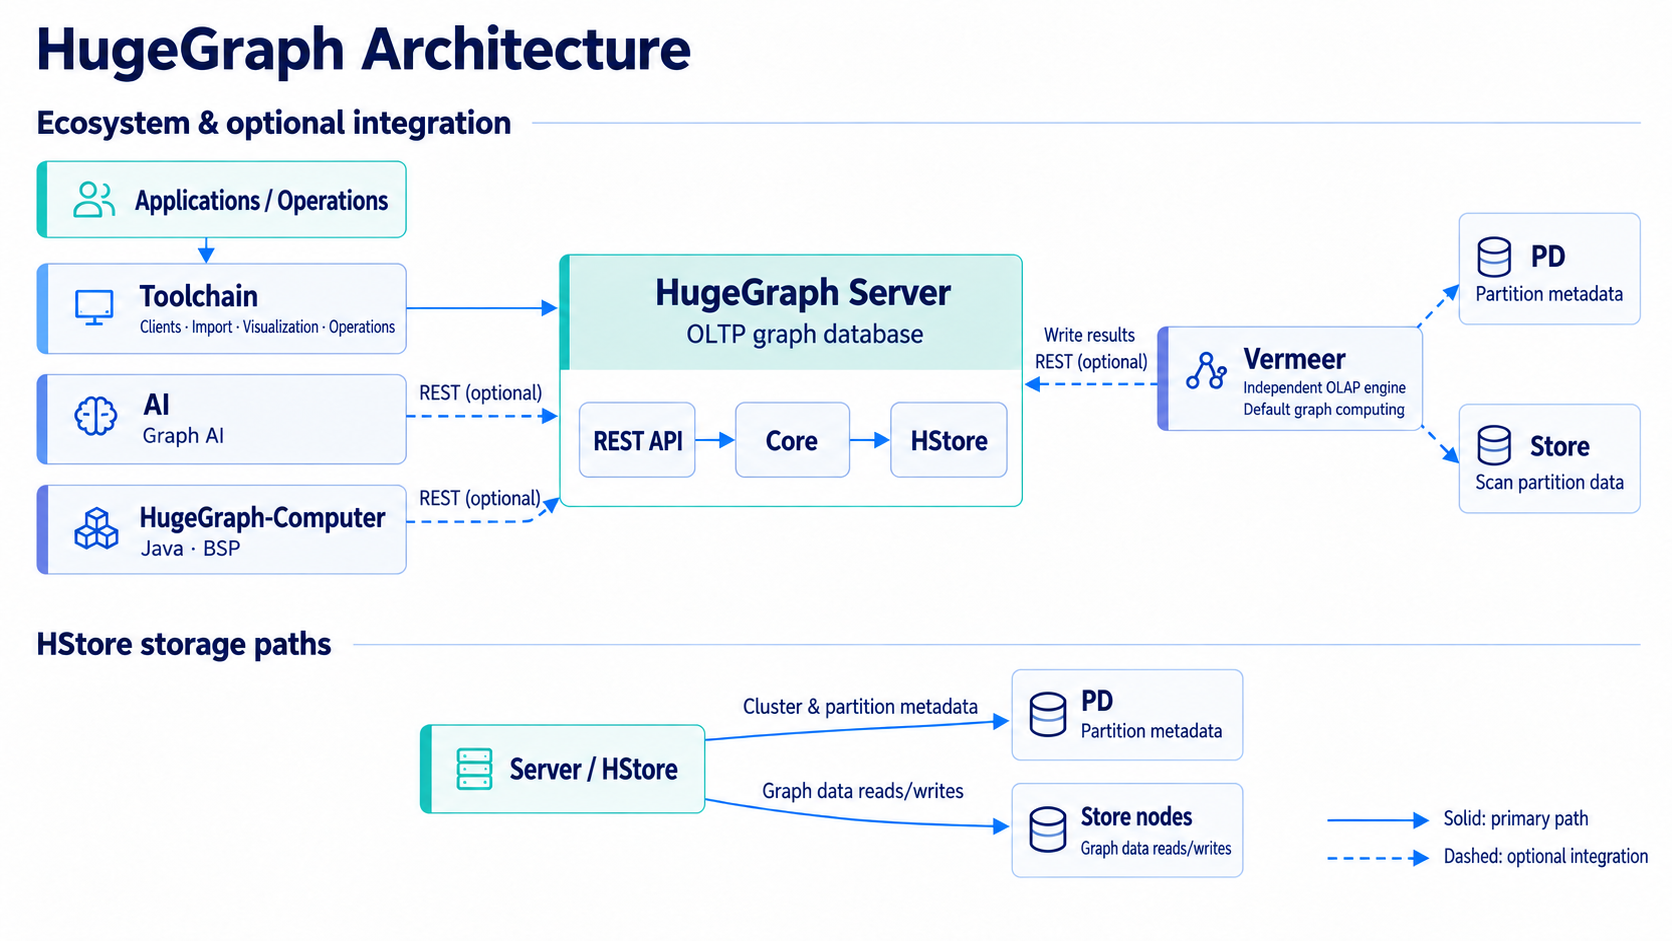
Figure: Server uses HStore as an example backend; see the Mermaid diagram below for independent backends such as RocksDB and HBase. Vermeer and HugeGraph-Computer are independent OLAP engines. Dashed arrows indicate optional integration.
Ecosystem Integration
flowchart TB
  Apps["Applications / Operations"] --> Toolchain["Toolchain"] --> Server["Server REST API"]
  AI["AI"] -. REST .-> Server
  Computer["Computer"] -. REST .-> Server
  Vermeer["Vermeer"] -. PD .-> PD["PD"]
  Vermeer -. Scan .-> Store["Store"]
Vermeer -. Write .-> ServerOptional connections do not mean every AI, Computer, or Vermeer task must connect to Server, PD, or Store. Computer and AI read and write through the Server REST API. Vermeer’s HugeGraph input queries PD for partition metadata and scans HStore partitions directly through Store. With HugeGraph result output, it writes results back through the Server REST API.
Server Internals
flowchart TB
  API["REST API / Gremlin"] --> Core["Core"] --> Adapter["Backend adapter"]
  Adapter --> RocksDB["RocksDB"]
  Adapter --> HBase["HBase"]
  Adapter --> HStore["HStore"]
  HStore --> PD["PD"]
HStore --> Store["Store"]Server REST APIs and Gremlin send requests to Core, which reads and writes through a backend adapter. RocksDB and HBase are independent backends. The HStore adapter obtains cluster metadata and partition information from PD and sends graph operations to Store nodes. PD manages metadata and partitions; it does not carry graph data reads and writes.
Current Server implementations include RocksDB, HBase, HStore, and memory backends. Memory is for testing or temporary use, not a persistent production deployment. See the Server quick start for production deployment options.
Main Toolchain components:
- Hubble — Web visualization and management workspace for schema, imports, and queries.
- Loader — Multi-source batch data import utility for fast bulk loading.
- Tools — CLI operations tool for cluster maintenance, backup, and restore.
- Client — Official programmatic client SDKs available in Java, Python, and Go.
Independent Graph Computing Engines
- Vermeer — High-performance Go in-memory graph computing engine with 15+ OLAP algorithms.
- HugeGraph-Computer — Java distributed graph computing framework based on BSP/Pregel.
Historical Architecture
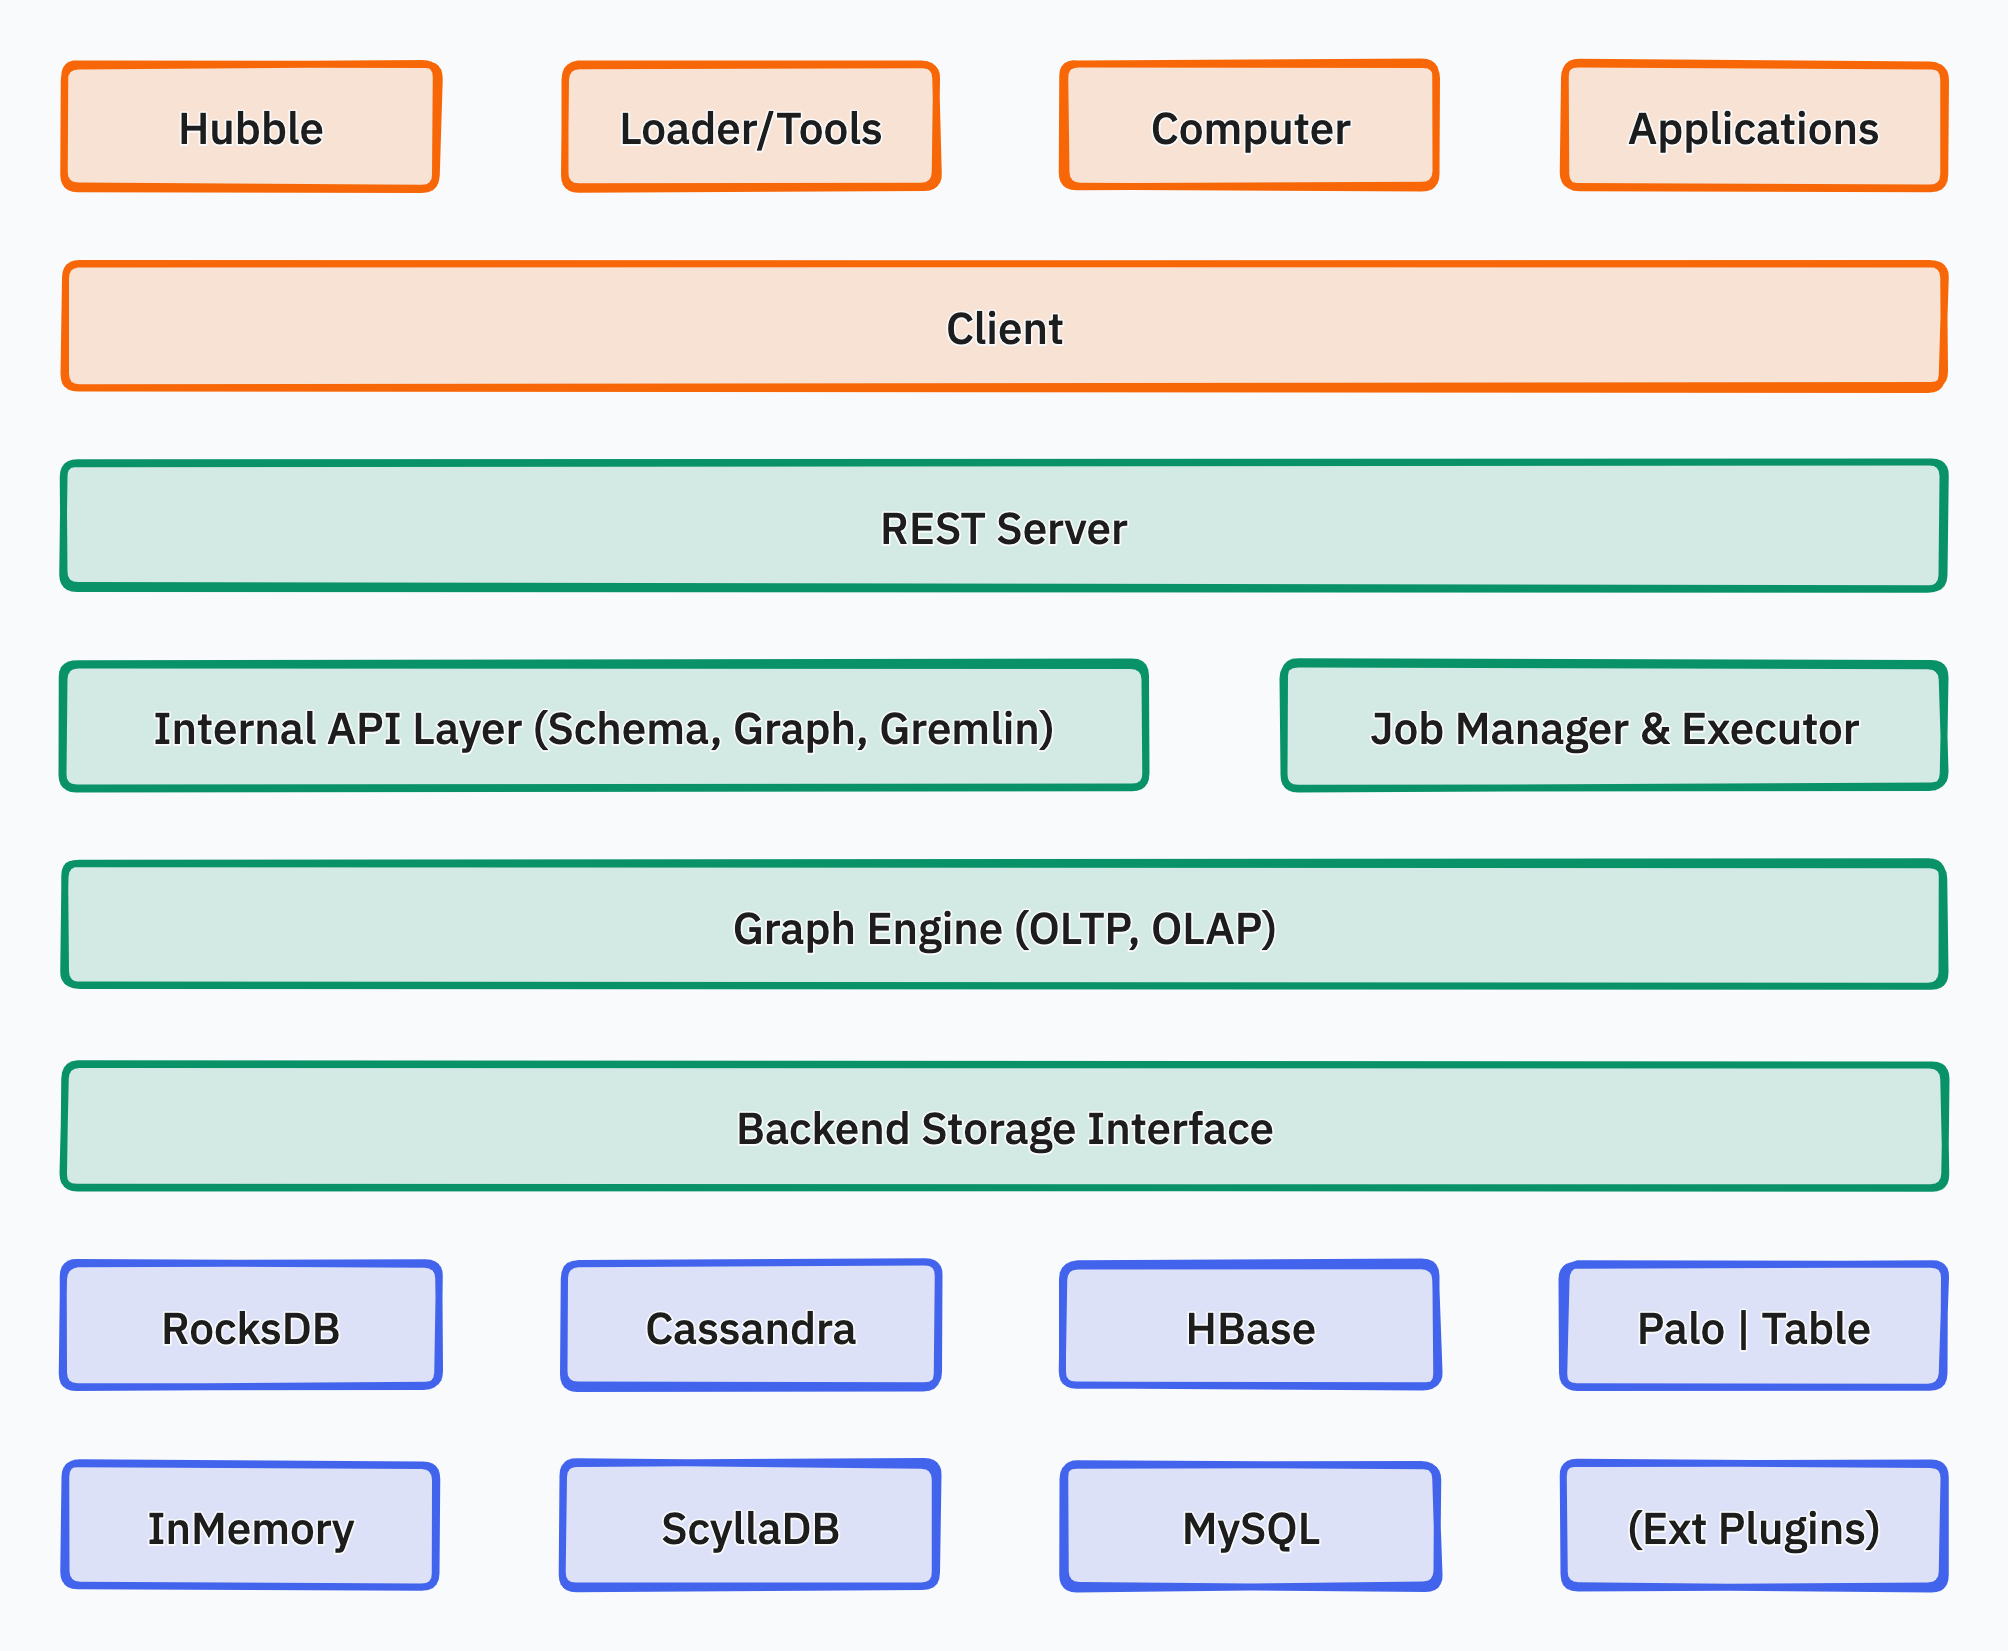
The following diagram is retained for historical reference. Its depiction of Server providing both OLTP and OLAP, and of various old backends, does not describe current master.
Expand the historical architecture diagram
Related Topics
Extension mechanism, SPI registration, and plugin lifecycle in HugeGraph.
Historical background on the property graph model, graph partitioning, and early architecture tradeoffs.