This is the multi-page printable view of this section. .
Documentation
- 1: Apache HugeGraph Introduction
- 2: Download Apache HugeGraph (Incubating)
- 3: Quick Start
- 3.1: HugeGraph (OLTP)
- 3.1.1: HugeGraph Server Quick Start
- 3.1.2: HugeGraph-PD Quick Start
- 3.1.3: HugeGraph-Store Quick Start
- 3.2: HugeGraph ToolChain
- 3.3: HugeGraph-AI
- 3.3.1: HugeGraph-LLM
- 3.3.2: HugeGraph-ML
- 3.3.3: HugeGraph-LLM Workflow
- 3.3.4: Configuration Reference
- 3.3.5: HugeGraph-LLM REST API
- 3.4: HugeGraph Computing (OLAP)
- 3.5: HugeGraph Client
- 3.1: HugeGraph (OLTP)
- 4: HugeGraph-Server Configuration
- 5: Clients and APIs
- 5.1: HugeGraph RESTful API
- 5.1.1: Graphspace API
- 5.1.2: Schema API
- 5.1.3: PropertyKey API
- 5.1.4: VertexLabel API
- 5.1.5: EdgeLabel API
- 5.1.6: IndexLabel API
- 5.1.7: Rebuild API
- 5.1.8: Vertex API
- 5.1.9: Edge API
- 5.1.10: Traverser API
- 5.1.11: Rank API
- 5.1.12: Variable API
- 5.1.13: Graphs API
- 5.1.14: Task API
- 5.1.15: Gremlin API
- 5.1.16: Cypher API
- 5.1.17: Authentication API
- 5.1.18: Metrics API
- 5.1.19: Other API
- 5.2: HugeGraph Java Client
- 5.3: Gremlin-Console
- 5.1: HugeGraph RESTful API
- 6: GUIDES
- 7: Query Languages
- 7.1: HugeGraph Gremlin
- 7.2: HugeGraph Examples
- 8: PERFORMANCE
- 9: Contribution Guidelines
- 10: CHANGELOGS
- 11: Apache Contributor Agreements
Apache HugeGraph Documentation
Apache HugeGraph includes graph database, graph computing, and graph AI components. The HugeGraph core engine manages property graphs, transactions, and real-time queries; Computer and Vermeer run graph algorithms; and HugeGraph-AI provides GraphRAG, graph machine learning, and a Python client.
Quick Navigation by Scenario
| I want to… | Start here |
|---|---|
| Run graph queries (OLTP) | HugeGraph Server Quickstart |
| Large-scale graph computing (OLAP) | Graph Computing Engine |
| Build Graph + AI applications | HugeGraph-AI |
| Batch import data | HugeGraph Loader |
| Visualize and manage graphs | Hubble Web UI |
Ecosystem Overview
Core Components
- HugeGraph Core Engine (OLTP): Exposes REST APIs through HugeGraph Server and supports Gremlin and Cypher queries
- HugeGraph Toolchain: Includes Java/Go clients, Loader, Hubble, Spark Connector, and Tools; the Python client is maintained in HugeGraph-AI, and a Rust client is under development
- HugeGraph Computer: Contains the distributed Computer engine and the in-memory Vermeer engine
- HugeGraph-AI: Includes GraphRAG, graph machine learning, the Python client, and the Vermeer Python client
Deployment Modes
| Mode | Core Components | Suitable Scenarios | Data Scale |
|---|---|---|---|
| Standalone | Server + RocksDB | Development, testing, and small to medium-scale data | ≤ 2 TB |
| Distributed | Server + PD + Store (HStore) | Production, horizontal scaling, and multi-replica deployment | ≤ 1 PB |
See the system introduction and the corresponding quick-start guides for each component’s scope and startup instructions.
1 - Apache HugeGraph Introduction
What Is Apache HugeGraph?
Apache HugeGraph is an easy-to-use, efficient, general-purpose open-source full-stack graph system (GitHub). It covers three major areas: graph databases (OLTP real-time queries), graph computing (OLAP large-scale analysis), and graph AI (GraphRAG and graph machine learning).
HugeGraph supports fast storage and queries for tens of billions of vertices and edges, with strong OLTP performance. Its graph engine is compatible with Apache TinkerPop 3 and supports both Gremlin and Cypher (the OpenCypher standard).
Typical use cases: deep relationship exploration, association analysis, path search, feature extraction, community detection, and knowledge graphs. Application areas: network security, telecom anti-fraud, financial risk control, advertising and recommendations, social networks, and intelligent Q&A.
Ecosystem Overview
HugeGraph Server (OLTP Graph Engine)
HugeGraph Server is the OLTP engine and service entry point for the graph database. It handles property graph modeling, transaction processing, query execution, and API access. Graph data is stored in the configured RocksDB, HStore, or HBase backend.
- Property graph and schema: Manages VertexLabel, EdgeLabel, PropertyKey, and IndexLabel definitions
- Query languages: Supports Gremlin (TinkerPop 3) and Cypher (OpenCypher)
- REST API: Provides endpoints for schemas, graph data, queries, tasks, and operations
- Indexes and queries: Supports exact, range, and compound-condition queries
- Storage backends: Versions 1.7.0 through
masterprimarily support RocksDB (standalone), HStore (distributed), and HBase
The main modules include hugegraph-core, the storage backend modules, and hugegraph-api. Core implements the graph model, transactions, and query logic; backend modules connect to specific storage systems; and the API module provides HTTP access. Current REST resource paths include the graph space and graph name, for example:
Standalone deployments commonly use RocksDB. Distributed deployments use HStore: PD manages cluster metadata and partition scheduling, while Store persists graph data and replicas. HBase can be used as a separate storage backend.
HugeGraph Toolchain
HugeGraph Toolchain provides clients, data import, visual management, Spark integration, and command-line operations. Together, these tools cover the main stages of a graph application’s lifecycle, from data ingestion to routine management.
| Module | Purpose |
|---|---|
| Client | Wraps schema management, graph data reads and writes, Gremlin, and Traverser APIs; supports Java, Python, and Go, with a Rust client under development |
| Loader | Reads data from local files, HDFS, JDBC, Kafka, or another graph, converts it into vertices and edges, and imports it into HugeGraph in batches |
| Hubble | Provides a web management interface for graph connections, schemas, data import, Gremlin queries, and visual results |
| Spark Connector | Reads and writes HugeGraph data in Spark jobs for offline big-data processing |
| Tools | Provides command-line operations for deployment, graph management, backup and restore, and Gremlin execution |
Graph Computing Engines (OLAP)
The HugeGraph-Computer repository provides two complementary OLAP graph computing engines:
- Vermeer: Written in Go, it uses a master-worker architecture and primarily performs in-memory computation. It provides REST APIs, gRPC, and a web UI, and is suitable for fast small- and medium-scale graph analysis.
- Computer: Written in Java, it implements the distributed BSP/Pregel computing model and can run on Kubernetes, YARN, or local processes. It can spill data to disk when memory thresholds are exceeded and is suitable for larger graph computing workloads.
Both engines can read HugeGraph data, but their runtime architectures, resource requirements, configuration, and algorithm interfaces differ.
HugeGraph-AI (Graph + AI)
HugeGraph-AI connects graph technology with large language models and graph machine learning frameworks. The repository uses Python 3.10 or later and manages its workspace with uv. Its main modules are:
- hugegraph-llm: Provides GraphRAG, knowledge graph construction, natural-language queries, and Text2Gremlin
- hugegraph-ml: Provides models for node classification, graph classification, graph embeddings, link prediction, and fraud detection
- hugegraph-python-client: Manages schemas, graph data, and Gremlin queries from Python
- vermeer-python-client: Calls Vermeer graph computing services from Python
Deployment Modes
| Mode | Core Components | Suitable Scenarios | Data Scale |
|---|---|---|---|
| Standalone (OLTP) | Server + RocksDB | Development, testing, and small to medium-scale data | ≤ 2 TB |
| Distributed (OLTP) | Server + PD + Store (HStore) | Production, horizontal scaling, and multi-replica deployment | ≤ 1 PB |
Graph computing is an OLAP workload. Its capacity and resource requirements depend on the selected engine, graph structure, and algorithm, and do not use the OLTP storage capacity figures above.
Where to Start
| Goal | Documentation |
|---|---|
| Start the graph database and run queries | Server Quick Start |
| Import data in batches | Loader |
| Manage graphs through a web interface | Hubble |
| Run graph algorithms | Vermeer and Computer |
| Build GraphRAG or graph machine learning applications | HugeGraph-AI |
Community
- GitHub Issues
- Developer mailing list: dev@hugegraph.apache.org
- How to subscribe to the mailing list
- Security reports: security@hugegraph.apache.org
- WeChat public account: Apache HugeGraph
1.1 - Introduction with HugeGraph
Summary
Apache HugeGraph is an easy-to-use, efficient, general-purpose open-source graph database system (Graph Database, GitHub project address), implementing the Apache TinkerPop3 framework and fully compatible with the Gremlin query language, With complete toolchain components, it helps users easily build applications and products based on graph databases. HugeGraph supports fast import of more than 10 billion vertices and edges, and provides millisecond-level relational query capability (OLTP). It also supports large-scale distributed graph computing (OLAP).
Typical application scenarios of HugeGraph include deep relationship exploration, association analysis, path search, feature extraction, data clustering, community detection, knowledge graph, etc., and are applicable to business fields such as network security, telecommunication fraud, financial risk control, advertising recommendation, social network, and intelligence Robots, etc.
Features
HugeGraph supports graph operations in online and offline environments, batch importing of data and efficient complex relationship analysis. It can seamlessly be integrated with big data platforms. HugeGraph supports multi-user parallel operations. Users can enter Gremlin query statements and get graph query results in time. They can also call the HugeGraph API in user programs for graph analysis or queries.
This system has the following features:
- Ease of use: HugeGraph supports the Gremlin graph query language and a RESTful API, providing common interfaces for graph retrieval, and peripheral tools with complete functions to easily implement various graph-based query and analysis operations.
- Efficiency: HugeGraph has been deeply optimized in graph storage and graph computing, and provides a variety of batch import tools, which can easily complete the rapid import of tens of billions of data, and achieve millisecond-level response for graph retrieval through optimized queries. Supports simultaneous online real-time operations of thousands of users.
- Universal: HugeGraph supports the Apache Gremlin standard graph query language and the Property Graph standard graph modeling method, and supports graph-based OLTP and OLAP schemes. Integrate Apache Hadoop and Apache Spark big data platforms.
- Scalable: supports distributed storage, multiple copies of data, and horizontal expansion, built-in multiple back-end storage engines, and can easily expand the back-end storage engine through plug-ins.
- Open: HugeGraph code is open source (Apache 2 License), customers can modify and customize independently, and selectively give back to the open-source community.
The functions of this system include but are not limited to:
- Supports batch import of data from multiple data sources (including local files, HDFS files, MySQL databases, and other data sources), and supports import of multiple file formats (including TXT, CSV, JSON, and other formats)
- With a visual operation interface, it can be used for operation, analysis, and display diagrams, reducing the threshold for users to use
- Optimized graph interface: shortest path (Shortest Path), K-step connected subgraph (K-neighbor), K-step to reach the adjacent point (K-out), personalized recommendation algorithm PersonalRank, etc.
- Implemented based on the Apache TinkerPop3 framework, supports Gremlin graph query language
- Support attribute graph, attributes can be added to vertices and edges, and support rich attribute types
- Has independent schema metadata information, has powerful graph modeling capabilities, and facilitates third-party system integration
- Support multi-vertex ID strategy: support primary key ID, support automatic ID generation, support user-defined string ID, support user-defined digital ID
- The attributes of edges and vertices can be indexed to support precise query, range query, and full-text search
- The storage system adopts a plug-in method, supporting RocksDB (standalone/cluster), Cassandra, ScyllaDB, HBase, MySQL, PostgreSQL, Palo and Memory, etc.
- Integrated with big data systems such as HDFS, Spark/Flink, GraphX, etc., supports BulkLoad operation to import massive data.
- Supports HA(high availability), multiple data replicas, backup and recovery, monitoring, distributed Trace, etc.
Modules
- [HugeGraph-Store]: HugeGraph-Store is a distributed storage engine to manage large-scale graph data by integrating storage and computation within a unified system.
- [HugeGraph-PD]: HugeGraph-PD (Placement Driver) manages metadata and coordinates storage nodes.
- HugeGraph-Server: HugeGraph-Server is the core part of the HugeGraph project, containing Core, Backend, API and other submodules;
- Core: Implements the graph engine, connects to the Backend module downwards, and supports the API module upwards;
- Backend: Implements the storage of graph data to the backend, supports backends including Memory, Cassandra, ScyllaDB, RocksDB, HBase, MySQL and PostgreSQL, users can choose one according to the actual situation;
- API: Built-in REST Server provides RESTful API to users and is fully compatible with Gremlin queries. (Supports distributed storage and computation pushdown)
- HugeGraph-Toolchain: (Toolchain)
- HugeGraph-Client: HugeGraph-Client provides a RESTful API client for connecting to HugeGraph-Server, currently only the Java version is implemented, users of other languages can implement it themselves;
- HugeGraph-Loader: HugeGraph-Loader is a data import tool based on HugeGraph-Client, which transforms ordinary text data into vertices and edges of the graph and inserts them into the graph database;
- HugeGraph-Hubble: HugeGraph-Hubble is HugeGraph’s Web visualization management platform, a one-stop visualization analysis platform, the platform covers the whole process from data modeling, to fast data import, to online and offline analysis of data, and unified management of the graph;
- HugeGraph-Tools: HugeGraph-Tools is HugeGraph’s deployment and management tool, including graph management, backup/recovery, Gremlin execution and other functions.
- HugeGraph-Computer: HugeGraph-Computer is a distributed graph processing system (OLAP). It is an implementation of Pregel. It can run on clusters such as Kubernetes/Yarn, and supports large-scale graph computing.
- HugeGraph-AI: HugeGraph-AI is HugeGraph’s independent AI component, providing training and inference functions of graph neural networks, LLM/Graph RAG combination/Python-Client and other related components, continuously updating.
Contact Us
- GitHub Issues: Feedback on usage issues and functional requirements (quick response)
- Feedback Email: dev@hugegraph.apache.org (subscriber only)
- Security Email: security@hugegraph.apache.org (Report SEC problems)
- WeChat public account: Apache HugeGraph, welcome to scan this QR code to follow us.
{width=“300” height=“94”}
2 - Download Apache HugeGraph (Incubating)
Instructions:
- It is recommended to use the latest version of the HugeGraph software package. Please select Java11 for the runtime environment.
- To verify downloads, use the corresponding hash (SHA512), signature, and Project Signature Verification KEYS.
- Instructions for checking hash (SHA512) and signatures are on the Validate Release page, and you can also refer to ASF official instructions.
- Note: The version numbers of all components of HugeGraph have been kept consistent, and the version numbers of Maven repositories such as
client/loader/hubble/commonare the same. You can refer to these for dependency references maven example.
Latest Version 1.7.0
- Release Date: 2025-11-28
- Release Notes
Binary Packages
Source Packages
Please refer to build from source.
| Server | Toolchain | AI | Computer |
|---|---|---|---|
| [Source] [Sign] [SHA512] | [Source] [Sign] [SHA512] | [Source] [Sign] [SHA512] | [Source] [Sign] [SHA512] |
Archived Versions
Note:
1.3.0is the last major version compatible with Java8, please switch to or migrate to Java11 as soon as possible (lower versions of Java have potentially more SEC risks and performance impacts). Starting from version1.5.0, a Java11 runtime environment is required.
1.5.0
- Release Date: 2024-12-10
- Release Notes
Binary Packages
Source Packages
| Server | Toolchain | AI | Computer |
|---|---|---|---|
| [Source] [Sign] [SHA512] | [Source] [Sign] [SHA512] | [Source] [Sign] [SHA512] | [Source] [Sign] [SHA512] |
1.3.0
- Release Date: 2024-04-01
- Release Notes
Binary Packages
Source Packages
| Server | Toolchain | AI | Common |
|---|---|---|---|
| [Source] [Sign] [SHA512] | [Source] [Sign] [SHA512] | [Source] [Sign] [SHA512] | [Source] [Sign] [SHA512] |
1.2.0
- Release Date: 2023-12-28
- Release Notes
Binary Packages
Source Packages
| Server | Toolchain | Computer | Common |
|---|---|---|---|
| [Source] [Sign] [SHA512] | [Source] [Sign] [SHA512] | [Source] [Sign] [SHA512] | [Source] [Sign] [SHA512] |
1.0.0
- Release Date: 2023-02-22
- Release Notes
Binary Packages
Source Packages
3 - Quick Start
Choose the quick-start guide for Server, Toolchain, graph computing, or HugeGraph-AI according to your needs. Each component is released independently, so check the runtime requirements and version of the corresponding repository before installation.
3.1 - HugeGraph (OLTP)
🚀 Best practice: Prioritize using DeepWiki intelligent documents
To address the issue of outdated static documents, we provide DeepWiki with real-time updates and more comprehensive content. It is equivalent to an expert with the latest knowledge of the project, which is very suitable for all developers to read and consult before starting the project.
👉 Strongly recommend visiting and having a conversation with: incubator-hugegraph
3.1.1 - HugeGraph Server Quick Start
1 HugeGraph Server Overview
apache/hugegraph is the main repository for the HugeGraph graph database. Its top-level modules include hugegraph-server, hugegraph-pd, and hugegraph-store. This page describes the hugegraph-server module and the service it runs.
The hugegraph-server module contains hugegraph-core, hugegraph-api, hugegraph-dist, and storage adapters. Core implements the property graph model, transactions, and TinkerPop interfaces. API provides the HTTP service and delegates client requests to Core. Graph data is stored in RocksDB (the default standalone backend), HStore (distributed), or HBase.
⚠️ Version note: This page follows HugeGraph 1.7.0 through the
masterbranch and covers only RocksDB, HStore, and HBase. For other legacy backends and their configuration, see the HugeGraph 1.5.x documentation.
Naming:
HugeGraphmeans the overall project or main repository,hugegraph-serveris the Server module in that repository, andHugeGraphServeris the Java class for the service process. This page uses “Server service” for a running graph database service.
2 Dependency for Building/Running
2.1 Install Java 11 (JDK 11)
The hugegraph-server module in HugeGraph 1.7.0 is compiled with Java 11. Running and building it from source require Java 11 or later.
Before continuing, run java -version to confirm your JDK version.
Java 8 is no longer supported starting from 1.7.0.
3 Deploy
There are four ways to deploy the Server service:
- Method 1: Use Docker container (Convenient for Test/Dev)
- Method 2: Download the binary tarball
- Method 3: Source code compilation
- Method 4: One-click deployment
Do not expose Gremlin, Cypher, or other query endpoints directly to the public Internet. In production, enable authentication and authorization, restrict network access, and retain audit logs. See the Security Guide for deployment guidance.
3.1 Use Docker container (Convenient for Test/Dev)
You can refer to the Docker deployment guide.
You can use docker run -itd --name=server -p 8080:8080 -e PASSWORD=xxx hugegraph/hugegraph:1.7.0 to quickly start a Server instance using the RocksDB backend.
Optional:
- You can use
docker exec -it server bashto enter the container for troubleshooting or other maintenance operations. - You can use
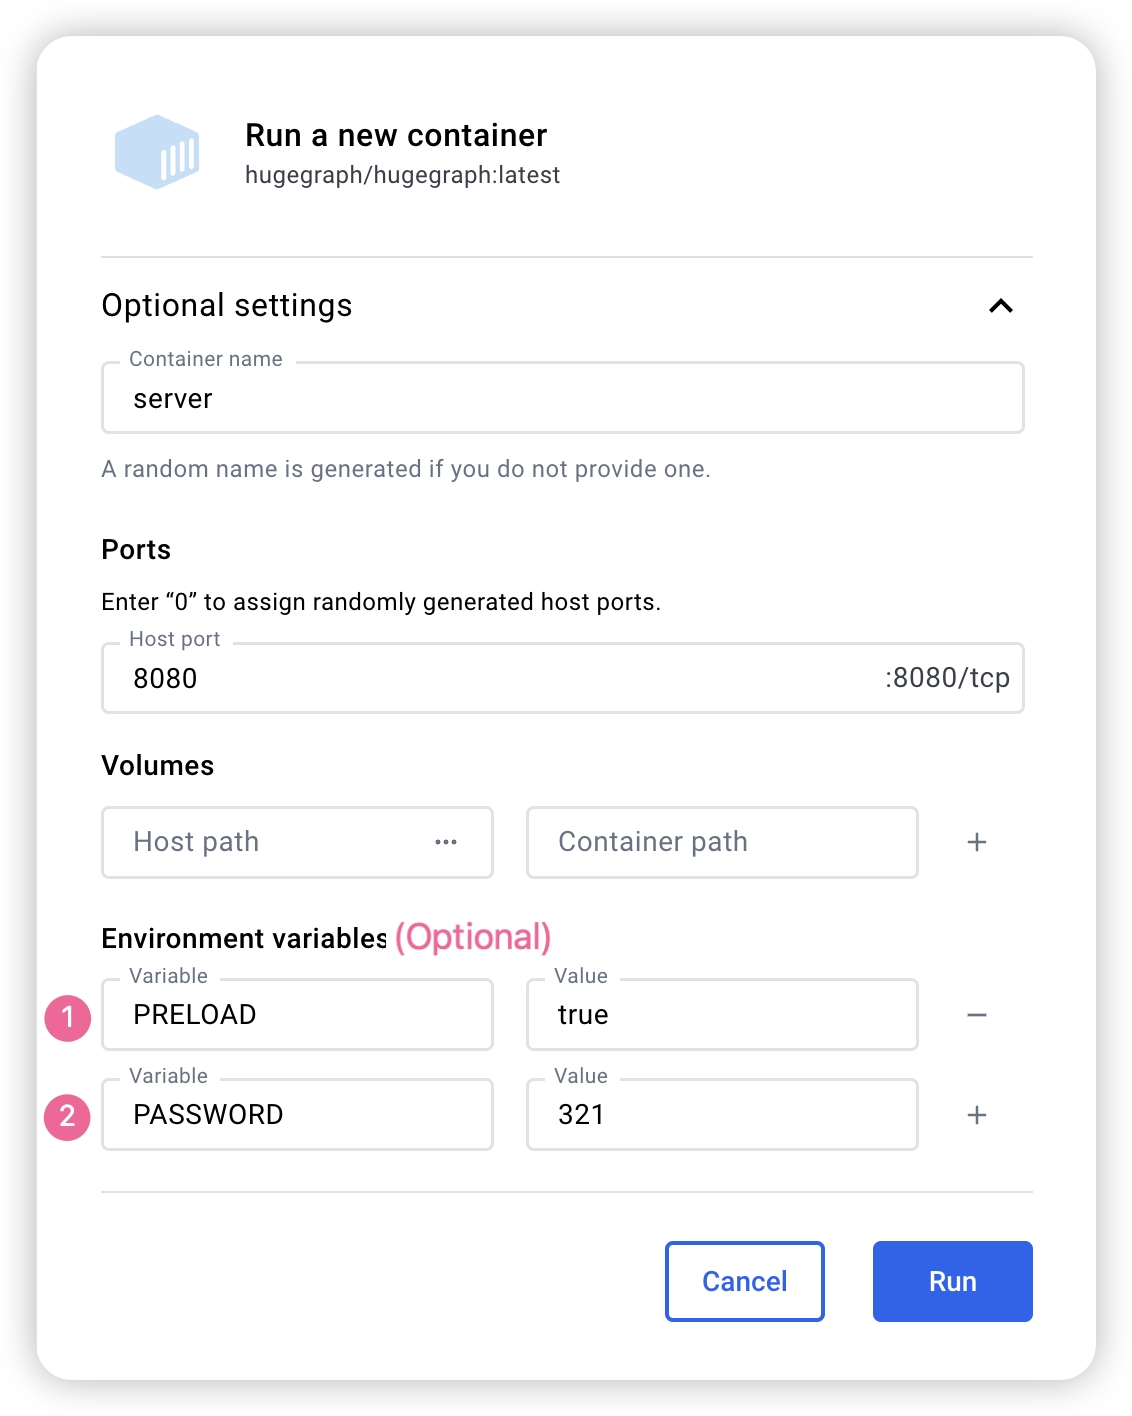
docker run -itd --name=server -p 8080:8080 -e PRELOAD="true" hugegraph/hugegraph:1.7.0to preload a built-in sample graph at startup. You can verify it through theRESTful API. See 5.1.4 for details. - You can use
-e PASSWORD=xxxto enable authentication mode and set the admin password. See Config Authentication for details.
If you use Docker Desktop, you can set the options as follows:
Note: The Docker Compose files use bridge networking (
hg-net) and work on Linux and Mac (Docker Desktop). For the 3-node distributed cluster on Mac (Docker Desktop), allocate at least 12 GB of memory (Settings → Resources → Memory). On Linux, Docker uses host memory directly.
If you want a single, unified setup for multiple HugeGraph services, you can use docker compose.
Two compose files are available in the docker/ directory:
- Single-node quickstart (pre-built images):
docker/docker-compose.yml - Single-node dev build (build from source):
docker/docker-compose.dev.yml
To enable authentication, add PASSWORD=xxx to the service environment in the compose file or pass -e PASSWORD=xxx to docker run.
See docker/README.md for the full setup guide.
Note:
HugeGraph Docker images are provided as a convenient way to start HugeGraph quickly, but they are not official ASF distribution artifacts. You can find more details in the ASF Release Distribution Policy.
We recommend using a release tag (such as
1.7.0or1.x.0) for stable deployments. Use thelatesttag only if you want the newest features still under development.
3.2 Download the binary tarball
You could download the binary tarball from the download page of the ASF site like this:
3.3 Source code compilation
Please ensure that the wget/curl commands are installed before compiling the source code
Download HugeGraph source code in either of the following 2 ways (so as the other HugeGraph repos/modules):
- download the stable/release version from the ASF site
- clone the unstable/latest version by GitBox(ASF) or GitHub
Compile and generate tarball
A successful build includes the following line:
After a successful build, the generated distribution is the *hugegraph-*.tar.gz file in the repository root.
3.4 One-click deployment (Outdated)
HugeGraph-Tools provides a one-click deployment command that downloads, extracts, configures, and starts the Server service and HugeGraph-Hubble. These tools are included in the HugeGraph-Toolchain distribution.
Of course, you should download the tarball of HugeGraph-Toolchain first.
note:
${version}is the version, The latest version can refer to Download Page, or click the link to download directly from the Download page
The general entry script for HugeGraph-Tools is bin/hugegraph, Users can use the help command to view its usage, here only the commands for one-click deployment are introduced.
{hugegraph-version} is the Server service and HugeGraphStudio version; see conf/version-mapping.yaml for supported mappings. {install-path} is the installation directory, while {download-path-prefix} optionally overrides the tarball download location. For example, deploy version 0.6 with bin/hugegraph deploy -v 0.6 -p services.
4 Config
If you need to quickly start HugeGraph just for testing, then you only need to modify a few configuration items (see next section). For detailed configuration introduction, please refer to configuration document and introduction to configuration items
5 Startup
5.1 Use a startup script to startup
Startup is divided into “first startup” and “non-first startup”. On the first startup, you need to initialize the backend database before starting the service.
If the service was stopped manually, or needs to be started again for any other reason, you can usually start it directly because the backend database is persistent.
When HugeGraphServer starts, it connects to the backend storage and checks its version information. If the backend has not been initialized, or if it was initialized with an incompatible version (for example, old-version data), HugeGraphServer will fail to start and report an error.
If you need to access HugeGraphServer externally, modify the restserver.url configuration item in rest-server.properties (the default is http://127.0.0.1:8080) and change it to the machine name or IP address.
Since the configuration (hugegraph.properties) and startup steps required by various backends are slightly different, the following will introduce the configuration and startup of each backend one by one.
Note: Configure Server Authentication before starting HugeGraphServer if you need Auth mode (especially for production or public network environments).
5.1.1 Distributed Storage (HStore)
Distributed storage is a new feature introduced after HugeGraph 1.5.0, which implements distributed data storage and computation based on HugeGraph-PD and HugeGraph-Store components.
To use the distributed storage engine, you need to deploy HugeGraph-PD and HugeGraph-Store first. See HugeGraph-PD Quick Start and HugeGraph-Store Quick Start.
After ensuring that both PD and Store services are started, modify the hugegraph.properties configuration of HugeGraph-Server:
Then enable PD discovery in rest-server.properties (required for every HugeGraph-Server node):
If configuring multiple HugeGraph-Server nodes, you need to modify the rest-server.properties configuration file for each node, for example:
Node 1 (Master node):
Node 2 (Worker node):
Also, you need to modify the port configuration in gremlin-server.yaml for each node:
Node 1:
Node 2:
Initialize the database:
Start the Server:
The startup sequence for using the distributed storage engine is:
- Start HugeGraph-PD
- Start HugeGraph-Store
- Initialize the database (only for the first time)
- Start HugeGraph-Server
Verify that the service is started properly:
The sequence to stop the services should be the reverse of the startup sequence:
- Stop HugeGraph-Server
- Stop HugeGraph-Store
- Stop HugeGraph-PD
Docker Distributed Cluster
Run the full distributed cluster (3 PD + 3 Store + 3 Server) with Docker Compose:
Services communicate via container hostnames on the hg-net bridge network. Configuration is injected via environment variables:
Verify the cluster:
To view runtime logs for any container use docker logs <container-name> (e.g. docker logs hg-pd0).
See docker/README.md for the full environment variable reference, port table, and troubleshooting guide.
5.1.2 RocksDB / ToplingDB
RocksDB is an embedded database that does not require manual installation and deployment. GCC version >= 4.3.0 (GLIBCXX_3.4.10) is required. If not, GCC needs to be upgraded in advance
Update hugegraph.properties
Initialize the database (required on the first startup, or a new configuration was manually added under ‘conf/graphs/’)
Start server
ToplingDB (Beta): As a high-performance alternative to RocksDB, please refer to the configuration guide: ToplingDB Quick Start
5.1.3 HBase
users need to install HBase by themselves, requiring version 2.0 or above,download link
Update hugegraph.properties
Initialize the database (required on the first startup, or a new configuration was manually added under ‘conf/graphs/’)
Start server
5.1.4 Create an example graph when startup
Pass the -p true argument when starting the script to enable preload, which creates a sample graph.
And use the RESTful API to request HugeGraphServer and get the following result:
This indicates the successful creation of the sample graph.
5.2 Use Docker to startup
In 3.1 Use Docker container, we introduced how to deploy hugegraph-server with Docker. You can also switch storage backends or preload a sample graph by setting the corresponding parameters.
5.2.1 Create an example graph when starting a server
Set the environment variable PRELOAD=true when starting Docker so that sample data is loaded during startup.
Use
docker runUse
docker run -itd --name=server -p 8080:8080 -e PRELOAD=true hugegraph/hugegraph:1.7.0Use
docker-composeCreate a
docker-compose.ymlfile like the following and setPRELOAD=truein the environment.example.groovyis a predefined script used to preload sample data. If needed, you can mount a newexample.groovyscript to change the preload data.Use
docker-compose up -dto start the container.
And use the RESTful API to request HugeGraphServer and get the following result:
This indicates that the sample graph was created successfully.
6. Access server
6.1 Service startup status check
Use jps to see a service process
curl request RESTfulAPI
Return 200, which means the server starts normally.
6.2 Request Server
The RESTful API of HugeGraphServer includes various types of resources, typically including graph, schema, gremlin, traverser and task.
graphcontainsvertices、edgesschemacontainsvertexlabels、propertykeys、edgelabels、indexlabelsgremlincontains variousGremlinstatements, such asg.v(), which can be executed synchronously or asynchronouslytraversercontains various advanced queries including shortest paths, intersections, N-step reachable neighbors, etc.taskcontains query and delete with asynchronous tasks
6.2.1 Get vertices and its related properties in hugegraph
explanation
Since there are many vertices and edges in the graph, for list-type requests, such as getting all vertices, getting all edges, etc., the server will compress the data and return it, so when use curl, you get a bunch of garbled characters, you can redirect to gunzip for decompression. It is recommended to use the Chrome browser + Restlet plugin to send HTTP requests for testing.
The current default configuration of HugeGraphServer can only be accessed locally, and the configuration can be modified so that it can be accessed on other machines.
response body:
For the detailed API, please refer to RESTful-API
You can also visit localhost:8080/swagger-ui/index.html to check the API.
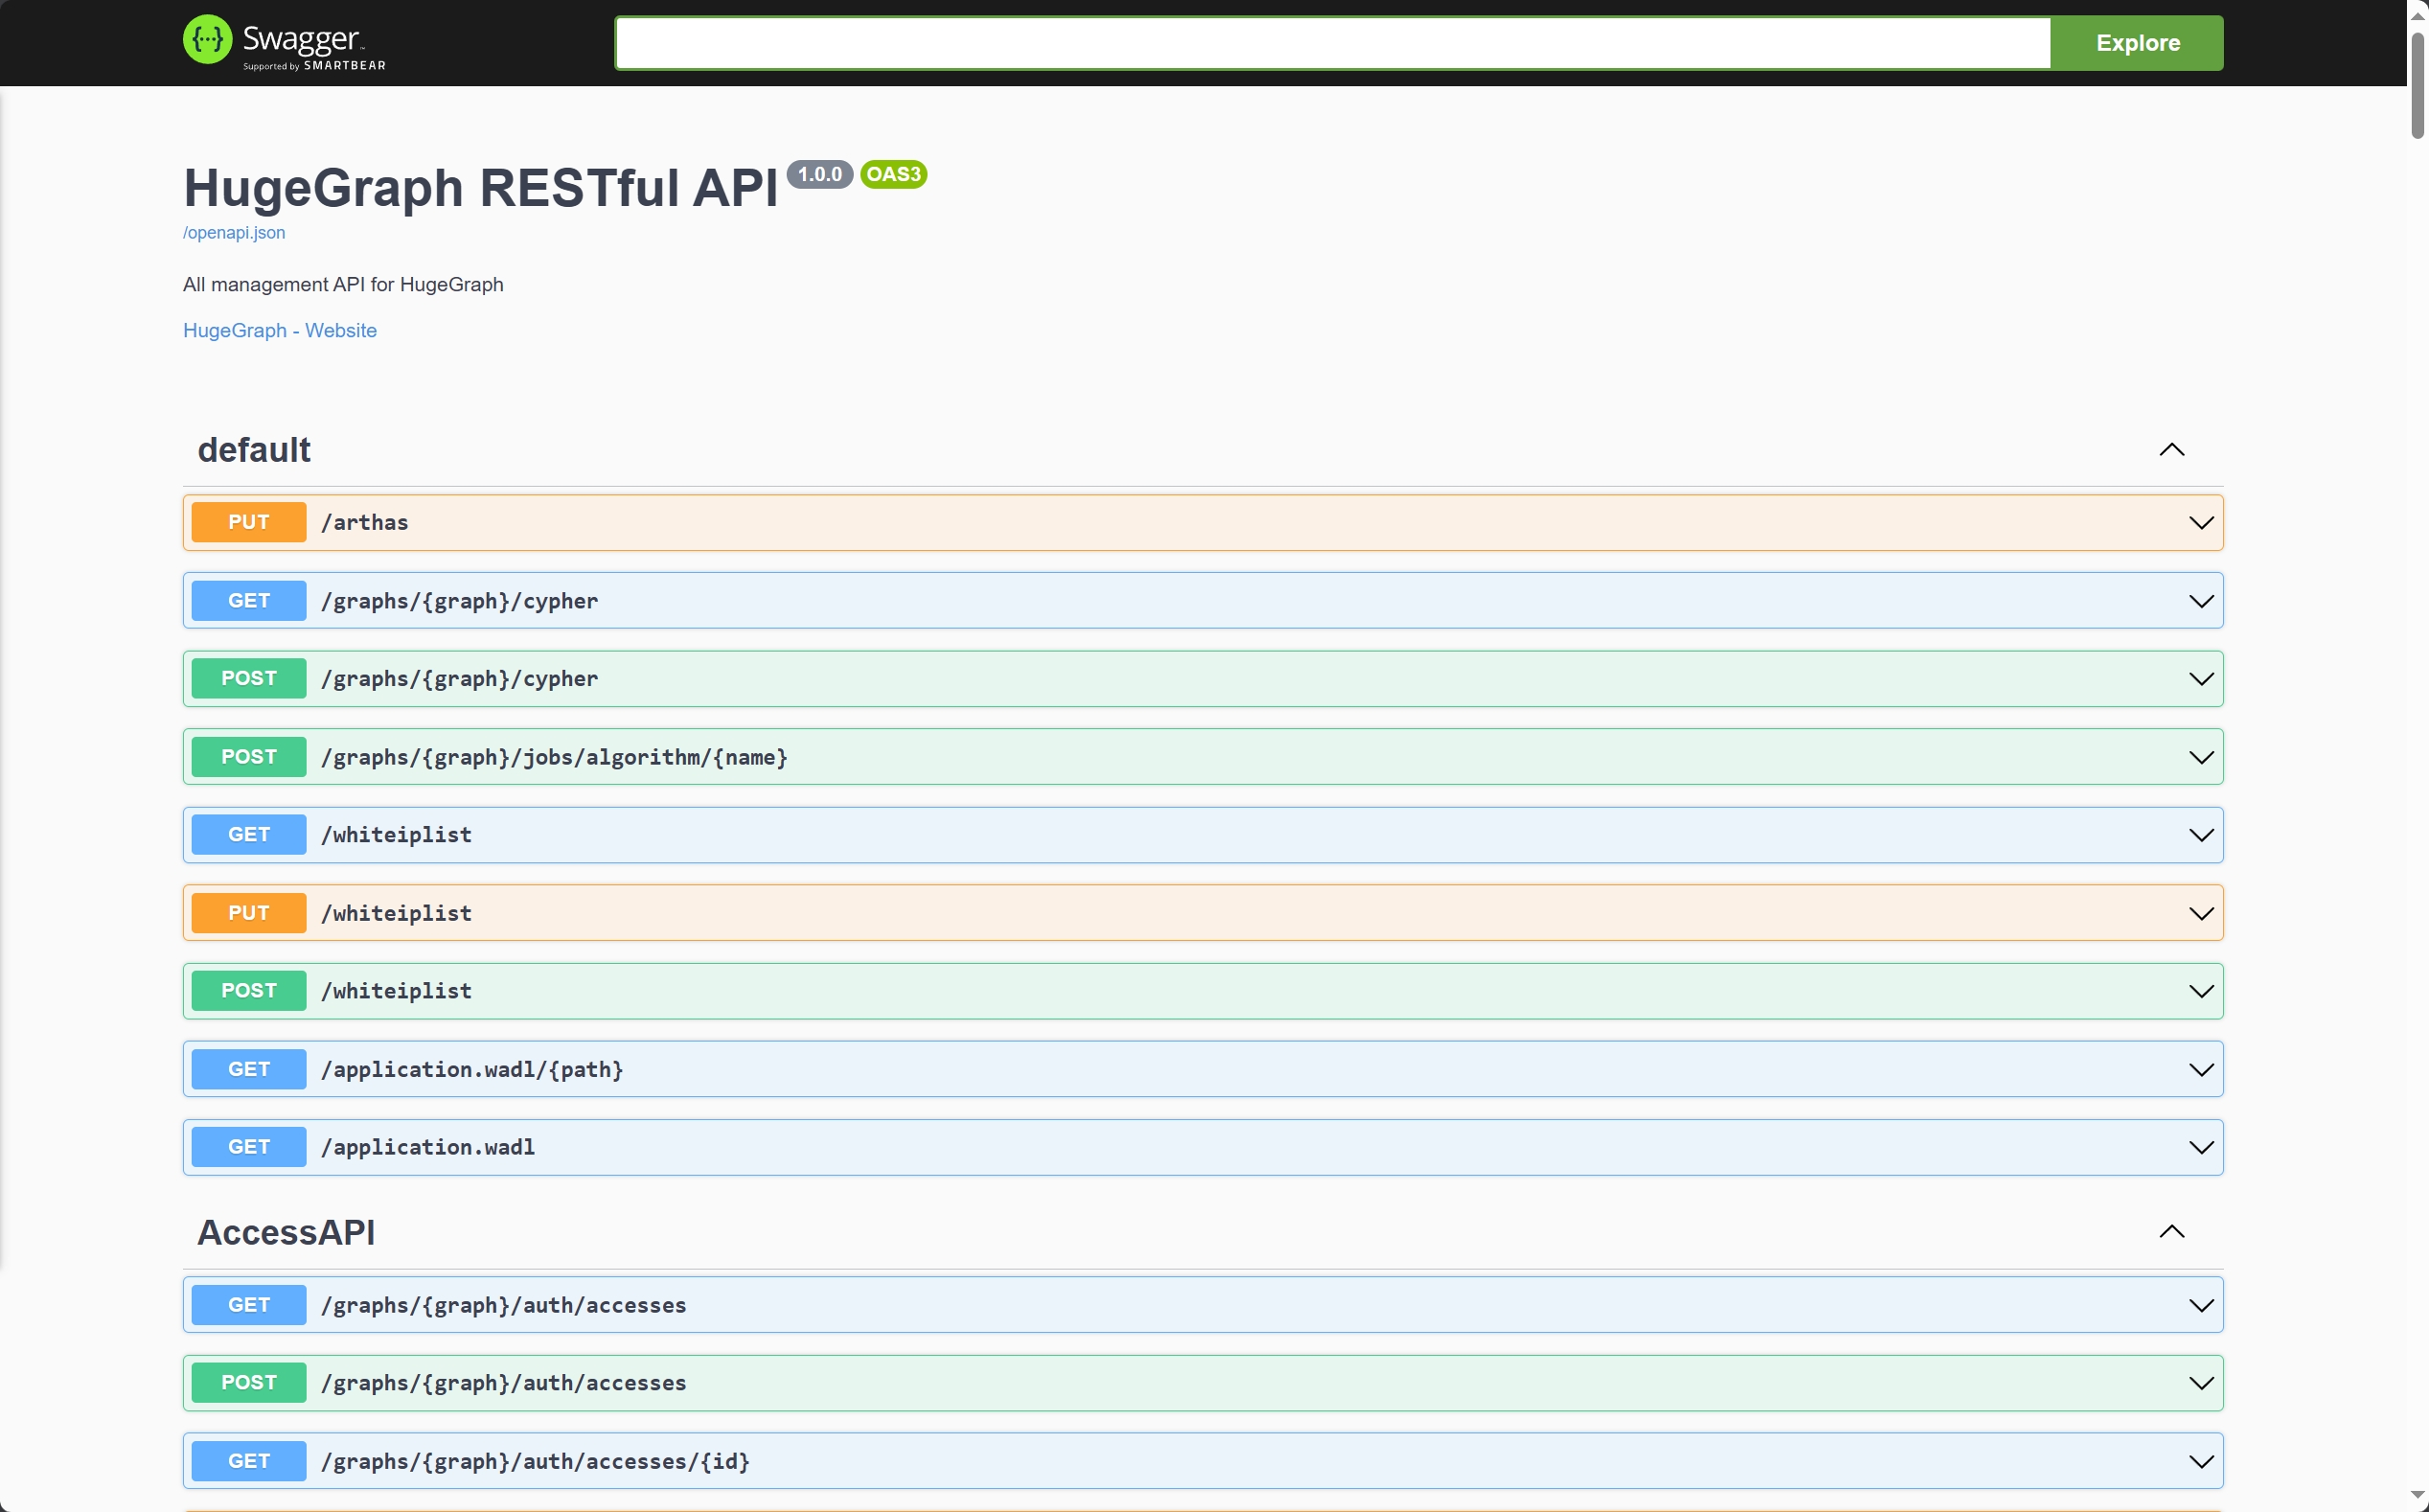
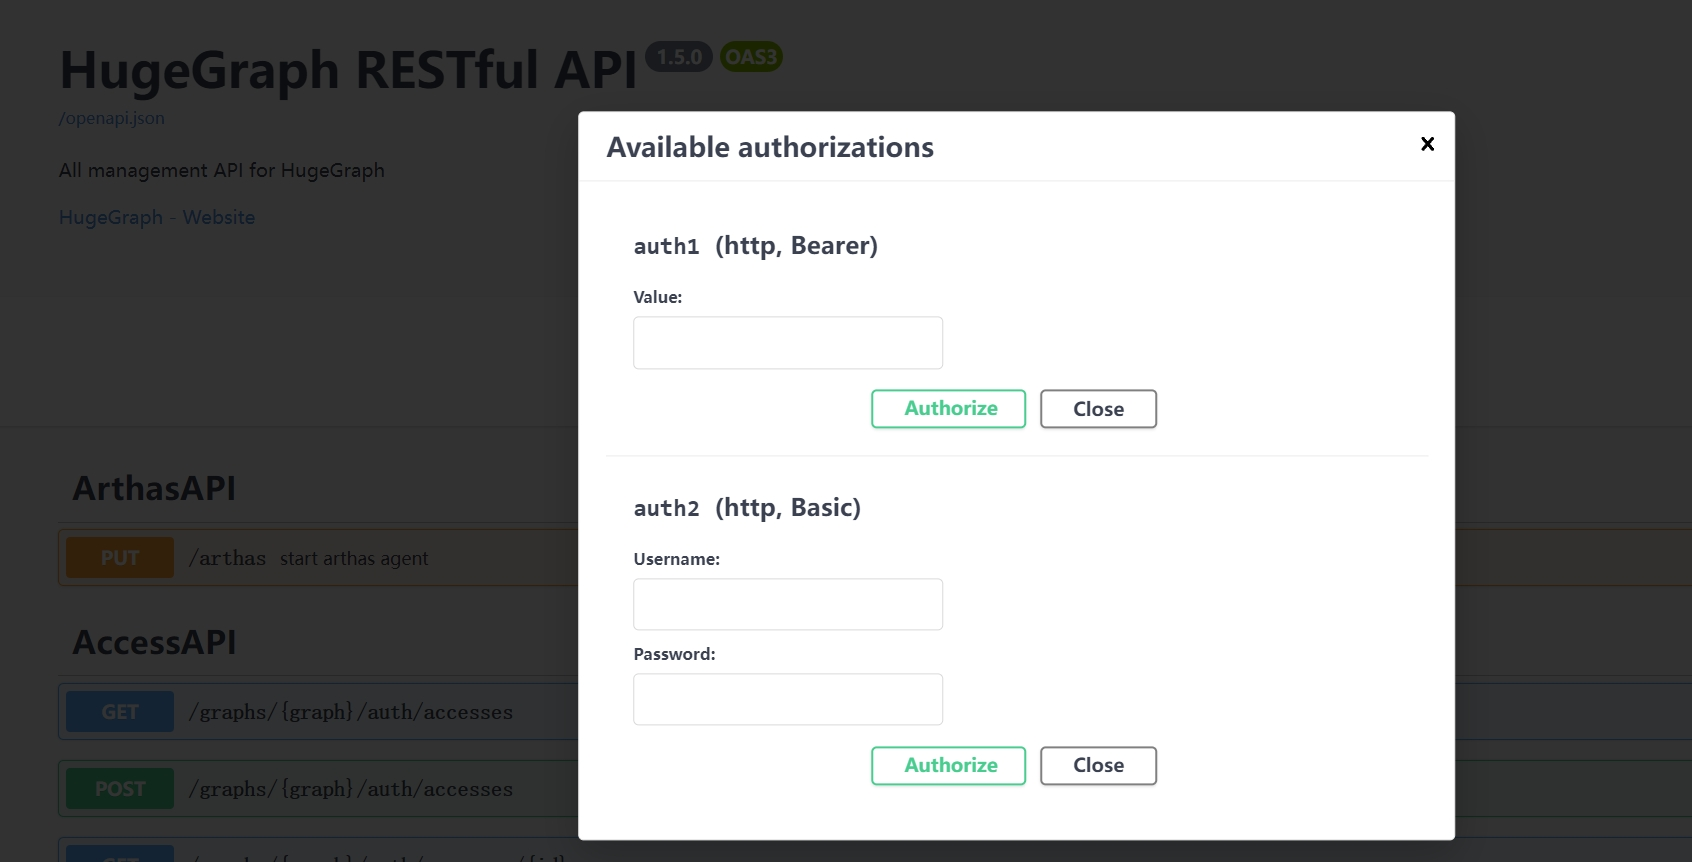
When using Swagger UI to debug the API provided by HugeGraph, if HugeGraph Server turns on authentication mode, you can enter authentication information on the Swagger page.
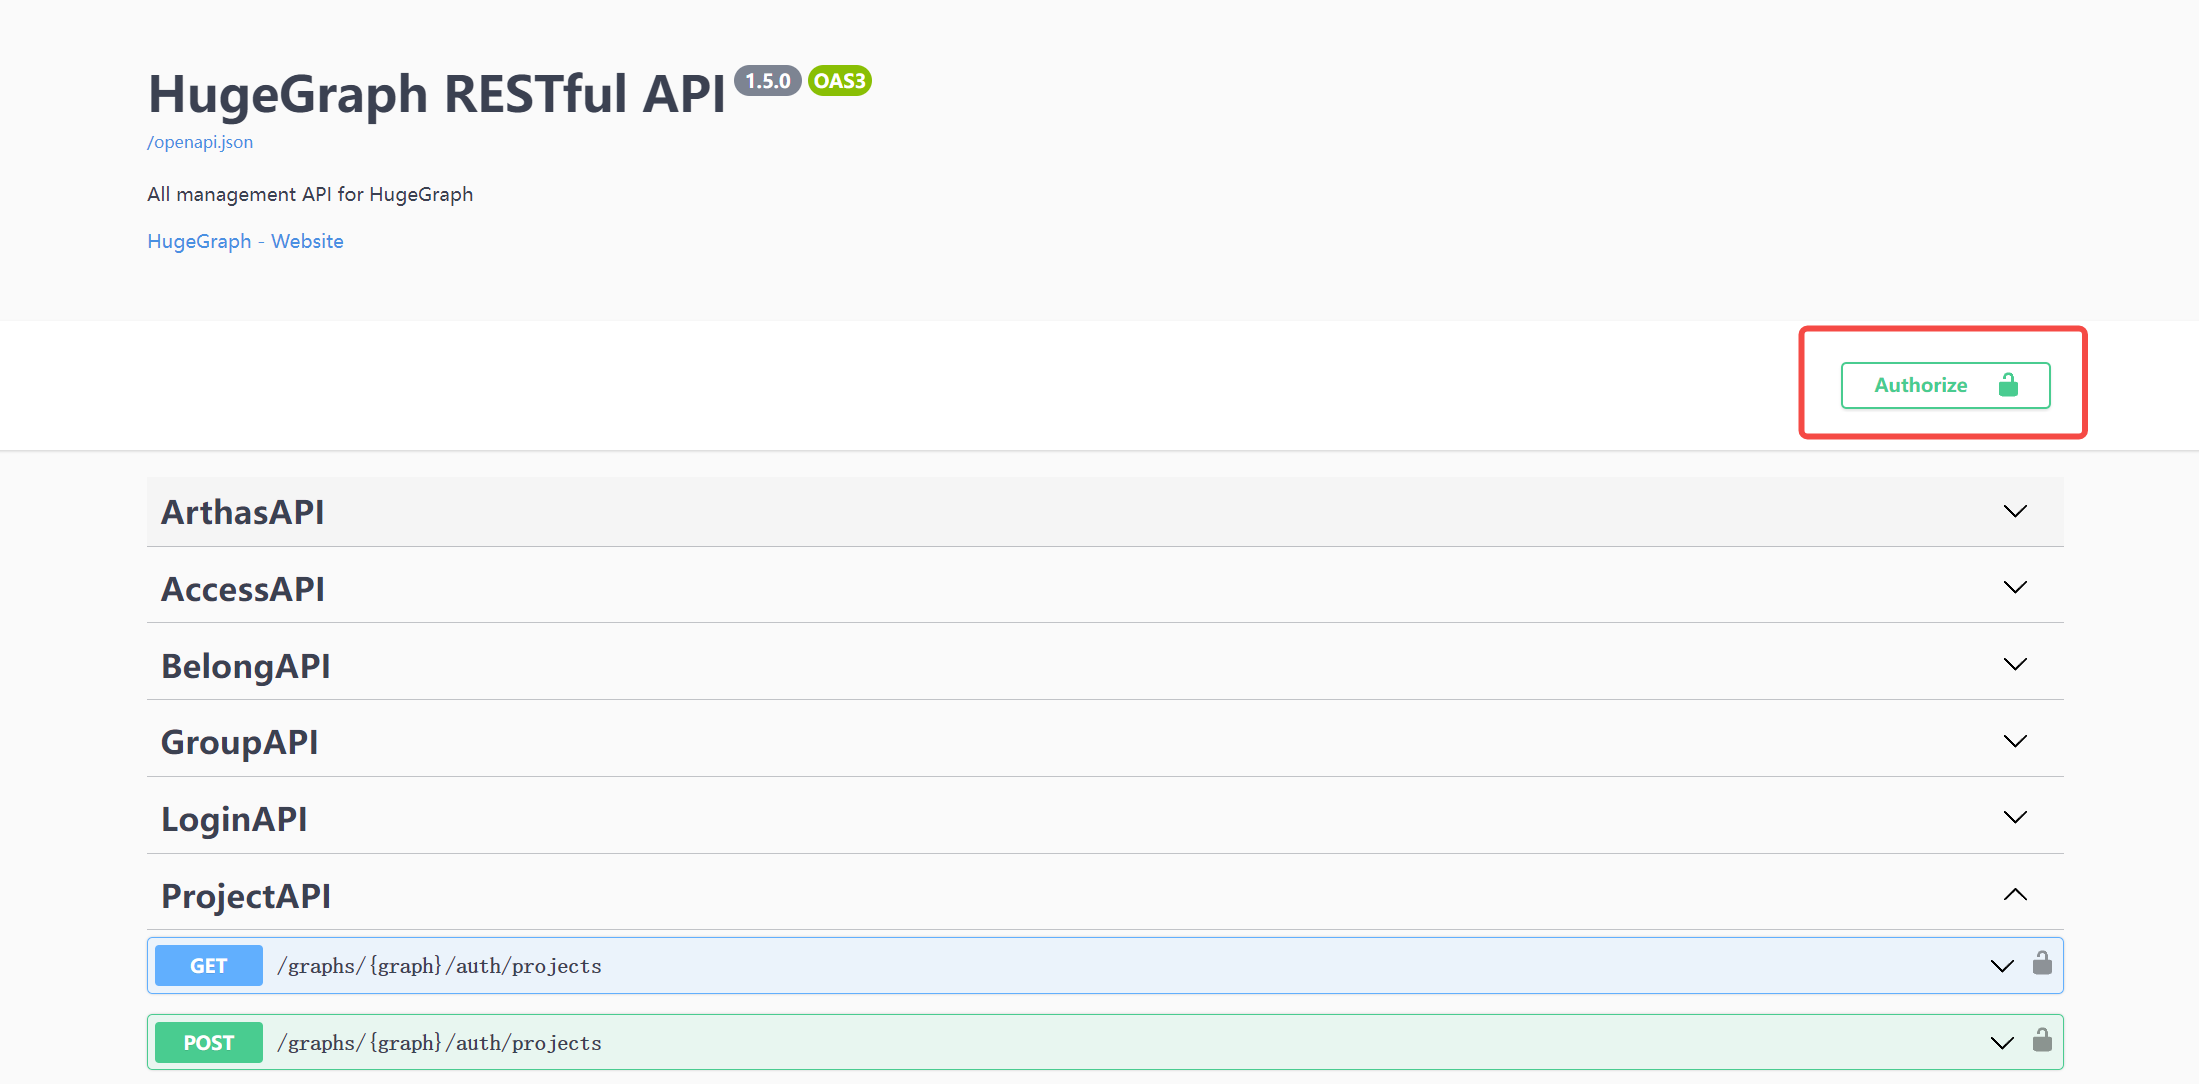
Currently, HugeGraph supports setting authentication information in two forms: Basic and Bearer.
7 Stop Server
8 Debug Server with IntelliJ IDEA
Please refer to Setup Server in IDEA
3.1.2 - HugeGraph-PD Quick Start
1 HugeGraph-PD Overview
HugeGraph-PD (Placement Driver) is the metadata management component of HugeGraph’s distributed version, responsible for managing the distribution of graph data and coordinating storage nodes. It plays a central role in distributed HugeGraph, maintaining cluster status and coordinating HugeGraph-Store storage nodes.
2 Prerequisites
2.1 Requirements
- Operating System: Linux or macOS (Windows has not been fully tested)
- Java version: ≥ 11
- Maven version: ≥ 3.5.0
3 Deployment
There are two ways to deploy the HugeGraph-PD component:
- Method 1: Download the tar package
- Method 2: Compile from source
3.1 Download the tar package
Download the latest version of HugeGraph-PD from the Apache HugeGraph official download page:
3.2 Compile from source
3.3 Docker Deployment
The HugeGraph-PD Docker image is available on Docker Hub as hugegraph/pd.
Note: The following steps assume you have already cloned or pulled the HugeGraph main repository locally, or at least have its
docker/directory available.
Use the docker compose setup to deploy the complete 3-node cluster (PD + Store + Server):
To run a single PD node via docker run, configuration is provided via environment variables:
Environment variable reference:
| Variable | Required | Default | Description |
|---|---|---|---|
HG_PD_GRPC_HOST | Yes | — | This node’s hostname/IP for gRPC (e.g. pd0 in Docker, 192.168.1.10 on bare metal) |
HG_PD_RAFT_ADDRESS | Yes | — | This node’s Raft address (e.g. pd0:8610) |
HG_PD_RAFT_PEERS_LIST | Yes | — | All PD peers (e.g. pd0:8610,pd1:8610,pd2:8610) |
HG_PD_INITIAL_STORE_LIST | Yes | — | Expected store gRPC addresses (e.g. store0:8500,store1:8500,store2:8500) |
HG_PD_GRPC_PORT | No | 8686 | gRPC server port |
HG_PD_REST_PORT | No | 8620 | REST API port |
HG_PD_DATA_PATH | No | /hugegraph-pd/pd_data | Metadata storage path |
HG_PD_INITIAL_STORE_COUNT | No | 1 | Minimum stores required for cluster availability |
Note: In Docker bridge networking, use container hostnames (e.g.
pd0) forHG_PD_GRPC_HOSTandHG_PD_RAFT_ADDRESSinstead of IP addresses.
Deprecated aliases:
GRPC_HOST,RAFT_ADDRESS,RAFT_PEERS,PD_INITIAL_STORE_LISTstill work but log a deprecation warning. Use theHG_PD_*names for new deployments.
To view runtime logs for a running PD container use docker logs <container-name> (e.g. docker logs hg-pd0).
See docker/README.md for the full cluster setup guide.
4 Configuration
The main configuration file for PD is conf/application.yml. Here are the key configuration items:
For multi-node deployment, you need to modify the port and address configurations for each node to ensure proper communication between nodes.
5 Start and Stop
5.1 Start PD
In the PD installation directory, execute:
The startup script supports a -d flag to control daemon mode:
-d true(default): run as a background daemon; the script returns immediately.-d false: run in foreground — the scriptexecs Java, so the container/supervisor process IS Java. Use this when running under Docker or a process supervisor (systemd, supervisord) so crashes are detected and the service is restarted automatically.
After successful startup, you can see logs similar to the following in logs/hugegraph-pd-stdout.log:
5.2 Stop PD
In the PD installation directory, execute:
6 Verification
Confirm that the PD service is running properly:
If it returns {"status":"UP"}, it indicates that the PD service has been successfully started.
You can also verify Store node status through the PD API:
If the response shows state as Up, the corresponding Store node is running normally. The example below shows a single Store node. In a healthy 3-node deployment, the storeId list should contain three IDs, and stateCountMap.Up, numOfService, and numOfNormalService should all be 3.
3.1.3 - HugeGraph-Store Quick Start
1 HugeGraph-Store Overview
HugeGraph-Store is the storage node component of HugeGraph’s distributed version, responsible for actually storing and managing graph data. It works in conjunction with HugeGraph-PD to form HugeGraph’s distributed storage engine, providing high availability and horizontal scalability.
2 Prerequisites
2.1 Requirements
- Operating System: Linux or macOS (Windows has not been fully tested)
- Java version: ≥ 11
- Maven version: ≥ 3.5.0
- Deploy HugeGraph-PD first for multi-node deployment
3 Deployment
There are two ways to deploy the HugeGraph-Store component:
- Method 1: Download the tar package
- Method 2: Compile from source
3.1 Download the tar package
Download the latest version of HugeGraph-Store from the Apache HugeGraph official download page:
3.2 Compile from source
3.3 Docker Deployment
The HugeGraph-Store Docker image is available on Docker Hub as hugegraph/store.
Note: The following steps assume you have already cloned or pulled the HugeGraph main repository locally, or at least have its
docker/directory available.
Use the compose file to deploy the complete 3-node cluster (PD + Store + Server):
To run a single Store node via docker run:
Environment variable reference:
| Variable | Required | Default | Description |
|---|---|---|---|
HG_STORE_PD_ADDRESS | Yes | — | PD gRPC addresses (e.g. pd0:8686,pd1:8686,pd2:8686) |
HG_STORE_GRPC_HOST | Yes | — | This node’s hostname/IP for gRPC (e.g. store0) |
HG_STORE_RAFT_ADDRESS | Yes | — | This node’s Raft address (e.g. store0:8510) |
HG_STORE_GRPC_PORT | No | 8500 | gRPC server port |
HG_STORE_REST_PORT | No | 8520 | REST API port |
HG_STORE_DATA_PATH | No | /hugegraph-store/storage | Data storage path |
Note: In Docker bridge networking, use container hostnames (e.g.
store0) forHG_STORE_GRPC_HOSTinstead of IP addresses.
Deprecated aliases:
PD_ADDRESS,GRPC_HOST,RAFT_ADDRESSstill work but log a deprecation warning. Use theHG_STORE_*names for new deployments.
4 Configuration
The main configuration file for Store is conf/application.yml. Here are the key configuration items:
For multi-node deployment, you need to modify the following configurations for each Store node:
grpc.port(RPC port) for each noderaft.address(Raft protocol port) for each nodeserver.port(REST port) for each nodeapp.data-path(data storage path) for each node
5 Start and Stop
5.1 Start Store
Ensure that the PD service is already started, then in the Store installation directory, execute:
The startup script supports a -d flag to control daemon mode:
-d true(default): run as a background daemon; the script returns immediately.-d false: run in foreground — the scriptexecs Java, so the container/supervisor process IS Java. Use this when running under Docker or a process supervisor (systemd, supervisord) so crashes are detected and the service is restarted automatically.
After successful startup, you can see logs similar to the following in logs/hugegraph-store-server.log:
5.2 Stop Store
In the Store installation directory, execute:
6 Multi-Node Deployment Example
Below is a configuration example for a three-node deployment:
6.1 Three-Node Configuration Reference
- 3 PD nodes
- raft ports: 8610, 8611, 8612
- rpc ports: 8686, 8687, 8688
- rest ports: 8620, 8621, 8622
- 3 Store nodes
- raft ports: 8510, 8511, 8512
- rpc ports: 8500, 8501, 8502
- rest ports: 8520, 8521, 8522
6.2 Store Node Configuration
For the three Store nodes, the main configuration differences are as follows:
Node A:
Node B:
Node C:
All nodes should point to the same PD cluster:
6.3 Docker Distributed Cluster Configuration
The distributed Store cluster definition is included in docker/docker-compose-3pd-3store-3server.yml. Each Store node gets its own hostname and environment variables:
Store nodes start only after all PD nodes pass healthchecks (/v1/health), enforced via depends_on: condition: service_healthy.
To view runtime logs for a running Store container use docker logs <container-name> (e.g. docker logs hg-store0).
See docker/README.md for the full setup guide.
7 Verify Store Service
Confirm that the Store service is running properly:
If it returns {"status":"UP"}, it indicates that the Store service has been successfully started.
You can also check Store node status through the PD API:
If Store is configured successfully, the response should include status information for the current node, and state: "Up" means the node is running normally.
The example below shows a single Store node. If all three nodes are configured correctly and running, the storeId list should contain three IDs, and stateCountMap.Up, numOfService, and numOfNormalService should all be 3.
3.2 - HugeGraph ToolChain
HugeGraph Toolchain includes the Java and Go clients, Loader, Hubble, Tools, and Spark Connector. See the documents in this section for each module’s features and usage.
Testing Guide: For running toolchain tests locally, please refer to HugeGraph Toolchain Local Testing Guide
DeepWiki provides real-time updated project documentation with more comprehensive and accurate content, suitable for quickly understanding the latest project information.
Source repository: apache/hugegraph-toolchain
3.2.1 - HugeGraph-Hubble Quick Start
1 HugeGraph-Hubble Overview
⚠️ Security notice: As of the 1.7.0 release, Hubble does not provide Auth/Login protection. This feature is planned for the 1.8.0 release. Do not expose Hubble to the public Internet or untrusted networks; restrict access with IP/port allowlists and HTTPS.
Testing Guide: For running HugeGraph-Hubble tests locally, please refer to HugeGraph Toolchain Local Testing Guide
HugeGraph-Hubble is HugeGraph’s web management interface. It manages graph connections and schemas, imports data, runs Gremlin queries, and visualizes query results.
The platform mainly includes the following modules:
Graph Management
Graph Management creates and maintains connections, switches between graphs, and provides access, editing, deletion, and query operations.
Metadata Modeling
Metadata Modeling manages PropertyKeys, VertexLabels, EdgeLabels, and IndexLabels. It provides list and graph views and supports reusing metadata across graphs.
Graph Analysis
Graph Analysis runs Gremlin and path queries and displays results as a graph, table, or JSON. It also keeps execution history and saved statements, and exports query results as JSON.
Task Management
Task Management displays background tasks such as asynchronous Gremlin jobs and index creation or rebuilding.
Data Import
The data import page is intended for small-scale trials. For bulk or production imports, use HugeGraph Loader.
The data import page guides you through creating a task, uploading files, and mapping fields. Multiple import tasks can run in parallel, with resumable uploads and error retries.
2 Deploy
There are three ways to deploy hugegraph-hubble
- Use Docker (Convenient for Test/Dev)
- Download the Toolchain binary package
- Source code compilation
2.1 Use docker (Convenient for Test/Dev)
Special Note: If you are starting
hubblewith Docker, andhubbleand the server are on the same host. When configuring the hostname for the graph on the Hubble web page, please do not directly set it tolocalhost/127.0.0.1. This will refer to thehubblecontainer internally rather than the host machine, resulting in a connection failure to the server.If
hubbleandserveris in the same docker network, we recommend using thecontainer_name(in our example, it isserver) as the hostname, and8080as the port. Or you can use the host IP as the hostname, and the port is configured by the host for the server.
We can use docker run -itd --name=hubble -p 8088:8088 hugegraph/hubble:1.5.0 to quick start hubble.
Alternatively, you can use Docker Compose to start hubble. Additionally, if hubble and the graph is in the same Docker network, you can access the graph using the container name of the graph, eliminating the need for the host machine’s IP address.
Use docker-compose up -d,docker-compose.yml is following:
Note:
The docker image of hugegraph-hubble is a convenience release to start hugegraph-hubble quickly, but not official distribution artifacts. You can find more details from ASF Release Distribution Policy.
Recommend to use
release tag(like1.5.0) for the stable version. Uselatesttag to experience the newest functions in development.
2.2 Download the Toolchain binary package
hubble is in the toolchain project. First, download the binary tar tarball
Run hubble
After startup, open http://<host>:8088. Run bin/stop-hubble.sh to stop the service.
2.3 Source code compilation
Hubble’s build uses frontend-maven-plugin in hugegraph-hubble/hubble-dist/pom.xml to install Node.js 18.20.8 and Yarn 1.22.21, so neither tool needs to be installed beforehand.
Download the toolchain source code.
Compile hubble. It depends on the loader and client, so you need to build these dependencies in advance during the compilation process (you can skip this step later).
Run hubble
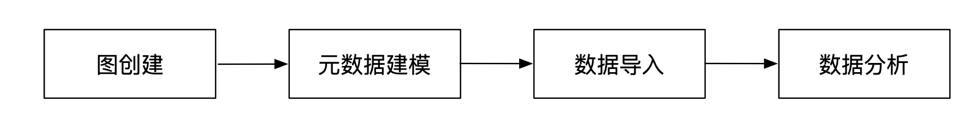
3 Platform Workflows
The module usage process of the platform is as follows:
4 Platform Instructions
4.1 Graph Management
4.1.1 Graph creation
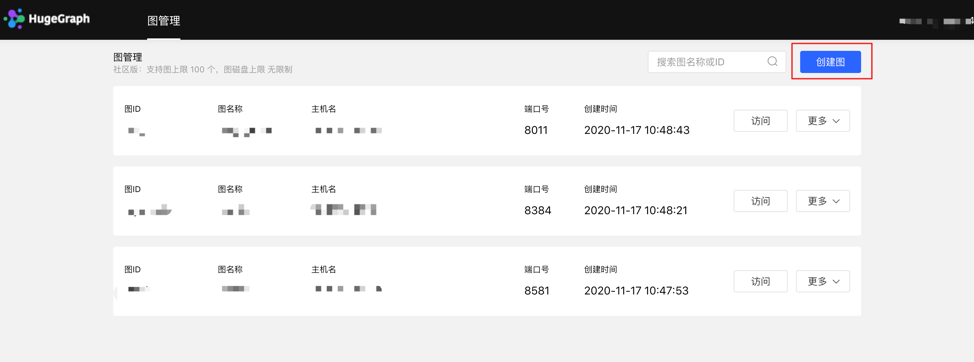
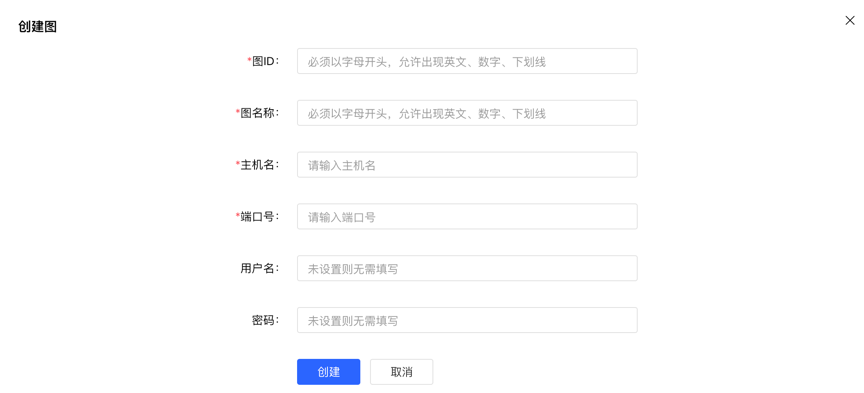
Under the graph management module, click [Create graph], and realize the connection of multiple graphs by filling in the graph ID, graph name, host name, port number, username, and password information.
Create graph by filling in the content as follows:
Special Note: If you are starting
hubblewith Docker, andhubbleand the server are on the same host. When configuring the hostname for the graph on the Hubble web page, please do not directly set it tolocalhost/127.0.0.1. Ifhubbleandserveris in the same docker network, we recommend using thecontainer_name(in our example, it isgraph) as the hostname, and8080as the port. Or you can use the host IP as the hostname, and the port is configured by the host for the server.
4.1.2 Graph Access
Realize the information access to the graph space. After entering, you can perform operations such as multidimensional query analysis, metadata management, data import, and algorithm analysis of the graph.
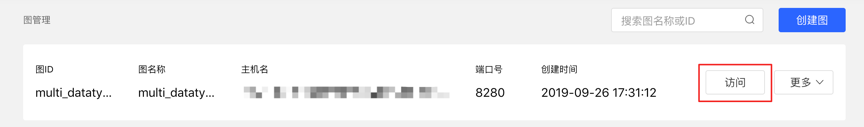
4.1.3 Graph management
- Users can achieve unified management of graphs through overview, search, and information editing and deletion of single graphs.
- Search range: You can search for the graph name and ID.
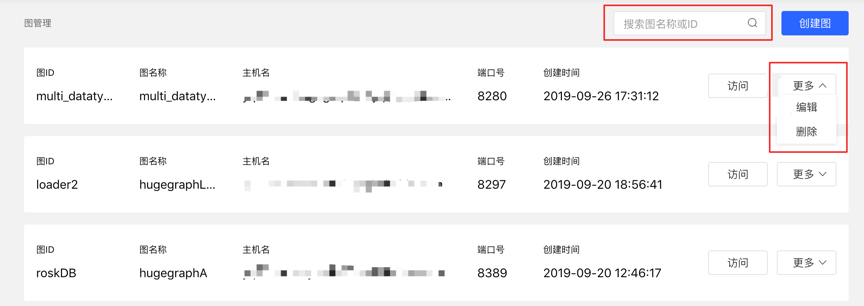
4.2 Metadata Modeling (list + graph mode)
4.2.1 Module entry
Left navigation:
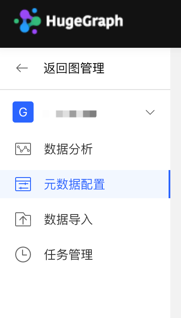
4.2.2 Property type
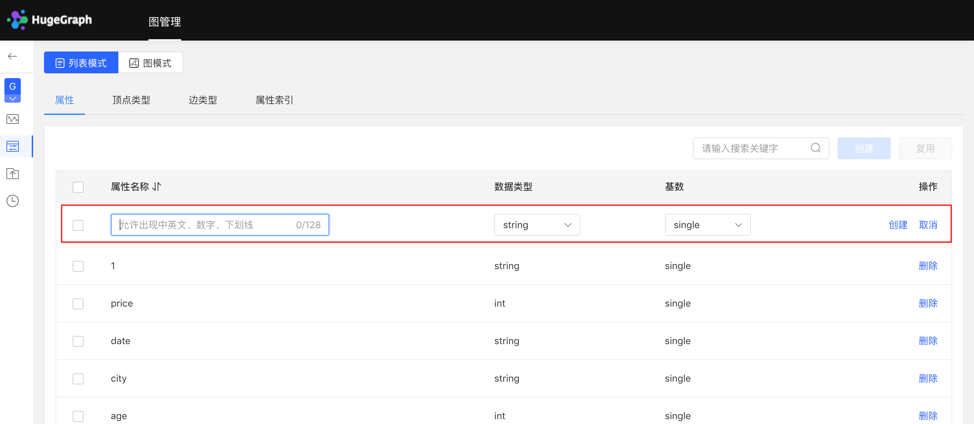
4.2.2.1 Create type
- Fill in or select the attribute name, data type, and cardinality to complete the creation of the attribute.
- Created attributes can be used as attributes of vertex type and edge type.
List mode:
Graph mode:
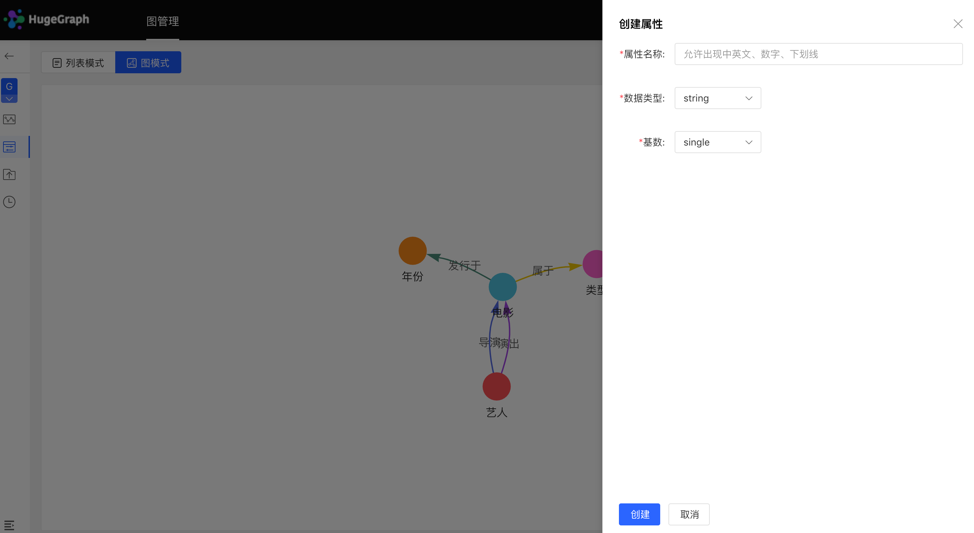
4.2.2.2 Reuse
- The platform provides the [Reuse] function, which can directly reuse the metadata of other graphs.
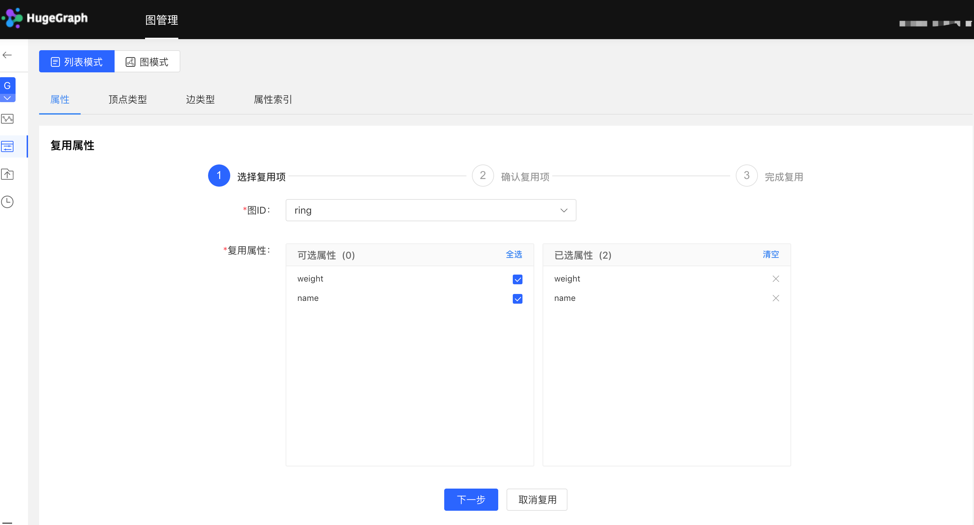
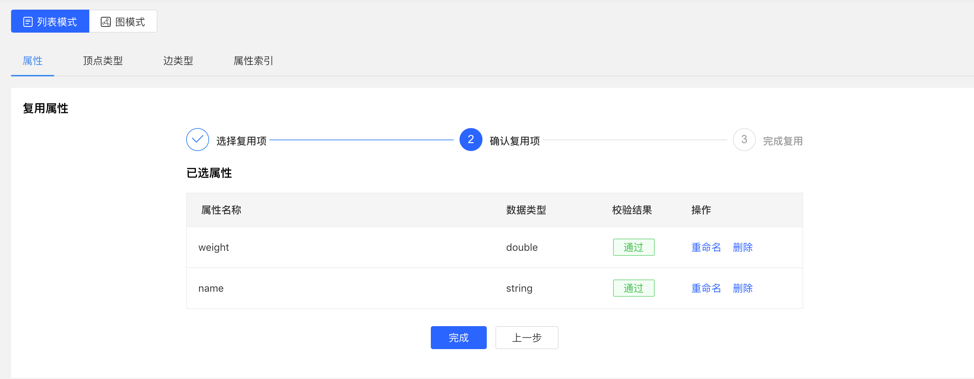
- Select the graph ID that needs to be reused, and continue to select the attributes that need to be reused. After that, the platform will check whether there is a conflict. After passing, the metadata can be reused.
Select reuse items:
Check reuse items:
4.2.2.3 Management
- You can delete a single item or delete it in batches in the attribute list.
4.2.3 Vertex type
4.2.3.1 Create type
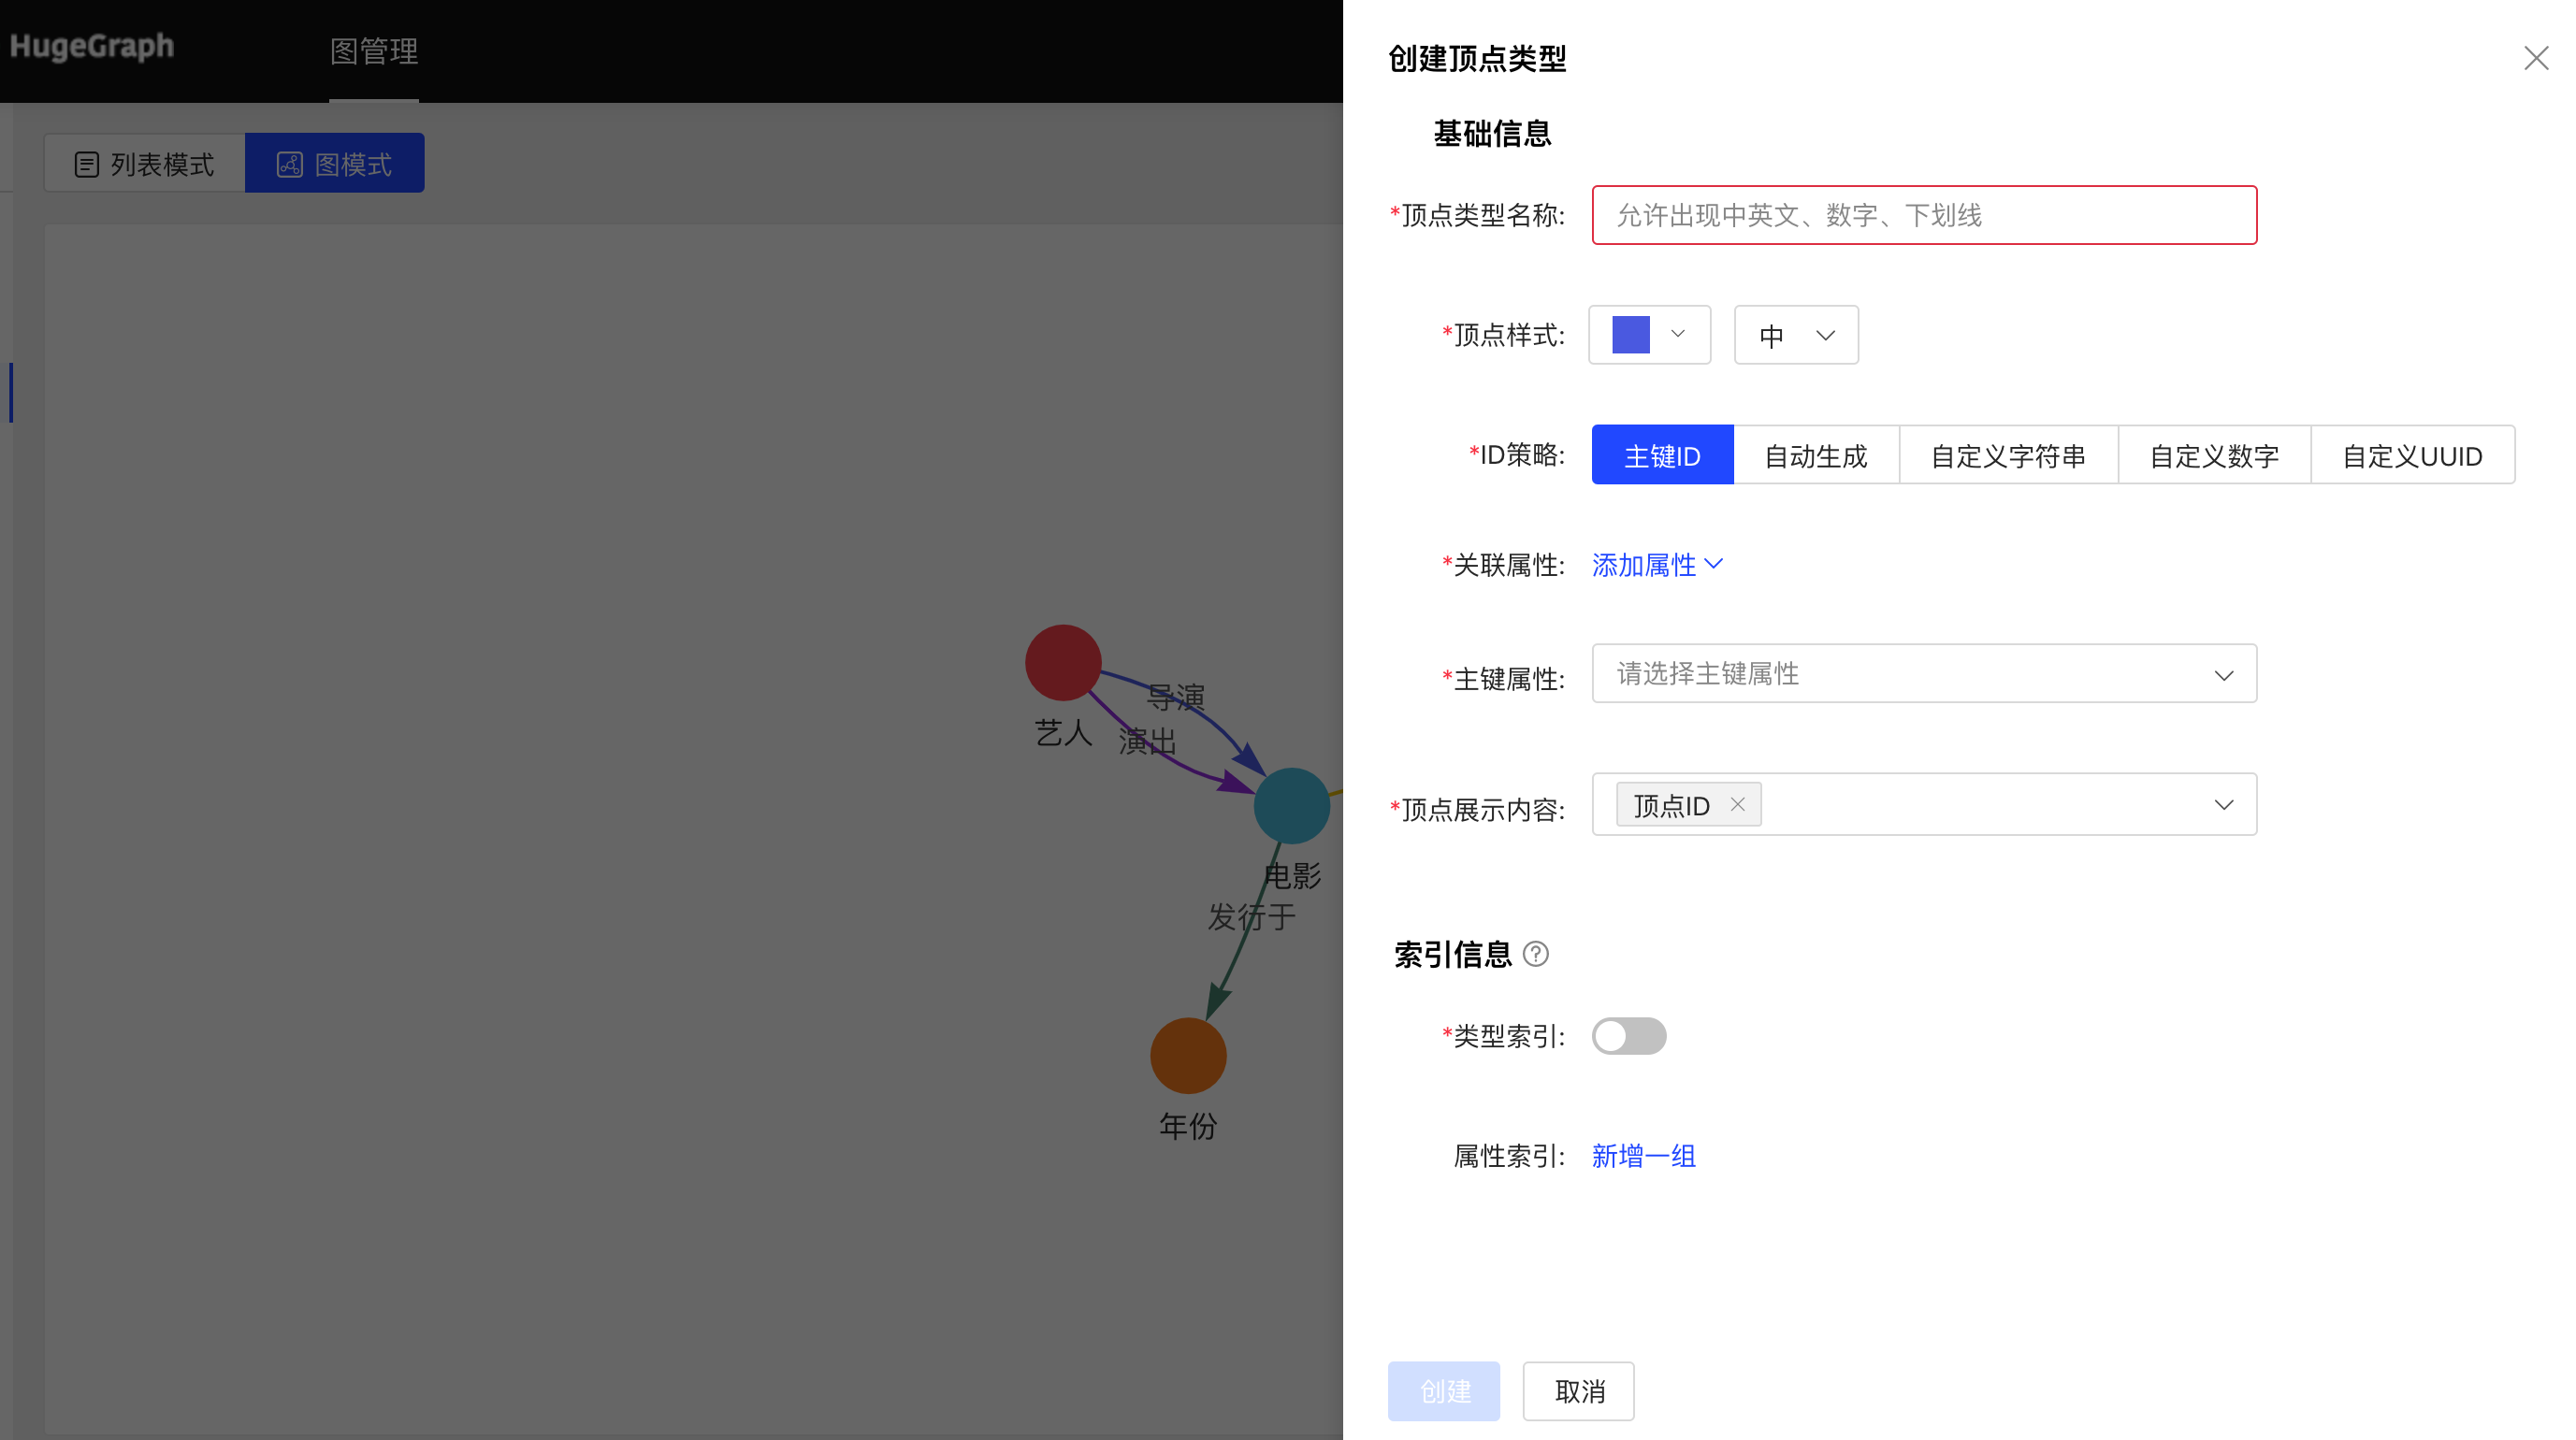
- Fill in or select the vertex type name, ID strategy, association attribute, primary key attribute, vertex style, content displayed below the vertex in the query result, and index information: including whether to create a type index, and the specific content of the attribute index, complete the vertex Type creation.
List mode:
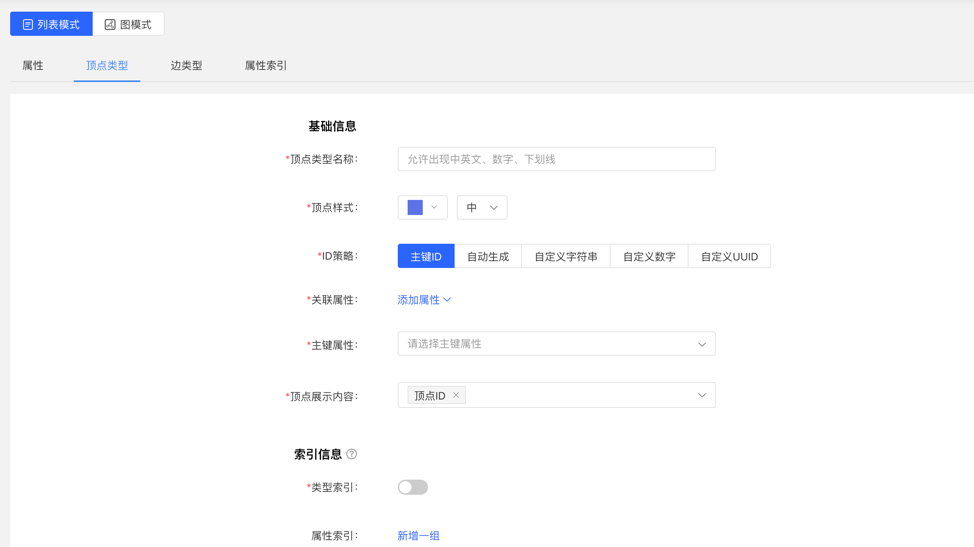
Graph mode:
4.2.3.2 Reuse
- The multiplexing of vertex types will reuse the attributes and attribute indexes associated with this type together.
- The reuse method is similar to the property reuse, see 3.2.2.2.
4.2.3.3 Administration
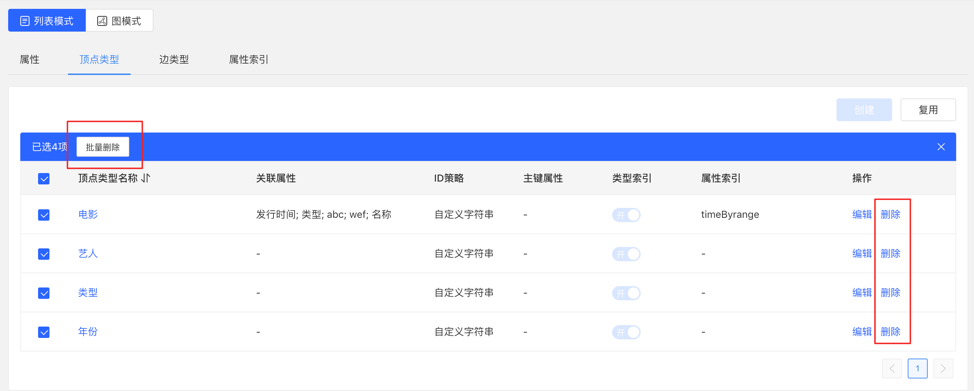
Editing operations are available. The vertex style, association type, vertex display content, and attribute index can be edited, and the rest cannot be edited.
You can delete a single item or delete it in batches.
4.2.4 Edge Types
4.2.4.1 Create
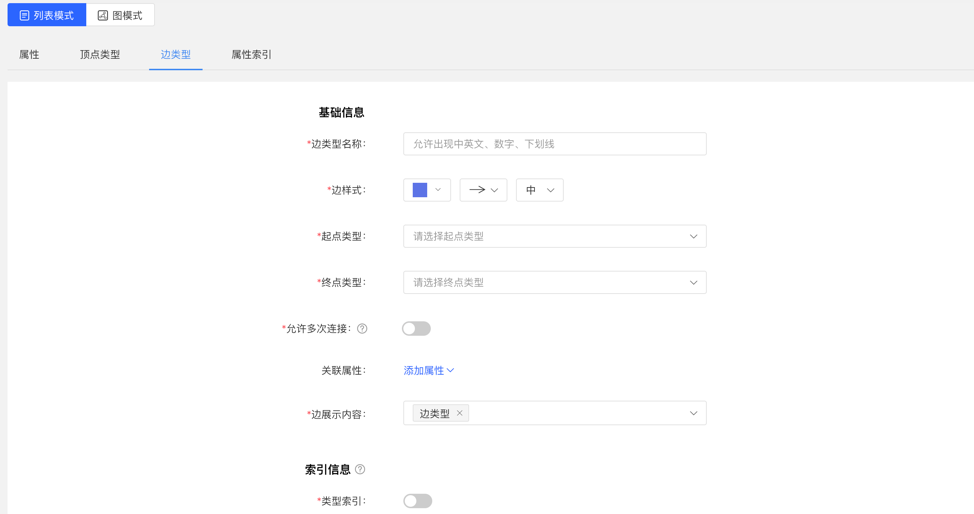
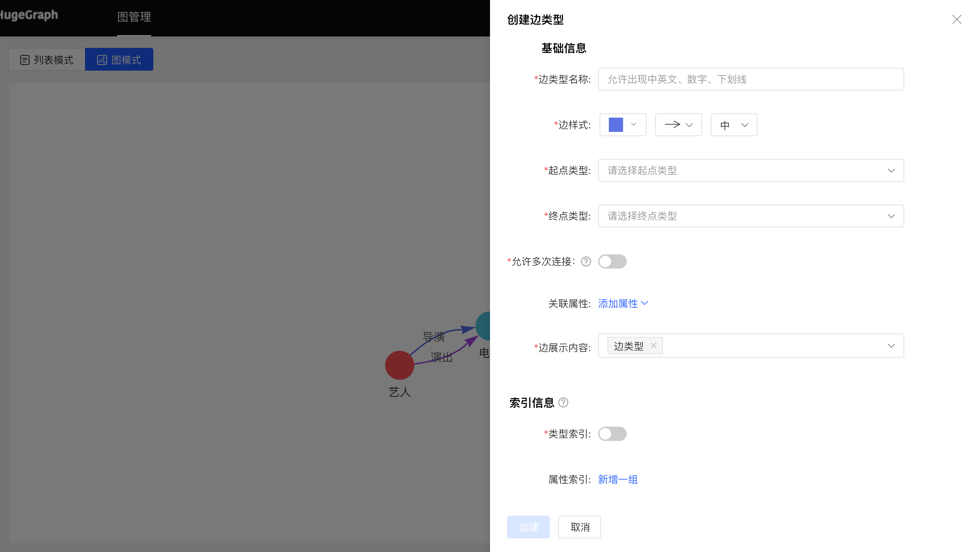
- Fill in or select the edge type name, start point type, end point type, associated attributes, whether to allow multiple connections, edge style, content displayed below the edge in the query result, and index information: including whether to create a type index, and attribute index The specific content, complete the creation of the edge type.
List mode:
Graph mode:
4.2.4.2 Reuse
- The reuse of the edge type will reuse the start point type, end point type, associated attribute and attribute index of this type.
- The reuse method is similar to the property reuse, see 3.2.2.2.
4.2.4.3 Administration
- Editing operations are available. Edge styles, associated attributes, edge display content, and attribute indexes can be edited, and the rest cannot be edited, the same as the vertex type.
- You can delete a single item or delete it in batches.
4.2.5 Index Types
Displays vertex and edge indices for vertex types and edge types.
4.3 Data Import
Note:currently, we recommend to use hugegraph-loader to import data formally. The built-in import of
hubbleis used for testing and getting started.
The usage process of data import is as follows:

4.3.1 Module entrance
Left navigation:
4.3.2 Create task
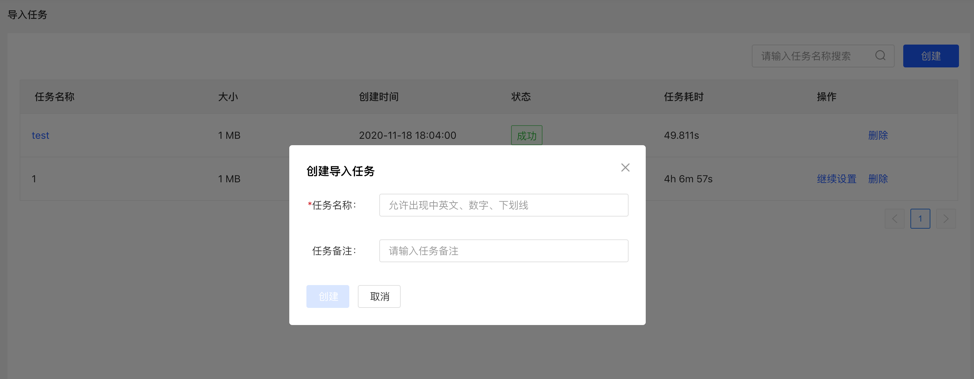
- Fill in the task name and remarks (optional) to create an import task.
- Multiple import tasks can be created and imported in parallel.
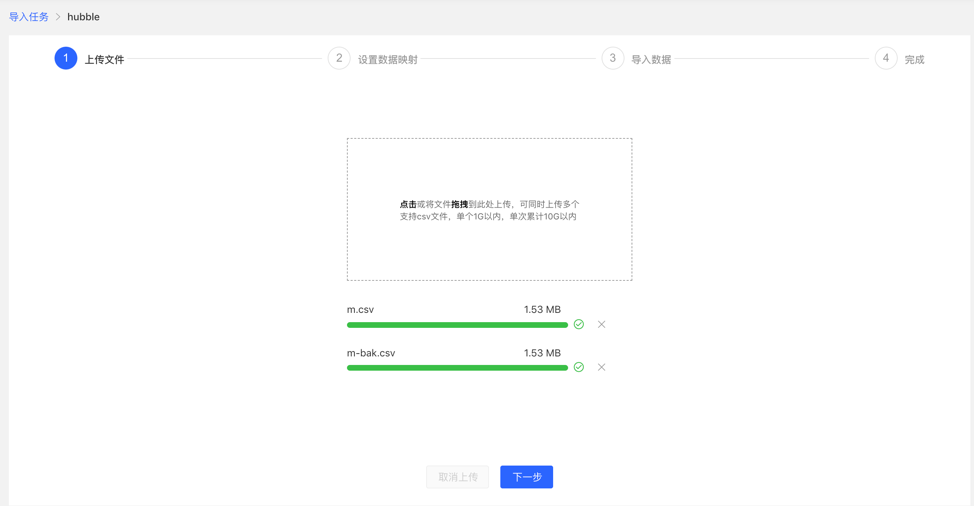
4.3.3 Uploading files
- Upload the file that needs to be composed. The currently supported format is CSV, which will be updated continuously in the future.
- Multiple files can be uploaded at the same time.
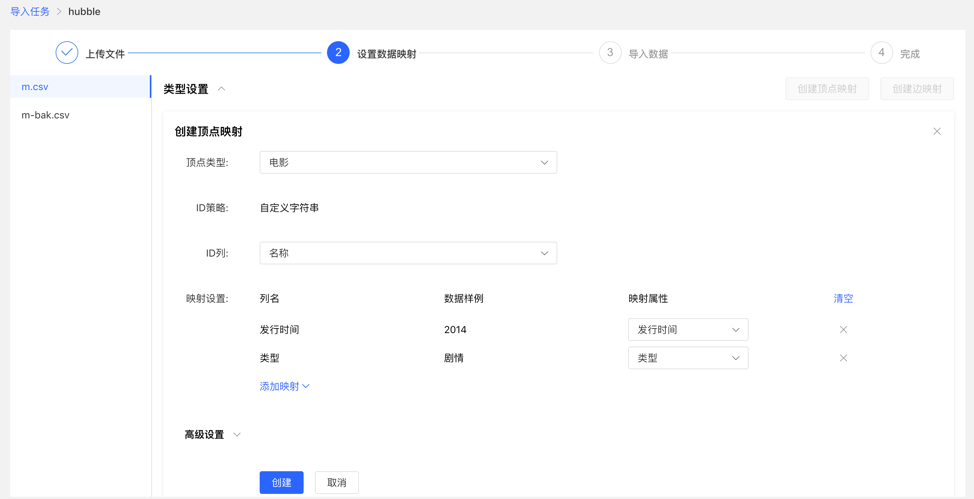
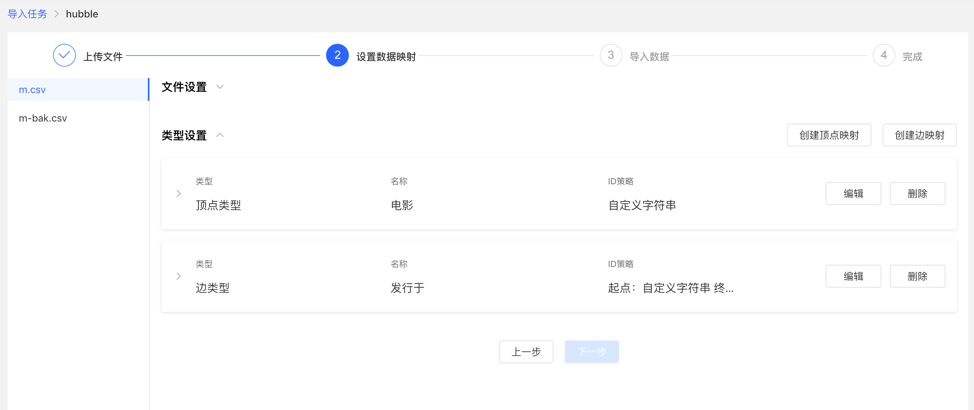
4.3.4 Setting up data mapping
Set up data mapping for uploaded files, including file settings and type settings
File settings: Check or fill in whether to include the header, separator, encoding format and other settings of the file itself, all set the default values, no need to fill in manually
Type setting:
Vertex map and edge map:
【Vertex Type】: Select the vertex type, and upload the column data in the file for its ID mapping;
【Edge Type】: Select the edge type and map the column data of the uploaded file to the ID column of its start point type and end point type;
Mapping settings: upload the column data in the file for the attribute mapping of the selected vertex type. Here, if the attribute name is the same as the header name of the file, the mapping attribute can be automatically matched, and there is no need to manually fill in the selection.
After completing the setting, the setting list will be displayed before proceeding to the next step. It supports the operations of adding, editing and deleting mappings.
Fill in the settings map:
Mapping list:
4.3.5 Import data
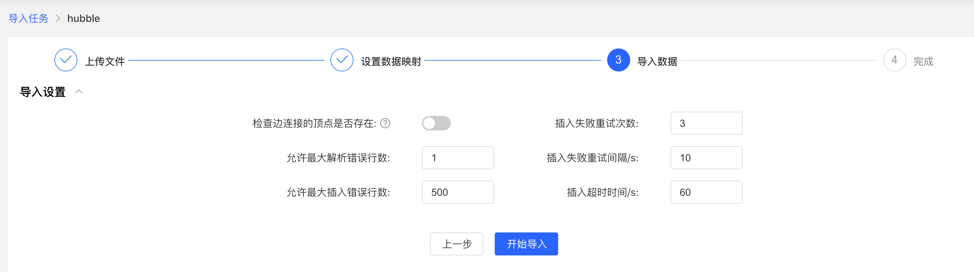
Before importing, you need to fill in the import setting parameters. After filling in, you can start importing data into the gallery.
- Import settings
- The import setting parameter items are as shown in the figure below, all set the default value, no need to fill in manually
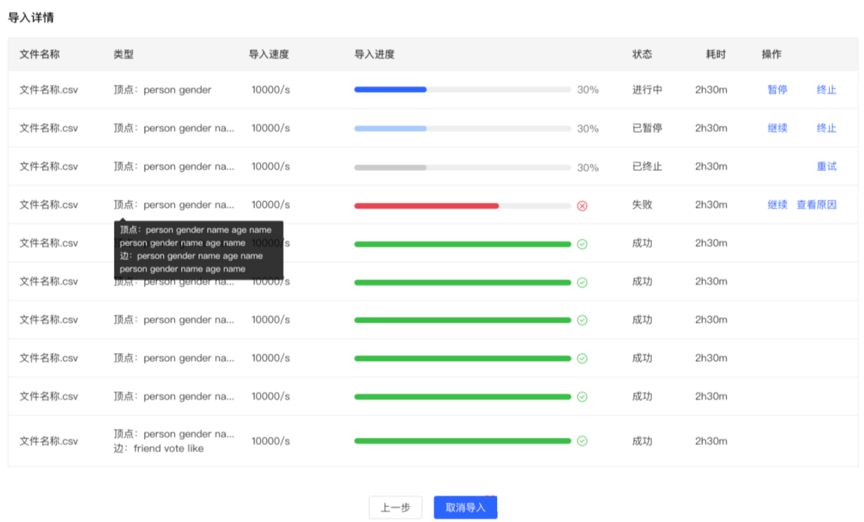
- Import details
- Click Start Import to start the file import task
- The import details provide the mapping type, import speed, import progress, time-consuming and the specific status of the current task set for each uploaded file, and can pause, resume, stop and other operations for each task
- If the import fails, you can view the specific reason
4.4 Data Analysis
4.4.1 Module entry
Left navigation:
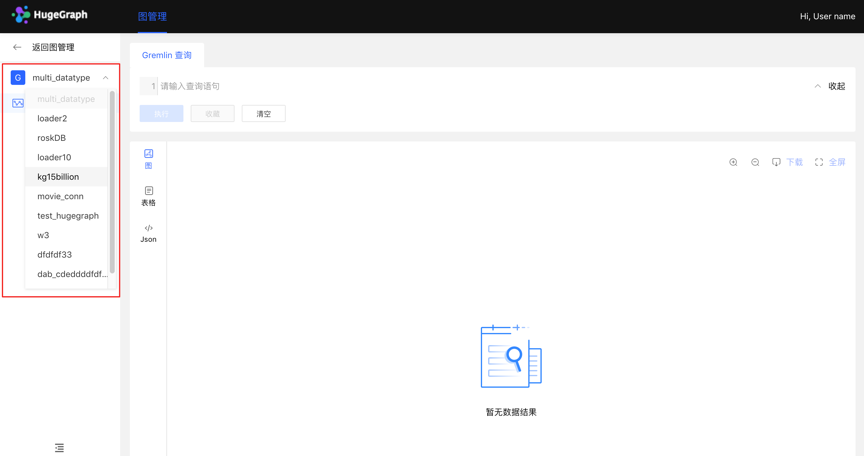
4.4.2 Multi-graphs switching
By switching the entrance on the left, flexibly switch the operation space of multiple graphs
4.4.3 Graph Analysis and Processing
HugeGraph supports Gremlin, a graph traversal query language of Apache TinkerPop3. Gremlin is a general graph database query language. By entering Gremlin statements and clicking execute, you can perform query and analysis operations on graph data, and create and delete vertices/edges. vertex/edge attribute modification, etc.
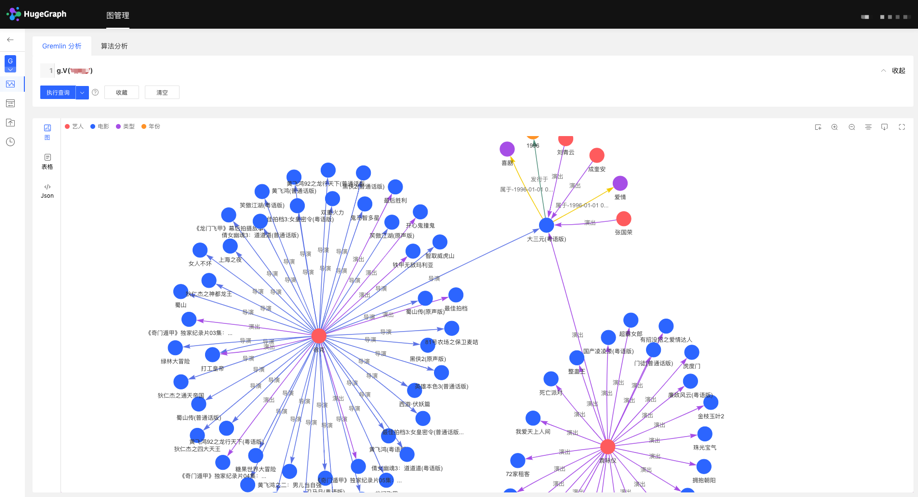
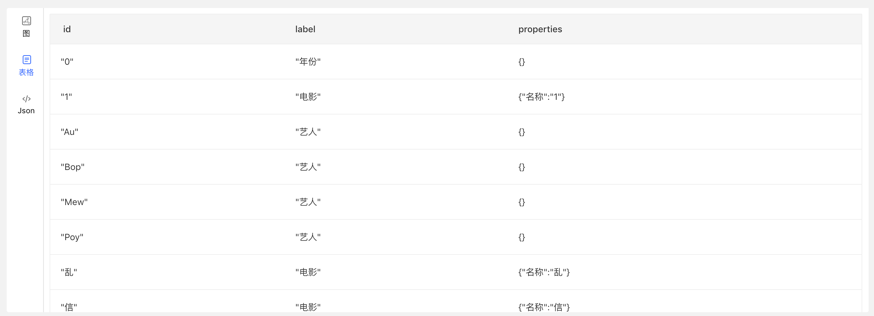
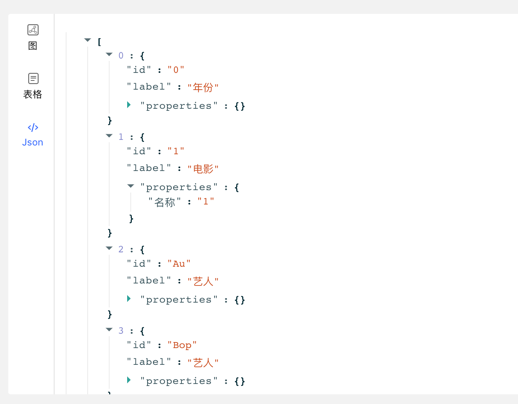
After Gremlin query, below is the graph result display area, which provides 3 kinds of graph result display modes: [Graph Mode], [Table Mode], [Json Mode].
⚠️ SEC Reminder: Hubble allows the direct input and execution of native Gremlin query statements on the web interface, which grants users relatively high operational privileges. Please avoid exposing the Hubble service to public network environments. It is recommended to ensure that the graph database server has enabled the Authentication System (Auth) combined with an IP Whitelist for strict permission control when in use, preventing unauthorized access or malware execution risks.
Support zoom, center, full screen, export and other operations.
【Picture Mode】
【Table mode】
【Json mode】
4.4.4 Data Details
Click the vertex/edge entity to view the data details of the vertex/edge, including vertex/edge type, vertex ID, attribute and corresponding value, expand the information display dimension of the graph, and improve the usability.
4.4.5 Multidimensional Path Query of Graph Results
In addition to the global query, an in-depth customized query and hidden operations can be performed for the vertices in the query result to realize customized mining of graph results.
Right-click a vertex, and the menu entry of the vertex appears, which can be displayed, inquired, hidden, etc.
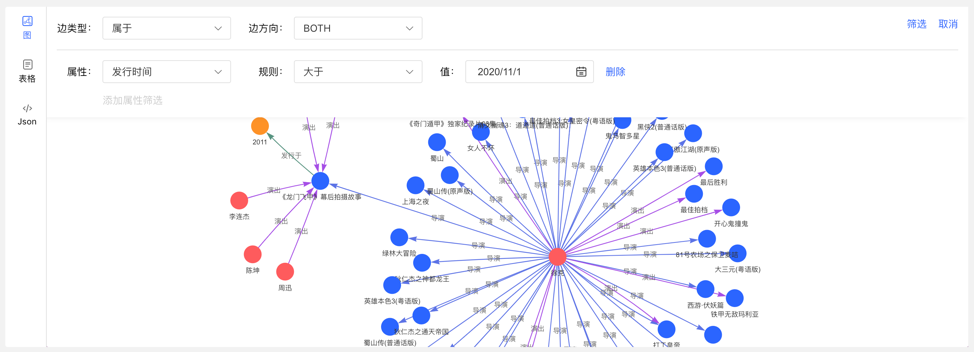
- Expand: Click to display the vertices associated with the selected point.
- Query: By selecting the edge type and edge direction associated with the selected point, and then selecting its attributes and corresponding filtering rules under this condition, a customized path display can be realized.
- Hide: When clicked, hides the selected point and its associated edges.
Double-clicking a vertex also displays the vertex associated with the selected point.
4.4.6 Add vertex/edge
4.4.6.1 Added vertex
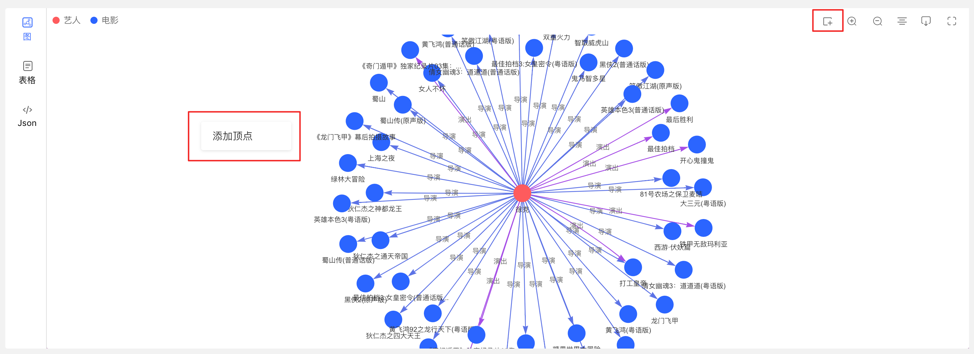
In the graph area, two entries can be used to dynamically add vertices, as follows:
- Click on the graph area panel, the Add Vertex entry appears
- Click the first icon in the action bar in the upper right corner
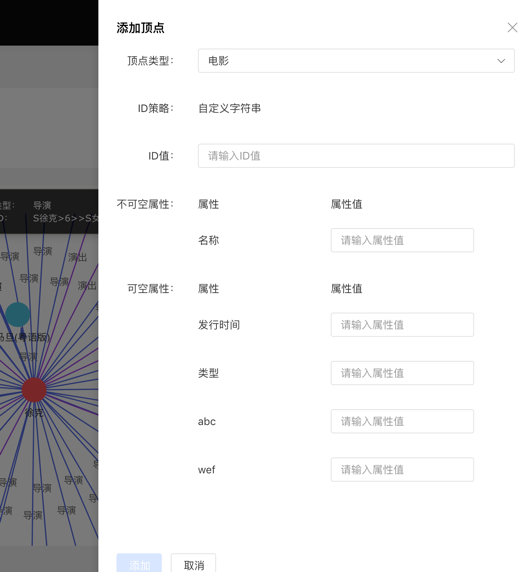
Complete the addition of vertices by selecting or filling in the vertex type, ID value, and attribute information.
The entry is as follows:
Add the vertex content as follows:
4.4.6.2 Add edge
Right-click a vertex in the graph result to add the outgoing or incoming edge of that point.
4.4.7 Execute the query of records and favorites
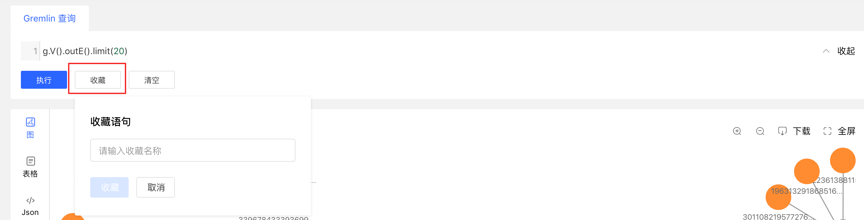
- Record each query record at the bottom of the graph area, including: query time, execution type, content, status, time-consuming, as well as [collection] and [load] operations, to achieve a comprehensive record of graph execution, with traces to follow, and Can quickly load and reuse execution content
- Provides the function of collecting sentences, which can be used to collect frequently used sentences, which is convenient for fast calling of high-frequency sentences.
4.5 Task Management
4.5.1 Module entry
Left navigation:
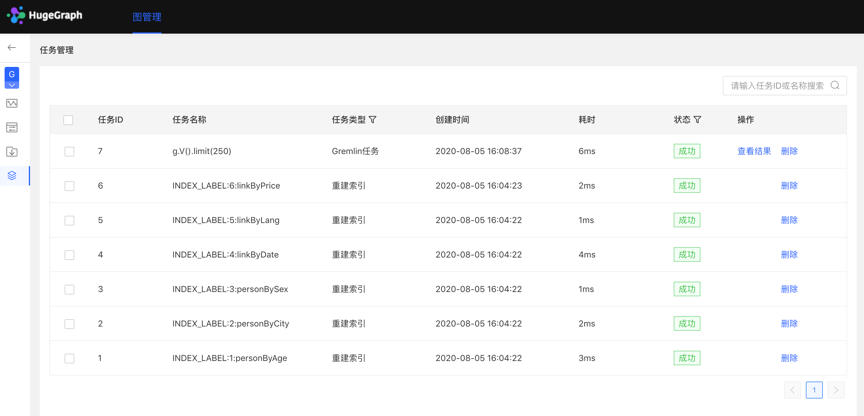
4.5.2 Task Management
- Provide unified management and result viewing of asynchronous tasks. There are 4 types of asynchronous tasks, namely:
- gremlin: Gremlin tasks
- algorithm: OLAP algorithm task
- remove_schema: remove metadata
- rebuild_index: rebuild the index
- The list displays the asynchronous task information of the current graph, including task ID, task name, task type, creation time, time-consuming, status, operation, and realizes the management of asynchronous tasks.
- Support filtering by task type and status
- Support searching for task ID and task name
- Asynchronous tasks can be deleted or deleted in batches
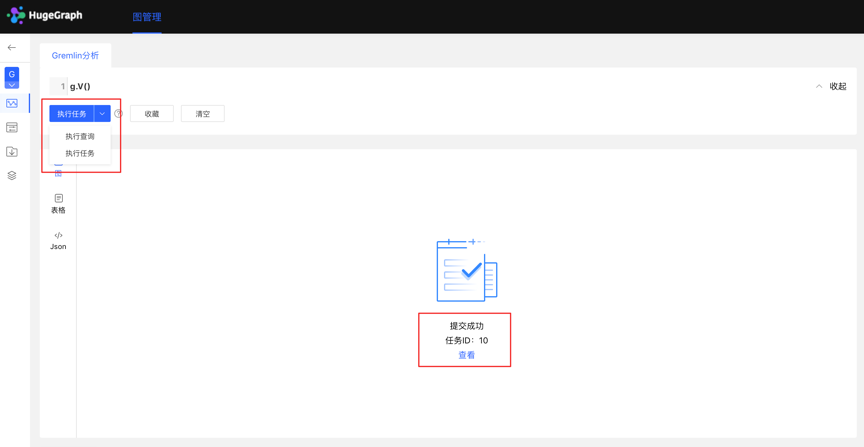
4.5.3 Gremlin asynchronous tasks
- Create a task
- The data analysis module currently supports two Gremlin operations, Gremlin query and Gremlin task; if the user switches to the Gremlin task, after clicking execute, an asynchronous task will be created in the asynchronous task center;
- Task submission
- After the task is submitted successfully, the graph area returns the submission result and task ID
- Mission details
- Provide [View] entry, you can jump to the task details to view the specific execution of the current task After jumping to the task center, the currently executing task line will be displayed directly
Click to view the entry to jump to the task management list, as follows:
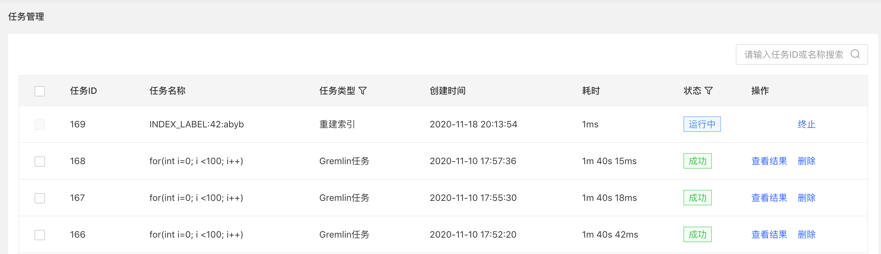
- View the results
- The results are displayed in the form of JSON
4.5.4 OLAP algorithm tasks
There is no visual OLAP algorithm execution on Hubble. You can call the RESTful API to perform OLAP algorithm tasks, find the corresponding tasks by ID in the task management, and view the progress and results.
4.5.5 Delete metadata, rebuild index
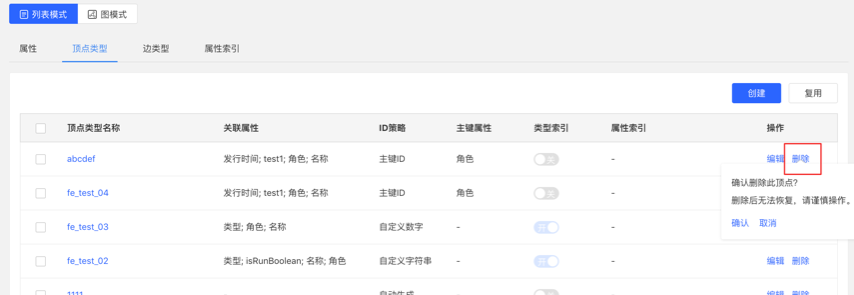
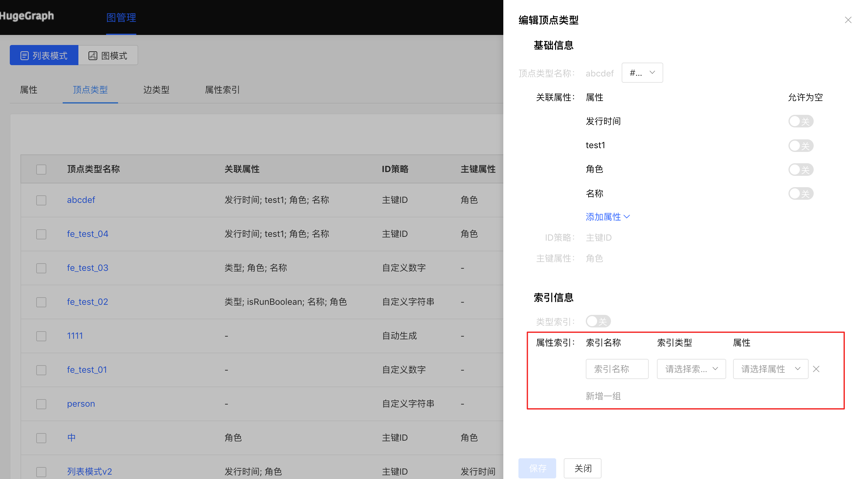
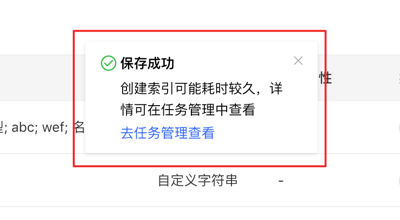
- Create a task
- In the metadata modeling module, when deleting metadata, an asynchronous task for deleting metadata can be created
- When editing an existing vertex/edge type operation, when adding an index, an asynchronous task of creating an index can be created
- Task details
- After confirming/saving, you can jump to the task center to view the details of the current task
5 Configuration
HugeGraph-Hubble can be configured through the conf/hugegraph-hubble.properties file.
5.1 Server Configuration
| Configuration Item | Default Value | Description |
|---|---|---|
hubble.host | 0.0.0.0 | The address that Hubble service binds to |
hubble.port | 8088 | The port that Hubble service listens on |
5.2 Server and PD
| Configuration | Default | Description |
|---|---|---|
pd.enabled | false | Whether to discover services through PD; keep false for a standalone Server |
server.direct_url | http://127.0.0.1:8080 | Server address used when pd.enabled=false |
pd.peers | 127.0.0.1:8686 | PD node address |
pd.server | 127.0.0.1:8620 | PD service address |
route.type | NODE_PORT | Service routing mode: NODE_PORT, DDS, or BOTH |
5.3 Gremlin Query Limits
These settings control query result limits to prevent memory issues:
| Configuration Item | Default Value | Description |
|---|---|---|
gremlin.suffix_limit | 250 | Maximum query suffix length |
gremlin.vertex_degree_limit | 100 | Maximum vertex degree to display |
gremlin.edges_total_limit | 500 | Maximum number of edges returned |
gremlin.batch_query_ids | 100 | ID batch query size |
3.2.2 - HugeGraph-Loader Quick Start
1 HugeGraph-Loader Overview
HugeGraph-Loader is the data import component of HugeGraph, which can convert data from various data sources into graph vertices and edges and import them into the graph database in batches.
Currently supported data sources include:
- Local disk file or directory, supports TEXT, CSV and JSON format files, supports compressed files
- HDFS file or directory supports compressed files
- Mainstream relational databases, such as MySQL, PostgreSQL, Oracle, SQL Server
Local disk files and HDFS files support resumable uploads.
It will be explained in detail below.
Note: HugeGraph-Loader requires HugeGraph Server service, please refer to HugeGraph-Server Quick Start to download and start Server
Testing Guide: For running HugeGraph-Loader tests locally, please refer to HugeGraph Toolchain Local Testing Guide
2 Get HugeGraph-Loader
HugeGraph-Loader is available in the following three ways:
- Use docker image (Convenient for Test/Dev)
- Download the compiled tarball
- Clone source code then compile and install
2.1 Use Docker image (Convenient for Test/Dev)
We can deploy the loader service using docker run -itd --name loader hugegraph/loader:1.5.0. For the data that needs to be loaded, it can be copied into the loader container either by mounting -v /path/to/data/file:/loader/file or by using docker cp.
Alternatively, to start the loader using docker-compose, the command is docker-compose up -d. An example of the docker-compose.yml is as follows:
The specific data loading process can be referenced under 4.5 User Docker to load data
Note:
The docker image of hugegraph-loader is a convenience release to start hugegraph-loader quickly, but not official distribution artifacts. You can find more details from ASF Release Distribution Policy.
Recommend to use
release tag(like1.5.0) for the stable version. Uselatesttag to experience the newest functions in development.
2.2 Download the compiled archive
Download the latest version of the HugeGraph-Toolchain release package:
2.3 Clone source code to compile and install
Clone the latest version of HugeGraph-Loader source package:
Due to the license limitation of the Oracle OJDBC, you need to manually install ojdbc to the local maven repository.
Visit the Oracle jdbc downloads page. Select Oracle Database 12c Release 2 (12.2.0.1) drivers, as shown in the following figure.
After opening the link, select “ojdbc8.jar”.
Install ojdbc8 to the local maven repository, enter the directory where ojdbc8.jar is located, and execute the following command.
Compile and generate tar package:
3 How to use
The basic process of using HugeGraph-Loader is divided into the following steps:
- Write graph schema
- Prepare data files
- Write input source map files
- Execute command import
3.1 Construct graph schema
This step is the modeling process. Users need to have a clear idea of their existing data and the graph model they want to create, and then write the schema to build the graph model.
For example, if you want to create a graph with two types of vertices and two types of edges, the vertices are “people” and “software”, the edges are “people know people” and “people create software”, and these vertices and edges have some attributes, For example, the vertex “person” has: “name”, “age” and other attributes, “Software” includes: “name”, “sale price” and other attributes; side “knowledge” includes: “date” attribute and so on.
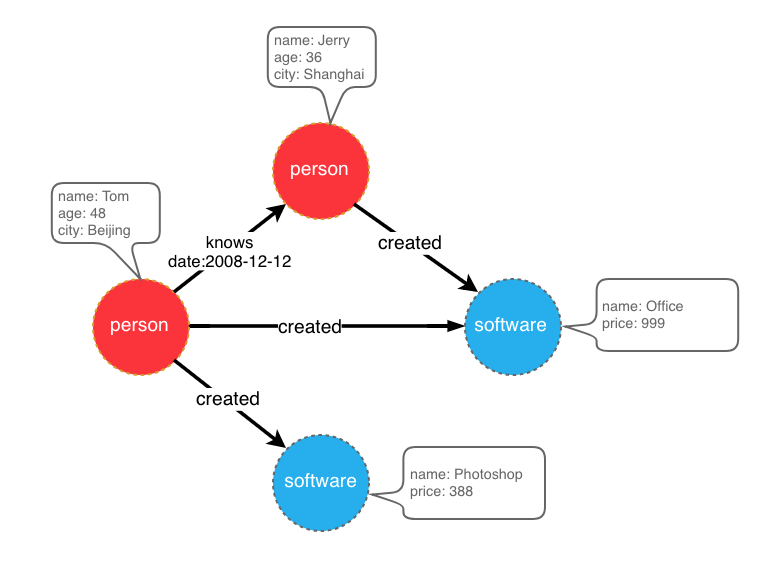
graph model example
After designing the graph model, we can use groovy to write the definition of schema and save it to a file, here named schema.groovy.
Please refer to the corresponding section in hugegraph-client for the detailed description of the schema.
3.2 Prepare data
The data sources currently supported by HugeGraph-Loader include:
- local disk file or directory
- HDFS file or directory
- Partial relational database
- Kafka topic
3.2.1 Data source structure
3.2.1.1 Local disk file or directory
The user can specify a local disk file as the data source. If the data is scattered in multiple files, a certain directory is also supported as the data source, but multiple directories are not supported as the data source for the time being.
For example, my data is scattered in multiple files, part-0, part-1 … part-n. To perform the import, it must be ensured that they are placed in one directory. Then in the loader’s mapping file, specify path as the directory.
Supported file formats include:
- TEXT
- CSV
- JSON
TEXT is a text file with custom delimiters, the first line is usually the header, and the name of each column is recorded, and no header line is allowed (specified in the mapping file). Each remaining row represents a record, which will be converted into a vertex/edge; each column of the row corresponds to a field, which will be converted into the id, label or attribute of the vertex/edge;
An example is as follows:
CSV is a TEXT file with commas , as delimiters. When a column value itself contains a comma, the column value needs to be enclosed in double quotes, for example:
The JSON file requires that each line is a JSON string, and the format of each line needs to be consistent.
3.2.1.2 HDFS file or directory
Users can also specify HDFS files or directories as data sources, all of the above requirements for local disk files or directories apply here. In addition, since HDFS usually stores compressed files, loader also provides support for compressed files, and local disk file or directory also supports compressed files.
Currently supported compressed file types include: GZIP, BZ2, XZ, LZMA, SNAPPY_RAW, SNAPPY_FRAMED, Z, DEFLATE, LZ4_BLOCK, LZ4_FRAMED, ORC, and PARQUET.
3.2.1.3 Mainstream relational database
The loader also supports some relational databases as data sources, and currently supports MySQL, PostgreSQL, Oracle, and SQL Server.
However, the requirements for the table structure are relatively strict at present. If association query needs to be done during the import process, such a table structure is not allowed. The associated query means: after reading a row of the table, it is found that the value of a certain column cannot be used directly (such as a foreign key), and you need to do another query to determine the true value of the column.
For example, Suppose there are three tables, person, software and created
If the id strategy of person or software is specified as PRIMARY_KEY when modeling (schema), choose name as the primary key (note: this is the concept of vertex-label in hugegraph), when importing edge data, the source vertex and target need to be spliced out. For the id of the vertex, you must go to the person/software table with p_id/s_id to find the corresponding name. In the case of the schema that requires additional query, the loader does not support it temporarily. In this case, the following two methods can be used instead:
- The id strategy of person and software is still specified as PRIMARY_KEY, but the id column of the person table and software table is used as the primary key attribute of the vertex, so that the id can be generated by directly splicing p_id and s_id with the label of the vertex when importing an edge;
- Specify the id policy of person and software as CUSTOMIZE, and then directly use the id column of the person table and the software table as the vertex id, so that p_id and s_id can be used directly when importing edges;
The key point is to make the edge use p_id and s_id directly, don’t check it again.
3.2.2 Prepare vertex and edge data
3.2.2.1 Vertex Data
The vertex data file consists of data line by line. Generally, each line is used as a vertex, and each column is used as a vertex attribute. The following description uses CSV format as an example.
- person vertex data (the data itself does not contain a header)
- software vertex data (the data itself contains the header)
3.2.2.2 Edge data
The edge data file consists of data line by line. Generally, each line is used as an edge. Some columns are used as the IDs of the source and target vertices, and other columns are used as edge attributes. The following uses JSON format as an example.
- knows edge data
- created edge data
3.3 Write data source mapping file
3.3.1 Mapping file overview
The mapping file of the input source is used to describe how to establish the mapping relationship between the input source data and the vertex type/edge type of the graph. It is organized in JSON format and consists of multiple mapping blocks, each of which is responsible for mapping an input source. Mapped to vertices and edges.
Specifically, each mapping block contains an input source and multiple vertex mapping and edge mapping blocks, and the input source block corresponds to the local disk file or directory, HDFS file or directory and relational database are responsible for describing the basic information of the data source, such as where the data is, what format, what is the delimiter, etc. The vertex map/edge map is bound to the input source, which columns of the input source can be selected, which columns are used as ids, which columns are used as attributes, and what attributes are mapped to each column, the values of the columns are mapped to what values of attributes, and so on.
In the simplest terms, each mapping block describes: where is the file to be imported, which type of vertices/edges each line of the file is to be used as which columns of the file need to be imported, and the corresponding vertices/edges of these columns. what properties, etc.
Note: The format of the mapping file before version 0.11.0 and the format after 0.11.0 has changed greatly. For the convenience of expression, the mapping file (format) before 0.11.0 is called version 1.0, and the version after 0.11.0 is version 2.0. And unless otherwise specified, the “map file” refers to version 2.0.
Two versions of the mapping file are given directly here (the above graph model and data file are described)
The 1.0 version of the mapping file is centered on the vertex and edge, and sets the input source; while the 2.0 version is centered on the input source, and sets the vertex and edge mapping. Some input sources (such as a file) can generate both vertices and edges. If you write in the 1.0 format, you need to write an input block in each of the vertex and edge mapping blocks. The two input blocks are exactly the same; and the 2.0 version only needs to write input once. Therefore, compared with version 1.0, version 2.0 can save some repetitive writing of input.
In the bin directory of hugegraph-loader-{version}, there is a script tool mapping-convert.sh that can directly convert the mapping file of version 1.0 to version 2.0. The usage is as follows:
A struct-v2.json will be generated in the same directory as struct.json.
3.3.2 Input Source
Input sources are currently divided into five categories: FILE, HDFS, JDBC, KAFKA and GRAPH, which are distinguished by the type node. We call them local file input sources, HDFS input sources, JDBC input sources, KAFKA input sources and GRAPH input source, which are described below.
3.3.2.1 Local file input source
- id: The id of the input source. This field is used to support some internal functions. It is not required (it will be automatically generated if it is not filled in). It is strongly recommended to write it, which is very helpful for debugging;
- skip: whether to skip the input source, because the JSON file cannot add comments, if you do not want to import an input source during a certain import, but do not want to delete the configuration of the input source, you can set it to true to skip it, the default is false, not required;
- input: input source map block, composite structure
- type: an input source type, file or FILE must be filled;
- path: the path of the local file or directory, the absolute path or the relative path relative to the mapping file, it is recommended to use the absolute path, required;
- file_filter: filter files with compound conditions from
path, compound structure, currently only supports configuration extensions, represented by child nodeextensions, the default is “*”, which means to keep all files; - format: the format of the local file, the optional values are CSV, TEXT and JSON, which must be uppercase and required;
- header: the column name of each column of the file, if not specified, the first line of the data file will be used as the header; when the file itself has a header and the header is specified, the first line of the file will be treated as a normal data line; JSON The file does not need to specify a header, optional;
- delimiter: The column delimiter of the file line, the default is comma
","as the delimiter, theJSONfile does not need to be specified, optional; - charset: the encoded character set of the file, the default is
UTF-8, optional; - date_format: custom date format, the default value is yyyy-MM-dd HH:mm:ss, optional; if the date is presented in the form of a timestamp, this item must be written as
timestamp(fixed writing); - time_zone: Set which time zone the date data is in, the default value is
GMT+8, optional; - skipped_line: The line to be skipped, compound structure, currently only the regular expression of the line to be skipped can be configured, described by the child node
regex, no line is skipped by default, optional; - compression: The compression format of the file, the optional values are NONE, GZIP, BZ2, XZ, LZMA, SNAPPY_RAW, SNAPPY_FRAMED, Z, DEFLATE, LZ4_BLOCK, LZ4_FRAMED, ORC and PARQUET, the default is NONE, which means a non-compressed file, optional;
- list_format: When a column of the file (non-JSON) is a collection structure (the Cardinality of the PropertyKey in the corresponding figure is Set or List), you can use this item to set the start character, separator, and end character of the column, compound structure :
- start_symbol: The start character of the collection structure column (the default value is
[, JSON format currently does not support specification) - elem_delimiter: the delimiter of the collection structure column (the default value is
|, JSON format currently only supports native,delimiter) - end_symbol: the end character of the collection structure column (the default value is
], the JSON format does not currently support specification)
- start_symbol: The start character of the collection structure column (the default value is
3.3.2.2 HDFS input source
The nodes and meanings of the above local file input source are basically applicable here. Only the different and unique nodes of the HDFS input source are listed below.
- type: input source type, must fill in hdfs or HDFS, required;
- path: the path of the HDFS file or directory, it must be the absolute path of HDFS, required;
- core_site_path: the path of the core-site.xml file of the HDFS cluster, the key point is to specify the address of the NameNode (
fs.default.name) and the implementation of the file system (fs.hdfs.impl);
3.3.2.3 JDBC input source
As mentioned above, it supports multiple relational databases, but because their mapping structures are very similar, they are collectively referred to as JDBC input sources, and then use the vendor node to distinguish different databases.
- type: input source type, must fill in jdbc or JDBC, required;
- vendor: database type, optional options are [MySQL, PostgreSQL, Oracle, SQLServer], case-insensitive, required;
- driver: the type of driver used by jdbc, required;
- url: the url of the database that jdbc wants to connect to, required;
- database: the name of the database to be connected, required;
- schema: The name of the schema to be connected, different databases have different requirements, and the details are explained below;
- table: the name of the table to be connected, at least one of
tableorcustom_sqlis required; - custom_sql: custom SQL statement, at least one of
tableorcustom_sqlis required; - username: username to connect to the database, required;
- password: password for connecting to the database, required;
- batch_size: The size of one page when obtaining table data by page, the default is 500, optional;
MYSQL
| Node | Fixed value or common value |
|---|---|
| vendor | MYSQL |
| driver | com.mysql.cj.jdbc.Driver |
| url | jdbc:mysql://127.0.0.1:3306 |
schema: nullable, if filled in, it must be the same as the value of database
POSTGRESQL
| Node | Fixed value or common value |
|---|---|
| vendor | POSTGRESQL |
| driver | org.postgresql.Driver |
| url | jdbc:postgresql://127.0.0.1:5432 |
schema: nullable, default is “public”
ORACLE
| Node | Fixed value or common value |
|---|---|
| vendor | ORACLE |
| driver | oracle.jdbc.driver.OracleDriver |
| url | jdbc:oracle:thin:@127.0.0.1:1521 |
schema: nullable, the default value is the same as the username
SQLSERVER
| Node | Fixed value or common value |
|---|---|
| vendor | SQLSERVER |
| driver | com.microsoft.sqlserver.jdbc.SQLServerDriver |
| url | jdbc:sqlserver://127.0.0.1:1433 |
schema: required
3.3.2.4 Kafka input source
- type: input source type,
kafkaorKAFKA, required; - bootstrap_server: set the list of kafka bootstrap servers;
- topic: the topic to subscribe to;
- group: group of Kafka consumers;
- from_beginning: set whether to read from the beginning;
- format: format of the local file, options are CSV, TEXT and JSON, must be uppercase, required;
- header: column name of each column of the file, if not specified, the first line of the data file will be used as the header; when the file itself has a header and the header is specified, the first line of the file will be treated as an ordinary data line; JSON files do not need to specify the header, optional;
- delimiter: delimiter of the file line, default is comma “,” as delimiter, JSON files do not need to specify, optional;
- charset: encoding charset of the file, default is UTF-8, optional;
- date_format: customized date format, default value is yyyy-MM-dd HH:mm:ss, optional; if the date is presented in the form of timestamp, this item must be written as timestamp (fixed);
- extra_date_formats: a customized list of another date formats, empty by default, optional; each item in the list is an alternate date format to the date_format specified date format;
- time_zone: set which time zone the date data is in, default is GMT+8, optional;
- skipped_line: the line you want to skip, composite structure, currently can only configure the regular expression of the line to be skipped, described by the child node regex, the default is not to skip any line, optional;
- early_stop: the record pulled from Kafka broker at a certain time is empty, stop the task, default is false, only for debugging, optional;
3.3.2.5 GRAPH input Source
- type: Data source type; must be filled in as
graphorGRAPH(required); - graphspace: Source graphSpace name; default is
DEFAULT; - graph: Source graph name (required);
- username: HugeGraph username;
- password: HugeGraph password;
- selected_vertices: Filtering rules for vertices to be synchronized;
- ignored_vertices: Filtering rules for vertices to be ignored;
- selected_edges: Filtering rules for edges to be synchronized;
- ignored_edges: Filtering rules for edges to be ignored;
- pd-peers: HugeGraph-PD node addresses;
- meta-endpoints: Meta service endpoints of the source cluster;
- cluster: Source cluster name;
- batch_size: Batch size for reading data from the source graph; default is 500;
3.3.3 Vertex and Edge Mapping
The nodes of vertex and edge mapping (a key in the JSON file) have a lot of the same parts. The same parts are introduced first, and then the unique nodes of vertex map and edge map are introduced respectively.
Nodes of the same section
- label:
labelto which the vertex/edge data to be imported belongs, required; - field_mapping: Map the column name of the input source column to the attribute name of the vertex/edge, optional;
- value_mapping: map the data value of the input source to the attribute value of the vertex/edge, optional;
- selected: select some columns to insert, other unselected ones are not inserted, cannot exist at the same time as
ignored, optional; - ignored: ignore some columns so that they do not participate in insertion, cannot exist at the same time as
selected, optional; - null_values: You can specify some strings to represent null values, such as “NULL”. If the vertex/edge attribute corresponding to this column is also a nullable attribute, the value of this attribute will not be set when constructing the vertex/edge, optional ;
- update_strategies: If the data needs to be updated in batches in a specific way, you can specify a specific update strategy for each attribute (see below for details), optional;
- unfold: Whether to unfold the column, each unfolded column will form a row with other columns, which is equivalent to unfolding into multiple rows; for example, the value of a certain column (id column) of the file is
[1,2,3], The values of other columns are18,Beijing. When unfold is set, this row will become 3 rows, namely:1,18,Beijing,2,18,Beijingand3,18, Beijing. Note that this will only expand the column selected as id. Default false, optional;
Update strategy supports 8 types: (requires all uppercase)
- Value accumulation:
SUM - Take the greater of the two numbers/dates:
BIGGER - Take the smaller of two numbers/dates:
SMALLER - Set property takes union:
UNION - Set attribute intersection:
INTERSECTION - List attribute append element:
APPEND - List/Set attribute delete element:
ELIMINATE - Override an existing property:
OVERRIDE
Note: If the newly imported attribute value is empty, the existing old data will be used instead of the empty value. For the effect, please refer to the following example
Note : After adopting the batch update strategy, the number of disk read requests will increase significantly, and the import speed will be several times slower than that of pure write coverage (at this time HDD disk [IOPS](https://en.wikipedia .org/wiki/IOPS) will be the bottleneck, SSD is recommended for speed)
Unique Nodes for Vertex Maps
- id: Specify a column as the id column of the vertex. When the vertex id policy is
CUSTOMIZE, it is required; when the id policy isPRIMARY_KEY, it must be empty;
Unique Nodes for Edge Maps
- source: Select certain columns of the input source as the id column of source vertex. When the id policy of the source vertex is
CUSTOMIZE, a certain column must be specified as the id column of the vertex; when the id policy of the source vertex isWhen PRIMARY_KEY, one or more columns must be specified for splicing the id of the generated vertex, that is, no matter which id strategy is used, this item is required; - target: Specify certain columns as the id columns of target vertex, similar to source, so I won’t repeat them;
- unfold_source: Whether to unfold the source column of the file, the effect is similar to that in the vertex map, and will not be repeated;
- unfold_target: Whether to unfold the target column of the file, the effect is similar to that in the vertex mapping, and will not be repeated;
3.4 Execute command import
After preparing the graph model, data file, and input source mapping relationship file, the data file can be imported into the graph database.
The import process is controlled by commands submitted by the user, and the user can control the specific process of execution through different parameters.
3.4.1 Parameter description
| Parameter | Default value | Required or not | Description |
|---|---|---|---|
-f or --file | Y | Path to configure script | |
-g or --graph | hugegraph | Graph name | |
--graphspace | DEFAULT | Graph space name | |
-s or --schema | Schema file path; optional when the Schema already exists | ||
-h or --host or -i | localhost | Address of HugeGraphServer | |
-p or --port | 8080 | Port number of HugeGraphServer | |
--username | null | When HugeGraphServer enables permission authentication, the username of the current graph | |
--password | null | When HugeGraphServer enables permission authentication, the password of the current graph | |
--create-graph | false | Whether to automatically create the graph if it does not exist | |
--token | null | When HugeGraphServer has enabled authorization authentication, the token of the current graph | |
--protocol | http | Protocol for sending requests to the server, optional http or https | |
--pd-peers | PD service node addresses | ||
--pd-token | Token for accessing PD service | ||
--meta-endpoints | Meta information storage service addresses | ||
--direct | false | Whether to directly connect to HugeGraph-Store | |
--route-type | NODE_PORT | Route selection method (optional values: NODE_PORT / DDS / BOTH) | |
--cluster | hg | Cluster name | |
--trust-store-file | When the request protocol is https, the client’s certificate file path | ||
--trust-store-password | When the request protocol is https, the client certificate password | ||
--clear-all-data | false | Whether to clear the original data on the server before importing data | |
--clear-timeout | 240 | Timeout for clearing the original data on the server before importing data | |
--incremental-mode | false | Whether to use the breakpoint resume mode; only input sources FILE and HDFS support this mode. Enabling this mode allows starting the import from where the last import stopped | |
--failure-mode | false | When failure mode is true, previously failed data will be imported. Generally, the failed data file needs to be manually corrected and edited before re-importing | |
--batch-insert-threads | CPUs | Batch insert thread pool size (CPUs is the number of logical cores available to the current OS) | |
--single-insert-threads | 8 | Size of single insert thread pool | |
--max-conn | 4 * CPUs | The maximum number of HTTP connections between HugeClient and HugeGraphServer; it is recommended to adjust this when adjusting threads | |
--max-conn-per-route | 2 * CPUs | The maximum number of HTTP connections for each route between HugeClient and HugeGraphServer; it is recommended to adjust this item when adjusting threads | |
--batch-size | 500 | The number of data items in each batch when importing data | |
--max-parse-errors | 1 | The maximum number of data parsing errors allowed (per line); the program exits when this value is reached | |
--max-insert-errors | 500 | The maximum number of data insertion errors allowed (per row); the program exits when this value is reached | |
--timeout | 60 | Timeout (seconds) for insert result return | |
--shutdown-timeout | 10 | Waiting time for multithreading to stop (seconds) | |
--retry-times | 3 | Maximum number of retries after a timeout | |
--retry-interval | 10 | Interval before retry (seconds) | |
--check-vertex | false | Whether to check if the vertices connected by the edge exist when inserting the edge | |
--print-progress | true | Whether to print the number of imported items in real time on the console | |
--dry-run | false | Enable this mode to only parse data without importing; usually used for testing | |
--help or -help | false | Print help information | |
--parser-threads or --parallel-count | max(2,CPUs/2) | Number of parallel read pipelines; --parallel-count is deprecated | |
--start-file | 0 | Start file index for partial loading | |
--end-file | -1 | End file index for partial loading | |
--scatter-sources | false | Scatter multiple sources for I/O optimization | |
--cdc-flush-interval | 30000 | The flush interval for Flink CDC | |
--cdc-sink-parallelism | 1 | The sink parallelism for Flink CDC | |
--max-read-errors | 1 | The maximum number of read error lines before exiting | |
--max-read-lines | -1L | The maximum number of read lines, task stops when reached | |
--test-mode | false | Whether the loader works in test mode | |
--use-prefilter | false | Whether to filter vertex in advance | |
--short-id | Mapping customized ID to shorter ID | ||
--vertex-edge-limit | -1L | The maximum number of vertex’s edges | |
--sink-type | true | Sink to different storage type switch | |
--vertex-partitions | 64 | The number of partitions of the HBase vertex table | |
--edge-partitions | 64 | The number of partitions of the HBase edge table | |
--vertex-table-name | HBase vertex table name | ||
--edge-table-name | HBase edge table name | ||
--hbase-zk-quorum | HBase ZooKeeper quorum | ||
--hbase-zk-port | HBase ZooKeeper port | ||
--hbase-zk-parent | HBase ZooKeeper parent | ||
--restore | false | Set graph mode to RESTORING | |
--backend | hstore | The backend store type when creating graph if not exists | |
--serializer | binary | The serializer type when creating graph if not exists | |
--scheduler-type | distributed | The task scheduler type when creating graph if not exists | |
--batch-failure-fallback | true | Whether to fallback to single insert when batch insert fails |
3.4.2 Breakpoint Continuation Mode
Usually, the Loader task takes a long time to execute. If the import interrupt process exits for some reason, and next time you want to continue the import from the interrupted point, this is the scenario of using breakpoint continuation.
The user sets the command line parameter –incremental-mode to true to open the breakpoint resume mode. The key to breakpoint continuation lies in the progress file. When the import process exits, the import progress at the time of exit will be recorded.
Recorded in the progress file, the progress file is located in the ${struct} directory, the file name is like load-progress ${date}, ${struct} is the prefix of the mapping file, and ${date} is the start of the import
moment. For example, for an import task started at 2019-10-10 12:30:30, the mapping file used is struct-example.json, then the path of the progress file is the same as struct-example.json
Sibling struct-example/load-progress 2019-10-10 12:30:30.
Note: The generation of progress files is independent of whether –incremental-mode is turned on or not, and a progress file is generated at the end of each import.
If the data file formats are all legal and the import task is stopped by the user (CTRL + C or kill, kill -9 is not supported), that is to say, if there is no error record, the next import only needs to be set to Continue for the breakpoint.
But if the limit of –max-parse-errors or –max-insert-errors is reached because too much data is invalid or network abnormality is reached, Loader will record these original rows that failed to insert into In the failed file, after the user modifies the data lines in the failed file, set –reload-failure to true to import these “failed files” as input sources (does not affect the normal file import), Of course, if there is still a problem with the modified data line, it will be logged again to the failure file (don’t worry about duplicate lines).
Each vertex map or edge map will generate its own failure file when data insertion fails. The failure file is divided into a parsing failure file (suffix .parse-error) and an insertion failure file (suffix .insert-error).
They are stored in the ${struct}/current directory. For example, there is a vertex mapping person, and an edge mapping knows in the mapping file, each of which has some error lines. When the Loader exits, you will see the following files in the ${struct}/current directory:
- person-b4cd32ab.parse-error: Vertex map person parses wrong data
- person-b4cd32ab.insert-error: Vertex map person inserts wrong data
- knows-eb6b2bac.parse-error: edge map knows parses wrong data
- knows-eb6b2bac.insert-error: edge map knows inserts wrong data
.parse-error and .insert-error do not always exist together. Only lines with parsing errors will have .parse-error files, and only lines with insertion errors will have .insert-error files.
3.4.3 logs directory file description
The log and error data during program execution will be written into the hugegraph-loader.log file.
3.4.4 Execute command
Run bin/hugegraph-loader and pass in parameters
4 Complete example
Given below is an example in the example directory of the hugegraph-loader package. (GitHub address)
4.1 Prepare data
Vertex file: example/file/vertex_person.csv
Vertex file: example/file/vertex_software.txt
Edge file: example/file/edge_knows.json
Edge file: example/file/edge_created.json
4.2 Write schema
4.3 Write the input source mapping file example/file/struct.json
4.4 Command to import
After the import is complete, statistics similar to the following will appear:
4.5 Use Docker to load data
4.5.1 Use docker exec to load data directly
4.5.1.1 Prepare data
If you just want to try out the loader, you can import the built-in example dataset without needing to prepare additional data yourself.
If using custom data, before importing data with the loader, we need to copy the data into the container.
First, following the steps in 4.1–4.3, we can prepare the data and then use docker cp to copy the prepared data into the loader container.
Suppose we’ve prepared the corresponding dataset following the above steps, stored in the hugegraph-dataset folder with the following file structure:
Copy the files into the container.
4.5.1.2 Data loading
Taking the built-in example dataset as an example, we can use the following command to load the data.
If you need to import your custom dataset, you need to modify the paths for -f (data script) and -s (schema) configurations.
You can refer to 3.4.1-Parameter description for the rest of the parameters.
If loading a custom dataset, following the previous example, you would use:
If
loaderandserverare in the same Docker network, you can specify-h {server_container_name}; otherwise, you need to specify the IP of theserverhost (in our example,server_container_nameisserver).
Then we can see the result:
You can also use curl or hubble to observe the import result. Here’s an example using curl:
If you want to check the import result of edges, you can use curl "http://localhost:8080/graphs/hugegraph/graph/edges" | gunzip.
4.5.2 Enter the docker container to load data
Besides using docker exec directly for data import, we can also enter the container for data loading. The basic process is similar to 4.5.1.
Enter the container by docker exec -it loader bash and execute the command:
The results of the execution will be similar to those shown in 4.5.1.
4.6 Import data by spark-loader
The current source uses Spark 3.2.2 and Scala 2.12. Other combinations need independent verification.
The parameters of spark-loader are divided into two parts. Note: Because the abbreviations of
these two-parameter names have overlapping parts, please use the full name of the parameter.
And there is no need to guarantee the order between the two parameters.
- hugegraph parameters (Reference: hugegraph-loader parameter description )
- Spark task submission parameters (Reference: Submitting Applications)
Example:
3.2.3 - HugeGraph-Tools Quick Start
1 HugeGraph-Tools Overview
HugeGraph-Tools is an automated deployment, management and backup/restore component of HugeGraph.
Testing Guide: For running HugeGraph-Tools tests locally, please refer to HugeGraph Toolchain Local Testing Guide
2 Get HugeGraph-Tools
HugeGraph-Tools is included in the Toolchain distribution. You can download the distribution or build it from source.
- Download the compiled tarball
- Clone source code then compile and install
2.1 Download the compiled archive
Download the latest version of the HugeGraph-Toolchain package:
2.2 Clone source code to compile and install
Please ensure that the wget command is installed before compiling the source code
Download the latest version of the HugeGraph-Tools source package:
Compile and generate tar package:
Generate tar package hugegraph-tools-${version}.tar.gz
3 How to use
3.1 Function overview
After decompression, enter the hugegraph-tools directory, you can use bin/hugegraph or bin/hugegraph help to view the usage information. mainly divided:
- Graph management type, graph-mode-set, graph-mode-get, graph-list, graph-get, graph-clear, graph-create, graph-clone and graph-drop
- Asynchronous task management type, task-list, task-get, task-delete, task-cancel and task-clear
- Gremlin type, gremlin-execute and gremlin-schedule
- Backup/Restore type, backup, restore, migrate, schedule-backup and dump
- Authentication data backup/restore type, auth-backup and auth-restore
- Install deployment type, deploy, clear, start-all and stop-all
3.2 [options]-Global Variable
options is a global variable of HugeGraph-Tools, which can be configured in hugegraph-tools/bin/hugegraph, including:
- –graph,HugeGraph-Tools The name of the graph to operate on, the default value is hugegraph
- –url,The service address of HugeGraph-Server, the default is http://127.0.0.1:8080
- –user,When HugeGraph-Server opens authentication, pass username
- –password,When HugeGraph-Server opens authentication, pass the user’s password
- –timeout,Timeout when connecting to HugeGraph-Server, the default is 30s
- –protocol, connection protocol, either http or https; the default is http
- –trust-store-file,The path of the certificate file, when –url uses https, the truststore file used by HugeGraph-Client, the default is empty, which means using the built-in truststore file conf/hugegraph.truststore of hugegraph-tools
- –trust-store-password,The password of the certificate file, when –url uses https, the password of the truststore used by HugeGraph-Client, the default is empty, representing the password of the built-in truststore file of hugegraph-tools
The above global variables can also be set through environment variables. One way is to use export on the command line to set temporary environment variables, which are valid until the command line is closed
| Global Variable | Environment Variable | Example |
|---|---|---|
| –url | HUGEGRAPH_URL | export HUGEGRAPH_URL=http://127.0.0.1:8080 |
| –graph | HUGEGRAPH_GRAPH | export HUGEGRAPH_GRAPH=hugegraph |
| –user | HUGEGRAPH_USERNAME | export HUGEGRAPH_USERNAME=admin |
| –password | HUGEGRAPH_PASSWORD | export HUGEGRAPH_PASSWORD=test |
| –timeout | HUGEGRAPH_TIMEOUT | export HUGEGRAPH_TIMEOUT=30 |
| –trust-store-file | HUGEGRAPH_TRUST_STORE_FILE | export HUGEGRAPH_TRUST_STORE_FILE=/tmp/trust-store |
| –trust-store-password | HUGEGRAPH_TRUST_STORE_PASSWORD | export HUGEGRAPH_TRUST_STORE_PASSWORD=xxxx |
Another way is to set the environment variable in the bin/hugegraph script:
3.3 Graph Management Type, graph-mode-set, graph-mode-get, graph-list, graph-get, graph-clear, graph-create, graph-clone and graph-drop
- graph-mode-set, set graph restore mode
- –graph-mode or -m, required, specifies the mode to be set, legal values include [NONE, RESTORING, MERGING, LOADING]
- graph-mode-get, get graph restore mode
- graph-list, list all graphs in a HugeGraph-Server
- graph-get, get a graph and its storage backend type
- graph-clear, clear all schema and data of a graph
- –confirm-message or -c, required, delete confirmation information, manual input is required, double confirmation to prevent accidental deletion, “I’m sure to delete all data”, including double quotes
- graph-create, create a new graph with configuration file
- –name or -n, optional, the name of the new graph, default is hugegraph
- –file or -f, required, the path to the graph configuration file
- graph-clone, clone an existing graph
- –name or -n, optional, the name of the cloned graph, default is hugegraph
- –clone-graph-name, optional, the name of the source graph to clone from, default is hugegraph
- graph-drop, drop a graph (different from graph-clear, this completely removes the graph)
- –confirm-message or -c, required, confirmation message “I’m sure to drop the graph”, including double quotes
When you need to restore the backup graph to a new graph, you need to set the graph mode to RESTORING mode; when you need to merge the backup graph into an existing graph, you need to first set the graph mode to MERGING model.
3.4 Asynchronous task management Type,task-list、task-get and task-delete
- task-list,List the asynchronous tasks in a graph, which can be filtered according to the status of the tasks
- –status,Optional, specify the status of the task to view, i.e. filter tasks by status
- –limit,Optional, specify the number of tasks to be obtained, the default is -1, which means to obtain all eligible tasks
- task-get,Get detailed information about an asynchronous task
- –task-id,Required, specifies the ID of the asynchronous task
- task-delete,Delete information about an asynchronous task
- –task-id,Required, specifies the ID of the asynchronous task
- task-cancel,Cancel the execution of an asynchronous task
- –task-id,ID of the asynchronous task to cancel
- task-clear,Clean up completed asynchronous tasks
- –force,Optional. When set, it means to clean up all asynchronous tasks. Unfinished ones are canceled first, and then all asynchronous tasks are cleared. By default, only completed asynchronous tasks are cleaned up
3.5 Gremlin Type,gremlin-execute and gremlin-schedule
⚠️ SEC Reminder: The execution of Gremlin depends on the actual logic of the statements, which may involve scenarios such as large-scale data modification and high-risk system calls with potential implicit hazards. Please use this tool only in secure and trusted network environments. It is imperative to configure and secure HugeGraph-Server with the Authentication System (Auth) and an IP Whitelist to restrict execution requests on the server side. Never hand over the tool or expose the execution entry to unauthorized personnel.
- gremlin-execute, send Gremlin statements to HugeGraph-Server to execute query or modification operations, execute synchronously, and return results after completion
- –file or -f, specify the script file to execute, UTF-8 encoding, mutually exclusive with –script
- –script or -s, specifies the script string to execute, mutually exclusive with –file
- –aliases or -a, Gremlin alias settings, the format is: key1=value1,key2=value2,…
- –bindings or -b, Gremlin binding settings, the format is: key1=value1,key2=value2,…
- –language or -l, the language of the Gremlin script, the default is gremlin-groovy
–file and –script are mutually exclusive, one of them must be set
- gremlin-schedule, send Gremlin statements to HugeGraph-Server to perform query or modification operations, asynchronous execution, and return the asynchronous task id immediately after the task is submitted
- –file or -f, specify the script file to execute, UTF-8 encoding, mutually exclusive with –script
- –script or -s, specifies the script string to execute, mutually exclusive with –file
- –bindings or -b, Gremlin binding settings, the format is: key1=value1,key2=value2,…
- –language or -l, the language of the Gremlin script, the default is gremlin-groovy
–file and –script are mutually exclusive, one of them must be set
3.6 Backup/Restore Type
- backup, back up the schema or data in a certain graph out of the HugeGraph system, and store it on the local disk or HDFS in the form of JSON
- –format, the backup format, optional values include [json, text], the default is json
- –all-properties, whether to back up all properties of vertices/edges, only valid when –format is text, default false
- –label, the type of vertices/edges to be backed up, only valid when –format is text, only valid when backing up vertices or edges
- –properties, properties of vertices/edges to be backed up, separated by commas, only valid when –format is text, valid only when backing up vertices or edges
- –compress, whether to compress data during backup, the default is true
- –directory or -d, the directory to store schema or data, the default is ‘./{graphName}’ for local directory, and ‘{fs.default.name}/{graphName}’ for HDFS
- –huge-types or -t, the data types to be backed up, separated by commas, the optional value is ‘all’ or a combination of one or more [vertex, edge, vertex_label, edge_label, property_key, index_label], ‘all’ Represents all 6 types, namely vertices, edges and all schemas
- –log or -l, specify the log directory, the default is the current directory
- –retry, specify the number of failed retries, the default is 3
- –thread-num or -T, the number of threads to use, default is Math.min(10, Math.max(4, CPUs / 2))
- –split-size or -s, specifies the size of splitting vertices or edges when backing up, the default is 1048576
- -D, use the mode of -Dkey=value to specify dynamic parameters, and specify HDFS configuration items when backing up data to HDFS, for example: -Dfs.default.name=hdfs://localhost:9000
- restore, restore schema or data stored in JSON format to a new graph (RESTORING mode) or merge into an existing graph (MERGING mode)
- –directory or -d, the directory to store schema or data, the default is ‘./{graphName}’ for local directory, and ‘{fs.default.name}/{graphName}’ for HDFS
- –clean, whether to delete the directory specified by –directory after the recovery map is completed, the default is false
- –huge-types or -t, data types to restore, separated by commas, optional value is ‘all’ or a combination of one or more [vertex, edge, vertex_label, edge_label, property_key, index_label], ‘all’ Represents all 6 types, namely vertices, edges and all schemas
- –log or -l, specify the log directory, the default is the current directory
- –retry, specify the number of failed retries, the default is 3
- –thread-num or -T, the number of threads to use, default is Math.min(10, Math.max(4, CPUs / 2))
- -D, use the mode of -Dkey=value to specify dynamic parameters, which are used to specify HDFS configuration items when restoring graphs from HDFS, for example: -Dfs.default.name=hdfs://localhost:9000
restore command can be used only if –format is executed as backup for json
- migrate, migrate the currently connected graph to another HugeGraphServer
- –target-graph, the name of the target graph, the default is hugegraph
- –target-url, the HugeGraphServer where the target graph is located, the default is http://127.0.0.1:8081
- –target-user, the username used to access the target graph
- –target-password, the password to access the target map
- –target-timeout, the timeout for accessing the target map
- –target-trust-store-file, access the truststore file used by the target graph
- –target-trust-store-password, the password to access the truststore used by the target map
- –directory or -d, during the migration process, the directory where the schema or data of the source graph is stored. For a local directory, the default is ‘./{graphName}’; for HDFS, the default is ‘{fs.default.name}/ {graphName}’
- –huge-types or -t, the data types to be migrated, separated by commas, the optional value is ‘all’ or a combination of one or more [vertex, edge, vertex_label, edge_label, property_key, index_label], ‘all’ Represents all 6 types, namely vertices, edges and all schemas
- –log or -l, specify the log directory, the default is the current directory
- –retry, specify the number of failed retries, the default is 3
- –split-size or -s, specify the size of the vertex or edge block when backing up the source graph during the migration process, the default is 1048576
- -D, use the mode of -Dkey=value to specify dynamic parameters, which are used to specify HDFS configuration items when the data needs to be backed up to HDFS during the migration process, for example: -Dfs.default.name=hdfs://localhost: 9000
- –graph-mode or -m, the mode to set the target graph when restoring the source graph to the target graph, legal values include [RESTORING, MERGING]
- –keep-local-data, whether to keep the backup of the source map generated in the process of migrating the map, the default is false, that is, the backup of the source map is not kept after the default migration map ends
- schedule-backup, periodically back up the graph and keep a certain number of the latest backups (currently only supports local file systems)
- –directory or -d, required, specifies the directory of the backup data
- –backup-num, optional, specifies the number of latest backups to save, defaults to 3
- –interval, an optional item, specifies the backup cycle, the format is the same as the Linux crontab format
- dump, export all vertices and edges in the graph, using the
vertex vertex-edge1 vertex-edge2...JSON format by default. To customize the format, implement aFormattersubclass such asCustomFormatterunderhugegraph-tools/src/main/java/org/apache/hugegraph/formatter, then select it when running the command:bin/hugegraph dump -f CustomFormatter- –formatter or -f, specify the formatter to use, the default is JsonFormatter
- –directory or -d, the directory where schema or data is stored, the default is the current directory
- –log or -l, specify the log directory, the default is the current directory
- –retry, specify the number of failed retries, the default is 3
- –split-size or -s, specifies the size of splitting vertices or edges when backing up, the default is 1048576
- -D, use the mode of -Dkey=value to specify dynamic parameters, and specify HDFS configuration items when backing up data to HDFS, for example: -Dfs.default.name=hdfs://localhost:9000
3.7 Authentication data backup/restore type
- auth-backup, backup authentication data to a specified directory
- –types or -t, types of authentication data to back up, separated by commas, optional value is ‘all’ or a combination of one or more [user, group, target, belong, access], ‘all’ represents all 5 types
- –directory or -d, directory to store backup data, defaults to current directory
- –log or -l, specify the log directory, the default is the current directory
- –retry, specify the number of failed retries, the default is 3
- –thread-num or -T, the number of threads to use, default is Math.min(10, Math.max(4, CPUs / 2))
- -D, use the mode of -Dkey=value to specify dynamic parameters, and specify HDFS configuration items when backing up data to HDFS, for example: -Dfs.default.name=hdfs://localhost:9000
- auth-restore, restore authentication data from a specified directory
- –types or -t, types of authentication data to restore, separated by commas, optional value is ‘all’ or a combination of one or more [user, group, target, belong, access], ‘all’ represents all 5 types
- –directory or -d, directory where backup data is stored, defaults to current directory
- –log or -l, specify the log directory, the default is the current directory
- –retry, specify the number of failed retries, the default is 3
- –thread-num or -T, the number of threads to use, default is Math.min(10, Math.max(4, CPUs / 2))
- –strategy, conflict handling strategy, optional values are [stop, ignore], default is stop. stop means stop restoring when encountering conflicts, ignore means ignore conflicts and continue restoring
- –init-password, initial password to set when restoring users, required when restoring user data
- -D, use the mode of -Dkey=value to specify dynamic parameters, which are used to specify HDFS configuration items when restoring data from HDFS, for example: -Dfs.default.name=hdfs://localhost:9000
3.8 Install the deployment type
- deploy, one-click download, install and start HugeGraph-Server and HugeGraph-Studio
- -v, required, specifies the HugeGraph-Server and HugeGraph-Studio version to install
- -p, required, specifies the installed HugeGraph-Server and HugeGraph-Studio directories
- -u, optional, specifies the link to download the HugeGraph-Server and HugeGraph-Studio compressed packages
- clear, clean up HugeGraph-Server and HugeGraph-Studio directories and tarballs
- -p, required, specifies the directory of HugeGraph-Server and HugeGraph-Studio to be cleaned
- start-all, start HugeGraph-Server and HugeGraph-Studio with one click, and start monitoring, automatically pull up the service when the service dies
- -v, required, specifies the installed HugeGraph-Server and HugeGraph-Studio version to start
- -p, required, specifies the directory where HugeGraph-Server and HugeGraph-Studio are installed
- stop-all, close HugeGraph-Server and HugeGraph-Studio with one click
There is an optional parameter -u in the deploy command. When provided, the specified download address will be used instead of the default download address to download the tar package, and the address will be written into the
~/hugegraph-download-url-prefixfile; if no address is specified later When -u and~/hugegraph-download-url-prefixare not specified, the tar package will be downloaded from the address specified by~/hugegraph-download-url-prefix; if there is neither -u nor~/hugegraph-download-url-prefix, it will be downloaded from the default download address
3.9 Specific command parameters
The specific parameters of each subcommand are as follows:
3.10 Specific command example
1. gremlin statement
2. Show task status
3. Set and show graph mode
4. Cleanup Graph
5. Backup Graph
6. Periodic Backup Graph
7. Recovery Graph
8. Graph Migration
3.2.4 - HugeGraph-Spark-Connector Quick Start
1 HugeGraph-Spark-Connector Overview
HugeGraph-Spark-Connector uses the Spark DataFrame API to write bulk data to HugeGraph. The current implementation provides vertex and edge writers.
2 Environment Requirements
- Java 8+
- Maven 3.6+
- Spark 3.x
- Scala 2.12
3 Building
3.1 Build without executing tests
3.2 Build with default tests
4 Usage
Add the dependency to pom.xml, replacing ${revision} with the release version you use:
4.1 Schema Definition Example
If we have a graph, the schema is defined as follows:
4.2 Vertex Sink (Scala)
4.3 Edge Sink (Scala)
5 Configuration Parameters
5.1 Client Configs
Client Configs are used to configure hugegraph-client.
| Parameter | Default Value | Description |
|---|---|---|
host | localhost | Address of HugeGraphServer |
port | 8080 | Port of HugeGraphServer |
graph | hugegraph | Graph name |
protocol | http | Protocol for sending requests to the server, optional http or https |
username | null | Username of the current graph when HugeGraphServer enables permission authentication |
token | null | Token of the current graph when HugeGraphServer has enabled authorization authentication |
timeout | 60 | Timeout (seconds) for inserting results to return |
max-conn | CPUS * 4 | The maximum number of HTTP connections between HugeClient and HugeGraphServer |
max-conn-per-route | CPUS * 2 | The maximum number of HTTP connections for each route between HugeClient and HugeGraphServer |
trust-store-file | null | The client’s certificate file path when the request protocol is https |
trust-store-token | null | The client’s certificate password when the request protocol is https |
5.2 Graph Data Configs
Graph Data Configs describe how DataFrame columns map to vertices or edges.
| Parameter | Default Value | Description |
|---|---|---|
data-type | Graph data type, must be vertex or edge | |
label | Label to which the vertex/edge data to be imported belongs | |
id | Specify a column as the id column of the vertex. When the vertex id policy is CUSTOMIZE, it is required; when the id policy is PRIMARY_KEY, it must be empty | |
source-name | Select certain columns of the input source as the id column of source vertex. When the id policy of the source vertex is CUSTOMIZE, a certain column must be specified as the id column of the vertex; when the id policy of the source vertex is PRIMARY_KEY, one or more columns must be specified for splicing the id of the generated vertex, that is, no matter which id strategy is used, this item is required | |
target-name | Specify certain columns as the id columns of target vertex, similar to source-name | |
selected-fields | Select some columns to insert, other unselected ones are not inserted, cannot exist at the same time as ignored-fields | |
ignored-fields | Ignore some columns so that they do not participate in insertion, cannot exist at the same time as selected-fields | |
batch-size | 500 | The number of data items in each batch when importing data |
5.3 Common Configs
Common Configs contains some common configurations.
| Parameter | Default Value | Description |
|---|---|---|
delimiter | , | Separator of source-name, target-name, selected-fields or ignored-fields |
6 License
The same as HugeGraph, hugegraph-spark-connector is also licensed under Apache 2.0 License.
3.3 - HugeGraph-AI
hugegraph-ai provides Python clients for HugeGraph, graph machine learning tools, and LLM tools for knowledge graph construction and GraphRAG applications.
Apache License 2.0 · Ask DeepWiki
Modules
- hugegraph-llm: knowledge graph construction, GraphRAG, and natural-language graph queries.
- hugegraph-ml: reads graph data from HugeGraph and runs graph learning models.
- hugegraph-python-client: a Python SDK for managing schemas and graph data and running Gremlin queries.
- vermeer-python-client: a Python SDK for the Vermeer graph computing service.
The repository uses a uv workspace to manage the LLM and Python client packages. HugeGraph-ML is a path dependency rather than a workspace member.
Requirements
- HugeGraph-LLM: Python 3.10 or 3.11
- HugeGraph-ML and the Python clients: Python 3.10 or later
uv0.7 or later- HugeGraph Server 1.5 or later
Deploy with Docker Compose
The repository includes a Compose file that starts both HugeGraph Server and the RAG service:
Default addresses:
- HugeGraph Server:
http://localhost:8080 - RAG service and Web UI:
http://localhost:8001
Start the RAG Service from Source
uv sync creates .venv at the repository root. Do not create a separate environment under hugegraph-llm, because doing so can bypass the dependencies locked by the workspace.
Install ML Dependencies
Example scripts are under hugegraph-ml/src/hugegraph_ml/examples/.
Next Steps
3.3.1 - HugeGraph-LLM
HugeGraph-LLM connects graph databases with large language models for knowledge graph construction, GraphRAG, and natural-language graph queries. Its demo service hosts the Gradio UI and FastAPI endpoints in the same process and listens on port 8001 by default.
Requirements
AI-generated project documentation: Ask DeepWiki
- Python 3.10 or 3.11
uv0.7 or later- HugeGraph Server 1.5 or later
Deploy with Docker Compose
Prepare the environment files from the HugeGraph-AI repository root:
After startup, HugeGraph Server is available at http://localhost:8080, and the RAG service and Web UI are available at http://localhost:8001.
Start from Source
Install dependencies through the workspace at the repository root:
To use a custom address and port:
The service stores model, HugeGraph, and login settings in hugegraph-llm/.env. Prompts are stored separately in hugegraph-llm/src/hugegraph_llm/resources/demo/config_prompt.yaml. The configuration code creates missing files with default values.
Main Capabilities
Build RAG Indexes
The first Web UI tab splits text into a chunk vector index, extracts vertices and edges according to a schema, writes the graph to HugeGraph, and updates the vertex vector index. The schema can be inline JSON or the name of an existing graph. Through the REST API, a graph name requires a matching client_config.graph; inline JSON neither connects to HugeGraph nor accepts client_config.
GraphRAG
The query pipeline can combine direct LLM answers, chunk-vector retrieval, and graph retrieval. Graph retrieval first extracts keywords and matches vertices, then attempts Text2Gremlin. If generation or execution fails, it can fall back to predefined graph traversals. Request parameters control result limits, vector distance thresholds, template counts, and reranking.
Text2Gremlin
POST /text2gremlin generates Gremlin from natural language, the graph schema, and optional examples. A custom prompt must retain {query}, {schema}, {example}, and {vertices}.
Models and Vector Backends
Chat, information extraction, and Text2Gremlin can independently use an OpenAI-compatible endpoint, Ollama, or LiteLLM. The embedding model is configured separately. FAISS is the default vector index; Milvus or Qdrant are available after installing the optional dependencies:
See the configuration reference and REST API for details.
Development Checks
3.3.2 - HugeGraph-ML
HugeGraph-ML reads graph data from HugeGraph and converts it to DGL graphs for tasks such as node embedding, node classification, and graph classification. Model implementations are under hugegraph-ml/src/hugegraph_ml/models/.
Requirements
- Python 3.10 or later
- HugeGraph Server 1.0 or later; 1.5 or later is recommended
uv0.7 or later
Installation
HugeGraph-ML is a path dependency of the root project but is not a uv workspace member. Select the ml extra at the repository root instead of creating another lock file in the subdirectory.
Implemented Models
The current README lists these models:
| Models | Main purpose |
|---|---|
| AGNN, APPNP, ARMA, Cluster-GCN, DAGNN, DeeperGCN, GRAND, JKNet | Node classification |
| BGNN, CARE-GNN | Fraud detection |
| BGRL, DGI, GRACE | Representation learning |
| DiffPool | Graph classification |
| GATNE, P-GNN, SEAL | Link prediction or network embedding |
| C&S | Correction and smoothing of predictions |
The source also includes GIN for graph classification and MLPClassifier for downstream classification. The model count changes between versions; use src/hugegraph_ml/models/ as the authoritative list.
DGI Node Embedding Example
First import DGL’s Cora dataset into HugeGraph:
Read the graph and train DGI:
The complete script is hugegraph-ml/src/hugegraph_ml/examples/dgi_example.py.
GRAND Node Classification Example
The complete script is hugegraph-ml/src/hugegraph_ml/examples/grand_example.py.
Troubleshooting
- Connection failures: check the HugeGraph Server address, port, and credentials.
- Schema mismatches: the examples use
CORA_vertexandCORA_edge; pass the actual labels for your own data. - DGL or PyTorch import failures: rerun
uv sync --extra mlfrom the repository root and confirm that Python comes from the root.venv.
3.3.3 - HugeGraph-LLM Workflow
This page explains the processing flow in the HugeGraph-LLM Web UI. See HugeGraph-LLM for startup instructions.
1. Build RAG Indexes
The first tab splits documents into a chunk vector index. It also extracts vertices and edges according to a schema, writes them to HugeGraph, and maintains a vertex vector index.
flowchart TD
    A[Input document] --> B[Split text]
    B --> C[Generate chunk vectors]
    C --> D[Write vector index]
    B --> E[LLM extracts vertices and edges from schema]
    E --> F[Write to HugeGraph]
    F --> G[Update vertex vector index]
Common operations are Import into Vector, Extract Graph Data, Load into GraphDB, and Update Vid Embedding. The page can also inspect or clear chunk indexes, vertex indexes, and graph data. Clearing removes existing data, so first confirm that the current graph and indexes are not still used by other queries.
2. GraphRAG Queries
The second tab can answer directly with the LLM, use only chunk-vector retrieval, use only graph retrieval, or combine graph and vector retrieval.
flowchart TD
    Q[Question] --> V[Query chunk vector index]
    Q --> K[Extract keywords]
    K --> M[Match graph vertices]
    M --> T[Generate and execute Gremlin]
    T -->|Failure| B[Fallback to BFS graph traversal]
    T --> R[Prepare graph results]
    B --> R
    V --> S[Merge and rerank]
    R --> S
    S --> A[Generate answer]
Graph retrieval first matches HugeGraph vertices exactly by keyword and then uses vector similarity if no exact match exists. The matched vertices are passed to Text2Gremlin. If generation or execution fails, the pipeline can fall back to a predefined traversal.
Template Num controls how many examples Text2Gremlin uses. A value less than or equal to zero supplies no templates; a positive value retrieves that many similar examples.
3. Text2Gremlin
The third tab reads the graph schema, retrieves similar natural-language and Gremlin examples, fills the prompt with the question, schema, examples, and matched vertices, then generates Gremlin and optionally executes it.
A custom prompt must contain {query}, {schema}, {example}, and {vertices}. The REST API rejects a request if any placeholder is missing.
4. Graph and Administration Tools
Graph Tools runs graph operations directly. Admin Tools provides functions such as log access. When login is enabled, the UI and APIs require USER_TOKEN; the log endpoint additionally requires a separately configured, secure ADMIN_TOKEN.
5. Prompt Language
Set LANGUAGE=EN or LANGUAGE=CN in hugegraph-llm/.env, then restart the service. This selects the language of built-in prompts; it does not translate input documents and is not a field in the /rag request body.
6. REST Calls
The Web UI and REST API use the same pipeline. For application integration, use /rag, /rag/graph, /graph/extract, and /text2gremlin; see the REST API for request formats.
3.3.4 - Configuration Reference
HugeGraph-LLM reads runtime settings from hugegraph-llm/.env. Prompts are stored separately in hugegraph-llm/src/hugegraph_llm/resources/demo/config_prompt.yaml and are not written to .env.
Create or update the files from configuration-class defaults with:
.env contains keys and passwords. Do not commit it to version control.
Basic Options
| Setting | Default | Description |
|---|---|---|
LANGUAGE | EN | Prompt language: EN or CN |
CHAT_LLM_TYPE | openai | Answer model: openai, litellm, or ollama/local |
EXTRACT_LLM_TYPE | openai | Information extraction model; same choices as above |
TEXT2GQL_LLM_TYPE | openai | Text2Gremlin model; same choices as above |
EMBEDDING_TYPE | openai | Embedding model; same choices as above, or empty |
RERANKER_TYPE | empty | cohere or siliconflow |
KEYWORD_EXTRACT_TYPE | llm | llm, textrank, or hybrid |
WINDOW_SIZE | 3 | TextRank window size, from 1 to 10 |
HYBRID_LLM_WEIGHTS | 0.5 | Weight of LLM results in hybrid mode, from 0 to 1 |
OpenAI-Compatible APIs
Chat, extraction, and Text2Gremlin can use different endpoints, keys, and models.
| Purpose | API base | Key | Model | Default maximum tokens |
|---|---|---|---|---|
| Answer | OPENAI_CHAT_API_BASE | OPENAI_CHAT_API_KEY | OPENAI_CHAT_LANGUAGE_MODEL | OPENAI_CHAT_TOKENS=8192 |
| Extraction | OPENAI_EXTRACT_API_BASE | OPENAI_EXTRACT_API_KEY | OPENAI_EXTRACT_LANGUAGE_MODEL | OPENAI_EXTRACT_TOKENS=256 |
| Text2Gremlin | OPENAI_TEXT2GQL_API_BASE | OPENAI_TEXT2GQL_API_KEY | OPENAI_TEXT2GQL_LANGUAGE_MODEL | OPENAI_TEXT2GQL_TOKENS=4096 |
| Embedding | OPENAI_EMBEDDING_API_BASE | OPENAI_EMBEDDING_API_KEY | OPENAI_EMBEDDING_MODEL | Not applicable |
The default API base is https://api.openai.com/v1. The default language model for all three tasks is gpt-4.1-mini, and the default embedding model is text-embedding-3-small.
OPENAI_BASE_URL and OPENAI_API_KEY provide general fallback values. Embeddings also support OPENAI_EMBEDDING_BASE_URL and OPENAI_EMBEDDING_API_KEY as fallback values.
LiteLLM
| Purpose | API base | Key | Model | Default maximum tokens |
|---|---|---|---|---|
| Answer | LITELLM_CHAT_API_BASE | LITELLM_CHAT_API_KEY | LITELLM_CHAT_LANGUAGE_MODEL | LITELLM_CHAT_TOKENS=8192 |
| Extraction | LITELLM_EXTRACT_API_BASE | LITELLM_EXTRACT_API_KEY | LITELLM_EXTRACT_LANGUAGE_MODEL | LITELLM_EXTRACT_TOKENS=256 |
| Text2Gremlin | LITELLM_TEXT2GQL_API_BASE | LITELLM_TEXT2GQL_API_KEY | LITELLM_TEXT2GQL_LANGUAGE_MODEL | LITELLM_TEXT2GQL_TOKENS=4096 |
| Embedding | LITELLM_EMBEDDING_API_BASE | LITELLM_EMBEDDING_API_KEY | LITELLM_EMBEDDING_MODEL | Not applicable |
The default language model is openai/gpt-4.1-mini, and the default embedding model is openai/text-embedding-3-small. Model names generally use the provider/model form; supported values depend on the LiteLLM service.
Ollama
| Purpose | Host | Port | Model |
|---|---|---|---|
| Answer | OLLAMA_CHAT_HOST | OLLAMA_CHAT_PORT | OLLAMA_CHAT_LANGUAGE_MODEL |
| Extraction | OLLAMA_EXTRACT_HOST | OLLAMA_EXTRACT_PORT | OLLAMA_EXTRACT_LANGUAGE_MODEL |
| Text2Gremlin | OLLAMA_TEXT2GQL_HOST | OLLAMA_TEXT2GQL_PORT | OLLAMA_TEXT2GQL_LANGUAGE_MODEL |
| Embedding | OLLAMA_EMBEDDING_HOST | OLLAMA_EMBEDDING_PORT | OLLAMA_EMBEDDING_MODEL |
The default host is 127.0.0.1 and the default port is 11434. Model names have no defaults; pull the required models in Ollama before use.
Reranking
| Setting | Default | Description |
|---|---|---|
COHERE_BASE_URL | https://api.cohere.com/v1/rerank | Cohere rerank endpoint; CO_API_URL is a fallback |
RERANKER_API_KEY | empty | Cohere or SiliconFlow key |
RERANKER_MODEL | empty | Model name supported by the service |
HugeGraph Connection and Retrieval Limits
| Setting | Default | Description |
|---|---|---|
GRAPH_URL | 127.0.0.1:8080 | HugeGraph address; it is not split into IP and port |
GRAPH_NAME | hugegraph | Graph name |
GRAPH_USER | admin | User name |
GRAPH_PWD | xxx | Password |
GRAPH_SPACE | empty | GraphSpace name |
LIMIT_PROPERTY | False | Whether to limit returned properties; read as a string by the configuration class |
MAX_GRAPH_PATH | 10 | Maximum graph path length |
MAX_GRAPH_ITEMS | 30 | Maximum number of graph retrieval items |
EDGE_LIMIT_PRE_LABEL | 8 | Result limit for each edge label |
VECTOR_DIS_THRESHOLD | 0.9 | Results beyond this vector-distance threshold are ignored |
TOPK_PER_KEYWORD | 1 | Candidates per keyword |
TOPK_RETURN_RESULTS | 20 | Results returned after reranking |
External Vector Databases
The default implementation can use local FAISS. After enabling optional dependencies, the following settings are also available:
| Setting | Default |
|---|---|
QDRANT_HOST | empty |
QDRANT_PORT | 6333 |
QDRANT_API_KEY | empty |
MILVUS_HOST | empty |
MILVUS_PORT | 19530 |
MILVUS_USER | empty |
MILVUS_PASSWORD | empty |
Login and Log API
| Setting | Default | Description |
|---|---|---|
ENABLE_LOGIN | False | Whether to require a Bearer token; read as a string by the configuration class |
USER_TOKEN | 4321 | Token for the Web UI and regular APIs |
ADMIN_TOKEN | xxxx | Administrator token used by /logs |
/logs returns 403 when ADMIN_TOKEN is empty or still set to xxxx. Replace both the user and administrator tokens in production.
Minimal OpenAI Configuration
Configuration Loading
Configuration classes supply code defaults and then apply overrides from .env and the process environment. The Web UI and configuration APIs can update current settings at runtime and write supported fields back to .env. Restart the service after editing .env manually; prompt YAML can be refreshed by the page-loading logic.
Configuration definitions are in:
hugegraph-llm/src/hugegraph_llm/config/llm_config.pyhugegraph-llm/src/hugegraph_llm/config/hugegraph_config.pyhugegraph-llm/src/hugegraph_llm/config/admin_config.pyhugegraph-llm/src/hugegraph_llm/config/prompt_config.py
3.3.5 - HugeGraph-LLM REST API
The HugeGraph-LLM demo process serves both the Web UI and REST API. The default address is http://localhost:8001:
Authentication
Enable login in .env:
Requests then require a Bearer token:
RAG
POST /rag
Returns one or more answer types according to the switches. When none is explicitly selected, only graph_only is enabled.
The response contains only enabled answer fields:
Other optional parameters include graph_ratio, rerank_method (bleu or reranker), near_neighbor_first, custom_priority_info, and three custom prompt fields.
POST /rag/graph
Runs graph retrieval without generating a final natural-language answer:
graph_recall in the response can contain keywords, match_vids, gremlin, graph_result, and vertex_degree_list. Set get_vertex_only=true to return immediately after vertex matching.
Graph Extraction
POST /graph/extract
An inline schema does not connect to HugeGraph:
texts can be a string or an array of strings. language accepts zh or en; split_type accepts document, paragraph, or sentence.
When schema is an existing graph name, also pass client_config, and make client_config.graph match that name:
A successful response always contains status, result.vertices, result.edges, warnings, and meta.
Text2Gremlin
POST /text2gremlin
output_types can contain:
match_resulttemplate_gremlinraw_gremlintemplate_execution_resultraw_execution_result
If omitted, only template_gremlin is returned by default. An empty array lets the implementation return all outputs. A custom gremlin_prompt must contain {query}, {schema}, {example}, and {vertices}.
Runtime Configuration
POST /config/graph
POST /config/llm and POST /config/embedding
Both endpoints use the same request model. OpenAI or LiteLLM example:
Ollama requests still require the common fields; api_key and api_base can be empty strings:
POST /config/rerank
reranker_type accepts cohere or siliconflow. Cohere also accepts cohere_base_url.
These endpoints change the process’s active configuration and may write values back to .env. client_config in /rag, /rag/graph, and /text2gremlin overrides the HugeGraph connection for one request. The current implementation still changes process-global settings temporarily, so do not issue long-running requests with different connections concurrently.
Logs
POST /logs
This endpoint requires ADMIN_TOKEN in .env to be changed to a secure value. Example request body:
log_file must be a file name under logs/ and cannot contain path separators.
3.4 - HugeGraph Computing (OLAP)
The HugeGraph-Computer repository contains two OLAP systems: Computer, a distributed BSP framework implemented in Java, and Vermeer, an in-memory graph computing platform implemented in Go.
DeepWiki provides real-time updated project documentation with more comprehensive and accurate content, suitable for quickly understanding the latest project information.
3.4.1 - HugeGraph-Vermeer Quick Start
1. Overview of Vermeer
1.1 Architecture
Vermeer is a high-performance, memory-first graph computing framework written in Go (start once, execute any task), supporting ultra-fast computation of 15+ OLAP graph algorithms (most tasks complete in seconds to minutes), with master and worker roles. Currently, there is only one master (HA can be added), and there can be multiple workers.
The master is responsible for communication, forwarding, and aggregation, with minimal computation and resource usage. Workers are computation nodes used to store graph data and run computation tasks, consuming a large amount of memory and CPU. The grpc and rest modules handle internal communication and external calls, respectively.
The framework’s runtime configuration can be passed via command-line parameters or specified in configuration files located in the config/ directory. The --env parameter can specify which configuration file to use, e.g., --env=master specifies using master.ini. Note that the master needs to specify the listening port, and the worker needs to specify the listening port and the master’s ip:port.
1.2 Running Method
- Option 1: Docker Compose (Recommended)
Please ensure that docker-compose.yaml exists in your project root directory. If it doesn’t, here is an example:
Modify docker-compose.yaml
- Volume: For example, change both instances of
~/:/go/bin/configto/home/user/config:/go/bin/config(or your own configuration directory). - Subnet: Modify the subnet IP based on your actual situation. Note that the ports each container needs to access are specified in the config file. Please refer to the contents of the project’s
configfolder for details.
Build the Image and Start in the Project Directory (or docker build first, then docker-compose up)
View Logs / Stop / Remove
- Option 2: Start individually via
docker run(Manually create network and assign static IP)
Ensure the CONFIG_DIR has proper read/execute permissions for the Docker process.
Build the image:
Create a custom bridge network (one-time operation):
Run master (adjust CONFIG_DIR to your absolute configuration path, and you can adjust the IP as needed based on your actual situation).
Run worker:
View logs / Stop / Remove:
- Option 3: Build from Source
Build. You can refer Vermeer Readme.
Enter the directory and input ./vermeer --env=master or ./vermeer --env=worker01.
2. Task Creation REST API
2.1 Introduction
This REST API provides all task creation functions, including reading graph data and various computation functions, offering both asynchronous and synchronous return interfaces. The returned content includes information about the created tasks. The overall process of using Vermeer is to first create a task to read the graph data, and after the graph is read, create a computation task to execute the computation. The graph will not be automatically deleted; multiple computation tasks can be run on one graph without repeated reading. If deletion is needed, the delete graph interface can be used. Task statuses can be divided into graph reading task status and computation task status. Generally, the client only needs to know four statuses: created, in progress, completed, and error. The graph status is the basis for determining whether the graph is available. If the graph is being read or the graph status is erroneous, the graph cannot be used to create computation tasks. The delete graph interface is only available when the graph is in the loaded or error status and has no computation tasks.
Available URLs are as follows:
- Asynchronous return interface: POST http://master_ip:port/tasks/create returns only whether the task creation is successful, and the task status needs to be actively queried to determine completion.
- Synchronous return interface: POST http://master_ip:port/tasks/create/sync returns after the task is completed.
2.2 Loading Graph Data
Refer to the Vermeer parameter list document for specific parameters.
Vermeer provides three ways to load data:
- Load from Local Files
You can obtain the dataset in advance, such as the Twitter-2010 dataset. Acquisition method: https://snap.stanford.edu/data/twitter-2010.html The first Twitter-2010.text.gz is sufficient.
Request Example:
- Load from HugeGraph
Request Example:
⚠️ Security Warning: Never store real passwords in configuration files or code. Use environment variables or a secure credential management system instead.
- Load from HDFS
Request Example:
2.3 Output Computation Results
All Vermeer computation tasks support multiple result output methods, which can be customized: local, hdfs, afs, or hugegraph. Add the corresponding parameters under the params parameter when sending the request to take effect. When output.need_statistics is set to 1, it supports outputting statistical information of the computation results, which will be written in the interface task information. The statistical mode operators currently support “count” and “modularity,” but only for community detection algorithms.
Refer to the Vermeer parameter list document for specific parameters.
Request example:
3. Supported Algorithms
3.1 PageRank
The PageRank algorithm, also known as the web ranking algorithm, is a technique used by search engines to calculate the relevance and importance of web pages (nodes) based on their mutual hyperlinks.
- If a web page is linked to by many other web pages, it indicates that the web page is relatively important, and its PageRank value will be relatively high.
- If a web page with a high PageRank value links to other web pages, the PageRank value of the linked web pages will also increase accordingly.
The PageRank algorithm is suitable for scenarios such as web page ranking and identifying key figures in social networks.
Request example:
3.2 WCC (Weakly Connected Components)
The weakly connected components algorithm calculates all connected subgraphs in an undirected graph and outputs the weakly connected subgraph ID to which each vertex belongs, indicating the connectivity between points and distinguishing different connected communities.
Request example:
3.3 LPA (Label Propagation Algorithm)
The label propagation algorithm is a graph clustering algorithm commonly used in social networks to discover potential communities.
Request example:
3.4 Degree Centrality
The degree centrality algorithm calculates the degree centrality value of each node in the graph, supporting both undirected and directed graphs. Degree centrality is an important indicator of node importance; the more edges a node has with other nodes, the higher its degree centrality value, and the more important the node is in the graph. In an undirected graph, degree centrality is calculated based on edge information to count the number of times a node appears, resulting in the degree centrality value of the node. In a directed graph, it is based on the direction of the edges, filtering based on input or output-edge information to count the number of times a node appears, resulting in the in-degree or out-degree value of the node. It indicates the importance of each point, with more important points having higher degrees.
Request example:
3.5 Closeness Centrality
Closeness centrality is used to calculate the inverse of the shortest distance from a node to all other reachable nodes, accumulating and normalizing the value. Closeness centrality can be used to measure the time it takes for information to be transmitted from the node to other nodes. The larger the closeness centrality of a node, the closer its position in the graph is to the center, suitable for scenarios such as identifying key nodes in social networks.
Request example:
3.6 Betweenness Centrality
The betweenness centrality algorithm determines the value of a node as a “bridge” node; the larger the value, the more likely it is to be a necessary path between two points in the graph. Typical examples include mutual followers in social networks. It is suitable for measuring the degree of aggregation around a node in a community.
Request example:
3.7 Triangle Count
The triangle count algorithm calculates the number of triangles passing through each vertex, suitable for calculating the relationships between users and whether the associations form triangles. The more triangles, the higher the degree of association between nodes in the graph, and the tighter the organizational relationship. In social networks, triangles indicate cohesive communities, and identifying triangles helps understand clustering and interconnections among individuals or groups in the network. In financial or transaction networks, the presence of triangles may indicate suspicious or fraudulent activities, and triangle counting can help identify transaction patterns that may require further investigation.
The output result is the Triangle Count corresponding to each vertex, i.e., the number of triangles the vertex is part of.
Note: This algorithm is for undirected graphs and ignores edge directions.
Request example:
3.8 K-Core
The K-Core algorithm marks all vertices with a degree of K, suitable for graph pruning and finding the core part of the graph.
Request example:
3.9 SSSP (Single Source Shortest Path)
The single source the shortest path algorithm calculates the shortest distance from one point to all other points.
Request example:
3.10 KOUT
Starting from a point, get the k-layer nodes of this point.
Request example:
3.11 Louvain
The Louvain algorithm is a community detection algorithm based on modularity. The basic idea is that nodes in the network try to traverse all neighbor community labels and choose the community label that maximizes the modularity increment. After maximizing modularity, each community is regarded as a new node, and the process is repeated until the modularity no longer increases.
The distributed Louvain algorithm implemented on Vermeer is affected by factors such as node order and parallel computation. Due to the random traversal order of the Louvain algorithm, community compression also has a certain randomness, leading to different results in multiple executions. However, the overall trend will not change significantly.
Request example:
3.12 Jaccard Similarity Coefficient
The Jaccard index, also known as the Jaccard similarity coefficient, is used to compare the similarity and diversity between finite sample sets. The larger the Jaccard coefficient value, the higher the similarity of the samples. It is used to calculate the Jaccard similarity coefficient between a given source point and all other points in the graph.
Request example:
3.13 Personalized PageRank
The goal of personalized PageRank is to calculate the relevance of all nodes relative to user u. Starting from the node corresponding to user u, at each node, there is a probability of 1-d to stop walking and start again from u, or a probability of d to continue walking, randomly selecting a node from the nodes pointed to by the current node to walk down. It is used to calculate the personalized PageRank score starting from a given starting point, suitable for scenarios such as social recommendations.
Since the calculation requires using out-degree, load.use_out_degree needs to be set to 1 when reading the graph.
Request example:
3.14 Global Kout
Calculate the k-degree neighbors of all nodes in the graph (excluding themselves and 1~k-1 degree neighbors). Due to the severe memory expansion of the global kout algorithm, k is currently limited to 1 and 2. Additionally, the global kout algorithm supports filtering functions (parameters such as “compute.filter”:“risk_level==1”), and the filtering condition is judged when calculating the k-degree. The final result set includes those that meet the filtering condition. The algorithm’s final output is the number of neighbors that meet the condition.
Request example:
3.15 Clustering Coefficient
The clustering coefficient represents the coefficient of the clustering degree of nodes in a graph. In real networks, especially in specific networks, nodes tend to establish a tightly organized relationship due to relatively high-density connection points. The clustering coefficient algorithm (Cluster Coefficient) is used to calculate the clustering degree of nodes in the graph. This algorithm is for local clustering coefficients. The local clustering coefficient can measure the clustering degree around each node in the graph.
Request example:
3.16 SCC (Strongly Connected Components)
In the mathematical theory of directed graphs, if every vertex of a graph can be reached from any other point in the graph, the graph is said to be strongly connected. The parts of any directed graph that can achieve strong connectivity are called strongly connected components. It indicates the connectivity between points and distinguishes different connected communities.
Request example:
🚧, further updates and improvements will be made at any time. Suggestions and feedback are welcome.
3.4.2 - HugeGraph-Computer Quick Start
1 HugeGraph-Computer Overview
The HugeGraph-Computer is a distributed graph processing system for HugeGraph (OLAP). It is an implementation of Pregel. It runs on a Kubernetes(K8s) framework.(It focuses on supporting graph data volumes of hundreds of billions to trillions, using disk for sorting and acceleration, which is one of the biggest differences from Vermeer)
Features
- Support distributed MPP graph computing, and integrates with HugeGraph as graph input/output storage.
- Based on the BSP (Bulk Synchronous Parallel) model, an algorithm performs computing through multiple parallel iterations; every iteration is a superstep.
- Auto memory management. The framework will never be OOM(Out of Memory) since it will split some data to disk if it doesn’t have enough memory to hold all the data.
- The part of edges or the messages of super node can be in memory, so you will never lose it.
- You can load the data from HDFS or HugeGraph, or any other system.
- You can output the results to HDFS or HugeGraph, or any other system.
- Easy to develop a new algorithm. You just need to focus on vertex-only processing just like as in a single server, without worrying about message transfer and memory/storage management.
2 Dependency for Building/Running
2.1 Install Java 11 (JDK 11)
Must use ≥ Java 11 to run Computer, and configure by yourself.
Be sure to execute the java -version command to check the jdk version before reading
3 Get Started
3.1 Run PageRank algorithm locally
To run the algorithm with HugeGraph-Computer, you need to install Java 11 or later versions.
You also need to deploy HugeGraph-Server and Etcd.
There are two ways to get HugeGraph-Computer:
- Download the compiled tarball
- Clone source code then compile and package
3.1.1 Download the compiled archive
Download the latest version of the HugeGraph-Computer release package:
3.1.2 Clone source code to compile and package
Clone the latest version of HugeGraph-Computer source package:
Compile and generate tar package:
3.1.3 Start master node
You can use
-cparameter specify the configuration file, more computer config please see:Computer Config Options
3.1.4 Start worker node
3.1.5 Query algorithm results
3.1.5.1 Enable OLAP index query for server
If the OLAP index is not enabled, it needs to be enabled. More reference: modify-graphs-read-mode
3.1.5.2 Query page_rank property value:
3.2 Run PageRank algorithm in Kubernetes
To run an algorithm with HugeGraph-Computer, you need to deploy HugeGraph-Server first
3.2.1 Install HugeGraph-Computer CRD
3.2.2 Show CRD
3.2.3 Install hugegraph-computer-operator&etcd-server
3.2.4 Wait for hugegraph-computer-operator&etcd-server deployment to complete
3.2.5 Submit a job
More computer crd please see: Computer CRD
More computer config please see: Computer Config Options
3.2.6 Show job
3.2.7 Show log of nodes
3.2.8 Show success event of a job
NOTE: it will only be saved for one hour
3.2.9 Query algorithm results
If the output to Hugegraph-Server is consistent with Locally, if output to HDFS, please check the result file in the directory of /hugegraph-computer/results/{jobId} directory.
4. Built-In algorithms document
4.1 Supported algorithms list:
Centrality Algorithm:
- PageRank
- BetweennessCentrality
- ClosenessCentrality
- DegreeCentrality
Community Algorithm:
- ClusteringCoefficient
- Kcore
- Lpa
- TriangleCount
- Wcc
Path Algorithm:
- RingsDetection
- RingsDetectionWithFilter
More algorithms please see: Built-In algorithms
4.2 Algorithm describe
TODO
5 Algorithm development guide
TODO
6 Note
- If some classes under computer-k8s cannot be found, you need to execute
mvn compilein advance to generate corresponding classes.
3.4.3 - HugeGraph-Computer Configuration Reference
Computer Config Options
The defaults in the tables come from ComputerOptions.java in the computer-api module. When the distribution’s conf/computer.properties explicitly overrides an option, the table shows “code default (packaged: actual value)”. At runtime, values in the configuration file take precedence.
1. Basic Configuration
Core job settings for HugeGraph-Computer.
| config option | default value | description |
|---|---|---|
| hugegraph.url | http://127.0.0.1:8080 | The HugeGraph server URL to load data and write results back. |
| hugegraph.name | hugegraph | The graph name to load data and write results back. |
| hugegraph.username | "" (empty) | The username for HugeGraph authentication (leave empty if authentication is disabled). |
| hugegraph.password | "" (empty) | The password for HugeGraph authentication (leave empty if authentication is disabled). |
| job.id | local_0001 (packaged: local_001) | The job identifier on YARN cluster or K8s cluster. |
| job.namespace | "" (empty) | The job namespace used to separate different data sources. This option is managed by the runtime system. |
| job.workers_count | 1 | The number of workers for one graph algorithm job. In K8s, this option is set by the Operator. |
| job.partitions_count | 1 | The number of partitions for computing one graph algorithm job. |
| job.partitions_thread_nums | 4 | The number of threads for partition parallel compute. |
2. Algorithm Configuration
Algorithm-specific configuration for computation logic.
| config option | default value | description |
|---|---|---|
| algorithm.params_class | ComputerOptions.Null placeholder class | Required. The class used to pass algorithm parameters before the algorithm runs. |
| algorithm.result_class | ComputerOptions.Null placeholder class | The vertex value class used to store computation results. |
| algorithm.message_class | ComputerOptions.Null placeholder class | The message class passed while computing a vertex. |
3. Input Configuration
Configuration for loading input data from HugeGraph or other sources.
3.1 Input Source
| config option | default value | description |
|---|---|---|
| input.source_type | hugegraph-server | The source type to load input data, allowed values: [‘hugegraph-server’, ‘hugegraph-loader’]. The ‘hugegraph-loader’ means use hugegraph-loader to load data from HDFS or file. If using ‘hugegraph-loader’, please configure ‘input.loader_struct_path’ and ‘input.loader_schema_path’. |
| input.loader_struct_path | "" (empty) | The structure path for Loader input. It takes effect only when input.source_type=hugegraph-loader. |
| input.loader_schema_path | "" (empty) | The schema path for Loader input. It takes effect only when input.source_type=hugegraph-loader. |
3.2 Input Splits
| config option | default value | description |
|---|---|---|
| input.split_size | 1048576 (1 MB) | The input split size in bytes. |
| input.split_max_splits | 10000000 | The maximum number of input splits. |
| input.split_page_size | 500 | The page size for streamed load input split data. |
| input.split_fetch_timeout | 300 | The timeout in seconds to fetch input splits. |
3.3 Input Processing
| config option | default value | description |
|---|---|---|
| input.filter_class | org.apache.hugegraph.computer.core.input.filter.DefaultInputFilter | The class to create input-filter object. Input-filter is used to filter vertex edges according to user needs. |
| input.edge_direction | OUT | The direction of edges to load, allowed values: [OUT, IN, BOTH]. When the value is BOTH, edges in both OUT and IN directions will be loaded. |
| input.edge_freq | MULTIPLE | The frequency of edges that can exist between a pair of vertices, allowed values: [SINGLE, SINGLE_PER_LABEL, MULTIPLE]. SINGLE means only one edge can exist between a pair of vertices (identified by sourceId + targetId); SINGLE_PER_LABEL means each edge label can have one edge between a pair of vertices (identified by sourceId + edgeLabel + targetId); MULTIPLE means many edges can exist between a pair of vertices (identified by sourceId + edgeLabel + sortValues + targetId). |
| input.max_edges_in_one_vertex | 200 | The maximum number of adjacent edges allowed to be attached to a vertex. The adjacent edges will be stored and transferred together as a batch unit. |
3.4 Input Performance
| config option | default value | description |
|---|---|---|
| input.send_thread_nums | 4 | The number of threads for parallel sending of vertices or edges. |
4. Snapshot & Storage Configuration
HugeGraph-Computer supports snapshot functionality to save vertex/edge partitions to local storage or MinIO object storage, enabling checkpoint recovery or accelerating repeated computations.
4.1 Basic Snapshot Configuration
| config option | default value | description |
|---|---|---|
| snapshot.write | false | Whether to write snapshots of input vertex/edge partitions. |
| snapshot.load | false | Whether to load from snapshots of vertex/edge partitions. |
| snapshot.name | "" (empty) | User-defined snapshot name to distinguish different snapshots. |
4.2 MinIO Integration (Optional)
MinIO can be used as a distributed object storage backend for snapshots in K8s deployments.
| config option | default value | description |
|---|---|---|
| snapshot.minio_endpoint | "" (empty) | MinIO service endpoint (e.g., http://minio:9000). Required when using MinIO. |
| snapshot.minio_access_key | minioadmin | MinIO access key for authentication. |
| snapshot.minio_secret_key | minioadmin | MinIO secret key for authentication. |
| snapshot.minio_bucket_name | "" (empty) | MinIO bucket name for storing snapshot data. |
Usage Scenarios:
- Checkpoint Recovery: Resume from snapshots after job failures, avoiding data reloading
- Repeated Computations: Load data from snapshots when running the same algorithm multiple times
- A/B Testing: Save multiple snapshot versions of the same dataset to test different algorithm parameters
Example: Local Snapshot (in computer.properties):
Example: MinIO Snapshot (in K8s CRD computerConf):
5. Worker & Master Configuration
Configuration for worker and master computation logic.
5.1 Master Configuration
| config option | default value | description |
|---|---|---|
| master.computation_class | org.apache.hugegraph.computer.core.master.DefaultMasterComputation | Master-computation is computation that can determine whether to continue to the next superstep. It runs at the end of each superstep on the master. |
5.2 Worker Computation
| config option | default value | description |
|---|---|---|
| worker.computation_class | org.apache.hugegraph.computer.core.config.Null | The class to create worker-computation object. Worker-computation is used to compute each vertex in each superstep. |
| worker.combiner_class | org.apache.hugegraph.computer.core.config.Null | Combiner can combine messages into one value for a vertex. For example, PageRank algorithm can combine messages of a vertex to a sum value. |
| worker.partitioner | org.apache.hugegraph.computer.core.graph.partition.HashPartitioner | The partitioner that decides which partition a vertex should be in, and which worker a partition should be in. |
5.3 Worker Combiners
| config option | default value | description |
|---|---|---|
| worker.vertex_properties_combiner_class | org.apache.hugegraph.computer.core.combiner.OverwritePropertiesCombiner | The combiner can combine several properties of the same vertex into one properties at input step. |
| worker.edge_properties_combiner_class | org.apache.hugegraph.computer.core.combiner.OverwritePropertiesCombiner | The combiner can combine several properties of the same edge into one properties at input step. |
5.4 Worker Buffers
| config option | default value | description |
|---|---|---|
| worker.received_buffers_bytes_limit | 104857600 (100 MB) | The limit bytes of buffers of received data. The total size of all buffers can’t exceed this limit. If received buffers reach this limit, they will be merged into a file (spill to disk). |
| worker.write_buffer_capacity | 52428800 (50 MB) | The initial size of write buffer that used to store vertex or message. |
| worker.write_buffer_threshold | 52428800 (50 MB) | The threshold of write buffer. Exceeding it will trigger sorting. The write buffer is used to store vertex or message. |
5.5 Worker Data & Timeouts
| config option | default value | description |
|---|---|---|
| worker.data_dirs | [jobs] | The directories separated by ‘,’ that received vertices and messages can persist into. |
| worker.wait_sort_timeout | 600000 (10 minutes) | The max timeout (in ms) for message-handler to wait for sort-thread to sort one batch of buffers. |
| worker.wait_finish_messages_timeout | 86400000 (24 hours) | The max timeout (in ms) for message-handler to wait for finish-message of all workers. |
6. I/O & Output Configuration
Configuration for output computation results.
6.1 Output Class & Result
| config option | default value | description |
|---|---|---|
| output.output_class | org.apache.hugegraph.computer.core.output.LogOutput | The class to output the computation result of each vertex. Called after iteration computation. |
| output.result_name | value | The value is assigned dynamically by #name() of instance created by WORKER_COMPUTATION_CLASS. |
| output.result_write_type | OLAP_COMMON | The result write-type to output to HugeGraph, allowed values: [OLAP_COMMON, OLAP_SECONDARY, OLAP_RANGE]. |
6.2 Output Behavior
| config option | default value | description |
|---|---|---|
| output.with_adjacent_edges | false | Whether to output the adjacent edges of the vertex. |
| output.with_vertex_properties | false | Whether to output the properties of the vertex. |
| output.with_edge_properties | false | Whether to output the properties of the edge. |
6.3 Batch Output
| config option | default value | description |
|---|---|---|
| output.batch_size | 500 | The batch size of output. |
| output.batch_threads | 1 | The number of threads used for batch output. |
| output.single_threads | 1 | The number of threads used for single output. |
6.4 HDFS Output
| config option | default value | description |
|---|---|---|
| output.hdfs_url | hdfs://127.0.0.1:9000 | The HDFS URL for output. |
| output.hdfs_user | hadoop | The HDFS user for output. |
| output.hdfs_path_prefix | /hugegraph-computer/results | The directory of HDFS output results. |
| output.hdfs_delimiter | , (comma) | The delimiter of HDFS output. |
| output.hdfs_merge_partitions | true | Whether to merge output files of multiple partitions. |
| output.hdfs_replication | 3 | The replication number of HDFS. |
| output.hdfs_core_site_path | "" (empty) | The HDFS core site path. |
| output.hdfs_site_path | "" (empty) | The HDFS site path. |
| output.hdfs_kerberos_enable | false | Whether Kerberos authentication is enabled for HDFS. |
| output.hdfs_kerberos_principal | "" (empty) | The HDFS principal for Kerberos authentication. |
| output.hdfs_kerberos_keytab | "" (empty) | The HDFS keytab file for Kerberos authentication. |
| output.hdfs_krb5_conf | /etc/krb5.conf | Kerberos configuration file path. |
6.5 Retry & Timeout
| config option | default value | description |
|---|---|---|
| output.retry_times | 3 | The retry times when output fails. |
| output.retry_interval | 10 | The retry interval (in seconds) when output fails. |
| output.thread_pool_shutdown_timeout | 60 | The timeout (in seconds) of output thread pool shutdown. |
7. Network & Transport Configuration
Configuration for network communication between workers and master.
7.1 Server Configuration
| config option | default value | description |
|---|---|---|
| transport.server_host | 127.0.0.1 | The hostname or IP that listens for transport data. This option is managed by the runtime system. |
| transport.server_port | 0 | The port that listens for transport data; 0 assigns a random port. This option is managed by the runtime system. |
| transport.server_threads | 4 | The number of transport threads for server. |
7.2 Client Configuration
| config option | default value | description |
|---|---|---|
| transport.client_threads | 4 | The number of transport threads for client. |
| transport.client_connect_timeout | 3000 | The timeout (in ms) of client connect to server. |
7.3 Protocol Configuration
| config option | default value | description |
|---|---|---|
| transport.provider_class | org.apache.hugegraph.computer.core.network.netty.NettyTransportProvider | The transport provider, currently only supports Netty. |
| transport.io_mode | AUTO | The network IO mode, allowed values: [NIO, EPOLL, AUTO]. AUTO means selecting the appropriate mode automatically. |
| transport.tcp_keep_alive | true | Whether to enable TCP keep-alive. |
| transport.transport_epoll_lt | false | Whether to enable EPOLL level-trigger (only effective when io_mode=EPOLL). |
7.4 Buffer Configuration
| config option | default value | description |
|---|---|---|
| transport.send_buffer_size | 0 | The size of socket send-buffer in bytes. 0 means using system default value. |
| transport.receive_buffer_size | 0 | The size of socket receive-buffer in bytes. 0 means using system default value. |
| transport.write_buffer_high_mark | 67108864 (64 MB) | The high water mark for write buffer in bytes. It will trigger sending unavailable if the number of queued bytes > write_buffer_high_mark. |
| transport.write_buffer_low_mark | 33554432 (32 MB) | The low water mark for write buffer in bytes. It will trigger sending available if the number of queued bytes < write_buffer_low_mark. |
7.5 Flow Control
| config option | default value | description |
|---|---|---|
| transport.max_pending_requests | 8 | The max number of client unreceived ACKs. It will trigger sending unavailable if the number of unreceived ACKs >= max_pending_requests. |
| transport.min_pending_requests | 6 | The minimum number of client unreceived ACKs. It will trigger sending available if the number of unreceived ACKs < min_pending_requests. |
| transport.min_ack_interval | 200 | The minimum interval (in ms) of server reply ACK. |
7.6 Timeouts
| config option | default value | description |
|---|---|---|
| transport.close_timeout | 10000 | The timeout (in ms) of close server or close client. |
| transport.sync_request_timeout | 10000 | The timeout (in ms) to wait for response after sending sync-request. |
| transport.finish_session_timeout | 0 | The timeout (in ms) to finish session. 0 means using (transport.sync_request_timeout × transport.max_pending_requests). |
| transport.write_socket_timeout | 3000 | The timeout (in ms) to write data to socket buffer. |
| transport.server_idle_timeout | 360000 (6 minutes) | The max timeout (in ms) of server idle. |
7.7 Heartbeat
| config option | default value | description |
|---|---|---|
| transport.heartbeat_interval | 20000 (20 seconds) | The minimum interval (in ms) between heartbeats on client side. |
| transport.max_timeout_heartbeat_count | 120 | The maximum times of timeout heartbeat on client side. If the number of timeouts waiting for heartbeat response continuously > max_timeout_heartbeat_count, the channel will be closed from client side. |
7.8 Advanced Network Settings
| config option | default value | description |
|---|---|---|
| transport.max_syn_backlog | 511 | The capacity of SYN queue on server side. 0 means using system default value. |
| transport.recv_file_mode | true | Whether to enable receive buffer-file mode. It will receive buffer and write to file from socket using zero-copy if enabled. Note: Requires OS support for zero-copy (e.g., Linux sendfile/splice). |
| transport.network_retries | 3 | The number of retry attempts for network communication if network is unstable. |
8. Storage & Persistence Configuration
Configuration for HGKV (HugeGraph Key-Value) storage engine and value files.
8.1 HGKV Configuration
| config option | default value | description |
|---|---|---|
| hgkv.max_file_size | 2147483648 (2 GB) | The max number of bytes in each HGKV file. |
| hgkv.max_data_block_size | 65536 (64 KB) | The max byte size of HGKV file data block. |
| hgkv.max_merge_files | 10 | The max number of files to merge at one time. |
| hgkv.temp_file_dir | /tmp/hgkv | This folder is used to store temporary files during the file merging process. |
8.2 Value File Configuration
| config option | default value | description |
|---|---|---|
| valuefile.max_segment_size | 1073741824 (1 GB) | The max number of bytes in each segment of value-file. |
9. BSP & Coordination Configuration
Configuration for Bulk Synchronous Parallel (BSP) protocol and etcd coordination.
| config option | default value | description |
|---|---|---|
| bsp.etcd_endpoints | http://localhost:2379 | The etcd endpoints; separate multiple addresses with commas. In K8s deployments, this option is set by the Operator. |
| bsp.max_super_step | 10 (packaged: 2) | The max super step of the algorithm. |
| bsp.register_timeout | 300000 (packaged: 100000) | The max timeout (in ms) to wait for master and workers to register. |
| bsp.wait_workers_timeout | 86400000 (24 hours) | The max timeout (in ms) to wait for workers BSP event. |
| bsp.wait_master_timeout | 86400000 (24 hours) | The max timeout (in ms) to wait for master BSP event. |
| bsp.log_interval | 30000 (30 seconds) | The log interval (in ms) to print the log while waiting for BSP event. |
10. Performance Tuning Configuration
Configuration for performance optimization.
| config option | default value | description |
|---|---|---|
| allocator.max_vertices_per_thread | 10000 | Maximum number of vertices per thread processed in each memory allocator. |
| sort.thread_nums | 4 | The number of threads performing internal sorting. |
11. System Administration Configuration
The following options are managed by the runtime system and should not be overridden in job configurations.
The following configuration items are automatically managed by the K8s Operator, Driver, or runtime system. Manual modification will cause cluster communication failures or job scheduling errors.
| config option | managed by | description |
|---|---|---|
| bsp.etcd_endpoints | K8s Operator | Automatically set to operator’s etcd service address |
| transport.server_host | Runtime | Automatically set to pod/container hostname |
| transport.server_port | Runtime | Automatically assigned random port |
| job.namespace | K8s Operator | Automatically set to job namespace |
| job.id | K8s Operator | Automatically set to job ID from CRD |
| job.workers_count | K8s Operator | Automatically set from CRD workerInstances |
| rpc.server_host | Runtime | RPC server hostname (system-managed) |
| rpc.server_port | Runtime | RPC server port (system-managed) |
| rpc.remote_url | Runtime | RPC remote URL (system-managed) |
Why These Are Forbidden:
- BSP/RPC Configuration: Must match the actual deployed etcd/RPC services. Manual overrides break coordination.
- Job Configuration: Must match K8s CRD specifications. Mismatches cause worker count errors.
- Transport Configuration: Must use actual pod hostnames/ports. Manual values prevent inter-worker communication.
K8s Operator Config Options
NOTE: Option needs to be converted through environment variable settings, e.g. k8s.internal_etcd_url => INTERNAL_ETCD_URL
| config option | default value | description |
|---|---|---|
| k8s.auto_destroy_pod | true | Whether to automatically destroy all pods when the job is completed or failed. |
| k8s.close_reconciler_timeout | 120 | The max timeout (in ms) to close reconciler. |
| k8s.internal_etcd_url | http://127.0.0.1:2379 | The internal etcd URL for operator system. |
| k8s.max_reconcile_retry | 3 | The max retry times of reconcile. |
| k8s.probe_backlog | 50 | The maximum backlog for serving health probes. |
| k8s.probe_port | 9892 | The port that the controller binds to for serving health probes. |
| k8s.ready_check_internal | 1000 | The time interval (ms) of check ready. |
| k8s.ready_timeout | 30000 | The max timeout (in ms) of check ready. |
| k8s.reconciler_count | 10 | The max number of reconciler threads. |
| k8s.resync_period | 600000 | The minimum frequency at which watched resources are reconciled. |
| k8s.timezone | Asia/Shanghai | The timezone of computer job and operator. |
| k8s.watch_namespace | hugegraph-computer-system | The namespace to watch custom resources in. Use ‘*’ to watch all namespaces. |
HugeGraph-Computer CRD
| spec | default value | description | required |
|---|---|---|---|
| algorithmName | The name of algorithm. | true | |
| jobId | The job id. | true | |
| image | The image of algorithm. | true | |
| computerConf | The map of computer config options. | true | |
| workerInstances | The number of worker instances, it will override the ‘job.workers_count’ option. | true | |
| pullPolicy | Always | The pull-policy of image, detail please refer to: https://kubernetes.io/docs/concepts/containers/images/#image-pull-policy | false |
| pullSecrets | The pull-secrets of Image, detail please refer to: https://kubernetes.io/docs/concepts/containers/images/#specifying-imagepullsecrets-on-a-pod | false | |
| masterCpu | The cpu limit of master, the unit can be ’m’ or without unit detail please refer to: https://kubernetes.io/docs/concepts/configuration/manage-resources-containers/#meaning-of-cpu | false | |
| workerCpu | The cpu limit of worker, the unit can be ’m’ or without unit detail please refer to: https://kubernetes.io/docs/concepts/configuration/manage-resources-containers/#meaning-of-cpu | false | |
| masterMemory | The memory limit of master, the unit can be one of Ei、Pi、Ti、Gi、Mi、Ki detail please refer to: https://kubernetes.io/docs/concepts/configuration/manage-resources-containers/#meaning-of-memory | false | |
| workerMemory | The memory limit of worker, the unit can be one of Ei、Pi、Ti、Gi、Mi、Ki detail please refer to: https://kubernetes.io/docs/concepts/configuration/manage-resources-containers/#meaning-of-memory | false | |
| log4jXml | The content of log4j.xml for computer job. | false | |
| jarFile | The jar path of computer algorithm. | false | |
| remoteJarUri | The remote jar uri of computer algorithm, it will overlay algorithm image. | false | |
| jvmOptions | The java startup parameters of computer job. | false | |
| envVars | please refer to: https://kubernetes.io/docs/tasks/inject-data-application/define-interdependent-environment-variables/ | false | |
| envFrom | please refer to: https://kubernetes.io/docs/tasks/inject-data-application/define-environment-variable-container/ | false | |
| masterCommand | bin/start-computer.sh | The run command of master, equivalent to ‘Entrypoint’ field of Docker. | false |
| masterArgs | ["-r master", “-d k8s”] | The run args of master, equivalent to ‘Cmd’ field of Docker. | false |
| workerCommand | bin/start-computer.sh | The run command of worker, equivalent to ‘Entrypoint’ field of Docker. | false |
| workerArgs | ["-r worker", “-d k8s”] | The run args of worker, equivalent to ‘Cmd’ field of Docker. | false |
| volumes | Please refer to: https://kubernetes.io/docs/concepts/storage/volumes/ | false | |
| volumeMounts | Please refer to: https://kubernetes.io/docs/concepts/storage/volumes/ | false | |
| secretPaths | The map of k8s-secret name and mount path. | false | |
| configMapPaths | The map of k8s-configmap name and mount path. | false | |
| podTemplateSpec | Please refer to: https://kubernetes.io/docs/reference/kubernetes-api/workload-resources/pod-template-v1/#PodTemplateSpec | false | |
| securityContext | Please refer to: https://kubernetes.io/docs/tasks/configure-pod-container/security-context/ | false |
KubeDriver Config Options
| config option | default value | description |
|---|---|---|
| k8s.build_image_bash_path | The path of command used to build image. | |
| k8s.enable_internal_algorithm | true | Whether enable internal algorithm. |
| k8s.framework_image_url | hugegraph/hugegraph-computer:latest | The image url of computer framework. |
| k8s.image_repository_password | The password for login image repository. | |
| k8s.image_repository_registry | The address for login image repository. | |
| k8s.image_repository_url | hugegraph/hugegraph-computer | The url of image repository. |
| k8s.image_repository_username | The username for login image repository. | |
| k8s.internal_algorithm | [pageRank] | The name list of all internal algorithm. Note: Algorithm names use camelCase here (e.g., pageRank), but algorithm implementations return underscore_case (e.g., page_rank). |
| k8s.internal_algorithm_image_url | hugegraph/hugegraph-computer:latest | The image url of internal algorithm. |
| k8s.jar_file_dir | /cache/jars/ | The directory where the algorithm jar will be uploaded. |
| k8s.kube_config | ~/.kube/config | The path of k8s config file. |
| k8s.log4j_xml_path | The log4j.xml path for computer job. | |
| k8s.namespace | hugegraph-computer-system | The namespace of hugegraph-computer system. |
| k8s.pull_secret_names | [] | The names of pull-secret for pulling image. |
3.5 - HugeGraph Client
The Java and Go clients are maintained in the HugeGraph Toolchain repository, while the Python client is maintained in the HugeGraph-AI repository. Their installation methods and APIs differ; see the corresponding pages for details.
3.5.1 - HugeGraph-Java-Client
1 Overview
HugeGraph Java Client translates Java APIs into REST requests to HugeGraph Server. It supports managing schemas and graph data, executing Gremlin queries, and calling Traverser APIs. See the Client API for detailed interfaces; this page shows how to use the client in a Java project.
For other languages, use the Go Client or the Python Client maintained in the HugeGraph-AI repository.
2 What You Need
- JDK 11 (used by the current CI; the source target remains Java 8)
- Maven 3.6+
3 How To Use
The basic steps to use HugeGraph-Client are as follows:
- Build a new Maven project by IDEA or Eclipse
- Add HugeGraph-Client dependency in a pom file;
- Create an object to invoke the interface of HugeGraph-Client
See the complete example in the following section for the detail.
4 Complete Example
4.1 Build New Maven Project
Using IDEA or Eclipse to create the project:
4.2 Add Hugegraph-Client Dependency In POM
Development versions of the client and server may differ. Check the corresponding release notes for compatibility before upgrading.
4.3 Example
4.3.1 SingleExample
4.3.2 BatchExample
4.4 Run The Example
Before running Example, you need to start the Server. For the startup process, seeHugeGraph-Server Quick Start.
4.5 More Information About Client-API
3.5.2 - HugeGraph Python Client Quick Start
hugegraph-python-client is the Python SDK for HugeGraph. It manages schemas, reads and writes graph data, and executes Gremlin queries. HugeGraph-LLM and HugeGraph-ML also use this client.
Requirements
- Python 3.9 or later
- An accessible HugeGraph Server
uv(recommended) orpip
Installation
The package is currently published on PyPI as hugegraph-python:
To use the latest repository code, sync the workspace from the root of the HugeGraph-AI repository:
Connect and Write Data
If GraphSpace is disabled in HugeGraph, omit graphspace. When it is enabled, pass the actual space name; the default space is usually DEFAULT.
Common Operations
Query the Schema
Update and Delete Graph Data
The graph API accepts dictionaries containing object properties:
Execute Gremlin
API parameters may change with the HugeGraph REST API version. If an interface is incompatible, first check the REST API documentation for the current server version and the client test cases.
Development Checks
Run formatting and static checks from the root of the HugeGraph-AI repository:
The source code and tests are under hugegraph-python-client/src/pyhugegraph/ and hugegraph-python-client/src/tests/.
3.5.3 - HugeGraph Go Client Quick Start
HugeGraph Go Client is the Go SDK in the Toolchain repository. It currently provides APIs for version queries, schemas, vertices, edges, and Gremlin.
This module is still under development. Refer to the source code under
hugegraph-client-go/api/v1for the currently available interfaces.
Requirements
- Go 1.19 or later
- An accessible HugeGraph Server; examples use
http://127.0.0.1:8080
Installation
Run the following command in a Go module project:
Initialize the Client
NewCommonClient requires Host to be an IP address. Leave the username and password empty when authentication is disabled. Current server graph resource paths include a graph space; use DEFAULT for the default space. Leaving GraphSpace empty applies only to older servers that still use the /graphs/{graph} path.
The Versions value returned by Version() includes the HugeGraph Server, Core, Gremlin, and REST API versions. The NewDefaultCommonClient() helper in the source connects to the hugegraph graph at 127.0.0.1:8080 with admin/pa authentication. Production code should normally pass an explicit configuration instead.
Available Entry Points
CommonClient currently exposes the following entry points:
| Entry point | Purpose |
|---|---|
Version() | Query the server version |
Schema() | Query the complete schema |
Propertykey | Manage property keys |
VertexLabel | Manage vertex labels |
EdgeLabel | Manage edge labels |
Vertex | Create vertices in single or batch mode and update vertex properties |
Gremlin | Execute Gremlin through GET or POST |
For complete usage, see the tests in each API directory, such as version_test.go and vertexlabel_test.go.
4 - HugeGraph-Server Configuration
This section covers HugeGraph-Server configuration files, available options, authentication, and HTTPS settings.
4.1 - Server Startup Guide
1 Overview
The directory for the configuration files is hugegraph-release/conf, and all the configurations related to the service and the graph itself are located in this directory.
The main configuration files include gremlin-server.yaml, rest-server.properties, and hugegraph.properties.
The HugeGraphServer integrates the GremlinServer and RestServer internally, and gremlin-server.yaml and rest-server.properties are used to configure these two servers.
- GremlinServer: GremlinServer accepts Gremlin requests and invokes the graph engine.
- RestServer: It provides a RESTful API that, based on different HTTP requests, calls the corresponding Core API. If the user’s request body is a Gremlin statement, it will be forwarded to GremlinServer to perform operations on the graph data.
Now let’s introduce these three configuration files one by one.
2. gremlin-server.yaml
The main structure of gremlin-server.yaml is shown below. Some imports are omitted from this example; refer to the file included in the release package for the complete content.
In most cases, you only need to pay attention to channelizer, host, and port. Graphs are not loaded from the Gremlin Server graphs section. Whether local graph configurations are loaded is controlled by graph.load_from_local_config in rest-server.properties.
channelizer: The defaultWsAndHttpChannelizersupports both WebSocket and HTTP. Gremlin Console uses WebSocket, while HugeGraph Client, Loader, and Hubble use HTTP.
By default, the GremlinServer serves at localhost:8182. If you need to modify it, configure the host and port settings.
host: The hostname or IP address of the machine where the GremlinServer is deployed. Currently, HugeGraphServer does not support distributed deployment, and GremlinServer is not directly exposed to users.port: The port number of the machine where the GremlinServer is deployed.
Additionally, you need to add the corresponding configuration gremlinserver.url=http://host:port in rest-server.properties.
3. rest-server.properties
The following is an example of the available rest-server.properties options. The current upstream release template does not include graph.load_from_local_config, whose source-code default is false; set it explicitly to true when using local graph configurations under conf/graphs.
restserver.url: The URL at which the RestServer provides its services. Modify it according to the actual environment. If you can’t connet to server from other IP address, try to modify it as specific IP; or modify it ashttp://0.0.0.0to listen all network interfaces as a convenient solution, but need to take care of the network area that might access.graphs: The directory containing graph configuration files. The default is./conf/graphs.init-storescans this directory; the Server loads its properties files only whengraph.load_from_local_config=true.graph.load_from_local_config: Whether the Server reads local graph configurations at startup. Its default value in the source code isfalse.
The current upstream template still uses
arthas.telnet_port,arthas.http_port, andarthas.disabled_commands, butServerOptionsreads the camelCase names shown in the example above. Custom configurations should usearthas.telnetPort,arthas.httpPort, andarthas.disabledCommands.
The
gremlinserver.urlconfiguration option is the URL at which the GremlinServer provides services to the RestServer. By default, it is set tohttp://localhost:8182. If you need to modify it, it should match thehostandportsettings ingremlin-server.yaml.
4. hugegraph.properties
hugegraph.properties is a type of file. If the system has multiple graphs, there will be multiple similar files. This file is used to configure parameters related to graph storage and querying. The default content of the file is as follows:
Pay attention to the following uncommented items:
gremlin.graph: The entry point for GremlinServer startup. Users should not modify this item.backend: The storage backend. Version 1.7.0 supportsmemory,rocksdb,hstore, andhbase.serializer: The serializer used when writing schemas, vertices, and edges to the backend. RocksDB usesbinary.store: The storage name used by the graph in the backend.rocksdb.data_path: This item is only meaningful when the backend is set torocksdb. It specifies the data directory for RocksDB.rocksdb.wal_path: This item is only meaningful when the backend is set torocksdb. It specifies the log directory for RocksDB.
5. Multi-Graph Configuration
A Server can load multiple graphs, with a separate properties file for each graph. The following example creates a RocksDB graph named hugegraph_rocksdb and an in-memory graph named hugegraph_memory.
[Optional]: Modify rest-server.properties
You can modify the graph profile directory in the graphs option of rest-server.properties. The default configuration is graphs=./conf/graphs, if you want to change it to another directory then adjust the graphs option, e.g. adjust it to graphs=/etc/hugegraph/graphs, example is as follows:
Under conf/graphs, create hugegraph_memory.properties and hugegraph_rocksdb.properties based on hugegraph.properties.
Configure hugegraph_memory.properties as follows:
Configure hugegraph_rocksdb.properties as follows:
Stop the server, execute init-store.sh (to create a new database for the new graph), and restart the server.
Check out created graphs:
Get details of a graph:
4.2 - Server Complete Configuration Manual
Gremlin Server Config Options
Corresponding configuration file gremlin-server.yaml
| config option | default value | description |
|---|---|---|
| host | 127.0.0.1 | The host or ip of Gremlin Server. |
| port | 8182 | The listening port of Gremlin Server. |
| graphs | {} | Graphs are loaded dynamically by the Server; do not configure them here. |
| evaluationTimeout | 30000 | Gremlin script evaluation timeout in milliseconds. |
| channelizer | org.apache.tinkerpop.gremlin.server.channel.WsAndHttpChannelizer | Handles both WebSocket and HTTP requests. |
| authentication | Not configured | When enabling authentication, configure the authenticator, handler, and path to rest-server.properties. |
Rest Server & API Config Options
Corresponding configuration file rest-server.properties
| config option | default value | description |
|---|---|---|
| graphs | ./conf/graphs | Directory containing graph configuration properties files. |
| graph.load_from_local_config | false | Whether to read the graphs directory when the Server starts; set to true when using local graph configuration. |
| server.id | Empty string | The id of rest server, used for license verification. |
| server.role | master | The role of nodes in the cluster, available types are [master, worker, computer] |
| restserver.url | http://127.0.0.1:8080 | The url for listening of rest server. |
| ssl.keystore_file | conf/hugegraph-server.keystore | The path of server keystore file used when https protocol is enabled. |
| ssl.keystore_password | hugegraph | The password of the server keystore file used when the https protocol is enabled. |
| restserver.max_worker_threads | 2 * CPUs | The maximum worker threads of rest server. |
| restserver.min_free_memory | 64 | The minimum free memory(MB) of rest server, requests will be rejected when the available memory of system is lower than this value. |
| restserver.request_timeout | 30 | The time in seconds within which a request must complete, -1 means no timeout. |
| restserver.connection_idle_timeout | 30 | The time in seconds to keep an inactive connection alive, -1 means no timeout. |
| restserver.connection_max_requests | 256 | The max number of HTTP requests allowed to be processed on one keep-alive connection, -1 means unlimited. |
| gremlinserver.url | http://127.0.0.1:8182 | The url of gremlin server. |
| gremlinserver.max_route | 8 | The max route number for gremlin server. |
| gremlinserver.timeout | 30 | The timeout in seconds of waiting for gremlin server. |
| batch.max_edges_per_batch | 2500 | The maximum number of edges submitted per batch. |
| batch.max_vertices_per_batch | 2500 | The maximum number of vertices submitted per batch. |
| batch.max_write_ratio | 70 | The maximum thread ratio for batch writing, only take effect if the batch.max_write_threads is 0. |
| batch.max_write_threads | 0 | The maximum threads for batch writing, if the value is 0, the actual value will be set to batch.max_write_ratio * restserver.max_worker_threads. |
| auth.authenticator | The class path of authenticator implementation. e.g., org.apache.hugegraph.auth.StandardAuthenticator, or a custom implementation. | |
| auth.graph_store | hugegraph | The name of graph used to store authentication information, like users, only for org.apache.hugegraph.auth.StandardAuthenticator. |
| auth.admin_pa | pa | Initial password for the built-in admin user in PD mode. It only applies when the user is first created and must be changed before deployment. |
| auth.audit_log_rate | 1000.0 | The max rate of audit log output per user, default value is 1000 records per second. |
| auth.cache_capacity | 10240 | The max cache capacity of each auth cache item. |
| auth.cache_expire | 600 | The expiration time in seconds of vertex cache. |
| auth.remote_url | If the address is empty, it provide auth service, otherwise it is auth client and also provide auth service through rpc forwarding. The remote url can be set to multiple addresses, which are concat by ‘,’. | |
| auth.token_expire | 86400 | The expiration time in seconds after token created |
| auth.token_secret | Randomly generated at startup | HS256 secret; configure it explicitly if existing tokens must remain valid across restarts. |
| exception.allow_trace | true | Whether to allow exception trace stack. |
| memory_monitor.threshold | 0.85 | The threshold of JVM(in-heap) memory usage monitoring , 1 means disabling this function. |
| memory_monitor.period | 2000 | The period in ms of JVM(in-heap) memory usage monitoring. |
| log.slow_query_threshold | 1000 | Slow query log threshold in milliseconds, 0 means disabled. |
| log.slow_query_body_limit | 512 | Maximum bytes of a request body recorded in the slow query log, 0 means disabled. The recorded prefix may contain sensitive Gremlin or Cypher literals. |
PD/Meta Config Options (Distributed Mode)
Corresponding configuration file rest-server.properties
| config option | default value | description |
|---|---|---|
| pd.peers | 127.0.0.1:8686 | PD server addresses (comma separated). |
| meta.endpoints | http://127.0.0.1:2379 | Meta service endpoints. |
| usePD | false | Whether to use PD to manage distributed metadata. |
Basic Config Options
Basic Config Options and Backend Config Options correspond to configuration files:{graph-name}.properties, such as hugegraph.properties
| config option | default value | description |
|---|---|---|
| gremlin.graph | org.apache.hugegraph.HugeFactory | Gremlin entrance to create graph. |
| backend | rocksdb | The data store type. For version 1.7.0+: [memory, rocksdb, hstore, hbase]. Note: cassandra, scylladb, mysql, postgresql were removed in 1.7.0 (use <= 1.5.x for legacy backends). |
| serializer | binary | The serializer for backend store, available values are [text, binary, cassandra, hbase, mysql]. |
| store | hugegraph | The database name like Cassandra Keyspace. |
| store.connection_detect_interval | 600 | The interval in seconds for detecting connections, if the idle time of a connection exceeds this value, detect it and reconnect if needed before using, value 0 means detecting every time. |
| store.graph | g | The graph table name, which store vertex, edge and property. |
| store.schema | m | The schema table name, which store meta data. |
| store.system | s | The system table name, which store system data. |
| schema.illegal_name_regex | .\s+$|~. | The regex specified the illegal format for schema name. |
| schema.cache_capacity | 10000 | The max cache size(items) of schema cache. |
| vertex.cache_type | l2 | The type of vertex cache, allowed values are [l1, l2]. |
| vertex.cache_capacity | 10000000 | The max cache size(items) of vertex cache. |
| vertex.cache_expire | 600 | The expire time in seconds of vertex cache. |
| vertex.check_customized_id_exist | false | Whether to check the vertices exist for those using customized id strategy. |
| vertex.default_label | vertex | The default vertex label. |
| vertex.tx_capacity | 10000 | The max size(items) of vertices(uncommitted) in transaction. |
| vertex.check_adjacent_vertex_exist | false | Whether to check the adjacent vertices of edges exist. |
| vertex.lazy_load_adjacent_vertex | true | Whether to lazy load adjacent vertices of edges. |
| vertex.part_edge_commit_size | 5000 | Whether to enable the mode to commit part of edges of vertex, enabled if commit size > 0, 0 means disabled. |
| vertex.encode_primary_key_number | true | Whether to encode number value of primary key in vertex id. |
| vertex.remove_left_index_at_overwrite | false | Whether remove left index at overwrite. |
| edge.cache_type | l2 | The type of edge cache, allowed values are [l1, l2]. |
| edge.cache_capacity | 1000000 | The max cache size(items) of edge cache. |
| edge.cache_expire | 600 | The expiration time in seconds of edge cache. |
| edge.tx_capacity | 10000 | The max size(items) of edges(uncommitted) in transaction. |
| query.page_size | 500 | The size of each page when querying by paging. |
| query.batch_size | 1000 | The size of each batch when querying by batch. |
| query.ignore_invalid_data | true | Whether to ignore invalid data of vertex or edge. |
| query.index_intersect_threshold | 1000 | The maximum number of intermediate results to intersect indexes when querying by multiple single index properties. |
| query.ramtable_edges_capacity | 20000000 | The maximum number of edges in ramtable, include OUT and IN edges. |
| query.ramtable_enable | false | Whether to enable ramtable for query of adjacent edges. |
| query.ramtable_vertices_capacity | 10000000 | The maximum number of vertices in ramtable, generally the largest vertex id is used as capacity. |
| query.optimize_aggregate_by_index | false | Whether to optimize aggregate query(like count) by index. |
| oltp.concurrent_depth | 10 | The min depth to enable concurrent oltp algorithm. |
| oltp.concurrent_threads | 10 | Thread number to concurrently execute oltp algorithm. |
| oltp.collection_type | EC | The implementation type of collections used in oltp algorithm. |
| rate_limit.read | 0 | The max rate(times/s) to execute query of vertices/edges. |
| rate_limit.write | 0 | The max rate(items/s) to add/update/delete vertices/edges. |
| task.wait_timeout | 10 | Timeout in seconds for waiting for the task to complete,such as when truncating or clearing the backend. |
| task.input_size_limit | 16777216 | The job input size limit in bytes. |
| task.result_size_limit | 16777216 | The job result size limit in bytes. |
| task.sync_deletion | false | Whether to delete schema or expired data synchronously. |
| task.ttl_delete_batch | 1 | The batch size used to delete expired data. |
| computer.config | /conf/computer.yaml | The config file path of computer job. |
| search.text_analyzer | ikanalyzer | Choose a text analyzer for searching the vertex/edge properties, available type are [word, ansj, hanlp, smartcn, jieba, jcseg, mmseg4j, ikanalyzer]. if use ‘ikanalyzer’, need download jar from ‘https://github.com/apache/hugegraph-doc/raw/ik_binary/dist/server/ikanalyzer-2012_u6.jar' to lib directory |
| search.text_analyzer_mode | smart | Specify the mode for the text analyzer, the available mode of analyzer are {word: [MaximumMatching, ReverseMaximumMatching, MinimumMatching, ReverseMinimumMatching, BidirectionalMaximumMatching, BidirectionalMinimumMatching, BidirectionalMaximumMinimumMatching, FullSegmentation, MinimalWordCount, MaxNgramScore, PureEnglish], ansj: [BaseAnalysis, IndexAnalysis, ToAnalysis, NlpAnalysis], hanlp: [standard, nlp, index, nShort, shortest, speed], smartcn: [], jieba: [SEARCH, INDEX], jcseg: [Simple, Complex], mmseg4j: [Simple, Complex, MaxWord], ikanalyzer: [smart, max_word]}. |
| snowflake.datacenter_id | 0 | The datacenter id of snowflake id generator. |
| snowflake.force_string | false | Whether to force the snowflake long id to be a string. |
| snowflake.worker_id | 0 | The worker id of snowflake id generator. |
| raft.mode | false | Whether the backend storage works in raft mode. |
| raft.safe_read | false | Whether to use linearly consistent read. |
| raft.use_snapshot | false | Whether to use snapshot. |
| raft.endpoint | 127.0.0.1:8281 | The peerid of current raft node. |
| raft.group_peers | 127.0.0.1:8281,127.0.0.1:8282,127.0.0.1:8283 | The peers of current raft group. |
| raft.path | ./raft-log | The log path of current raft node. |
| raft.use_replicator_pipeline | true | Whether to use replicator line, when turned on it multiple logs can be sent in parallel, and the next log doesn’t have to wait for the ack message of the current log to be sent. |
| raft.election_timeout | 10000 | Timeout in milliseconds to launch a round of election. |
| raft.snapshot_interval | 3600 | The interval in seconds to trigger snapshot save. |
| raft.backend_threads | current CPU v-cores | The thread number used to apply task to backend. |
| raft.read_index_threads | 8 | The thread number used to execute reading index. |
| raft.apply_batch | 1 | The apply batch size to trigger disruptor event handler. |
| raft.queue_size | 16384 | The disruptor buffers size for jraft RaftNode, StateMachine and LogManager. |
| raft.queue_publish_timeout | 60 | The timeout in second when publish event into disruptor. |
| raft.rpc_threads | 80 | The rpc threads for jraft RPC layer. |
| raft.rpc_connect_timeout | 5000 | The rpc connect timeout for jraft rpc. |
| raft.rpc_timeout | 60000 | The rpc timeout for jraft rpc. |
| raft.rpc_buf_low_water_mark | 10485760 | The ChannelOutboundBuffer’s low water mark of netty, when buffer size less than this size, the method ChannelOutboundBuffer.isWritable() will return true, it means that low downstream pressure or good network. |
| raft.rpc_buf_high_water_mark | 20971520 | The ChannelOutboundBuffer’s high water mark of netty, only when buffer size exceed this size, the method ChannelOutboundBuffer.isWritable() will return false, it means that the downstream pressure is too great to process the request or network is very congestion, upstream needs to limit rate at this time. |
| raft.read_strategy | ReadOnlyLeaseBased | The linearizability of read strategy. |
RocksDB Backend Config Options
| config option | default value | description |
|---|---|---|
| backend | Must be set to rocksdb. | |
| serializer | Must be set to binary. | |
| rocksdb.data_disks | [] | The optimized disks for storing data of RocksDB. The format of each element: STORE/TABLE: /path/disk.Allowed keys are [g/vertex, g/edge_out, g/edge_in, g/vertex_label_index, g/edge_label_index, g/range_int_index, g/range_float_index, g/range_long_index, g/range_double_index, g/secondary_index, g/search_index, g/shard_index, g/unique_index, g/olap] |
| rocksdb.data_path | rocksdb-data/data | The path for storing data of RocksDB. |
| rocksdb.wal_path | rocksdb-data/wal | The path for storing WAL of RocksDB. |
| rocksdb.option_path | The YAML file for configuring ToplingDB/RocksDB parameters. | |
| rocksdb.open_http | false | Whether to start ToplingDB HTTP service. Security: enable only in trusted networks and restrict access (firewall/ACL); the port and document_root are configured in the YAML (http.listening_ports/document_root). |
| rocksdb.allow_mmap_reads | false | Allow the OS to mmap file for reading sst tables. |
| rocksdb.allow_mmap_writes | false | Allow the OS to mmap file for writing. |
| rocksdb.block_cache_capacity | 8388608 | The amount of block cache in bytes that will be used by RocksDB, 0 means no block cache. |
| rocksdb.bloom_filter_bits_per_key | -1 | The bits per key in bloom filter, a good value is 10, which yields a filter with ~ 1% false positive rate, -1 means no bloom filter. |
| rocksdb.bloom_filter_block_based_mode | false | Use block based filter rather than full filter. |
| rocksdb.bloom_filter_whole_key_filtering | true | True if place whole keys in the bloom filter, else place the prefix of keys. |
| rocksdb.bottommost_compression | NO_COMPRESSION | The compression algorithm for the bottommost level of RocksDB, allowed values are none/snappy/z/bzip2/lz4/lz4hc/xpress/zstd. |
| rocksdb.bulkload_mode | false | Switch to the mode to bulk load data into RocksDB. |
| rocksdb.cache_index_and_filter_blocks | false | Indicating if we’d put index/filter blocks to the block cache. |
| rocksdb.compaction_style | LEVEL | Set compaction style for RocksDB: LEVEL/UNIVERSAL/FIFO. |
| rocksdb.compression | SNAPPY_COMPRESSION | The compression algorithm for compressing blocks of RocksDB, allowed values are none/snappy/z/bzip2/lz4/lz4hc/xpress/zstd. |
| rocksdb.compression_per_level | [NO_COMPRESSION, NO_COMPRESSION, SNAPPY_COMPRESSION, SNAPPY_COMPRESSION, SNAPPY_COMPRESSION, SNAPPY_COMPRESSION, SNAPPY_COMPRESSION] | The compression algorithms for different levels of RocksDB, allowed values are none/snappy/z/bzip2/lz4/lz4hc/xpress/zstd. |
| rocksdb.delayed_write_rate | 16777216 | The rate limit in bytes/s of user write requests when need to slow down if the compaction gets behind. |
| rocksdb.log_level | INFO | The info log level of RocksDB. |
| rocksdb.max_background_jobs | 8 | Maximum number of concurrent background jobs, including flushes and compactions. |
| rocksdb.level_compaction_dynamic_level_bytes | false | Whether to enable level_compaction_dynamic_level_bytes, if it’s enabled we give max_bytes_for_level_multiplier a priority against max_bytes_for_level_base, the bytes of base level is dynamic for a more predictable LSM tree, it is useful to limit worse case space amplification. Turning this feature on/off for an existing DB can cause unexpected LSM tree structure so it’s not recommended. |
| rocksdb.max_bytes_for_level_base | 536870912 | The upper-bound of the total size of level-1 files in bytes. |
| rocksdb.max_bytes_for_level_multiplier | 10.0 | The ratio between the total size of level (L+1) files and the total size of level L files for all L. |
| rocksdb.max_open_files | -1 | The maximum number of open files that can be cached by RocksDB, -1 means no limit. |
| rocksdb.max_subcompactions | 4 | The value represents the maximum number of threads per compaction job. |
| rocksdb.max_write_buffer_number | 6 | The maximum number of write buffers that are built up in memory. |
| rocksdb.max_write_buffer_number_to_maintain | 0 | The total maximum number of write buffers to maintain in memory. |
| rocksdb.min_write_buffer_number_to_merge | 2 | The minimum number of write buffers that will be merged together. |
| rocksdb.num_levels | 7 | Set the number of levels for this database. |
| rocksdb.optimize_filters_for_hits | false | This flag allows us to not store filters for the last level. |
| rocksdb.optimize_mode | true | Optimize for heavy workloads and big datasets. |
| rocksdb.pin_l0_filter_and_index_blocks_in_cache | false | Indicating if we’d put index/filter blocks to the block cache. |
| rocksdb.sst_path | The path for ingesting SST file into RocksDB. | |
| rocksdb.target_file_size_base | 67108864 | The target file size for compaction in bytes. |
| rocksdb.target_file_size_multiplier | 1 | The size ratio between a level L file and a level (L+1) file. |
| rocksdb.use_direct_io_for_flush_and_compaction | false | Enable the OS to use direct read/writes in flush and compaction. |
| rocksdb.use_direct_reads | false | Enable the OS to use direct I/O for reading sst tables. |
| rocksdb.write_buffer_size | 134217728 | Amount of data in bytes to build up in memory. |
| rocksdb.max_manifest_file_size | 104857600 | The max size of manifest file in bytes. |
| rocksdb.skip_stats_update_on_db_open | false | Whether to skip statistics update when opening the database, setting this flag true allows us to not update statistics. |
| rocksdb.max_file_opening_threads | 16 | The max number of threads used to open files. |
| rocksdb.max_total_wal_size | 0 | Total size of WAL files in bytes. Once WALs exceed this size, we will start forcing the flush of column families related, 0 means no limit. |
| rocksdb.db_write_buffer_size | 0 | Total size of write buffers in bytes across all column families, 0 means no limit. |
| rocksdb.delete_obsolete_files_period | 21600 | The periodicity in seconds when obsolete files get deleted, 0 means always do full purge. |
| rocksdb.hard_pending_compaction_bytes_limit | 274877906944 | The hard limit to impose on pending compaction in bytes. |
| rocksdb.level0_file_num_compaction_trigger | 2 | Number of files to trigger level-0 compaction. |
| rocksdb.level0_slowdown_writes_trigger | 20 | Soft limit on number of level-0 files for slowing down writes. |
| rocksdb.level0_stop_writes_trigger | 36 | Hard limit on number of level-0 files for stopping writes. |
| rocksdb.soft_pending_compaction_bytes_limit | 68719476736 | The soft limit to impose on pending compaction in bytes. |
Corresponding configuration file rest-server.properties
| config option | default value | description |
|---|---|---|
| server.use_k8s | false | Whether to enable K8s multi-tenancy mode. |
| k8s.namespace | hugegraph-computer-system | K8s namespace for compute jobs. |
| k8s.kubeconfig | Path to kubeconfig file. |
Corresponding configuration file rest-server.properties
| config option | default value | description |
|---|---|---|
| arthas.telnetPort | 8562 | Arthas telnet port. |
| arthas.httpPort | 8561 | Arthas HTTP port. |
| arthas.ip | 0.0.0.0 | Arthas bind IP. |
| arthas.disabledCommands | jad | Disabled Arthas commands, separated by commas. |
| config option | default value | description |
|---|---|---|
| backend | Must be set to hbase. | |
| serializer | Must be set to hbase. | |
| hbase.hosts | localhost | The hostnames or ip addresses of HBase zookeeper, separated with commas. |
| hbase.port | 2181 | The port address of HBase zookeeper. |
| hbase.threads_max | 64 | The max threads num of hbase connections. |
| hbase.znode_parent | /hbase | The znode parent path of HBase zookeeper. |
| hbase.zk_retry | 3 | The recovery retry times of HBase zookeeper. |
| hbase.aggregation_timeout | 43200 | The timeout in seconds of waiting for aggregation. |
| hbase.kerberos_enable | false | Is Kerberos authentication enabled for HBase. |
| hbase.kerberos_keytab | The HBase’s key tab file for kerberos authentication. | |
| hbase.kerberos_principal | The HBase’s principal for kerberos authentication. | |
| hbase.krb5_conf | etc/krb5.conf | Kerberos configuration file, including KDC IP, default realm, etc. |
| hbase.hbase_site | /etc/hbase/conf/hbase-site.xml | The HBase’s configuration file |
| hbase.enable_partition | true | Is pre-split partitions enabled for HBase. |
| hbase.vertex_partitions | 10 | The number of partitions of the HBase vertex table. |
| hbase.edge_partitions | 30 | The number of partitions of the HBase edge table. |
≤ 1.5 Version Config (Legacy)
The following backend stores are no longer supported in version 1.7.0+ and are only available in version 1.5.x and earlier:
| config option | default value | description |
|---|---|---|
| backend | Must be set to cassandra. | |
| serializer | Must be set to cassandra. | |
| cassandra.host | localhost | The seeds hostname or ip address of cassandra cluster. |
| cassandra.port | 9042 | The seeds port address of cassandra cluster. |
| cassandra.connect_timeout | 5 | The cassandra driver connect server timeout(seconds). |
| cassandra.read_timeout | 20 | The cassandra driver read from server timeout(seconds). |
| cassandra.keyspace.strategy | SimpleStrategy | The replication strategy of keyspace, valid value is SimpleStrategy or NetworkTopologyStrategy. |
| cassandra.keyspace.replication | [3] | The keyspace replication factor of SimpleStrategy, like ‘[3]’.Or replicas in each datacenter of NetworkTopologyStrategy, like ‘[dc1:2,dc2:1]’. |
| cassandra.username | The username to use to login to cassandra cluster. | |
| cassandra.password | The password corresponding to cassandra.username. | |
| cassandra.compression_type | none | The compression algorithm of cassandra transport: none/snappy/lz4. |
| cassandra.jmx_port=7199 | 7199 | The port of JMX API service for cassandra. |
| cassandra.aggregation_timeout | 43200 | The timeout in seconds of waiting for aggregation. |
| config option | default value | description |
|---|---|---|
| backend | Must be set to scylladb. | |
| serializer | Must be set to scylladb. |
Other options are consistent with the Cassandra backend.
| config option | default value | description |
|---|---|---|
| backend | Must be set to mysql. | |
| serializer | Must be set to mysql. | |
| jdbc.driver | com.mysql.jdbc.Driver | The JDBC driver class to connect database. |
| jdbc.url | jdbc:mysql://127.0.0.1:3306 | The url of database in JDBC format. |
| jdbc.username | root | The username to login database. |
| jdbc.password | ****** | The password corresponding to jdbc.username. |
| jdbc.ssl_mode | false | The SSL mode of connections with database. |
| jdbc.reconnect_interval | 3 | The interval(seconds) between reconnections when the database connection fails. |
| jdbc.reconnect_max_times | 3 | The reconnect times when the database connection fails. |
| jdbc.storage_engine | InnoDB | The storage engine of backend store database, like InnoDB/MyISAM/RocksDB for MySQL. |
| jdbc.postgresql.connect_database | template1 | The database used to connect when init store, drop store or check store exist. |
| config option | default value | description |
|---|---|---|
| backend | Must be set to postgresql. | |
| serializer | Must be set to postgresql. |
Other options are consistent with the MySQL backend.
The driver and url of the PostgreSQL backend should be set to:
jdbc.driver=org.postgresql.Driverjdbc.url=jdbc:postgresql://localhost:5432/
4.3 - Built-in User Authentication and Authorization Configuration and Usage in HugeGraph
Overview
To facilitate authentication usage in different user scenarios, HugeGraph currently provides built-in authorization StandardAuthenticator mode,
which supports multi-user authentication and fine-grained access control. It adopts a 4-layer design based on “User-UserGroup-Operation-Resource” to
flexibly control user roles and permissions (supports multiple GraphServers).
Some key designs of the StandardAuthenticator mode include:
- During initialization, a super administrator (
admin) user is created. Subsequently, other users can be created by the super administrator. Once newly created users are assigned sufficient permissions, they can create or manage more users. - It supports dynamic creation of users, user groups, and resources, as well as dynamic allocation or revocation of permissions.
- Users can belong to one or multiple user groups. Each user group can have permissions to operate on any number of resources. The types of operations include read, write, delete, execute, and others.
- “Resource” describes the data in the graph database, such as vertices that meet certain criteria. Each resource consists of three elements:
type,label, andproperties. There are 18 types in total, with the ability to combine any label and properties. The internal condition of a resource is an AND relationship, while the condition between multiple resources is an OR relationship.
Here is an example to illustrate:
Configure User Authentication
By default, HugeGraph does not enable user authentication, and it needs to be enabled by modifying the configuration file.
Because the flexibility of graph query languages can introduce potential system security risks, do not expose Gremlin, Cypher, or other query endpoints directly to the public network. In production, enable authentication, an IP allowlist, and audit logging, and isolate the Server process with Docker or Kubernetes.
You need to modify the configuration file to enable this feature. HugeGraph provides built-in authentication mode: StandardAuthenticator. This mode supports multi-user authentication and fine-grained permission control. Additionally, developers can implement their own HugeAuthenticator interface to integrate with their existing authentication systems.
HugeGraph uses HTTP Basic Authentication. The value after
Basic is the Base64 encoding of username:password. With curl, pass the credentials directly through -u:
Warning: Versions of HugeGraph-Server prior to 1.5.0 have a JWT-related security vulnerability in the Auth mode.
Users are advised to update to a newer version or manually set the JWT token’s secretKey. It can be set in the rest-server.properties file by setting the auth.token_secret information:
You can also generate it with the following command:
StandardAuthenticator Mode
The StandardAuthenticator mode supports user authentication and permission control by storing user information in the database backend. This
implementation authenticates users based on their names and passwords (encrypted) stored in the database and controls user permissions based on their
roles. Below is the specific configuration process (requires service restart):
Configure the authenticator and its rest-server file path in the gremlin-server.yaml configuration file:
Configure the authenticator and the graph that stores authorization data in rest-server.properties:
In the above configuration, the graph_store option specifies which graph to use for storing user information. If there are multiple graphs, you can choose any of them.
In the hugegraph{n}.properties configuration file, configure the gremlin.graph information:
For authorization API usage, see the Authentication API documentation.
Custom User Authentication System
If you need to support a more flexible user system, you can customize the authenticator for extension.
Simply implement the org.apache.hugegraph.auth.HugeAuthenticator interface with your custom authenticator,
and then modify the authenticator configuration item in the configuration file to point to your implementation.
Switching authentication mode
When init-store.sh is run for the first time and the admin user does not yet exist, the command prompts for the
administrator password. For an initialized persistent backend, init-store.sh adds the system metadata required for
authentication without deleting existing graph data.
Use docker to enable authentication mode
For versions of the hugegraph/hugegraph image equal to or greater than 1.2.0, you can enable authentication mode while starting the Docker image.
The steps are as follows:
1. Use docker run
To enable authentication mode, add the environment variable PASSWORD=xxx (you can freely set the password) in the docker run command:
2. Use docker-compose
Use docker-compose and set the environment variable PASSWORD=xxx:
3. Enter the container to enable authentication mode
Enter the container first:
Then follow Switching authentication mode
4.4 - Configuring HugeGraphServer to Use HTTPS Protocol
Overview
By default, HugeGraphServer uses the HTTP protocol. However, if you have security requirements for your requests, you can configure it to use HTTPS.
Server Configuration
Modify the conf/rest-server.properties configuration file and change the schema part of restserver.url to https.
The server’s conf directory already includes a keystore file named hugegraph-server.keystore, and the password for this file is hugegraph. These are the default values when enabling the HTTPS protocol. Users can generate their own keystore file and password, and then modify the values of ssl.keystore_file and ssl.keystore_password.
Client Configuration
Using HTTPS in HugeGraph-Client
When constructing a HugeClient, pass the HTTPS-related configurations. Here’s an example in Java:
Note: Before version 1.9.0, HugeGraph-Client was created directly using the
newkeyword and did not support the HTTPS protocol. Starting from version 1.9.0, it changed to use the builder pattern and supports configuring the HTTPS protocol.
Using HTTPS in HugeGraph-Loader
When starting an import task, add the following options in the command line:
Under the conf directory of hugegraph-loader, there is already a default client certificate file named hugegraph.truststore, and its password is hugegraph.
Using HTTPS in HugeGraph-Tools
When executing commands, add the following options in the command line:
Under the conf directory of hugegraph-tools, there is already a default client certificate file named hugegraph.truststore, and its password is hugegraph.
How to Generate Certificate Files
This section provides an example of generating certificates. If the default certificate is sufficient or if you already know how to generate certificates, you can skip this section.
Server
- Generate the server’s private key and import it into the server’s keystore file. The
server.keystoreis for the server’s use and contains its private key.
During the process, fill in the description information according to your requirements. The description information for the default certificate is as follows:
- Export the server certificate based on the server’s private key.
server.crt is the server’s certificate.
Client
client.truststore is for the client’s use and contains the trusted certificate.
4.5 - HugeGraph-Computer Config
Computer Config Options
| config option | default value | description |
|---|---|---|
| algorithm.message_class | org.apache.hugegraph.computer.core.config.Null | The class of message passed when compute vertex. |
| algorithm.params_class | org.apache.hugegraph.computer.core.config.Null | The class used to transfer algorithms’ parameters before algorithm been run. |
| algorithm.result_class | org.apache.hugegraph.computer.core.config.Null | The class of vertex’s value, the instance is used to store computation result for the vertex. |
| allocator.max_vertices_per_thread | 10000 | Maximum number of vertices per thread processed in each memory allocator |
| bsp.etcd_endpoints | http://localhost:2379 | The end points to access etcd. |
| bsp.log_interval | 30000 | The log interval(in ms) to print the log while waiting bsp event. |
| bsp.max_super_step | 10 | The max super step of the algorithm. |
| bsp.register_timeout | 300000 | The max timeout to wait for master and works to register. |
| bsp.wait_master_timeout | 86400000 | The max timeout(in ms) to wait for master bsp event. |
| bsp.wait_workers_timeout | 86400000 | The max timeout to wait for workers bsp event. |
| hgkv.max_data_block_size | 65536 | The max byte size of hgkv-file data block. |
| hgkv.max_file_size | 2147483648 | The max number of bytes in each hgkv-file. |
| hgkv.max_merge_files | 10 | The max number of files to merge at one time. |
| hgkv.temp_file_dir | /tmp/hgkv | This folder is used to store temporary files, temporary files will be generated during the file merging process. |
| hugegraph.name | hugegraph | The graph name to load data and write results back. |
| hugegraph.url | http://127.0.0.1:8080 | The hugegraph url to load data and write results back. |
| input.edge_direction | OUT | The data of the edge in which direction is loaded, when the value is BOTH, the edges in both OUT and IN direction will be loaded. |
| input.edge_freq | MULTIPLE | The frequency of edges can exist between a pair of vertices, allowed values: [SINGLE, SINGLE_PER_LABEL, MULTIPLE]. SINGLE means that only one edge can exist between a pair of vertices, use sourceId + targetId to identify it; SINGLE_PER_LABEL means that each edge label can exist one edge between a pair of vertices, use sourceId + edgelabel + targetId to identify it; MULTIPLE means that many edge can exist between a pair of vertices, use sourceId + edgelabel + sortValues + targetId to identify it. |
| input.filter_class | org.apache.hugegraph.computer.core.input.filter.DefaultInputFilter | The class to create input-filter object, input-filter is used to Filter vertex edges according to user needs. |
| input.loader_schema_path | The schema path of loader input, only takes effect when the input.source_type=loader is enabled | |
| input.loader_struct_path | The struct path of loader input, only takes effect when the input.source_type=loader is enabled | |
| input.max_edges_in_one_vertex | 200 | The maximum number of adjacent edges allowed to be attached to a vertex, the adjacent edges will be stored and transferred together as a batch unit. |
| input.source_type | hugegraph-server | The source type to load input data, allowed values: [‘hugegraph-server’, ‘hugegraph-loader’], the ‘hugegraph-loader’ means use hugegraph-loader load data from HDFS or file, if use ‘hugegraph-loader’ load data then please config ‘input.loader_struct_path’ and ‘input.loader_schema_path’. |
| input.split_fetch_timeout | 300 | The timeout in seconds to fetch input splits |
| input.split_max_splits | 10000000 | The maximum number of input splits |
| input.split_page_size | 500 | The page size for streamed load input split data |
| input.split_size | 1048576 | The input split size in bytes |
| job.id | local_0001 | The job id on Yarn cluster or K8s cluster. |
| job.partitions_count | 1 | The partitions count for computing one graph algorithm job. |
| job.partitions_thread_nums | 4 | The number of threads for partition parallel compute. |
| job.workers_count | 1 | The workers count for computing one graph algorithm job. |
| master.computation_class | org.apache.hugegraph.computer.core.master.DefaultMasterComputation | Master-computation is computation that can determine whether to continue next superstep. It runs at the end of each superstep on master. |
| output.batch_size | 500 | The batch size of output |
| output.batch_threads | 1 | The threads number used to batch output |
| output.hdfs_core_site_path | The hdfs core site path. | |
| output.hdfs_delimiter | , | The delimiter of hdfs output. |
| output.hdfs_kerberos_enable | false | Is Kerberos authentication enabled for Hdfs. |
| output.hdfs_kerberos_keytab | The Hdfs’s key tab file for kerberos authentication. | |
| output.hdfs_kerberos_principal | The Hdfs’s principal for kerberos authentication. | |
| output.hdfs_krb5_conf | /etc/krb5.conf | Kerberos configuration file. |
| output.hdfs_merge_partitions | true | Whether merge output files of multiple partitions. |
| output.hdfs_path_prefix | /hugegraph-computer/results | The directory of hdfs output result. |
| output.hdfs_replication | 3 | The replication number of hdfs. |
| output.hdfs_site_path | The hdfs site path. | |
| output.hdfs_url | hdfs://127.0.0.1:9000 | The hdfs url of output. |
| output.hdfs_user | hadoop | The hdfs user of output. |
| output.output_class | org.apache.hugegraph.computer.core.output.LogOutput | The class to output the computation result of each vertex. Be called after iteration computation. |
| output.result_name | value | The value is assigned dynamically by #name() of instance created by WORKER_COMPUTATION_CLASS. |
| output.result_write_type | OLAP_COMMON | The result write-type to output to hugegraph, allowed values are: [OLAP_COMMON, OLAP_SECONDARY, OLAP_RANGE]. |
| output.retry_interval | 10 | The retry interval when output failed |
| output.retry_times | 3 | The retry times when output failed |
| output.single_threads | 1 | The threads number used to single output |
| output.thread_pool_shutdown_timeout | 60 | The timeout seconds of output threads pool shutdown |
| output.with_adjacent_edges | false | Output the adjacent edges of the vertex or not |
| output.with_edge_properties | false | Output the properties of the edge or not |
| output.with_vertex_properties | false | Output the properties of the vertex or not |
| sort.thread_nums | 4 | The number of threads performing internal sorting. |
| transport.client_connect_timeout | 3000 | The timeout(in ms) of client connect to server. |
| transport.client_threads | 4 | The number of transport threads for client. |
| transport.close_timeout | 10000 | The timeout(in ms) of close server or close client. |
| transport.finish_session_timeout | 0 | The timeout(in ms) to finish session, 0 means using (transport.sync_request_timeout * transport.max_pending_requests). |
| transport.heartbeat_interval | 20000 | The minimum interval(in ms) between heartbeats on client side. |
| transport.io_mode | AUTO | The network IO Mode, either ‘NIO’, ‘EPOLL’, ‘AUTO’, the ‘AUTO’ means selecting the property mode automatically. |
| transport.max_pending_requests | 8 | The max number of client unreceived ack, it will trigger the sending unavailable if the number of unreceived ack >= max_pending_requests. |
| transport.max_syn_backlog | 511 | The capacity of SYN queue on server side, 0 means using system default value. |
| transport.max_timeout_heartbeat_count | 120 | The maximum times of timeout heartbeat on client side, if the number of timeouts waiting for heartbeat response continuously > max_heartbeat_timeouts the channel will be closed from client side. |
| transport.min_ack_interval | 200 | The minimum interval(in ms) of server reply ack. |
| transport.min_pending_requests | 6 | The minimum number of client unreceived ack, it will trigger the sending available if the number of unreceived ack < min_pending_requests. |
| transport.network_retries | 3 | The number of retry attempts for network communication,if network unstable. |
| transport.provider_class | org.apache.hugegraph.computer.core.network.netty.NettyTransportProvider | The transport provider, currently only supports Netty. |
| transport.receive_buffer_size | 0 | The size of socket receive-buffer in bytes, 0 means using system default value. |
| transport.recv_file_mode | true | Whether enable receive buffer-file mode, it will receive buffer write file from socket by zero-copy if enable. |
| transport.send_buffer_size | 0 | The size of socket send-buffer in bytes, 0 means using system default value. |
| transport.server_host | 127.0.0.1 | The server hostname or ip to listen on to transfer data. |
| transport.server_idle_timeout | 360000 | The max timeout(in ms) of server idle. |
| transport.server_port | 0 | The server port to listen on to transfer data. The system will assign a random port if it’s set to 0. |
| transport.server_threads | 4 | The number of transport threads for server. |
| transport.sync_request_timeout | 10000 | The timeout(in ms) to wait response after sending sync-request. |
| transport.tcp_keep_alive | true | Whether enable TCP keep-alive. |
| transport.transport_epoll_lt | false | Whether enable EPOLL level-trigger. |
| transport.write_buffer_high_mark | 67108864 | The high water mark for write buffer in bytes, it will trigger the sending unavailable if the number of queued bytes > write_buffer_high_mark. |
| transport.write_buffer_low_mark | 33554432 | The low water mark for write buffer in bytes, it will trigger the sending available if the number of queued bytes < write_buffer_low_mark.org.apache.hugegraph.config.OptionChecker$$Lambda$97/0x00000008001c8440@776a6d9b |
| transport.write_socket_timeout | 3000 | The timeout(in ms) to write data to socket buffer. |
| valuefile.max_segment_size | 1073741824 | The max number of bytes in each segment of value-file. |
| worker.combiner_class | org.apache.hugegraph.computer.core.config.Null | Combiner can combine messages into one value for a vertex, for example page-rank algorithm can combine messages of a vertex to a sum value. |
| worker.computation_class | org.apache.hugegraph.computer.core.config.Null | The class to create worker-computation object, worker-computation is used to compute each vertex in each superstep. |
| worker.data_dirs | [jobs] | The directories separated by ‘,’ that received vertices and messages can persist into. |
| worker.edge_properties_combiner_class | org.apache.hugegraph.computer.core.combiner.OverwritePropertiesCombiner | The combiner can combine several properties of the same edge into one properties at inputstep. |
| worker.partitioner | org.apache.hugegraph.computer.core.graph.partition.HashPartitioner | The partitioner that decides which partition a vertex should be in, and which worker a partition should be in. |
| worker.received_buffers_bytes_limit | 104857600 | The limit bytes of buffers of received data, the total size of all buffers can’t excess this limit. If received buffers reach this limit, they will be merged into a file. |
| worker.vertex_properties_combiner_class | org.apache.hugegraph.computer.core.combiner.OverwritePropertiesCombiner | The combiner can combine several properties of the same vertex into one properties at inputstep. |
| worker.wait_finish_messages_timeout | 86400000 | The max timeout(in ms) message-handler wait for finish-message of all workers. |
| worker.wait_sort_timeout | 600000 | The max timeout(in ms) message-handler wait for sort-thread to sort one batch of buffers. |
| worker.write_buffer_capacity | 52428800 | The initial size of write buffer that used to store vertex or message. |
| worker.write_buffer_threshold | 52428800 | The threshold of write buffer, exceeding it will trigger sorting, the write buffer is used to store vertex or message. |
K8s Operator Config Options
NOTE: Option needs to be converted through environment variable settings, e.g. k8s.internal_etcd_url => INTERNAL_ETCD_URL
| config option | default value | description |
|---|---|---|
| k8s.auto_destroy_pod | true | Whether to automatically destroy all pods when the job is completed or failed. |
| k8s.close_reconciler_timeout | 120 | The max timeout(in ms) to close reconciler. |
| k8s.internal_etcd_url | http://127.0.0.1:2379 | The internal etcd url for operator system. |
| k8s.max_reconcile_retry | 3 | The max retry times of reconcile. |
| k8s.probe_backlog | 50 | The maximum backlog for serving health probes. |
| k8s.probe_port | 9892 | The value is the port that the controller bind to for serving health probes. |
| k8s.ready_check_internal | 1000 | The time interval(ms) of check ready. |
| k8s.ready_timeout | 30000 | The max timeout(in ms) of check ready. |
| k8s.reconciler_count | 10 | The max number of reconciler thread. |
| k8s.resync_period | 600000 | The minimum frequency at which watched resources are reconciled. |
| k8s.timezone | Asia/Shanghai | The timezone of computer job and operator. |
| k8s.watch_namespace | hugegraph-computer-system | The value is watch custom resources in the namespace, ignore other namespaces, the ‘*’ means is all namespaces will be watched. |
HugeGraph-Computer CRD
| spec | default value | description | required |
|---|---|---|---|
| algorithmName | The name of algorithm. | true | |
| jobId | The job id. | true | |
| image | The image of algorithm. | true | |
| computerConf | The map of computer config options. | true | |
| workerInstances | The number of worker instances, it will instead the ‘job.workers_count’ option. | true | |
| pullPolicy | Always | The pull-policy of image, detail please refer to: https://kubernetes.io/docs/concepts/containers/images/#image-pull-policy | false |
| pullSecrets | The pull-secrets of Image, detail please refer to: https://kubernetes.io/docs/concepts/containers/images/#specifying-imagepullsecrets-on-a-pod | false | |
| masterCpu | The cpu limit of master, the unit can be ’m’ or without unit detail please refer to:https://kubernetes.io/docs/concepts/configuration/manage-resources-containers/#meaning-of-cpu | false | |
| workerCpu | The cpu limit of worker, the unit can be ’m’ or without unit detail please refer to:https://kubernetes.io/docs/concepts/configuration/manage-resources-containers/#meaning-of-cpu | false | |
| masterMemory | The memory limit of master, the unit can be one of Ei、Pi、Ti、Gi、Mi、Ki detail please refer to:https://kubernetes.io/docs/concepts/configuration/manage-resources-containers/#meaning-of-memory | false | |
| workerMemory | The memory limit of worker, the unit can be one of Ei、Pi、Ti、Gi、Mi、Ki detail please refer to:https://kubernetes.io/docs/concepts/configuration/manage-resources-containers/#meaning-of-memory | false | |
| log4jXml | The content of log4j.xml for computer job. | false | |
| jarFile | The jar path of computer algorithm. | false | |
| remoteJarUri | The remote jar uri of computer algorithm, it will overlay algorithm image. | false | |
| jvmOptions | The java startup parameters of computer job. | false | |
| envVars | please refer to: https://kubernetes.io/docs/tasks/inject-data-application/define-interdependent-environment-variables/ | false | |
| envFrom | please refer to: https://kubernetes.io/docs/tasks/inject-data-application/define-environment-variable-container/ | false | |
| masterCommand | bin/start-computer.sh | The run command of master, equivalent to ‘Entrypoint’ field of Docker. | false |
| masterArgs | ["-r master", “-d k8s”] | The run args of master, equivalent to ‘Cmd’ field of Docker. | false |
| workerCommand | bin/start-computer.sh | The run command of worker, equivalent to ‘Entrypoint’ field of Docker. | false |
| workerArgs | ["-r worker", “-d k8s”] | The run args of worker, equivalent to ‘Cmd’ field of Docker. | false |
| volumes | Please refer to: https://kubernetes.io/docs/concepts/storage/volumes/ | false | |
| volumeMounts | Please refer to: https://kubernetes.io/docs/concepts/storage/volumes/ | false | |
| secretPaths | The map of k8s-secret name and mount path. | false | |
| configMapPaths | The map of k8s-configmap name and mount path. | false | |
| podTemplateSpec | Please refer to: https://kubernetes.io/docs/reference/kubernetes-api/workload-resources/pod-template-v1/#PodTemplateSpec | false | |
| securityContext | Please refer to: https://kubernetes.io/docs/tasks/configure-pod-container/security-context/ | false |
KubeDriver Config Options
| config option | default value | description |
|---|---|---|
| k8s.build_image_bash_path | The path of command used to build image. | |
| k8s.enable_internal_algorithm | true | Whether enable internal algorithm. |
| k8s.framework_image_url | hugegraph/hugegraph-computer:latest | The image url of computer framework. |
| k8s.image_repository_password | The password for login image repository. | |
| k8s.image_repository_registry | The address for login image repository. | |
| k8s.image_repository_url | hugegraph/hugegraph-computer | The url of image repository. |
| k8s.image_repository_username | The username for login image repository. | |
| k8s.internal_algorithm | [pageRank] | The name list of all internal algorithm. |
| k8s.internal_algorithm_image_url | hugegraph/hugegraph-computer:latest | The image url of internal algorithm. |
| k8s.jar_file_dir | /cache/jars/ | The directory where the algorithm jar to upload location. |
| k8s.kube_config | ~/.kube/config | The path of k8s config file. |
| k8s.log4j_xml_path | The log4j.xml path for computer job. | |
| k8s.namespace | hugegraph-computer-system | The namespace of hugegraph-computer system. |
| k8s.pull_secret_names | [] | The names of pull-secret for pulling image. |
5 - Clients and APIs
This section covers the REST API, Gremlin Console, and client libraries. The current Server REST API identifies graph resources with both a graph space and a graph name. Refer to each API page and the Server OpenAPI page for the exact paths.
5.1 - HugeGraph RESTful API
⚠️ Version compatibility notes
- Current graph resource paths begin with
/graphspaces/{graphspace}/graphs/{graph}.- HugeGraph 1.5.x and earlier use
/graphs/{graph}. The request formats of APIs such as graph creation and cloning also differ from the current version.- The default graph space is
DEFAULT.- See the HugeGraph 1.5.x RESTful API documentation for older versions.
After starting Server, open http://localhost:8080/swagger-ui/index.html to view the OpenAPI page for the current version. See the usage example.
5.1.1 - Graphspace API
2.0 Graphspace
HugeGraph implements multi-tenancy through graph spaces, which isolate compute/storage resources per tenant.
Prerequisites
- Graphspace currently only works in HStore mode.
- In non-HStore mode you can only use the default graphspace
DEFAULT; creating/deleting/updating other graphspaces is not supported. - Set
usePD=trueinrest-server.propertiesandbackend=hstoreinhugegraph.properties. - Graphspace enables strict authentication by default (default credential:
admin:pa). Change the password immediately to avoid unauthorized access.
2.0.1 Create a graphspace
Method & Url
Request Body
Note: CPU/memory and Kubernetes-related capabilities are not publicly available yet.
| Name | Required | Type | Default | Range/Note | Description |
|---|---|---|---|---|---|
| name | Yes | String | Lowercase letters, digits, underscore; must start with a letter; max length 48 | Graphspace name | |
| description | Yes | String | Description | ||
| cpu_limit | Yes | Int | > 0 | CPU cores for the graphspace | |
| memory_limit | Yes | Int | > 0 (GB) | Memory quota in GB | |
| storage_limit | Yes | Int | > 0 | Maximum disk usage | |
| compute_cpu_limit | No | Int | 0 | >= 0 | Extra HugeGraph-Computer CPU cores; falls back to cpu_limit if unset or 0 |
| compute_memory_limit | No | Int | 0 | >= 0 | Extra HugeGraph-Computer memory in GB; falls back to memory_limit if unset or 0 |
| oltp_namespace | Yes | String | Kubernetes namespace for OLTP HugeGraph-Server | ||
| olap_namespace | Yes | String | Resources are merged when identical to oltp_namespace | Kubernetes namespace for OLAP / HugeGraph-Computer | |
| storage_namespace | Yes | String | Kubernetes namespace for HugeGraph-Store | ||
| operator_image_path | No | String | HugeGraph-Computer operator image registry | ||
| internal_algorithm_image_url | No | String | HugeGraph-Computer algorithm image registry | ||
| max_graph_number | Yes | Int | > 0 | Maximum number of graphs that can be created inside the graphspace | |
| max_role_number | Yes | Int | > 0 | Maximum number of roles that can be created inside the graphspace | |
| auth | No | Boolean | false | true / false | Whether to enable authentication for the graphspace |
| configs | No | Map | Additional configuration |
Response Status
Response Body
2.0.2 List all graphspaces
Method & Url
Response Status
Response Body
2.0.3 Get graphspace details
Params
Path parameters
- graphspace: Graphspace name
Method & Url
Response Status
Response Body
2.0.4 Update a graphspace
authcannot be changed once a graphspace is created.
Params
Path parameter
- graphspace: Graphspace name
Request parameters
- action: Must be
"update" - update: Container for the actual fields to update (see table below)
| Name | Required | Type | Range/Note | Description |
|---|---|---|---|---|
| name | Yes | String | Graphspace name | |
| description | Yes | String | Description | |
| cpu_limit | Yes | Int | > 0 | CPU cores for OLTP HugeGraph-Server |
| memory_limit | Yes | Int | > 0 (GB) | Memory quota (GB) for OLTP HugeGraph-Server |
| storage_limit | Yes | Int | > 0 | Maximum disk usage |
| compute_cpu_limit | No | Int | >= 0 | Extra HugeGraph-Computer CPU cores; falls back to cpu_limit if unset or 0 |
| compute_memory_limit | No | Int | >= 0 | Extra HugeGraph-Computer memory in GB; falls back to memory_limit if unset or 0 |
| oltp_namespace | Yes | String | Kubernetes namespace for OLTP HugeGraph-Server | |
| olap_namespace | Yes | String | Resources are merged when identical to oltp_namespace | Kubernetes namespace for OLAP |
| storage_namespace | Yes | String | Kubernetes namespace for HugeGraph-Store | |
| operator_image_path | No | String | HugeGraph-Computer operator image registry | |
| internal_algorithm_image_url | No | String | HugeGraph-Computer algorithm image registry | |
| max_graph_number | Yes | Int | > 0 | Maximum number of graphs |
| max_role_number | Yes | Int | > 0 | Maximum number of roles |
Method & Url
Request Body
Response Status
Response Body
2.0.5 Delete a graphspace
Params
Path parameter
- graphspace: Graphspace name
Method & Url
Response Status
Warning: deleting a graphspace releases all resources that belong to it.
5.1.2 - Schema API
1.1 Schema
HugeGraph provides a single interface to get all Schema information of a graph, including: PropertyKey, VertexLabel, EdgeLabel and IndexLabel.
Method & Url
Response Status
Response Body
5.1.3 - PropertyKey API
1.2 PropertyKey
Params Description:
- name: The name of the property type, required.
- data_type: The data type of the property type, including: bool, byte, int, long, float, double, text, blob, date, uuid. The default data type is
text(Represent astringtype) - cardinality: The cardinality of the property type, including: single, list, set. The default cardinality is
single.
Request Body Field Description:
- id: The ID value of the property type.
- properties: The properties of the property type. For properties, this field is empty.
- user_data: Setting the common information of the property type, such as setting the value range of the age property from 0 to 100. Currently, no validation is performed on this field, and it is only a reserved entry for future expansion.
1.2.1 Create a PropertyKey
Method & Url
Request Body
Response Status
Response Body
1.2.2 Add or Remove userdata for an existing PropertyKey
Params
- action: Indicates whether the current action is to add or remove userdata. Possible values are
append(add) andeliminate(remove).
Method & Url
Request Body
Response Status
Response Body
1.2.3 Get all PropertyKeys
Method & Url
Response Status
Response Body
1.2.4 Get PropertyKey according to name
Method & Url
Where age is the name of the PropertyKey to be retrieved.
Response Status
Response Body
1.2.5 Delete PropertyKey according to name
Method & Url
Where age is the name of the PropertyKey to be deleted.
Response Status
Response Body
5.1.4 - VertexLabel API
1.3 VertexLabel
Assuming that the PropertyKeys listed in 1.1.3 have already been created.
Params Description:
- id: The ID value of the vertex type.
- name: The name of the vertex type, required.
- id_strategy: The ID strategy for the vertex type, including primary key ID, auto-generated, custom string, custom number, custom UUID. The default strategy is primary key ID.
- properties: The property types associated with the vertex type.
- primary_keys: The primary key properties. This field must have a value when the ID strategy is PRIMARY_KEY, and must be empty for other ID strategies.
- enable_label_index: Whether to enable label indexing. It is disabled by default.
- index_names: The indexes created for the vertex type. See details in section 3.4.
- nullable_keys: Nullable properties.
- user_data: Setting the common information of the vertex type, similar to the property type.
1.3.1 Create a VertexLabel
Method & Url
Request Body
Response Status
Response Body
Starting from version v0.11.2, hugegraph-server supports Time-to-Live (TTL) functionality for vertices. The TTL for vertices is set through VertexLabel. For example, if you want the vertices of type “person” to have a lifespan of one day, you need to set the TTL field to 86400000 (in milliseconds) when creating the “person” VertexLabel.
Additionally, if the vertex has a property called “createdTime” and you want to use it as the starting point for calculating the vertex’s lifespan, you can set the ttl_start_time field in the VertexLabel. For example, if the “person” VertexLabel has a property called “createdTime” of type Date, and you want the vertices of type “person” to live for one day starting from the creation time, the Request Body for creating the “person” VertexLabel would be as follows:
1.3.2 Add properties or userdata to an existing VertexLabel, or remove userdata (removing properties is currently not supported)
Params
- action: Indicates whether the current action is to add or remove. Possible values are
append(add) andeliminate(remove).
Method & Url
Request Body
Response Status
Response Body
1.3.3 Get all VertexLabels
Method & Url
Response Status
Response Body
1.3.4 Get VertexLabel by name
Method & Url
Response Status
Response Body
1.3.5 Delete VertexLabel by name
Deleting a VertexLabel will result in the removal of corresponding vertices and related index data. This operation will generate an asynchronous task.
Method & Url
Response Status
Response Body
Note:
You can use
GET http://localhost:8080/graphspaces/DEFAULT/graphs/hugegraph/tasks/1(where “1” is the task_id) to query the execution status of the asynchronous task. For more information, refer to the Asynchronous Task RESTful API.
5.1.5 - EdgeLabel API
1.4 EdgeLabel
Assuming PropertyKeys from version 1.2.3 and VertexLabels from version 1.3.3 have already been created.
Params Explanation
- name: Name of the vertex type, required.
- source_label: Name of the source vertex type, required.
- target_label: Name of the target vertex type, required.
- frequency: Whether there can be multiple edges between two points, can have values SINGLE or MULTIPLE, optional (default value: SINGLE).
- properties: Property types associated with the edge type, optional.
- sort_keys: Specifies a list of differentiating key properties when multiple associations are allowed.
- nullable_keys: Nullable properties, optional (default: nullable).
- enable_label_index: Whether to enable type indexing, disabled by default.
1.4.1 Create an EdgeLabel
Method & Url
Request Body
Response Status
Response Body
Starting from version 0.11.2 of hugegraph-server, the TTL (Time to Live) feature for edges is supported. The TTL for edges is set through EdgeLabel. For example, if you want the “knows” type of edge to have a lifespan of one day, you need to set the TTL field to 86400000 when creating the “knows” EdgeLabel, where the unit is milliseconds.
Additionally, when the edge has a property called “createdTime” and you want to use the “createdTime” property as the starting point for calculating the edge’s lifespan, you can set the ttl_start_time field in the EdgeLabel. For example, if the knows EdgeLabel has a property called “createdTime” which is of type Date, and you want the “knows” type of edge to live for one day from the time of creation, the Request Body for creating the knows EdgeLabel would be as follows:
1.4.2 Add properties or userdata to an existing EdgeLabel, or remove userdata (removing properties is currently not supported)
Params
- action: Indicates whether the current action is to add or remove, with values
append(add) andeliminate(remove).
Method & Url
Request Body
Response Status
Response Body
1.4.3 Get all EdgeLabels
Method & Url
Response Status
Response Body
1.4.4 Get EdgeLabel by name
Method & Url
Response Status
Response Body
1.4.5 Delete EdgeLabel by name
Deleting an EdgeLabel will result in the deletion of corresponding edges and related index data. This operation will generate an asynchronous task.
Method & Url
Response Status
Response Body
Note:
You can query the execution status of an asynchronous task by using
GET http://localhost:8080/graphspaces/DEFAULT/graphs/hugegraph/tasks/1(where “1” is the task_id). For more information, refer to the Asynchronous Task RESTful API.
5.1.6 - IndexLabel API
1.5 IndexLabel
Assuming PropertyKeys from version 1.1.3, VertexLabels from version 1.2.3, and EdgeLabels from version 1.3.3 have already been created.
1.5.1 Create an IndexLabel
Method & Url
Request Body
Response Status
Response Body
1.5.2 Get all IndexLabels
Method & Url
Response Status
Response Body
1.5.3 Get IndexLabel by name
Method & Url
Response Status
Response Body
1.5.4 Delete IndexLabel by name
Deleting an IndexLabel will result in the deletion of related index data. This operation will generate an asynchronous task.
Method & Url
Response Status
Response Body
Note:
You can query the execution status of an asynchronous task by using
GET http://localhost:8080/graphspaces/DEFAULT/graphs/hugegraph/tasks/1(where “1” is the task_id). For more information, refer to the Asynchronous Task RESTful API.
5.1.7 - Rebuild API
1.6 Rebuild
1.6.1 Rebuild IndexLabel
Method & Url
Response Status
Response Body
Note:
You can get the asynchronous job status by
GET http://localhost:8080/graphspaces/DEFAULT/graphs/hugegraph/tasks/${task_id}(the task_id here should be 1). See More AsyncJob RESTfull API
1.6.2 Rebulid all Indexs of VertexLabel
Method & Url
Response Status
Response Body
Note:
You can get the asynchronous job status by
GET http://localhost:8080/graphspaces/DEFAULT/graphs/hugegraph/tasks/${task_id}(the task_id here should be 2). See More AsyncJob RESTfull API
1.6.3 Rebulid all Indexs of EdgeLabel
Method & Url
Response Status
Response Body
Note:
You can get the asynchronous job status by
GET http://localhost:8080/graphspaces/DEFAULT/graphs/hugegraph/tasks/${task_id}(the task_id here should be 3). See More AsyncJob RESTfull API
5.1.8 - Vertex API
2.1 Vertex
In vertex types, the Id strategy determines the type of the vertex Id, with the corresponding relationships as follows:
| Id_Strategy | id type |
|---|---|
| AUTOMATIC | number |
| PRIMARY_KEY | string |
| CUSTOMIZE_STRING | string |
| CUSTOMIZE_NUMBER | number |
| CUSTOMIZE_UUID | uuid |
For the GET/PUT/DELETE API of a vertex, the id part in the URL should be passed as the id value with type information. This type information is indicated by whether the JSON string is enclosed in quotes, meaning:
- When the id type is
number, the id in the URL is without quotes, for example:xxx/vertices/123456. - When the id type is
string, the id in the URL is enclosed in quotes, for example:xxx/vertices/"123456".
The next example requires first creating the graph schema from the following groovy script
2.1.1 Create a vertex
Method & Url
Request Body
Response Status
Response Body
2.1.2 Create multiple vertices
Method & Url
Request Body
Response Status
Response Body
2.1.3 Update vertex properties
Method & Url
Request Body
Note: There are three categories for property values: single, set, and list. If it is single, it means adding or updating the property value. If it is set or list, it means appending the property value.
Response Status
Response Body
2.1.4 Batch Update Vertex Properties
Function Description
Batch update properties of vertices and support various update strategies, including:
- SUM: Numeric accumulation
- BIGGER: Take the larger value between two numbers/dates
- SMALLER: Take the smaller value between two numbers/dates
- UNION: Take the union of set properties
- INTERSECTION: Take the intersection of set properties
- APPEND: Append elements to list properties
- ELIMINATE: Remove elements from list/set properties
- OVERRIDE: Override existing properties, if the new property is null, the old property is still used
Assuming the original vertex and properties are:
Add vertices with the following command:
Method & Url
Request Body
Response Status
Response Body
Result Analysis:
- The lang property does not specify an update strategy and is directly overwritten by the new value, regardless of whether the new value is null.
- The price property specifies the BIGGER update strategy. The old property value is 328, and the new property value is 299, so the old property value of 328 is retained.
- The age property specifies the OVERRIDE update strategy, but the new property value does not include age, which is equivalent to age being null. Therefore, the original property value of 32 is still retained.
- The city property also specifies the OVERRIDE update strategy, and the new property value is not null, so it overrides the old value.
- The weight property specifies the SUM update strategy. The old property value is 0.1, and the new property value is 0.2. The final value is 0.3.
- The hobby property (cardinality is Set) specifies the UNION update strategy, so the new value is taken as the union with the old value.
The usage of other update strategies can be inferred in a similar manner and will not be further elaborated.
2.1.5 Delete Vertex Properties
Method & Url
Request Body
Note: Here, the properties (keys and all values) will be directly deleted, regardless of whether the property values are single, set, or list.
Response Status
Response Body
2.1.6 Get Vertices that Meet the Criteria
Params
- label: Vertex type
- properties: Property key-value pairs (precondition: indexes are created for property queries)
- limit: Maximum number of results
- page: Page number
All of the above parameters are optional. If the page parameter is provided, the limit parameter must also be provided, and no other parameters are allowed. label, properties, and limit can be combined in any way.
Property key-value pairs consist of the property name and value in JSON format. Multiple property key-value pairs are allowed as query conditions. The property value supports exact matching, range matching, and fuzzy matching. For exact matching, use the format properties={"age":29}, for range matching, use the format properties={"age":"P.gt(29)"}, and for fuzzy matching, use the format properties={"city": "P.textcontains("ChengDu China")}. The following expressions are supported for range matching:
| Expression | Explanation |
|---|---|
| P.eq(number) | Vertices with property value equal to number |
| P.neq(number) | Vertices with property value not equal to number |
| P.lt(number) | Vertices with property value less than number |
| P.lte(number) | Vertices with property value less than or equal to number |
| P.gt(number) | Vertices with property value greater than number |
| P.gte(number) | Vertices with property value greater than or equal to number |
| P.between(number1,number2) | Vertices with property value greater than or equal to number1 and less than number2 |
| P.inside(number1,number2) | Vertices with property value greater than number1 and less than number2 |
| P.outside(number1,number2) | Vertices with property value less than number1 and greater than number2 |
| P.within(value1,value2,value3,…) | Vertices with property value equal to any of the given values |
Query all vertices with age 29 and label person
Method & Url
Response Status
Response Body
Paginate through all vertices, retrieve the first page (page without parameter value), limited to 3 records
Add vertices with the following command:
Method & Url
Response Status
Response Body
The returned body contains information about the page number of the next page, "page": "CIYxOnBldGVyAAAAAAAAAAM". When querying the next page, assign this value to the page parameter.
Paginate and retrieve all vertices, including the next page (passing the page value returned from the previous page), limited to 3 items.
Method & Url
Response Status
Response Body
At this point, "page": null indicates that there are no more pages available. (Note: When using Cassandra as the backend for performance reasons, if the returned page happens to be the last page, the page value may not be empty. When requesting the next page using that page value, it will return empty data and page = null. The same applies to other similar situations.)
2.1.7 Retrieve Vertex by ID
Method & Url
Response Status
Response Body
2.1.8 Delete Vertex by ID
Params
- label: Vertex type, optional parameter
Delete the vertex based on ID only.
Method & Url
Response Status
Delete Vertex by Label+ID
When deleting a vertex by specifying both the Label parameter and the ID, it generally offers better performance compared to deleting by ID alone.
Method & Url
Response Status
5.1.9 - Edge API
2.2 Edge
The modification of the vertex ID format also affects the ID of the edge, as well as the formats of the source vertex and target vertex IDs.
The EdgeId is formed by concatenating src-vertex-id + direction + label + sort-values + tgt-vertex-id, but the vertex ID types are not distinguished by quotation marks here. Instead, they are distinguished by prefixes:
- When the ID type is number, the vertex ID in the EdgeId has a prefix
L, like “L123456>1»L987654”. - When the ID type is string, the vertex ID in the EdgeId has a prefix
S, like “S1:peter>1»S2:lop”.
The following example requires creating a graph schema based on the following groovy script:
2.2.1 Creating an Edge
Params
Path Parameter Description:
- graph: The graph to operate on
Request Body Description:
- label: The edge type name (required)
- outV: The source vertex id (required)
- inV: The target vertex id (required)
- outVLabel: The source vertex type (required)
- inVLabel: The target vertex type (required)
- properties: The properties associated with the edge. The internal structure of the object is as follows:
- name: The property name
- value: The property value
Method & Url
Request Body
Response Status
Response Body
2.2.2 Creating Multiple Edges
Params
Path Parameter Description:
- graph: The graph to operate on
Request Parameter Description:
- check_vertex: Whether to check the existence of vertices (true | false). When set to true, an error will be thrown if the source or target vertices of the edge to be inserted do not exist. Default is true.
Request Body Description:
- List of edge information
Method & Url
Request Body
Response Status
Response Body
2.2.3 Updating Edge Properties
Params
Path Parameter Description:
- graph: The graph to operate on
- id: The ID of the edge to be operated on
Request Parameter Description:
- action: The append action
Request Body Description:
- Edge information
Method & Url
Request Body
NOTE: There are three categories of property values: single, set, and list. If it is single, it means adding or updating the property value. If it is set or list, it means appending the property value.
Response Status
Response Body
2.2.4 Batch Updating Edge Properties
Params
Path Parameter Description:
- graph: The graph to operate on
Request Body Description:
- edges: List of edge information
- update_strategies: For each property, you can set its update strategy individually, including:
- SUM: Only supports number type
- BIGGER/SMALLER: Only supports date/number type
- UNION/INTERSECTION: Only supports set type
- APPEND/ELIMINATE: Only supports collection type
- OVERRIDE
- check_vertex: Whether to check the existence of vertices (true | false). When set to true, an error will be thrown if the source or target vertices of the edge to be inserted do not exist. Default is true.
- create_if_not_exist: Currently only supports setting to true
Method & Url
Request Body
Response Status
Response Body
2.2.5 Deleting Edge Properties
Params
Path Parameter Description:
- graph: The graph to operate on
- id: The ID of the edge to be operated on
Request Parameter Description:
- action: The eliminate action
Request Body Description:
- Edge information
Method & Url
Request Body
NOTE: This will directly delete the properties (removing the key and all values), regardless of whether the property values are single, set, or list.
Response Status
Response Body
It is not possible to delete an attribute that is not set as nullable.
2.2.6 Fetching Edges that Match the Criteria
Params
Path Parameter:
- graph: The graph to operate on
Request Parameters:
- vertex_id: Vertex ID
- direction: Edge direction (OUT | IN | BOTH), default is BOTH
- label: Edge label
- properties: Key-value pairs of properties (requires pre-built indexes for property queries)
- keep_start_p: Default is false. When set to true, the range matching input expression will not be automatically escaped. For example,
properties={"age":"P.gt(0.8)"}will be interpreted as an exact match, i.e., the age property is equal to “P.gt(0.8)” - offset: Offset, default is 0
- limit: Number of queries, default is 100
- page: Page number
Key-value pairs of properties consist of the property name and value in JSON format. Multiple key-value pairs are allowed as query conditions. Property values support exact matching and range matching. For exact matching, it is in the form properties={"weight":0.8}. For range matching, it is in the form properties={"age":"P.gt(0.8)"}. The expressions supported by range matching are as follows:
| Expression | Description |
|---|---|
| P.eq(number) | Edges with property value equal to number |
| P.neq(number) | Edges with property value not equal to number |
| P.lt(number) | Edges with property value less than number |
| P.lte(number) | Edges with property value less than or equal to number |
| P.gt(number) | Edges with property value greater than number |
| P.gte(number) | Edges with property value greater than or equal to number |
| P.between(number1,number2) | Edges with property value greater than or equal to number1 and less than number2 |
| P.inside(number1,number2) | Edges with property value greater than number1 and less than number2 |
| P.outside(number1,number2) | Edges with property value less than number1 and greater than number2 |
| P.within(value1,value2,value3,…) | Edges with property value equal to any of the given values |
| P.textcontains(value) | Edges with property value containing the given value (string type) |
| P.contains(value) | Edges with property value containing the given value (collection type) |
Edges connected to the vertex person:marko(vertex_id=“1:marko”) with label knows and date property equal to “20160111”
Method & Url
Response Status
Response Body
Paginate and retrieve all edges, get the first page (page without parameter value), limit to 2 entries
Method & Url
Response Status
Response Body
The returned body contains the page number information for the next page, "page": "EoYxOm1hcmtvgggCAIQyOmxvcAAAAAAAAAAC". When querying the next page, assign this value to the page parameter.
Paginate and retrieve all edges, get the next page (include the page value returned from the previous page), limit to 2 entries
Method & Url
Response Status
Response Body
When "page": null is returned, it indicates that there are no more pages available.
NOTE: When the backend is Cassandra, for performance considerations, if the returned page happens to be the last page, the
pagevalue may not be empty. When requesting the next page data using thatpagevalue, it will returnempty dataandpage = null. Similar situations apply for other cases.
2.2.7 Fetching Edge by ID
Params
Path parameter description:
- graph: The graph to be operated on.
- id: The ID of the edge to be operated on.
Method & Url
Response Status
Response Body
2.2.8 Deleting Edge by ID
Params
Path parameter description:
- graph: The graph to be operated on.
- id: The ID of the edge to be operated on.
Request parameter description:
- label: The label of the edge.
Deleting Edge by ID only
Method & Url
Response Status
Deleting Edge by Label + ID
In general, specifying the Label parameter along with the ID to delete an edge will provide better performance compared to deleting by ID only.
Method & Url
Response Status
5.1.10 - Traverser API
3.1 Overview of Traverser API
HugeGraphServer provides a RESTful API interface for the HugeGraph graph database. In addition to the basic CRUD operations for vertices and edges, it also offers several traversal methods, which we refer to as the traverser API. These traversal methods implement various complex graph algorithms, making it convenient for users to analyze and explore the graph.
The Traverser API supported by HugeGraph includes:
- K-out API: It finds neighbors that are exactly N steps away from a given starting vertex. There are two versions:
- The basic version uses the GET method to find neighbors that are exactly N steps away from a given starting vertex.
- The advanced version uses the POST method to find neighbors that are exactly N steps away from a given starting vertex. The advanced version differs from the basic version in the following ways:
- Supports counting the number of neighbors only
- Supports filtering by edge and vertex properties
- Supports returning the shortest path to reach the neighbor
- K-neighbor API: It finds all neighbors that are within N steps of a given starting vertex. There are two versions:
- The basic version uses the GET method to find all neighbors that are within N steps of a given starting vertex.
- The advanced version uses the POST method to find all neighbors that are within N steps of a given starting vertex. The advanced version differs from the basic version in the following ways:
- Supports counting the number of neighbors only
- Supports filtering by edge and vertex properties
- Supports returning the shortest path to reach the neighbor
- Same Neighbors: It queries the common neighbors of two vertices.
- Jaccard Similarity API: It calculates the Jaccard similarity, which includes two types:
- One type uses the GET method to calculate the similarity (intersection over union) of neighbors between two vertices.
- The other type uses the POST method to find the top N vertices with the highest Jaccard similarity to a given starting vertex in the entire graph.
- Shortest Path API: It finds the shortest path between two vertices.
- All Shortest Paths: It finds all shortest paths between two vertices.
- Weighted Shortest Path: It finds the shortest weighted path from a starting vertex to a target vertex.
- Single Source Shortest Path: It finds the weighted shortest path from a single source vertex to all other vertices.
- Multi Node Shortest Path: It finds the shortest path between every pair of specified vertices.
- Paths API: It finds all paths between two vertices. There are two versions:
- The basic version uses the GET method to find all paths between a given starting vertex and an ending vertex.
- The advanced version uses the POST method to find all paths that meet certain conditions between a set of starting vertices and a set of ending vertices.
3.2 Detailed Explanation of Traverser API
In the following, we provide a detailed explanation of the Traverser API:
- Customized Paths API: It traverses all paths that pass through a batch of vertices according to a specific pattern.
- Template Path API: It specifies a starting point, an ending point, and the path information between them to find matching paths.
- Crosspoints API: It finds the intersection (common ancestors or common descendants) between two vertices.
- Customized Crosspoints API: It traverses multiple patterns starting from a batch of vertices and finds the intersections with the vertices reached in the final step.
- Rings API: It finds the cyclic paths that can be reached from a starting vertex.
- Rays API: It finds the paths from a starting vertex that reach the boundaries (i.e., paths without cycles).
- Fusiform Similarity API: It finds the fusiform similar vertices to a given vertex.
- Vertices API:
- Batch querying vertices by ID.
- Getting the partitions of vertices.
- Querying vertices by partition.
- Edges API:
- Batch querying edges by ID.
- Getting the partitions of edges.
- Querying edges by partition.
3.2 Detailed Explanation of Traverser API
The usage examples provided in this section are based on the graph presented on the TinkerPop official website:
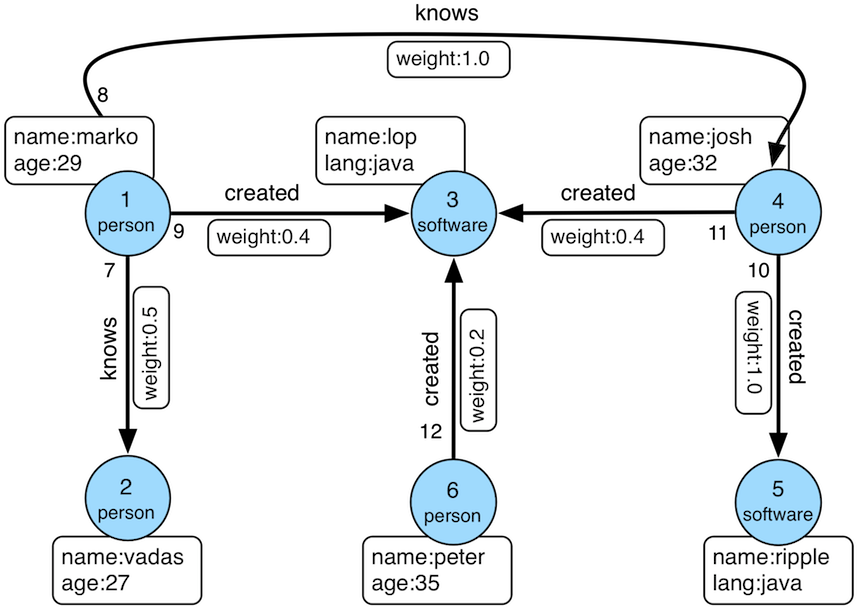
The data import program is as follows:
The vertex IDs are:
The edge IDs are:
3.2.1 K-out API (GET, Basic Version)
3.2.1.1 Functionality Overview
The K-out API allows you to find vertices that are exactly “depth” steps away from a given starting vertex, considering the specified direction, edge type (optional), and depth.
Params
- source: ID of the starting vertex (required)
- direction: Direction of traversal from the starting vertex (OUT, IN, BOTH). Optional, default is BOTH.
- max_depth: Number of steps (required)
- label: Edge type (optional), represents all edge labels by default
- nearest: When nearest is set to true, it means the shortest path length from the starting vertex to the result vertices is equal to the depth, and there is no shorter path. When nearest is set to false, it means there is at least one path of length depth from the starting vertex to the result vertices (not necessarily the shortest and may contain cycles). Optional, default is true.
- max_degree: Maximum number of adjacent edges to traverse per vertex during the query. Optional, default is 10000.
- capacity: Maximum number of vertices to be visited during the traversal. Optional, default is 10000000.
- limit: Maximum number of vertices to be returned. Optional, default is 10000000.
3.2.1.2 Usage Example
Method & Url
Response Status
Response Body
3.2.1.3 Use Cases
Finding vertices that are exactly N steps away in a relationship. Two examples:
- In a family relationship, finding all grandchildren of a person. The set of vertices that can be reached by person A through two consecutive “son” edges.
- Discovering potential friends in a social network. For example, finding users who are two degrees of friendship away from the target user, reachable through two consecutive “friend” edges.
3.2.2 K-out API (POST, Advanced Version)
3.2.2.1 Functionality Overview
The K-out API allows you to find vertices that are exactly “depth” steps away from a given starting vertex, considering the specified steps (including direction, edge type, and attribute filtering).
The advanced version differs from the basic version of K-out API in the following aspects:
- Supports counting the number of neighbors only
- Supports edge attribute filtering
- Supports returning the shortest path to the neighbor
Params
- source: The ID of the starting vertex, required.
- steps: Steps from the starting point, required, with the following structure:
- direction: Represents the direction of the edges (OUT, IN, BOTH), default is BOTH.
- edge_steps: The step set of edges, supporting label and properties filtering for the edge. If edge_steps is empty, the edge is not filtered.
- label: Edge types.
- properties: Filter edges based on property values.
- vertex_steps: The step set of vertices, supporting label and properties filtering for the vertex. If vertex_steps is empty, the vertex is not filtered.
- label: Vertex types.
- properties: Filter vertices based on property values.
- max_degree: Maximum number of adjacent edges to traverse for a single vertex, default is 10000 (Note: Prior to version 0.12, the parameter name was “degree” instead of “max_degree”. Starting from version 0.12, “max_degree” is used uniformly, while still supporting the “degree” syntax for backward compatibility).
- skip_degree: Sets the minimum number of edges to skip super vertices during the query process. If the number of adjacent edges for a vertex is greater than skip_degree, the vertex is completely skipped. Optional. If enabled, it should satisfy the constraint
skip_degree >= max_degree. Default is 0 (not enabled), indicating no skipping of any vertices (Note: Enabling this configuration means that during traversal, an attempt will be made to access skip_degree edges of a vertex, not just max_degree edges. This incurs additional traversal overhead and may have a significant impact on query performance. Please enable it only after understanding the implications).
- max_depth: Number of steps, required.
- nearest: When nearest is true, it means the shortest path length from the starting vertex to the result vertex is equal to depth, and there is no shorter path. When nearest is false, it means there is a path of length depth from the starting vertex to the result vertex (not necessarily the shortest and can contain cycles). Optional, default is true.
- count_only: Boolean value, true indicates only counting the number of results without returning specific results, false indicates returning specific results. Default is false.
- with_path: When true, it returns the shortest path from the starting vertex to each neighbor. When false, it does not return the shortest path. Optional, default is false.
- with_edge: Optional parameter, default is false:
- When true, the result will include complete edge information (all edges in the path):
- When with_path is true, it returns complete information of all edges in all paths.
- When with_path is false, no information is returned.
- When false, it only returns edge IDs.
- When true, the result will include complete edge information (all edges in the path):
- with_vertex: Optional parameter, default is false:
- When true, the result will include complete vertex information (all vertices in the path):
- When with_path is true, it returns complete information of all vertices in all paths.
- When with_path is false, it returns complete information of all neighbors.
- When false, it only returns vertex IDs.
- When true, the result will include complete vertex information (all vertices in the path):
- capacity: Maximum number of vertices to visit during traversal. Optional, default is 10000000.
- limit: Maximum number of vertices to return. Optional, default is 10000000.
- traverse_mode: Traversal mode. There are two options: “breadth_first_search” and “depth_first_search”, default is “breadth_first_search”.
3.2.2.2 Usage
Method & Url
Request Body
Response Status
Response Body
3.2.2.3 Use Cases
Refer to 3.2.1.3.
3.2.3 K-neighbor (GET, Basic Version)
3.2.3.1 Function Introduction
Find all vertices that are reachable within depth steps, including the starting vertex, based on the starting vertex, direction, edge type (optional), and depth.
Equivalent to the union of: starting vertex, K-out(1), K-out(2), …, K-out(max_depth).
Params
- source: ID of the starting vertex, required.
- direction: Direction in which the starting vertex’s edges extend (OUT, IN, BOTH). Optional, default is BOTH.
- max_depth: Number of steps, required.
- label: Edge type, optional, default represents all edge labels.
- max_degree: Maximum number of adjacent edges to traverse for a single vertex during the query process. Optional, default is 10000.
- limit: Maximum number of vertices to return, also represents the maximum number of vertices to visit during traversal. Optional, default is 10000000.
3.2.3.2 Usage
Method & Url
Response Status
Response Body
3.2.3.3 Use Cases
Find all vertices reachable within N steps, for example:
- In a family relationship, find all descendants within five generations of a person. This can be achieved by traversing five consecutive “parent-child” edges from person A.
- In a social network, discover friend circles. For example, users who can be reached by 1, 2, or 3 “friend” edges from the target user can form the target user’s friend circle.
3.2.4 K-neighbor API (POST, Advanced Version)
3.2.4.1 Function Introduction
Find all vertices that are reachable within depth steps from the starting vertex, based on the starting vertex, steps (including direction, edge type, and filter properties), and depth.
The difference from the Basic Version of K-neighbor API is that:
- It supports counting the number of neighbors only.
- It supports filtering edges based on their properties.
- It supports returning the shortest path to reach the neighbors.
Params
- source: Starting vertex ID, required.
- steps: Steps from the starting point, required, with the following structure:
- direction: Represents the direction of the edges (OUT, IN, BOTH), default is BOTH.
- edge_steps: The step set of edges, supporting label and properties filtering for the edge. If edge_steps is empty, the edge is not filtered.
- label: Edge types.
- properties: Filter edges based on property values.
- vertex_steps: The step set of vertices, supporting label and properties filtering for the vertex. If vertex_steps is empty, the vertex is not filtered.
- label: Vertex types.
- properties: Filter vertices based on property values.
- max_degree: Maximum number of adjacent edges to traverse for each vertex during the query process. Default is 10000. (Note: Before version 0.12, the parameter name within the step only supported “degree.” Starting from version 0.12, it is unified as “max_degree” and is backward compatible with the “degree” notation.)
- skip_degree: Used to set the minimum number of edges to discard super vertices during the query process. When the number of adjacent edges for a vertex exceeds skip_degree, the vertex is completely discarded. This is an optional parameter. If enabled, it should satisfy the constraint
skip_degree >= max_degree. Default is 0 (not enabled), which means no vertices are skipped. (Note: When this configuration is enabled, the traversal will attempt to access skip_degree edges for each vertex, not just max_degree edges. This incurs additional traversal overhead and may significantly impact query performance. Please make sure to understand this before enabling.)
- max_depth: Number of steps, required.
- count_only: Boolean value. If true, only the count of results is returned without the actual results. If false, the specific results are returned. Default is false.
- with_path: If true, the shortest path from the starting point to each neighbor is returned. If false, the shortest path from the starting point to each neighbor is not returned. This is an optional parameter. Default is false.
- with_edge: Optional parameter, default is false:
- When true, the result will include complete edge information (all edges in the path):
- When with_path is true, it returns complete information of all edges in all paths.
- When with_path is false, no information is returned.
- When false, it only returns edge IDs.
- When true, the result will include complete edge information (all edges in the path):
- with_vertex: Optional parameter, default is false:
- When true, the result will include complete vertex information (all vertices in the path):
- When with_path is true, it returns complete information of all vertices in all paths.
- When with_path is false, it returns complete information of all neighbors.
- When false, it only returns vertex IDs.
- When true, the result will include complete vertex information (all vertices in the path):
- limit: Maximum number of vertices to be returned. Also, the maximum number of vertices visited during the traversal process. This is an optional parameter. Default is 10000000.
3.2.4.2 Usage Method
Method & Url
Request Body
Response Status
Response Body
3.2.4.3 Use Cases
See 3.2.3.3
3.2.5 Same Neighbors
3.2.5.1 Function Introduction
Retrieve the common neighbors of two vertices.
Params
- vertex: ID of one vertex, required.
- other: ID of another vertex, required.
- direction: Direction in which the vertex expands outward (OUT, IN, BOTH). Optional, default is BOTH.
- label: Edge type. Optional, default represents all edge labels.
- max_degree: Maximum number of adjacent edges to traverse for each vertex during the query process. Optional, default is 10000.
- limit: Maximum number of common neighbors to be returned. Optional, default is 10000000.
3.2.5.2 Usage Method
Method & Url
Response Status
Response Body
3.2.5.3 Use Cases
Find the common neighbors of two vertices:
- In a social network, find the common followers or users both users are following.
3.2.6 Jaccard Similarity (GET)
3.2.6.1 Function Introduction
Compute the Jaccard similarity between two vertices (the intersection of the neighbors of the two vertices divided by the union of the neighbors of the two vertices).
Params
- vertex: ID of one vertex, required.
- other: ID of another vertex, required.
- direction: Direction in which the vertex expands outward (OUT, IN, BOTH). Optional, default is BOTH.
- label: Edge type. Optional, default represents all edge labels.
- max_degree: Maximum number of adjacent edges to traverse for each vertex during the query process. Optional, default is 10000.
3.2.6.2 Usage Method
Method & Url
Response Status
Response Body
3.2.6.3 Use Cases
Used to evaluate the similarity or closeness between two vertices.
3.2.7 Jaccard Similarity (POST)
3.2.7.1 Function Introduction
Compute the N vertices with the highest Jaccard similarity to a specified vertex.
The Jaccard similarity is calculated as the intersection of the neighbors of the two vertices divided by the union of the neighbors of the two vertices.
Params
- vertex: ID of a vertex, required.
- Steps from the starting point, required. The structure is as follows:
- direction: Direction of the edges (OUT, IN, BOTH). Optional, default is BOTH.
- labels: List of edge types.
- properties: Filter edges based on property values.
- max_degree: Maximum number of adjacent edges to traverse for each vertex during the query process. Default is 10000. (Note: Prior to version 0.12, the parameter name inside “step” was “degree”. Starting from version 0.12, it is unified as “max_degree” and still compatible with “degree” notation.)
- skip_degree: Used to set the minimum number of edges to skip super vertices during the query process. If the number of adjacent edges for a vertex is greater than skip_degree, the vertex is completely skipped. Optional, default is 0 (not enabled), which means no skipping. (Note: When this configuration is enabled, the traversal will attempt to access skip_degree edges of a vertex, not just max_degree edges. This incurs additional traversal overhead and may have a significant impact on query performance. Please enable it after understanding and confirming.)
- top: Return the top N vertices with the highest Jaccard similarity for a starting vertex. Optional, default is 100.
- capacity: Maximum number of vertices to be visited during the traversal process. Optional, default is 10000000.
3.2.7.2 Usage Method
Method & Url
Request Body
Response Status
Response Body
3.2.7.3 Use Cases
Used to find the vertices in the graph that have the highest similarity to a specified vertex.
3.2.8 Shortest Path
3.2.8.1 Function Introduction
Find the shortest path between a starting vertex and a target vertex based on the direction, edge type (optional), and maximum depth.
Params
- source: ID of the starting vertex, required.
- target: ID of the target vertex, required.
- direction: Direction in which the starting vertex expands (OUT, IN, BOTH). Optional, default is BOTH.
- max_depth: Maximum number of steps, required.
- label: Edge type, optional. Default represents all edge labels.
- max_degree: Maximum number of adjacent edges to traverse for each vertex during the query process. Optional, default is 10000.
- skip_degree: Used to set the minimum number of edges to skip super vertices during the query process. If the number of adjacent edges for a vertex is greater than skip_degree, the vertex is completely skipped. Optional, default is 0 (not enabled), which means no skipping. (Note: When this configuration is enabled, the traversal will attempt to access skip_degree edges of a vertex, not just max_degree edges. This incurs additional traversal overhead and may have a significant impact on query performance. Please enable it after understanding and confirming.)
- capacity: Maximum number of vertices to be visited during the traversal process. Optional, default is 10000000.
3.2.8.2 Usage Method
Method & Url
Response Status
Response Body
3.2.8.3 Use Cases
Used to find the shortest path between two vertices, for example:
- In a social network, finding the shortest path between two users, representing the closest friend relationship chain.
- In a device association network, finding the shortest association relationship between two devices.
3.2.9 All Shortest Paths
3.2.9.1 Function Introduction
Find all shortest paths between a starting vertex and a target vertex based on the direction, edge type (optional), and maximum depth.
Params
- source: ID of the starting vertex, required.
- target: ID of the target vertex, required.
- direction: Direction in which the starting vertex expands (OUT, IN, BOTH). Optional, default is BOTH.
- max_depth: Maximum number of steps, required.
- label: Edge type, optional. Default represents all edge labels.
- max_degree: Maximum number of adjacent edges to traverse for each vertex during the query process. Optional, default is 10000.
- skip_degree: Used to set the minimum number of edges to skip super vertices during the query process. If the number of adjacent edges for a vertex is greater than skip_degree, the vertex is completely skipped. Optional, default is 0 (not enabled), which means no skipping. (Note: When this configuration is enabled, the traversal will attempt to access skip_degree edges of a vertex, not just max_degree edges. This incurs additional traversal overhead and may have a significant impact on query performance. Please enable it after understanding and confirming.)
- capacity: Maximum number of vertices to be visited during the traversal process. Optional, default is 10000000.
3.2.9.2 Usage Method
Method & Url
Response Status
Response Body
3.2.9.3 Use Cases
Used to find all shortest paths between two vertices, for example:
- In a social network, finding all shortest paths between two users, representing all the closest friend relationship chains.
- In a device association network, finding all shortest association relationships between two devices.
3.2.10 Weighted Shortest Path
3.2.10.1 Function Introduction
Find a weighted shortest path between a starting vertex and a target vertex based on the direction, edge type (optional), maximum depth, and edge weight property.
Params
- source: ID of the starting vertex, required.
- target: ID of the target vertex, required.
- direction: Direction in which the starting vertex expands (OUT, IN, BOTH). Optional, default is BOTH.
- label: Edge type, optional. Default represents all edge labels.
- weight: Edge weight property, required. It must be a numeric property.
- max_degree: Maximum number of adjacent edges to traverse for each vertex during the query process. Optional, default is 10000.
- skip_degree: Used to set the minimum number of edges to skip super vertices during the query process. If the number of adjacent edges for a vertex is greater than skip_degree, the vertex is completely skipped. Optional, default is 0 (not enabled), which means no skipping. (Note: When this configuration is enabled, the traversal will attempt to access skip_degree edges of a vertex, not just max_degree edges. This incurs additional traversal overhead and may have a significant impact on query performance. Please enable it after understanding and confirming.)
- capacity: Maximum number of vertices to be visited during the traversal process. Optional, default is 10000000.
- with_vertex: true to include complete vertex information (all vertices in the path) in the result, false to only return vertex IDs. Optional, default is false.
3.2.10.2 Usage Method
Method & Url
Response Status
Response Body
3.2.10.3 Use Cases
Used to find the weighted shortest path between two vertices, for example:
- In a transportation network, finding the transportation method that requires the least cost from city A to city B.
3.2.11 Single Source Shortest Path
3.2.11.1 Function Introduction
Starting from a vertex, find the shortest paths from that vertex to other vertices in the graph (optional with weight).
Params
- source: ID of the starting vertex, required.
- direction: Direction in which the starting vertex expands (OUT, IN, BOTH). Optional, default is BOTH.
- label: Edge type, optional. Default represents all edge labels.
- weight: Edge weight property, optional. It must be a numeric property. If not provided or the edges don’t have this property, the weight is considered as 1.0.
- max_degree: Maximum number of adjacent edges to traverse for each vertex during the query process. Optional, default is 10000.
- skip_degree: Used to set the minimum number of edges to skip super vertices during the query process. If the number of adjacent edges for a vertex is greater than skip_degree, the vertex is completely skipped. Optional, default is 0 (not enabled), which means no skipping. (Note: When this configuration is enabled, the traversal will attempt to access skip_degree edges of a vertex, not just max_degree edges. This incurs additional traversal overhead and may have a significant impact on query performance. Please enable it after understanding and confirming.)
- capacity: Maximum number of vertices to be visited during the traversal process. Optional, default is 10000000.
- limit: Number of target vertices to be queried and the number of shortest paths to be returned. Optional, default is 10.
- with_vertex: true to include complete vertex information (all vertices in the path) in the result, false to only return vertex IDs. Optional, default is false.
3.2.11.2 Usage Method
Method & Url
Response Status
Response Body
3.2.11.3 Use Cases
Used to find the weighted shortest path from one vertex to other vertices, for example:
- Finding the shortest travel time by bus from Beijing to all other cities in the country.
3.2.12 Multi Node Shortest Path
3.2.12.1 Function Introduction
Finds the shortest paths between pairs of specified vertices.
Params
- vertices: Defines the starting vertices, required. It can be specified in the following ways:
- ids: Provide a list of vertex IDs as starting vertices.
- label and properties: If no IDs are specified, use the combined conditions of label and properties to query the starting vertices.
- label: Vertex type.
- properties: Query the starting vertices based on property values.
Note: Property values in properties can be a list, indicating that the value of the key can be any value in the list.
- step: Represents the path from the starting vertices to the destination vertices, required. The structure of the step is as follows:
- direction: Represents the direction of the edges (OUT, IN, BOTH). Default is BOTH.
- labels: List of edge types.
- properties: Filters the edges based on property values.
- max_degree: Maximum number of adjacent edges to traverse for each vertex during the query process. Default is 10000. (Note: Before version 0.12, the step only supported “degree” as the parameter name. Starting from version 0.12, “max_degree” is used uniformly, and “degree” is still supported for backward compatibility.)
- skip_degree: Used to set the minimum number of edges to skip super vertices during the query process. If the number of adjacent edges for a vertex is greater than skip_degree, the vertex is completely skipped. Optional, default is 0 (not enabled), which means no skipping. (Note: When this configuration is enabled, the traversal will attempt to access skip_degree edges of a vertex, not just max_degree edges. This incurs additional traversal overhead and may have a significant impact on query performance. Please enable it after understanding and confirming.)
- max_depth: Number of steps, required.
- capacity: Maximum number of vertices to be visited during the traversal process. Optional, default is 10000000.
- with_vertex: true to include complete vertex information (all vertices in the path) in the result, false to only return vertex IDs. Optional, default is false.
3.2.12.2 Usage Method
Method & Url
Request Body
Response Status
Response Body
3.2.12.3 Use Cases
Used to find the shortest paths between multiple vertices, for example:
- Finding the shortest paths between multiple companies and their legal representatives.
3.2.13 Paths (GET, Basic Version)
3.2.13.1 Function Introduction
Finds all paths based on conditions such as the starting vertex, destination vertex, direction, edge types (optional), and maximum depth.
Params
- source: ID of the starting vertex, required.
- target: ID of the destination vertex, required.
- direction: Direction in which the starting vertex expands (OUT, IN, BOTH). Optional, default is BOTH.
- label: Edge type. Optional, default represents all edge labels.
- max_depth: Number of steps, required.
- max_degree: Maximum number of adjacent edges to traverse for each vertex during the query process. Optional, default is 10000.
- capacity: Maximum number of vertices to be visited during the traversal process. Optional, default is 10000000.
- limit: Maximum number of paths to be returned. Optional, default is 10.
3.2.13.2 Usage Method
Method & Url
Response Status
Response Body
3.2.13.3 Use Cases
Used to find all paths between two vertices, for example:
- In a social network, finding all possible relationship paths between two users.
- In a device association network, finding all associated paths between two devices.
3.2.14 Paths (POST, Advanced Version)
3.2.14.1 Function Introduction
Finds all paths based on conditions such as the starting vertex, destination vertex, steps (step), and maximum depth.
Params
- sources: Defines the starting vertices, required. The specification methods include:
- ids: Provide the starting vertices through a list of vertex IDs.
- label and properties: If no IDs are specified, use the label and properties as combined conditions to query the starting vertices.
- label: Vertex type.
- properties: Query the starting vertices based on the values of their properties.
Note: The property values in properties can be a list, indicating that any value corresponding to the key is acceptable.
- targets: Defines the destination vertices, required. The specification methods include:
- ids: Provide the destination vertices through a list of vertex IDs.
- label and properties: If no IDs are specified, use the label and properties as combined conditions to query the destination vertices.
- label: Vertex type.
- properties: Query the destination vertices based on the values of their properties.
Note: The property values in properties can be a list, indicating that any value corresponding to the key is acceptable.
- step: Represents the path from the starting vertex to the destination vertex, required. The structure of Step is as follows:
- direction: Represents the direction of edges (OUT, IN, BOTH). The default is BOTH.
- labels: List of edge types.
- properties: Filters edges based on property values.
- max_degree: Maximum number of adjacent edges to traverse for each vertex during the query process. Default is 10000. (Note: Prior to version 0.12, step only supported degree as a parameter name. Starting from version 0.12, max_degree is used uniformly and degree writing is backward compatible.)
- skip_degree: Used to set the minimum number of edges to be discarded for super vertices during the query process. When the number of adjacent edges for a vertex is greater than skip_degree, the vertex is completely discarded. Optional, if enabled, it must satisfy the constraint
skip_degree >= max_degree. Default is 0 (not enabled), which means no points are skipped. (Note: When this configuration is enabled, the traversal will attempt to visit skip_degree edges of a vertex, not just max_degree edges. This incurs additional traversal overhead and may have a significant impact on query performance. Please make sure to understand before enabling it.)
- max_depth: Number of steps, required.
- nearest: When nearest is true, it means the shortest path length from the starting vertex to the result vertex is depth, and there is no shorter path. When nearest is false, it means there is a path of length depth from the starting vertex to the result vertex (not necessarily the shortest path and can have cycles). Optional, default is true.
- capacity: Maximum number of vertices to be visited during the traversal process. Optional, default is 10000000.
- limit: Maximum number of paths to be returned. Optional, default is 10.
- with_vertex: When true, the results include complete vertex information (all vertices in the path). When false, only the vertex IDs are returned. Optional, default is false.
3.2.14.2 Usage Method
Method & Url
Request Body
Response Status
Response Body
3.2.14.3 Use Cases
Used to find all paths between two vertices, for example:
- In a social network, finding all possible relationship paths between two users.
- In a device association network, finding all associated paths between two devices.
3.2.15 Customized Paths
3.2.15.1 Function Introduction
Finds all paths that meet the specified conditions based on a batch of starting vertices, edge rules (including direction, edge types, and property filters), and maximum depth.
Params
- sources: Defines the starting vertices, required. The specification methods include:
- ids: Provide the starting vertices through a list of vertex IDs.
- label and properties: If no IDs are specified, use the label and properties as combined conditions to query the starting vertices.
- label: Vertex type.
- properties: Query the starting vertices based on the values of their properties.
Note: The property values in properties can be a list, indicating that any value corresponding to the key is acceptable.
- steps: Represents the path rules traversed from the starting vertices and is a list of Steps. Required. The structure of each Step is as follows:
- direction: Represents the direction of edges (OUT, IN, BOTH). The default is BOTH.
- labels: List of edge types.
- properties: Filters edges based on property values.
- weight_by: Calculates the weight of edges based on the specified property. It is effective when sort_by is not NONE and is mutually exclusive with default_weight.
- default_weight: The default weight to be used when there is no property to calculate the weight of edges. It is effective when sort_by is not NONE and is mutually exclusive with weight_by.
- max_degree: Maximum number of adjacent edges to traverse for each vertex during the query process. Default is 10000. (Note: Prior to version 0.12, step only supported degree as a parameter name. Starting from version 0.12, max_degree is used uniformly and degree writing is backward compatible.)
- sample: Used when sampling is needed for the edges that meet the conditions of a specific step. -1 means no sampling, and the default is to sample 100 edges.
- sort_by: Sorts the paths based on their weights. Optional, default is NONE:
- NONE: No sorting, default value.
- INCR: Sorts in ascending order based on path weights.
- DECR: Sorts in descending order based on path weights.
- capacity: Maximum number of vertices to be visited during the traversal process. Optional, default is 10000000.
- limit: Maximum number of paths to be returned. Optional, default is 10.
- with_vertex: When true, the results include complete vertex information (all vertices in the path). When false, only the vertex IDs are returned. Optional, default is false.
3.2.15.2 Usage Method
Method & Url
Request Body
Response Status
Response Body
3.2.15.3 Use Cases
Suitable for finding various complex sets of paths, for example:
- In a social network, finding the paths from users who have watched movies directed by Zhang Yimou to the influencers they follow (Zhang Yimou —> Movie —> User —> Influencer).
- In a risk control network, finding the paths from multiple high-risk users to the friends of their direct relatives (High-risk user —> Direct relative —> Friend).
3.2.16 Template Paths
3.2.16.1 Function Introduction
Finds all paths that meet the specified conditions based on a batch of starting vertices, edge rules (including direction, edge types, and property filters), and maximum depth.
Params
- sources: Defines the starting vertices, required. The specification methods include:
- ids: Provide the starting vertices through a list of vertex IDs.
- label and properties: If no IDs are specified, use the label and properties as combined conditions to query the starting vertices.
- label: Vertex type.
- properties: Query the starting vertices based on the values of their properties.
Note: The property values in properties can be a list, indicating that any value corresponding to the key is acceptable.
- targets: Defines the ending vertices, required. The specification methods include:
- ids: Provide the ending vertices through a list of vertex IDs.
- label and properties: If no IDs are specified, use the label and properties as combined conditions to query the ending vertices.
- label: Vertex type.
- properties: Query the ending vertices based on the values of their properties.
Note: The property values in properties can be a list, indicating that any value corresponding to the key is acceptable.
- steps: Represents the path rules traversed from the starting vertices and is a list of Steps. Required. The structure of each Step is as follows:
- direction: Represents the direction of edges (OUT, IN, BOTH). The default is BOTH.
- labels: List of edge types.
- properties: Filters edges based on property values.
- max_times: The number of times the current step can be repeated. When set to N, it means the starting vertices can pass through the current step 1-N times.
- max_degree: Maximum number of adjacent edges to traverse for each vertex during the query process. Default is 10000. (Note: Prior to version 0.12, step only supported degree as a parameter name. Starting from version 0.12, max_degree is used uniformly and degree writing is backward compatible.)
- skip_degree: Used to set the minimum number of edges to discard super vertices during the query process. When the number of adjacent edges of a vertex is greater than skip_degree, the vertex is completely discarded. Optional. If enabled, it must satisfy the
skip_degree >= max_degreeconstraint. Default is 0 (not enabled), which means no points are skipped. (Note: After enabling this configuration, traversing will attempt to access a vertex’s skip_degree edges, not just max_degree edges. This incurs additional traversal overhead and may have a significant impact on query performance. Please ensure understanding before enabling.)
- with_ring: Boolean value, true to include cycles; false to exclude cycles. Default is false.
- capacity: Maximum number of vertices to be visited during the traversal process. Optional, default is 10000000.
- limit: Maximum number of paths to be returned. Optional, default is 10.
- with_vertex: When true, the results include complete vertex information (all vertices in the path). When false, only the vertex IDs are returned. Optional, default is
false.
3.2.16.2 Usage Method
Method & Url
Request Body
Response Status
Response Body
3.2.16.3 Use Cases
Suitable for finding various complex template paths, such as personA -(Friend)-> personB -(Classmate)-> personC, where the “Friend” and “Classmate” edges can have a maximum depth of 3 and 4 layers, respectively.
3.2.17 Crosspoints
3.2.17.1 Function Introduction
Finds the intersection points based on the specified conditions, including starting vertices, destination vertices, direction, edge types (optional), and maximum depth.
Params
- source: ID of the starting vertex, required.
- target: ID of the destination vertex, required.
- direction: The direction from the starting vertex to the destination vertex. The reverse direction is used from the destination vertex to the starting vertex. When set to BOTH, the direction is not considered (OUT, IN, BOTH). Optional, default is BOTH.
- label: Edge type, optional. Default represents all edge labels.
- max_depth: Number of steps, required.
- max_degree: Maximum number of adjacent edges to traverse for each vertex during the query process. Optional, default is 10000.
- capacity: Maximum number of vertices to be visited during the traversal process. Optional, default is 10000000.
- limit: Maximum number of intersection points to be returned. Optional, default is 10.
3.2.17.2 Usage Method
Method & Url
Response Status
Response Body
3.2.17.3 Use Cases
Used to find the intersection points and their paths between two vertices, such as:
- In a social network, finding the topics or influencers that two users have in common.
- In a family relationship, finding common ancestors.
3.2.18 Customized Crosspoints
3.2.18.1 Function Introduction
Finds the intersection of destination vertices that satisfy the specified conditions, including starting vertices, multiple edge rules (including direction, edge type, and property filters), and maximum depth.
Params
sources: Defines the starting vertices, required. The specified options include:
- ids: Provides a list of vertex IDs as starting vertices.
- label and properties: If no IDs are specified, uses the combined conditions of label and properties to query the starting vertices.
- label: Type of the vertex.
- properties: Queries the starting vertices based on property values.
Note: Property values in properties can be a list, indicating that the value of the key can be any item in the list.
path_patterns: Represents the path rules to be followed from the starting vertices. It is a list of rules. Required. Each rule is a PathPattern.
- Each PathPattern consists of a list of steps, where each step has the following structure:
- direction: Indicates the direction of the edge (OUT, IN, BOTH). Default is BOTH.
- labels: List of edge types.
- properties: Filters the edges based on property values.
- max_degree: Maximum number of adjacent edges to traverse for each vertex during the query process. Default is 10000.
- skip_degree: Sets the minimum number of edges to discard super vertices during the query process. If the number of adjacent edges for a vertex is greater than skip_degree, the vertex is completely discarded. Optional. If enabled, it must satisfy the constraint
skip_degree >= max_degree. Default is 0 (not enabled), which means no vertices are skipped. Note: When this configuration is enabled, the traversal process will attempt to visit skip_degree edges of a vertex, not just max_degree edges. This incurs additional traversal overhead and may significantly impact query performance. Please make sure you understand it before enabling.
- Each PathPattern consists of a list of steps, where each step has the following structure:
capacity: Maximum number of vertices to be visited during the traversal process. Optional. Default is 10000000.
limit: Maximum number of paths to be returned. Optional. Default is 10.
with_path: When set to true, returns the paths where the intersection points are located. When set to false, does not return the paths. Optional. Default is false.
with_vertex: Optional. Default is false.
- When set to true, the result includes complete vertex information (all vertices in the paths):
- When with_path is true, it returns complete information of all vertices in the paths.
- When with_path is false, it returns complete information of all intersection points.
- When set to false, only the vertex IDs are returned.
- When set to true, the result includes complete vertex information (all vertices in the paths):
3.2.18.2 Usage Method
Method & Url
Request Body
Response Status
Response Body
3.2.18.3 Use Cases
Used to query a group of vertices that have intersections at the destination through multiple paths. For example:
- In a product knowledge graph, multiple models of smartphones, learning devices, and gaming devices belong to the top-level category of electronic devices through different lower-level category paths.
3.2.19 Rings
3.2.19.1 Function Introduction
Finds reachable cycles based on the specified conditions, including starting vertices, direction, edge types (optional), and maximum depth.
For example: 1 -> 25 -> 775 -> 14690 -> 25, where the cycle is 25 -> 775 -> 14690 -> 25.
Params
- source: Starting vertex ID, required.
- direction: Direction of edges emitted from the starting vertex (OUT, IN, BOTH). Optional. Default is BOTH.
- label: Edge type. Optional. Default represents all edge labels.
- max_depth: Number of steps. Required.
- source_in_ring: Whether the starting point is included in the cycle. Optional. Default is true.
- max_degree: Maximum number of adjacent edges to traverse for each vertex during the query process. Optional. Default is 10000.
- capacity: Maximum number of vertices to be visited during the traversal process. Optional. Default is 10000000.
- limit: Maximum number of reachable cycles to be returned. Optional. Default is 10.
3.2.19.2 Usage Method
Method & Url
Response Status
Response Body
3.2.19.3 Use Cases
Used to query cycles reachable from the starting vertex, for example:
- In a risk control project, querying individuals or devices involved in a circular guarantee that a user is connected to.
- In a device network, discovering devices that have circular references around a specific device.
3.2.20 Rays
3.2.20.1 Function Introduction
Finds paths that diverge from the starting vertex and reach boundary vertices based on the specified conditions, including starting vertices, direction, edge types (optional), and maximum depth.
For example: 1 -> 25 -> 775 -> 14690 -> 2289 -> 18379, where 18379 is the boundary vertex, meaning there are no edges emitted from 18379.
Params
- source: Starting vertex ID, required.
- direction: Direction of edges emitted from the starting vertex (OUT, IN, BOTH). Optional. Default is BOTH.
- label: Edge type. Optional. Default represents all edge labels.
- max_depth: Number of steps. Required.
- max_degree: Maximum number of adjacent edges to traverse for each vertex during the query process. Optional. Default is 10000.
- capacity: Maximum number of vertices to be visited during the traversal process. Optional. Default is 10000000.
- limit: Maximum number of non-cycle paths to be returned. Optional. Default is 10.
3.2.20.2 Usage Method
Method & Url
Response Status
Response Body
3.2.20.3 Use Cases
Used to find paths from the starting vertex to boundary vertices based on a specific relationship, for example:
- In a family relationship, finding paths from a person to all descendants who do not have children.
- In a device network, discovering paths from a specific device to terminal devices.
3.2.21 Fusiform Similarity
3.2.21.1 Function Introduction
Queries a batch of “fusiform similar vertices” based on specified conditions. When two vertices share a certain relationship with many common vertices, they are considered “fusiform similar vertices.” For example, if “Reader A” has read 100 books, readers who have read 80 or more of these 100 books can be defined as “fusiform similar vertices” of “Reader A.”
Params
sources: Starting vertices, required. Specify using:
- ids: Provide a list of vertex IDs as starting vertices.
- label and properties: If ids are not specified, use the combined conditions of label and properties to query the starting vertices.
- label: Vertex type.
- properties: Query the starting vertices based on the values of their properties.
Note: Property values in properties can be a list, indicating that the value of the key can be any value in the list.
label: Edge type. Optional. Default represents all edge labels.
direction: Direction in which the starting vertex diverges (OUT, IN, BOTH). Optional. Default is BOTH.
min_neighbors: Minimum number of neighbors. If the number of neighbors is less than this threshold, the starting vertex is not considered a “fusiform similar vertex.” For example, if you want to find “fusiform similar vertices” of books read by “Reader A,” and min_neighbors is set to 100, it means that “Reader A” must have read at least 100 books to have “fusiform similar vertices.” Required.
alpha: Similarity, representing the proportion of common neighbors between the starting vertex and “fusiform similar vertices” to all neighbors of the starting vertex. Required.
min_similars: Minimum number of “fusiform similar vertices.” Only when the number of “fusiform similar vertices” of the starting vertex is greater than or equal to this value, the starting vertex and its “fusiform similar vertices” will be returned. Optional. Default is 1.
top: Returns the top highest similarity “fusiform similar vertices” of a starting vertex. Required. 0 means all.
group_property: Used together with min_groups. Returns the starting vertex and its “fusiform similar vertices” only if there are at least min_groups different values for a certain attribute of the starting vertex and its “fusiform similar vertices.” For example, when recommending “out-of-town” book buddies for “Reader A,” set group_property to the “city” attribute of readers and min_group to at least 2. Optional. If not specified, no filtering based on attributes is needed.
min_groups: Used together with group_property. Only meaningful when group_property is set.
max_degree: Maximum number of adjacent edges to traverse for each vertex during the query process. Optional. Default is 10000.
capacity: Maximum number of vertices to be visited during the traversal process. Optional. Default is 10000000.
limit: Maximum number of results to be returned (one starting vertex and its “fusiform similar vertices” count as one result). Optional. Default is 10.
with_intermediary: Whether to return the starting vertex and the intermediate vertices that are commonly related to the “fusiform
similar vertices.” Default is false.
- with_vertex: Optional. Default is false.
- true: Returns complete vertex information in the results.
- false: Only returns vertex IDs.
3.2.21.2 Usage Method
Method & Url
Request Body
Response Status
Response Body
3.2.21.3 Use Cases
Used to query vertices that have high similarity with a group of vertices. For example:
- Readers with similar book lists to a specific reader.
- Players who play similar games to a specific player.
3.2.22 Vertices
3.2.22.1 Batch Query Vertices by Vertex IDs
Params
- ids: List of vertex IDs to be queried.
Method & Url
Response Status
Response Body
3.2.22.2 Get Vertex Shard Information
Obtain vertex shard information by specifying the shard size split_size (can be used in conjunction with Scan in 3.2.21.3 to retrieve vertices).
Params
- split_size: Shard size, required.
Method & Url
Response Status
Response Body
3.2.22.3 Batch Retrieve Vertices Based on Shard Information
Retrieve vertices in batches based on the specified shard information (refer to 3.2.21.2 Shard for obtaining shard information).
Params
- start: Shard start position, required.
- end: Shard end position, required.
- page: Page position for pagination, optional. Default is null, no pagination. When page is “”, it represents the first page of pagination starting from the position indicated by start.
- page_limit: The upper limit of the number of vertices per page when retrieving vertices with pagination, optional. Default is 100000.
Method & Url
Response Status
Response Body
3.2.22.4 Use Cases
- Querying vertices by ID list, which can be used for batch vertex queries. For example, after querying multiple paths in a path search, you can further query all vertex properties of a specific path.
- Retrieving shards and querying vertices by shard, which can be used to traverse all vertices.
3.2.23 Edges
3.2.23.1 Batch Retrieve Edges Based on Edge IDs
Params
- ids: List of edge IDs to be queried.
Method & Url
Response Status
Response Body
3.2.23.2 Retrieve Edge Shard Information
Retrieve shard information for edges by specifying the shard size (split_size). This can be used in conjunction with the Scan operation described in section 3.2.22.3 to retrieve edges.
Params
- split_size: Shard size, required field.
Method & Url
Response Status
Response Body
3.2.23.3 Batch Retrieve Edges Based on Shard Information
Batch retrieve edges by specifying shard information (refer to section 3.2.22.2 for shard retrieval).
Params
- start: Shard starting position, required field.
- end: Shard ending position, required field.
- page: Page position for pagination, optional field. Default is null, which means no pagination. When
pageis empty, it indicates the first page of pagination starting from the position indicated bystart. - page_limit: Upper limit of the number of edges per page for paginated retrieval, optional field. Default is 100000.
Method & Url
Response Status
Response Body
3.2.23.4 Use Cases
- Querying edges based on ID list, suitable for batch retrieval of edges.
- Retrieving shard information and querying edges based on shards, useful for traversing all edges.
5.1.11 - Rank API
4.1 Rank API overview
Not only the Graph iteration (traverser) method, HugeGraph-Server also provide Rank API for recommendation purpose.
You can use it to recommend some vertexes much closer to a vertex.
4.2 Details of Rank API
4.2.1 Personal Rank API
A typical scenario for Personal Rank algorithm is in recommendation application. According to the out edges of a vertex,
recommend some other vertices that having the same or similar edges.
Here is a use case: According to someone’s reading habit or reading history, we can recommend some books he may be interested or some book pal.
For Example:
- Suppose we have a vertex, Person type, and named tom.He like 5 books
a,b,c,d,e. If we want to recommend some book pal and books for tom, an easier idea is let’s check whoever also liked these books (common hobby based). - Now, we need someone else, like neo, he like three books
b,d,f. And Jay, he like 4 booksc,d,e,g, and Lee, he also like 4 booksa,d,e,f. - For we don’t need to recommend books tom already read, the recommend-list should only contain the books Tom’s book pal already read but tom haven’t read yet. Such as book “f” and “g”, and with priority f > g.
- Now, we recompute Tom’s personal rank value, we will get a sorted TopN book pal or book recommend-list. (Choose OTHER_LABEL,for Only Book purpose)
4.2.1.0 Data Preparation
The case above is simple. Here we also provide a public test dataset MovieLens for use case. You should download the dataset. The load it into HugeGraph with HugeGraph-Loader. To make it simple, we ignore all properties data of user and move. only field id is enough. we also ignore the value of edge rating.
The metadata for input file and mapping file as follows:
Note: modify the
input.pathto your local path.
4.2.1.1 Function Introduction
suitable for bipartite graph, will return all vertex or a list of its correlation which related to all source vertex.
Bipartite Graph is a special model in Graph Theory, as well as a special flow in network. The strongest feature is, it split all vertex in graph into two sets. The vertex in the set is not connected. However,the vertex in two sets may connect with each other.
Suppose we have one bipartite graph based on user and things. A random walk based PersonalRank algorithm should be likes this:
- Choose a user u as start vertex, let’s set the initial weight to be 1.0 . Go from Vu with probability alpha to a neighbor vertex, and (1-alpha) to stay.
- If we decide to go outside, we would like to choose an edge, such as
rating, to find a common judge.- Then choose the neighbors of current vertex randomly with uniform distribution, and reset the weights with uniform distribution.
- Compensate the source vertex’s weight with (1 - alpha)
- Repeat step 2;
- Convergence after reaching a certain number of steps or precision, then we got a recommend-list.
Params
Required:
- source: the id of source vertex
- label: edge label go from the source vertex, should connect two different type of vertex
Optional:
- alpha: the probability of going out for one vertex in each iteration,similar to the alpha of PageRank,required, value range is (0, 1], default 0.85.
- max_degree: in query process, the max iteration number of adjacency edge for a vertex, default
10000 - max_depth: iteration number,range [2, 50], default
5 - with_label:result filter,default
BOTH_LABEL,optional list as follows:- SAME_LABEL:Only keep vertex which has the same type as source vertex
- OTHER_LABEL:Only keep vertex which has different type as source vertex (the another part in bipartite graph)
- BOTH_LABEL:Keep both type vertex
- limit: max return vertex number,default
100 - max_diff: accuracy for convergence, default
0.0001(will implement soon) - sorted: whether sort the result by rank or not, true for descending sort, false for none, default
true
4.2.1.2 Usage
Method & Url
Request Body
Response Status
Response Body
4.2.1.3 Suitable Scenario
In a bipartite graph build by two different type of vertex, recommend other most related vertex to one vertex. for example:
- Reading recommendation: find out the books should be recommended to someone first, It is also possible to recommend book pal with the highest common preferences at the same time (just like: WeChat “your friend also read xx " function)
- Social recommendation: find out other Poster who interested in same topics, or other News/Messages you may be interested with (Such as : “Hot News” function in Weibo)
- Commodity recommendation: according to someone’s shopping habit,find out a commodity list should recommend first, some online salesman may also be good (Such as : “You May Like” function in TaoBao)
4.2.2 Neighbor Rank API
4.2.2.0 Data Preparation
4.2.2.1 Function Introduction
In a general graph structure,find the first N vertices of each layer with the highest correlation with a given starting point and their relevance.
In graph words: to go out from the starting point, get the probability of going to each vertex of each layer.
Params
- source: id of source vertex,required
- alpha:the probability of going out for one vertex in each iteration,similar to the alpha of PageRank,required, value range is (0, 1]
- steps: a path rule for source vertex visited,it’s a list of Step,each Step map to a layout in result,required.The structure of each Step as follows:
- direction:the direction of edge(OUT, IN, BOTH), BOTH for default.
- labels:a list of edge types, will union all edge types
- max_degree:in query process, the max iteration number of adjacency edge for a vertex, default
10000(Note: before v0.12 step only support degree as parameter name, from v0.12, use max_degree, compatible with degree) - top: retains only the top N results with the highest weight in each layer of the results, default 100, max 1000
- capacity: the maximum number of vertexes visited during the traversal, optional, default 10000000
4.2.2.2 Usage
Method & Url
Request Body
Response Status
Response Body
4.2.2.3 Suitable Scenario
Find the vertices in different layers for a given start point that should be most recommended
- For example, in the four-layered structure of the audience, friends, movies, and directors, according to the movies that a certain audience’s friends like, recommend movies for that audience, or recommend directors for those movies based on who made them.
5.1.12 - Variable API
5.1 Variables
Variables can be used to store data about the entire graph. The data is accessed and stored in the form of key-value pairs.
5.1.1 Creating or Updating a Key-Value Pair
Method & Url
Request Body
Response Status
Response Body
5.1.2 Listing all key-value pairs
Method & Url
Response Status
Response Body
5.1.3 Listing a specific key-value pair
Method & Url
Response Status
Response Body
5.1.4 Deleting a specific key-value pair
Method & Url
Response Status
5.1.13 - Graphs API
6.1 Graphs
Important Reminder: Since HugeGraph 1.7.0, dynamic graph creation must enable authentication mode. For non-authentication mode, please refer to Graph Configuration File to statically create graphs through configuration files.
6.1.1 List all graphs in the graphspace
Params
Path parameters
- graphspace: Graphspace name
Method & Url
Response Status
Response Body
6.1.2 Get details of the graph
Params
Path parameters
- graphspace: Graphspace name
- graph: Graph name
Method & Url
Response Status
Response Body
6.1.3 Clear all data of a graph, include: schema, vertex, edge and index, This operation requires administrator privileges
Params
Path parameters
- graphspace: Graphspace name
- graph: Graph name
Query parameters
Since emptying the graph is a dangerous operation, we have added parameters for confirmation to the API to avoid false calls by users:
- confirm_message: default by
I'm sure to delete all data
Method & Url
Response Status
6.1.4 Clone graph, this operation requires administrator privileges
Params
Path parameters
- graphspace: Graphspace name
- graph: Name of the new graph to create
Query parameters
- clone_graph_name: name of an existed graph. To clone from an existing graph, the user can choose to transfer the configuration file, which will replace the configuration in the existing graph
Method & Url
Request Body [Optional]
Clone a non-auth mode graph (set Content-Type: application/json)
Note:
- The data/wal_path can’t be the same as the existing graph (use separate directories)
- Replace “gremlin.graph=org.apache.hugegraph.auth.HugeFactoryAuthProxy” to enable auth mode
Response Status
Response Body
6.1.5 Create graph, this operation requires administrator privileges
Params
Path parameters
- graphspace: Graphspace name
- graph: Graph name
Method & Url
Request Body
Create a non-auth graph (set Content-Type: application/json)
Note:
- The data/wal_path can’t be the same as the existing graph (use separate directories)
- Replace “gremlin.graph=org.apache.hugegraph.auth.HugeFactoryAuthProxy” to enable auth mode
Response Status
Response Body
6.1.6 Delete graph and its data
Params
Path parameters
- graphspace: Graphspace name
- graph: Graph name
Query parameters
Since deleting a graph is a dangerous operation, we have added parameters for confirmation to the API to avoid false calls by users:
- confirm_message: default by
I'm sure to drop the graph
Method & Url
Response Status
Note: For HugeGraph 1.5.0 and earlier versions, if you need to create or drop a graph, please still use the legacy
text/plain(properties) style request body instead of JSON.
6.2 Conf
6.2.1 Get configuration for a graph, This operation requires administrator privileges
Params
Path parameters
- graphspace: Graphspace name
- graph: Graph name
Method & Url
Response Status
Response Body
6.3 Mode
Allowed graph mode values are: NONE, RESTORING, MERGING, LOADING
- None mode is regular mode
- Not allowed to create schema with specified id
- Not support creating vertex with id for AUTOMATIC id strategy
- LOADING mode used to load data via hugegraph-loader.
- When adding vertices / edges, it is not checked whether the required attributes are passed in
Restore has two different modes: Restoring and Merging
- Restoring mode is used to restore schema and graph data to a new graph.
- Support create schema with specified id
- Support create vertex with id for AUTOMATIC id strategy
- Merging mode is used to merge schema and graph data to an existing graph.
- Not allowed to create schema with specified id
- Support create vertex with id for AUTOMATIC id strategy
Under normal circumstances, the graph mode is None. When you need to restore the graph, you need to temporarily modify the graph mode to Restoring or Merging as needed. When you complete the restore, change the graph mode to None.
6.3.1 Get graph mode
Params
Path parameters
- graphspace: Graphspace name
- graph: Graph name
Method & Url
Response Status
Response Body
Allowed graph mode values are: NONE, RESTORING, MERGING
6.3.2 Modify graph mode. This operation requires administrator privileges
Params
Path parameters
- graphspace: Graphspace name
- graph: Graph name
Method & Url
Request Body
Allowed graph mode values are: NONE, RESTORING, MERGING
Response Status
Response Body
6.3.3 Get graph’s read mode
Params
Path parameters
- graphspace: Graphspace name
- graph: Graph name
Method & Url
Response Status
Response Body
6.3.4 Modify graph’s read mode. This operation requires administrator privileges
Params
Path parameters
- graphspace: Graphspace name
- graph: Graph name
Method & Url
Request Body
Allowed read mode values are: ALL, OLTP_ONLY, OLAP_ONLY
Response Status
Response Body
6.4 Snapshot
6.4.1 Create a snapshot
Params
Path parameters
- graphspace: Graphspace name
- graph: Graph name
Method & Url
Response Status
Response Body
6.4.2 Resume a snapshot
Params
Path parameters
- graphspace: Graphspace name
- graph: Graph name
Method & Url
Response Status
Response Body
6.5 Compact
6.5.1 Manually compact graph, This operation requires administrator privileges
Params
Path parameters
- graphspace: Graphspace name
- graph: Graph name
Method & Url
Response Status
Response Body
5.1.14 - Task API
7.1 Task
7.1.1 List all async tasks in graph
Params
- status: the status of asyncTasks
- limit: the max number of tasks to return
Method & Url
Response Status
Response Body
7.1.2 View the details of an async task
Method & Url
Response Status
Response Body
7.1.3 Delete task information of an async task,won’t delete the task itself
Method & Url
Response Status
7.1.4 Cancel an async task, the task should be able to be canceled
If you already created an async task via Gremlin API as follows:
Method & Url
cancel it in 10s. if more than 10s, the task may already be finished, then can’t be cancelled.
Response Status
Response Body
At this point, the number of vertices whose label is man must be less than 10.
5.1.15 - Gremlin API
8.1 Gremlin
8.1.1 Sending a gremlin statement (GET) to HugeGraphServer for synchronous execution
Params
- gremlin: The gremlin statement to be sent to
HugeGraphServerfor execution - bindings: Used to bind parameters. Key is a string, and the value is the bound value (can only be a string or number). This functionality is similar to MySQL’s Prepared Statement and is used to speed up statement execution.
- language: The language type of the sent statement. Default is
gremlin-groovy. - aliases: Adds aliases for existing variables in the graph space.
Querying vertices
Method & Url
Response Status
Response Body
8.1.2 Sending a gremlin statement (POST) to HugeGraphServer for synchronous execution
Method & Url
Querying vertices
Request Body
Response Status
Response Body
Note:
Here we directly use the graph object (
hugegraph), first retrieve its traversal iterator (traversal()), and then retrieve the vertices. Instead of writinggraph.traversal().V()org.V(), you can use aliases to operate on the graph and traversal iterator. In this case,hugegraphis a native variable, and__g_hugegraphis an additional variable added by HugeGraphServer. Each graph will have a corresponding traversal iterator object in this format (__g_${graph}).
The structure of the response body is different from the RESTful API structure of other vertices or edges. Users may need to parse it manually.
Querying edges
Request Body
Response Status
Response Body
8.1.3 Sending a gremlin statement (POST) to HugeGraphServer for asynchronous execution
Method & Url
Querying vertices
Request Body
Note:
Asynchronous execution of Gremlin statements does not currently support aliases. You can use
graphto represent the graph you want to operate on, or directly use the name of the graph, such ashugegraph. Additionally,grepresents the traversal, which is equivalent tograph.traversal()orhugegraph.traversal().
Response Status
Response Body
Note:
You can query the execution status of an asynchronous task by using
GET http://localhost:8080/graphspaces/DEFAULT/graphs/hugegraph/tasks/1(where “1” is the task_id). For more information, refer to the Asynchronous Task RESTful API.
Querying edges
Request Body
Response Status
Response Body
Note:
You can query the execution status of an asynchronous task by using
GET http://localhost:8080/graphspaces/DEFAULT/graphs/hugegraph/tasks/2(where “2” is the task_id). For more information, refer to the Asynchronous Task RESTful API.
5.1.16 - Cypher API
9.1 Cypher
9.1.1 Sending a cypher statement (GET) to HugeGraphServer for synchronous execution
Method & Url
Params
Path parameters
- graphspace: Graphspace name
- graph: Graph name
Query parameters
- cypher: Cypher statement
Example
Response Status
Response Body
9.1.2 Sending a cypher statement (POST) to HugeGraphServer for synchronous execution
Method & Url
Params
Path parameters
- graphspace: Graphspace name
- graph: Graph name
Body
{cypher}
- cypher: Cypher statement
Note:
It is not in JSON format, but a plain text Cypher statement.
Example
Request Body
Response Status
Response Body
5.1.17 - Authentication API
10.1 User Authentication and Access Control
To enable authentication and related configurations, please refer to the Authentication Configuration documentation.
Overview of User Authentication and Access Control:
HugeGraph supports multi-user authentication and fine-grained access control. It adopts a 4-tier design based on “User-User Group-Operation-Resource” to flexibly control user roles and permissions. Resources describe data in the graph database, such as vertices that meet certain conditions. Each resource consists of three elements: type, label, and properties. There are a total of 18 types and combinations of any label and properties to form resources. The internal condition of a resource is an “AND” relationship, while the condition between multiple resources is an “OR” relationship. Users can belong to one or more user groups, and each user group can have permissions for any number of resources. The types of operations include read, write, delete, execute, etc. HugeGraph supports dynamically creating users, user groups, and resources, and supports dynamically assigning or revoking permissions. During the initialization of the database, a super administrator user is created, and subsequently, various role users can be created by the super administrator. If a newly created user is assigned sufficient permissions, they can create or manage more users.
Example:
user(name=boss) -belong-> group(name=all) -access(read)-> target(graph=graph1, resource={label: person, city: Beijing})
Description: User ‘boss’ has read permission for people in the ‘graph1’ graph from Beijing.
Interface Description:
The user authentication and access control interface includes 5 categories: UserAPI, GroupAPI, TargetAPI, BelongAPI, AccessAPI. Note Before 1.5.0, the format of ids such as group/target was similar to -69:grant. After 1.7.0, the id and name were consistent. Such as admin HugeGraph 1.5 x RESTful API
10.2 User (User) API
The user interface includes APIs for creating users, deleting users, modifying users, and querying user-related information.
10.2.1 Create User
Params
- user_name: User name
- user_password: User password
- user_phone: User phone number
- user_email: User email
Both user_name and user_password are required.
Request Body
Method & Url
Response Status
Response Body
In the response message, the password is encrypted as ciphertext.
10.2.2 Delete User
Params
- id: User ID to be deleted
Method & Url
Response Status
Response Body
10.2.3 Modify User
Params
- id: User ID to be modified
Method & Url
Request Body
Modify user_name, user_password, and user_phone.
Response Status
Response Body
The returned result is the entire user object including the modified content.
10.2.4 Query User List
Params
- limit: Upper limit of the number of results returned
Method & Url
Response Status
Response Body
10.2.5 Query a User
Params
- id: User ID to be queried
Method & Url
Response Status
Response Body
10.2.6 Query Roles of a User
Method & Url
Response Status
Response Body
10.3 Group (Group) API
Groups grant corresponding resource permissions, and users are assigned to different groups, thereby having different resource permissions. The group interface includes APIs for creating groups, deleting groups, modifying groups, and querying group-related information.
10.3.1 Create Group
Params
- group_name: Group name
- group_description: Group description
Request Body
Method & Url
Response Status
Response Body
10.3.2 Delete Group
Params
- id: Group ID to be deleted
Method & Url
Response Status
Response Body
10.3.3 Modify Group
Params
- id: Group ID to be modified
Method & Url
Request Body
Modify group_description
Response Status
Response Body
The returned result is the entire group object including the modified content.
10.3.4 Query Group List
Params
- limit: Upper limit of the number of results returned
Method & Url
Response Status
Response Body
10.3.5 Query a Specific Group
Params
- id: Group ID to be queried
Method & Url
Response Status
Response Body
10.4 Resource (Target) API
Resources describe data in the graph database, such as vertices that meet certain criteria. Each resource includes three elements: type, label, and properties. There are 18 types in total, and the combination of any label and any properties forms a resource. The internal conditions of a resource are based on the AND relationship, while the conditions between multiple resources are based on the OR relationship.
The resource API includes creating, deleting, modifying, and querying resources.
10.4.1 Create Resource
Params
- target_name: Name of the resource
- target_graph: Graph of the resource
- target_url: URL of the resource
- target_resources: Resource definitions (list)
target_resources can include multiple target_resource, stored in the form of a list.
Each target_resource contains:
- type: Optional value: VERTEX, EDGE, etc. Can be filled with ALL, indicating it can be a vertex or edge.
- label: Optional value: name of a vertex or edge type. Can be filled with *, indicating any type.
- properties: Map type, can contain multiple key-value pairs of properties. Must match all property values. Property values can support conditional ranges (e.g., age: P.gte(18)). If properties are null, it means any property is allowed. If both the property name and value are ‘*’, it also means any property is allowed.
For example, a specific resource: “target_resources”: [{“type”:“VERTEX”,“label”:“person”,“properties”:{“city”:“Beijing”,“age”:“P.gte(20)”}}]
The resource definition means: a vertex of type ‘person’ with the city property set to ‘Beijing’ and the age property greater than or equal to 20.
Request Body
Method & Url
Response Status
Response Body
10.4.2 Delete Resource
Params
- id: Resource Id to be deleted
Method & Url
Response Status
Response Body
10.4.3 Modify Resource
Params
- id: Resource Id to be modified
Method & Url
Request Body
Modify the ’type’ in the resource definition.
Response Status
Response Body
The response contains the entire target group object, including the modified content.
10.4.4 Query Resource List
Params
- limit: Upper limit of the number of returned results.
Method & Url
Response Status
Response Body
10.4.5 Query a Specific Resource
Params
- id: Id of the resource to query
Method & Url
Response Status
Response Body
10.5 Association of Roles (Belong) API
The association between users and user groups allows a user to be associated with one or more user groups. User groups have permissions for related resources, and the permissions for different user groups can be understood as different roles. In other words, users are associated with roles.
The API for associating roles includes creating, deleting, modifying, and querying the association of roles for users.
10.5.1 Create an Association of Roles for a User
Params
- user: User ID
- group: User group ID
- belong_description: Description
Request Body
Method & Url
Response Status
Response Body
10.5.2 Delete an Association of Roles
Params
- id: ID of the association of roles to delete
Method & Url
Response Status
Response Body
10.5.3 Modify an Association of Roles
An association of roles can only be modified for its description. The user and group properties cannot be modified. If you need to modify an association of roles, you need to delete the existing association and create a new one.
Params
- id: ID of the association of roles to modify
Method & Url
Request Body
Modify the belong_description field
Response Status
Response Body
The response includes the modified content as well as the entire association of roles object
10.5.4 Query List of Associations of Roles
Params
- limit: Upper limit on the number of results to return
Method & Url
Response Status
Response Body
10.5.5 View a Specific Association of Roles
Params
- id: The id of the association of roles to be queried
Method & Url
Response Status
Response Body
10.6 Authorization (Access) API
Grant permissions to user groups for resources, including operations such as READ, WRITE, DELETE, EXECUTE, etc. The authorization API includes: creating, deleting, modifying, and querying permissions.
10.6.1 Create Authorization (Granting permissions to user groups for resources)
Params
- group: Group ID
- target: Resource ID
- access_permission: Permission grant
- access_description: Authorization description
Access permissions:
- READ: Read operations, including all queries such as querying the schema, retrieving vertices/edges, aggregating vertex and edge counts (VERTEX_AGGR/EDGE_AGGR), and reading the graph’s status (STATUS), variables (VAR), tasks (TASK), etc.
- WRITE: Write operations, including creating and updating operations, such as adding property keys to the schema or adding/updating properties of vertices.
- DELETE: Delete operations, including deleting metadata, vertices, or edges.
- EXECUTE: Execute operations, including executing Gremlin queries, executing tasks, and executing metadata functions.
Request Body
Method & Url
Response Status
Response Body
10.6.2 Delete Authorization
Params
- id: The ID of the authorization to be deleted
Method & Url
Response Status
Response Body
10.6.3 Modify Authorization
Authorization can only be modified for its description. User group, resource, and permission cannot be modified. If you need to modify the authorization relationship, delete the original authorization and create a new one.
Params
- id: The ID of the authorization to be modified
Method & Url
Request Body
Modify access_description
Response Status
Response Body
The response includes the modified content as well as the entire authorization object.
10.6.4 Query Authorization List
Params
- limit: The maximum number of results to return
Method & Url
Response Status
Response Body
10.6.5 Query a Specific Authorization
Params
- id: The ID of the authorization to be queried
Method & Url
Response Status
Response Body
10.7 Graphspace Manager (Manager) API
Note: Before using the following APIs, you need to create a graphspace first. For example, create a graphspace named
gs1via the Graphspace API. The examples below assume thatgs1already exists.
- The graphspace manager API is used to grant/revoke manager roles for users at the graphspace level, and to query the roles of the current user or other users in a graphspace. Supported role types include
SPACE,SPACE_MEMBER, andADMIN.
10.7.1 Check whether the current login user has a specific role
Params
- type: Role type to check, optional
Method & Url
Response Status
Response Body
The API returns the string true or false indicating whether the current user has the given role.
10.7.2 List graphspace managers
Params
- type: Role type, optional, used to filter by role
Method & Url
Response Status
Response Body
10.7.3 Grant/create a graphspace manager
- The following example grants user
bosstheSPACE_MEMBERrole in graphspacegs1.
Request Body
Method & Url
Response Status
Response Body
10.7.4 Revoke graphspace manager privileges
- The following example revokes the
SPACE_MEMBERrole of userbossin graphspacegs1.
Params
- user: User ID to revoke
- type: Role type to revoke
Method & Url
Response Status
Response Body
10.7.5 Query roles of a specific user in a graphspace
Params
- user: User ID
Method & Url
Response Status
Response Body
5.1.18 - Metrics API
HugeGraph provides a metrics interface for obtaining monitoring information, such as statistics on each Gremlin execution time, cache size, etc. The metrics interface includes the following categories: basic metrics, statistical metrics, system metrics, and backend storage metrics.
1. Basic Metrics
1.1 Get All Basic Metrics
Params
- type: If the passed value is
json, it is returned in json format, otherwise it is returned in Promethaus format.
1.1.1 Method & Url
Response Status
Response Body
1.1.2 Method & Url
Response Status
Response Body
1.2 Get Gauges Metrics
Method & Url
Response Status
Response Body
1.3 Get Counters Metrics
Method & Url
Response Status
Response Body
1.4 Get Histograms Metrics
Method & Url
Response Status
Response Body
1.5 Get Meters Metrics
Method & Url
Response Status
Response Body
1.6 Get Timers Metrics
Method & Url
Response Status
Response Body
2.Statistical Metrics
Params
- type: If the passed value is JSON, it is returned in JSON format, otherwise it is returned in Promethaus format.
2.1 Method & Url
Response Status
Response Body
2.2 Method & Url
Response Status
Response Body
3.System Metrics
System metrics mainly return the machine metrics, such as memory, threads, and other information.
Method & Url
Response Status
Response Body
4.Backend Metrics
HugeGraph supports multiple backend storage, with backend metrics including memory, disk, and other information.
Method & Url
Response Status
Response Body
5.1.19 - Other API
11.1 Other
11.1.1 View Version Information of HugeGraph
Method & Url
Response Status
Response Body
5.2 - HugeGraph Java Client
The code in this document is written in java, but its style is very similar to gremlin(groovy). The user only needs to replace the variable declaration in the code with def or remove it directly,
You can convert java code into groovy; in addition, each line of statement can be without a semicolon at the end, groovy considers a line to be a statement.
The gremlin(groovy) written by the user in HugeGraph-Studio can refer to the java code in this document, and some examples will be given below.
1 HugeGraph-Client
HugeGraph-Client is the general entry for operating graph. Users must first create a HugeGraph-Client object and establish a connection (pseudo connection) with HugeGraph-Server before they can obtain the operation entry objects of schema, graph and gremlin.
HugeGraph-Client connects to an existing graph on the server. Its builder accepts a GraphSpace; the two-argument builder, or an empty GraphSpace value, uses DEFAULT.
If the above process of creating HugeClient fails, an exception will be thrown, and the user needs to use try-catch. If successful, continue to get schema, graph and gremlin manager.
When operating through gremlin in HugeGraph-Hubble(or HugeGraph-Studio), HugeClient is not required and can be ignored.
2 Schema
2.1 SchemaManager
SchemaManager is used to manage four kinds of schema in HugeGraph, namely PropertyKey (property type), VertexLabel (vertex type), EdgeLabel (edge type) and IndexLabel (index label). A SchemaManager object can be created for schema information definition.
The user can obtain the SchemaManager object using the following methods:
Create a schema object via gremlin in HugeGraph-Hubble:
The definition process of the 4 kinds of schema is described below.
2.2 PropertyKey
2.2.1 Interface and parameter introduction
PropertyKey is used to standardize the property constraints of vertices and edges, and properties of properties are not currently supported.
The constraint information that PropertyKey allows to define includes: name, datatype, cardinality, and userdata, which are introduced one by one below.
- name: The name of the property, used to distinguish different PropertyKeys, PropertyKeys with the same name are not allowed.
| interface | param | must set |
|---|---|---|
| propertyKey(String name) | name | y |
- datatype: property value type, you must select an explicit setting from the following table that conforms to the specific business scenario:
| interface | Java Class |
|---|---|
| asText() | String |
| asInt() | Integer |
| asDate() | Date |
| asUuid() | UUID |
| asBoolean() | Boolean |
| asByte() | Byte |
| asBlob() | Byte[] |
| asDouble() | Double |
| asFloat() | Float |
| asLong() | Long |
- cardinality: Whether the property value is single-valued or multivalued, in the case of multivalued, it is divided into allowing-duplicate values and not-allowing-duplicate values. This item is single by default. If necessary, you can select a setting from the following table:
| interface | cardinality | description |
|---|---|---|
| valueSingle() | single | single value |
| valueList() | list | multi-values that allow duplicate value |
| valueSet() | set | multi-values that not allow duplicate value |
- userdata: Users can add some constraints or additional information by themselves, and then check whether the incoming properties satisfy the constraints, or extract additional information when necessary:
| interface | description |
|---|---|
| userdata(String key, Object value) | The same key, the latter will cover the former |
2.2.2 Create PropertyKey
The syntax of creating the above PropertyKey object through gremlin in HugeGraph-Hubble is exactly the same. If the user does not define the schema variable, it should be written like this:
In the following examples, the syntax of gremlin and java is exactly the same, so we won’t repeat them.
- ifNotExist(): Add a judgment mechanism for create, if the current PropertyKey already exists, it will not be created, otherwise the property will be created. If no ifNotExist() is added, an exception will be thrown if a property-key with the same name already exists. The same as below, and will not be repeated there.
2.2.3 Delete PropertyKey
2.2.4 Query PropertyKey
2.3 VertexLabel
2.3.1 Interface and parameter introduction
VertexLabel is used to define the vertex type and describe the constraint information of the vertex.
The constraint information that VertexLabel allows to define include: name, idStrategy, properties, primaryKeys and nullableKeys, which are introduced one by one below.
- name: The name of the VertexLabel, used to distinguish different VertexLabels, VertexLabels with the same name are not allowed.
| interface | param | must set |
|---|---|---|
| vertexLabel(String name) | name | y |
- idStrategy: Each VertexLabel can choose its own ID strategy. There are currently three strategies to choose from, namely Automatic (automatically generated), Customize (user input) and PrimaryKey (primary attribute key). Among them, Automatic uses the Snowflake algorithm to generate ID, Customize requires the user to pass in the ID of string or number type, and PrimaryKey allows the user to select several properties of VertexLabel as the basis for differentiation. HugeGraph will be spliced and generated ID according to the value of the primary properties. idStrategy uses Automatic by default, but if the user does not explicitly set idStrategy and calls the primaryKeys(…) method to set the primary property, then idStrategy will automatically use PrimaryKey.
| interface | idStrategy | description |
|---|---|---|
| useAutomaticId | AUTOMATIC | generate id automatically by Snowflake algorithm |
| useCustomizeStringId | CUSTOMIZE_STRING | passed id by user, must be string type |
| useCustomizeNumberId | CUSTOMIZE_NUMBER | passed id by user, must be number type |
| usePrimaryKeyId | PRIMARY_KEY | choose some important prop as primary key to splice id |
- properties: define the properties of the vertex, the incoming parameter is the name of the PropertyKey.
| interface | description |
|---|---|
| properties(String… properties) | allow to pass multi properties |
- primaryKeys: When the user selects the ID strategy of PrimaryKey, several primary properties need to be selected from the properties of VertexLabel as the basis for differentiation;
| interface | description |
|---|---|
| primaryKeys(String… keys) | allow to choose multi prop as primaryKeys |
Note that the selection of the ID strategy and the setting of primaryKeys have some mutual constraints, which cannot be called at will. The constraints are shown in the following table:
| useAutomaticId | useCustomizeStringId | useCustomizeNumberId | usePrimaryKeyId | |
|---|---|---|---|---|
| unset primaryKeys | AUTOMATIC | CUSTOMIZE_STRING | CUSTOMIZE_NUMBER | ERROR |
| set primaryKeys | ERROR | ERROR | ERROR | PRIMARY_KEY |
- nullableKeys: For properties set by the properties(…) method, all of them are non-nullable by default, that is, the property must be assigned a value when creating a vertex, which may impose too strict integrity requirements on user data. In order to avoid such strong constraints, the user can set some properties to be nullable through this method, so that the properties can be unassigned when adding vertices.
| interface | description |
|---|---|
| nullableKeys(String… properties) | allow to pass multi props |
Note: primaryKeys and nullableKeys cannot intersect, because a property cannot be both primary and nullable.
- enableLabelIndex: The user can specify whether to create an index for the label. If you don’t create it, you can’t globally search for the vertices and edges of the specified label. If you create it, you can search globally, like
g.V().hasLabel('person'), g.E().has('label', 'person')query, but the performance will be slower when inserting data, and it will take up more storage space. This defaults to true.
| interface | description |
|---|---|
| enableLabelIndex(boolean enable) | Whether to create a label index |
- userdata: Users can add some constraints or additional information by themselves, and then check whether the incoming properties meet the constraints, or extract additional information when necessary.
| interface | description |
|---|---|
| userdata(String key, Object value) | The same key, the latter will cover the former |
2.3.2 Create VertexLabel
2.3.3 Update VertexLabel
VertexLabel can append constraints, but only properties and nullableKeys, and the appended properties must also be added to the nullableKeys collection.
2.3.4 Delete VertexLabel
2.3.5 Query VertexLabel
2.4 EdgeLabel
2.4.1 Interface and parameter introduction
EdgeLabel is used to define the edge type and describe the constraint information of the edge.
The constraint information that EdgeLabel allows to define include: name, sourceLabel, targetLabel, frequency, properties, sortKeys and nullableKeys, which are introduced one by one below.
- name: The name of the EdgeLabel, used to distinguish different EdgeLabels, EdgeLabels with the same name are not allowed.
| interface | param | must set |
|---|---|---|
| edgeLabel(String name) | name | y |
sourceLabel: The name of the source vertex type of the edge link, only one is allowed;
targetLabel: The name of the target vertex type of the edge link, only one is allowed;
| interface | param | must set |
|---|---|---|
| sourceLabel(String label) | label | y |
| targetLabel(String label) | label | y |
- frequency: Indicating the number of times a relationship occurs between two specific vertices, which can be single (single) or multiple (frequency), the default is single.
| interface | frequency | description |
|---|---|---|
| singleTime() | single | a relationship can only occur once |
| multiTimes() | multiple | a relationship can occur many times |
- properties: Define the properties of the edge.
| interface | description |
|---|---|
| properties(String… properties) | allow to pass multi props |
- sortKeys: When the frequency of EdgeLabel is multiple, some properties are needed to distinguish the multiple relationships, so sortKeys (sorted keys) is introduced;
| interface | description |
|---|---|
| sortKeys(String… keys) | allow to choose multi prop as sortKeys |
- nullableKeys: Consistent with the concept of nullableKeys in vertices.
Note: sortKeys and nullableKeys also cannot intersect.
enableLabelIndex: It is consistent with the concept of enableLabelIndex in the vertex.
userdata: Users can add some constraints or additional information by themselves, and then check whether the incoming properties meet the constraints, or extract additional information when necessary.
| interface | description |
|---|---|
| userdata(String key, Object value) | The same key, the latter will cover the former |
2.4.2 Create EdgeLabel
2.4.3 Update EdgeLabel
2.4.4 Delete EdgeLabel
2.4.5 Query EdgeLabel
2.5 IndexLabel
2.5.1 Interface and parameter introduction
IndexLabel is used to define the index type and describe the constraint information of the index, mainly for the convenience of query.
The constraint information that IndexLabel allows to define include: name, baseType, baseValue, indexFields, indexType, which are introduced one by one below.
- name: The name of the IndexLabel, used to distinguish different IndexLabels, IndexLabels with the same name are not allowed.
| interface | param | must set |
|---|---|---|
| indexLabel(String name) | name | y |
baseType: Indicates whether to index VertexLabel or EdgeLabel, used in conjunction with the baseValue below.
baseValue: Specifies the name of the VertexLabel or EdgeLabel to be indexed.
| interface | param | description |
|---|---|---|
| onV(String baseValue) | baseValue | build index for VertexLabel: ‘baseValue’ |
| onE(String baseValue) | baseValue | build index for EdgeLabel: ‘baseValue’ |
- indexFields: on which fields to index, it can be a joint index for multiple columns.
| interface | param | description |
|---|---|---|
| by(String… fields) | files | allow to build index for multi fields for secondary index |
- indexType: There are currently five types of indexes established, namely Secondary, Range, Search, Shard and Unique.
- Secondary Index supports exact matching secondary index, allow to build joint index, joint index supports index prefix search
- Single Property Secondary Index, support equality query, for example: the secondary index of the city property of the person vertex, you can use
g.V().has("city", "Beijing")to query all the vertices with “city attribute value is Beijing” - Joint Secondary Index, supports prefix query and equality query, such as: joint index of city and street properties of person vertex, you can use
g.V().has("city", "Beijing").has('street', 'Zhongguancun street ')to query all vertices of “city property value is Beijing and street property value is ZhongGuanCun”, org.V().has("city", "Beijing")to query all vertices of “city property value is Beijing”.
The query of Secondary Index is based on the query condition of “yes” or “equal”, and does not support “partial matching”.
- Single Property Secondary Index, support equality query, for example: the secondary index of the city property of the person vertex, you can use
- Range Index supports for range queries of numeric types
- Must be a single number or date attribute, for example: the range index of the age property of the person vertex, you can use
g.V().has("age", P.gt(18))to query the vertices with “age property value greater than 18” . In addition toP.gt(), also supportsP.gte(),P.lte(),P.lt(),P.eq(),P.between(),P.inside()andP.outside()etc.
- Must be a single number or date attribute, for example: the range index of the age property of the person vertex, you can use
- Search Index supports full-text search
- It must be a single text property, such as: full-text index of the address property of the person vertex, you can use
g.V().has("address", Text.contains('building')to query all vertices whose “address property contains a ‘building’”
The query of the Search Index is based on the query condition of “is” or “contains”.
- It must be a single text property, such as: full-text index of the address property of the person vertex, you can use
- Shard Index supports prefix matching + numeric range query
- The shard index of N properties supports range queries with equal prefixes. For example, the shard index of the city and age properties of the person vertex can use
g.V().has("city", "Beijing").has ("age", P.between(18, 30))Query “city property is Beijing and all vertices whose age is greater than or equal to 18 and less than 30”. - When all N properties are text properties in a Shard Index, it is equivalent to Secondary Index.
- When there is only one single number or date property in a Shard Index, it is equivalent to the Range Index.
Shard Index can have any number or date property, but at most one range search condition can be provided when querying, and the prefix properties of the Shard Search conditions must be “equals”.
- The shard index of N properties supports range queries with equal prefixes. For example, the shard index of the city and age properties of the person vertex can use
- Unique Index supports properties uniqueness constraints, that is, the value of properties can be limited to not repeat, and joint indexing is allowed, but querying is not supported now
- The unique index of single or multiple properties cannot be used for query, only the value of the property can be limited, and an error will be reported when there is a duplicate value.
- Secondary Index supports exact matching secondary index, allow to build joint index, joint index supports index prefix search
| interface | indexType | description |
|---|---|---|
| secondary() | Secondary | support prefix search |
| range() | Range | support range(numeric or date type) search |
| search() | Search | support full text search |
| shard() | Shard | support prefix + range(numeric or date type) search |
| unique() | Unique | support unique props value, not support search |
2.5.2 Create IndexLabel
2.5.3 Delete IndexLabel
2.5.4 Query IndexLabel
3 Graph
3.1 Vertex
Vertices are the most basic elements of a graph, and there can be many vertices in a graph. Here is an example of adding vertices:
- The key to adding vertices is the vertex properties. The number of parameters of the vertex adding function must be an even number and satisfy the order of
key1 -> val1, key2 -> val2 ..., and the order between key-value pairs is free . - The parameter must contain a special key-value pair, namely
T.label -> "val", which is used to define the category of the vertex, so that the program can obtain the schema definition of the VertexLabel from the cache or backend, and then do subsequent constraint checks. The label in the example is defined as person. - If the vertex type’s ID policy is
AUTOMATIC, users are not allowed to pass in id key-value pairs. - If the ID policy of the vertex type is
CUSTOMIZE_STRING, the user needs to pass in the value of the id of the String type. The key-value pair is like:"T.id", "123456". - If the ID policy of the vertex type is
CUSTOMIZE_NUMBER, the user needs to pass in the value of the id of the Number type. The key-value pair is like:"T.id", 123456. - If the ID policy of the vertex type is
PRIMARY_KEY, the parameters must also contain the name and value of the properties corresponding to theprimaryKeys, if not set an exception will be thrown. For example, theprimaryKeysofpersonisname, in the example, the value ofnameis set tomarko. - For properties that are not nullableKeys, a value must be assigned.
- The remaining parameters are the settings of other properties of the vertex, but they are not required.
- After calling the
addVertexmethod, the vertices are inserted into the backend storage system immediately.
3.2 Edge
After added vertices, edges are also needed to form a complete graph. Here is an example of adding edges:
- The function
addEdge()of the (source) vertex is to add an edge(relationship) between itself and another vertex. The first parameter of the function is the label of the edge, and the second parameter is the target vertex. The position and order of these two parameters are fixed. The subsequent parameters are the order ofkey1 -> val1, key2 -> val2 ..., set the properties of the edge, and the key-value pair order is free. - The source and target vertices must conform to the definitions of source-label and target label in EdgeLabel, and cannot be added arbitrarily.
- For properties that are not nullableKeys, a value must be assigned.
Note: When frequency is multiple, the value of the property type corresponding to sortKeys must be set.
4 GraphSpace
The client can manage multiple GraphSpaces in one physical deployment, and each GraphSpace can contain multiple graphs. When no GraphSpace is specified, it uses DEFAULT.
4.1 Create GraphSpace
4.2 GraphSpace Interface Summary
| Category | Interface | Description |
|---|---|---|
| Manager - Query | listGraphSpace() | Get all GraphSpace names |
| listProfile() / listProfile(String prefix) | Get GraphSpace profiles | |
| getGraphSpace(String name) | Get the specified GraphSpace | |
| getDefault() | Get the default GraphSpace | |
| Manager - Create/Update | createGraphSpace(GraphSpace) | Create a GraphSpace |
| updateGraphSpace(GraphSpace) | Update configuration | |
| setDefault(String name) | Set the default GraphSpace | |
| Manager - Delete | deleteGraphSpace(String name) | Delete the specified GraphSpace |
| GraphSpace - Properties | getName() / getDescription() | Get name / description |
| getGraphNumber() | Get the number of graphs | |
| GraphSpace - Configuration | setDescription(String) | Set description |
| setMaxGraphNumber(int) | Set the maximum number of graphs |
5 Simple Example
Simple examples can reference HugeGraph-Client
5.3 - Gremlin-Console
Gremlin-Console is an interactive client developed by TinkerPop. Users can use this client to perform various operations on Graph. There are two main usage modes:
- Stand-alone offline mode
- Client/Server mode
Note: Gremlin-Console is only for users to quickly get started and experience, it is not recommended for use in production environments.
1 Stand-alone offline mode
Since the lib directory already contains the HugeCore jar package, and HugeGraph-Server has been registered in the Console as a plug-in, the users can write a groovy script directly to call the code of HugeGraph-Core, and then hand it over to the parsing engine in Gremlin-Console for execution. As a result, the users can operate the graph without starting the Server.
Here is an example, first modify the hugegraph.properties configuration to use the Memory backend (using other backends may encounter some initialization issues):
Then enter the following command:
The
--here will be parsed by getopts as the last option, allowing the subsequent options to be passed to Gremlin-Console for processing.-irepresentsExecute the specified script and leave the console open on completion. For more options, you can refer to the source code of Gremlin-Console.
example.groovy is an example script under the scripts directory. This script inserts some data and queries the number of vertices and edges in the graph at the end.
You can continue to enter Gremlin statements to operate on the graph:
For more Gremlin statements, please refer to Tinkerpop Official Website
2 Client/Server mode
Gremlin Console connects to HugeGraph Server through WebSocket. The default configuration uses WsAndHttpChannelizer, which handles both WebSocket and HTTP requests, so there is no need to switch the Channelizer.
Confirm that host and port match the settings in remote.yaml, and then follow the steps to start HugeGraph Server.
Then enter Gremlin-Console:
To connect to the server, you need to specify the connection parameters in the configuration file, and there is a default remote.yaml file in the conf directory
After a successful connection, if the sample graph example.groovy is imported during the startup of HugeGraph-Server, you can directly perform queries in the console.
NOTE: In Client/Server mode, all operations related to the Server should be prefixed with
:>. If not added, it indicates local console operations.
You can also put multiple statements in a single string variable and send them to the Server at once:
For more information on the use of Gremlin-Console, please refer to Tinkerpop Official Website
6 - GUIDES
This section covers HugeGraph architecture, design, backup and restore, plugin development, security settings, and frequently asked questions.
6.1 - HugeGraph Architecture Overview
1 Overview
As a full-stack graph system covering Graph Database, Graph Computing, and Graph AI, HugeGraph is centered around a high-performance graph engine (HugeGraph Server) and supports both OLTP and OLAP graph computation types. For the OLTP layer, it implements the Apache TinkerPop3 framework and supports the Gremlin and Cypher query languages. It comes with a complete application toolchain and provides a pluggable backend storage driver framework.
Below is the overall architecture diagram of HugeGraph:
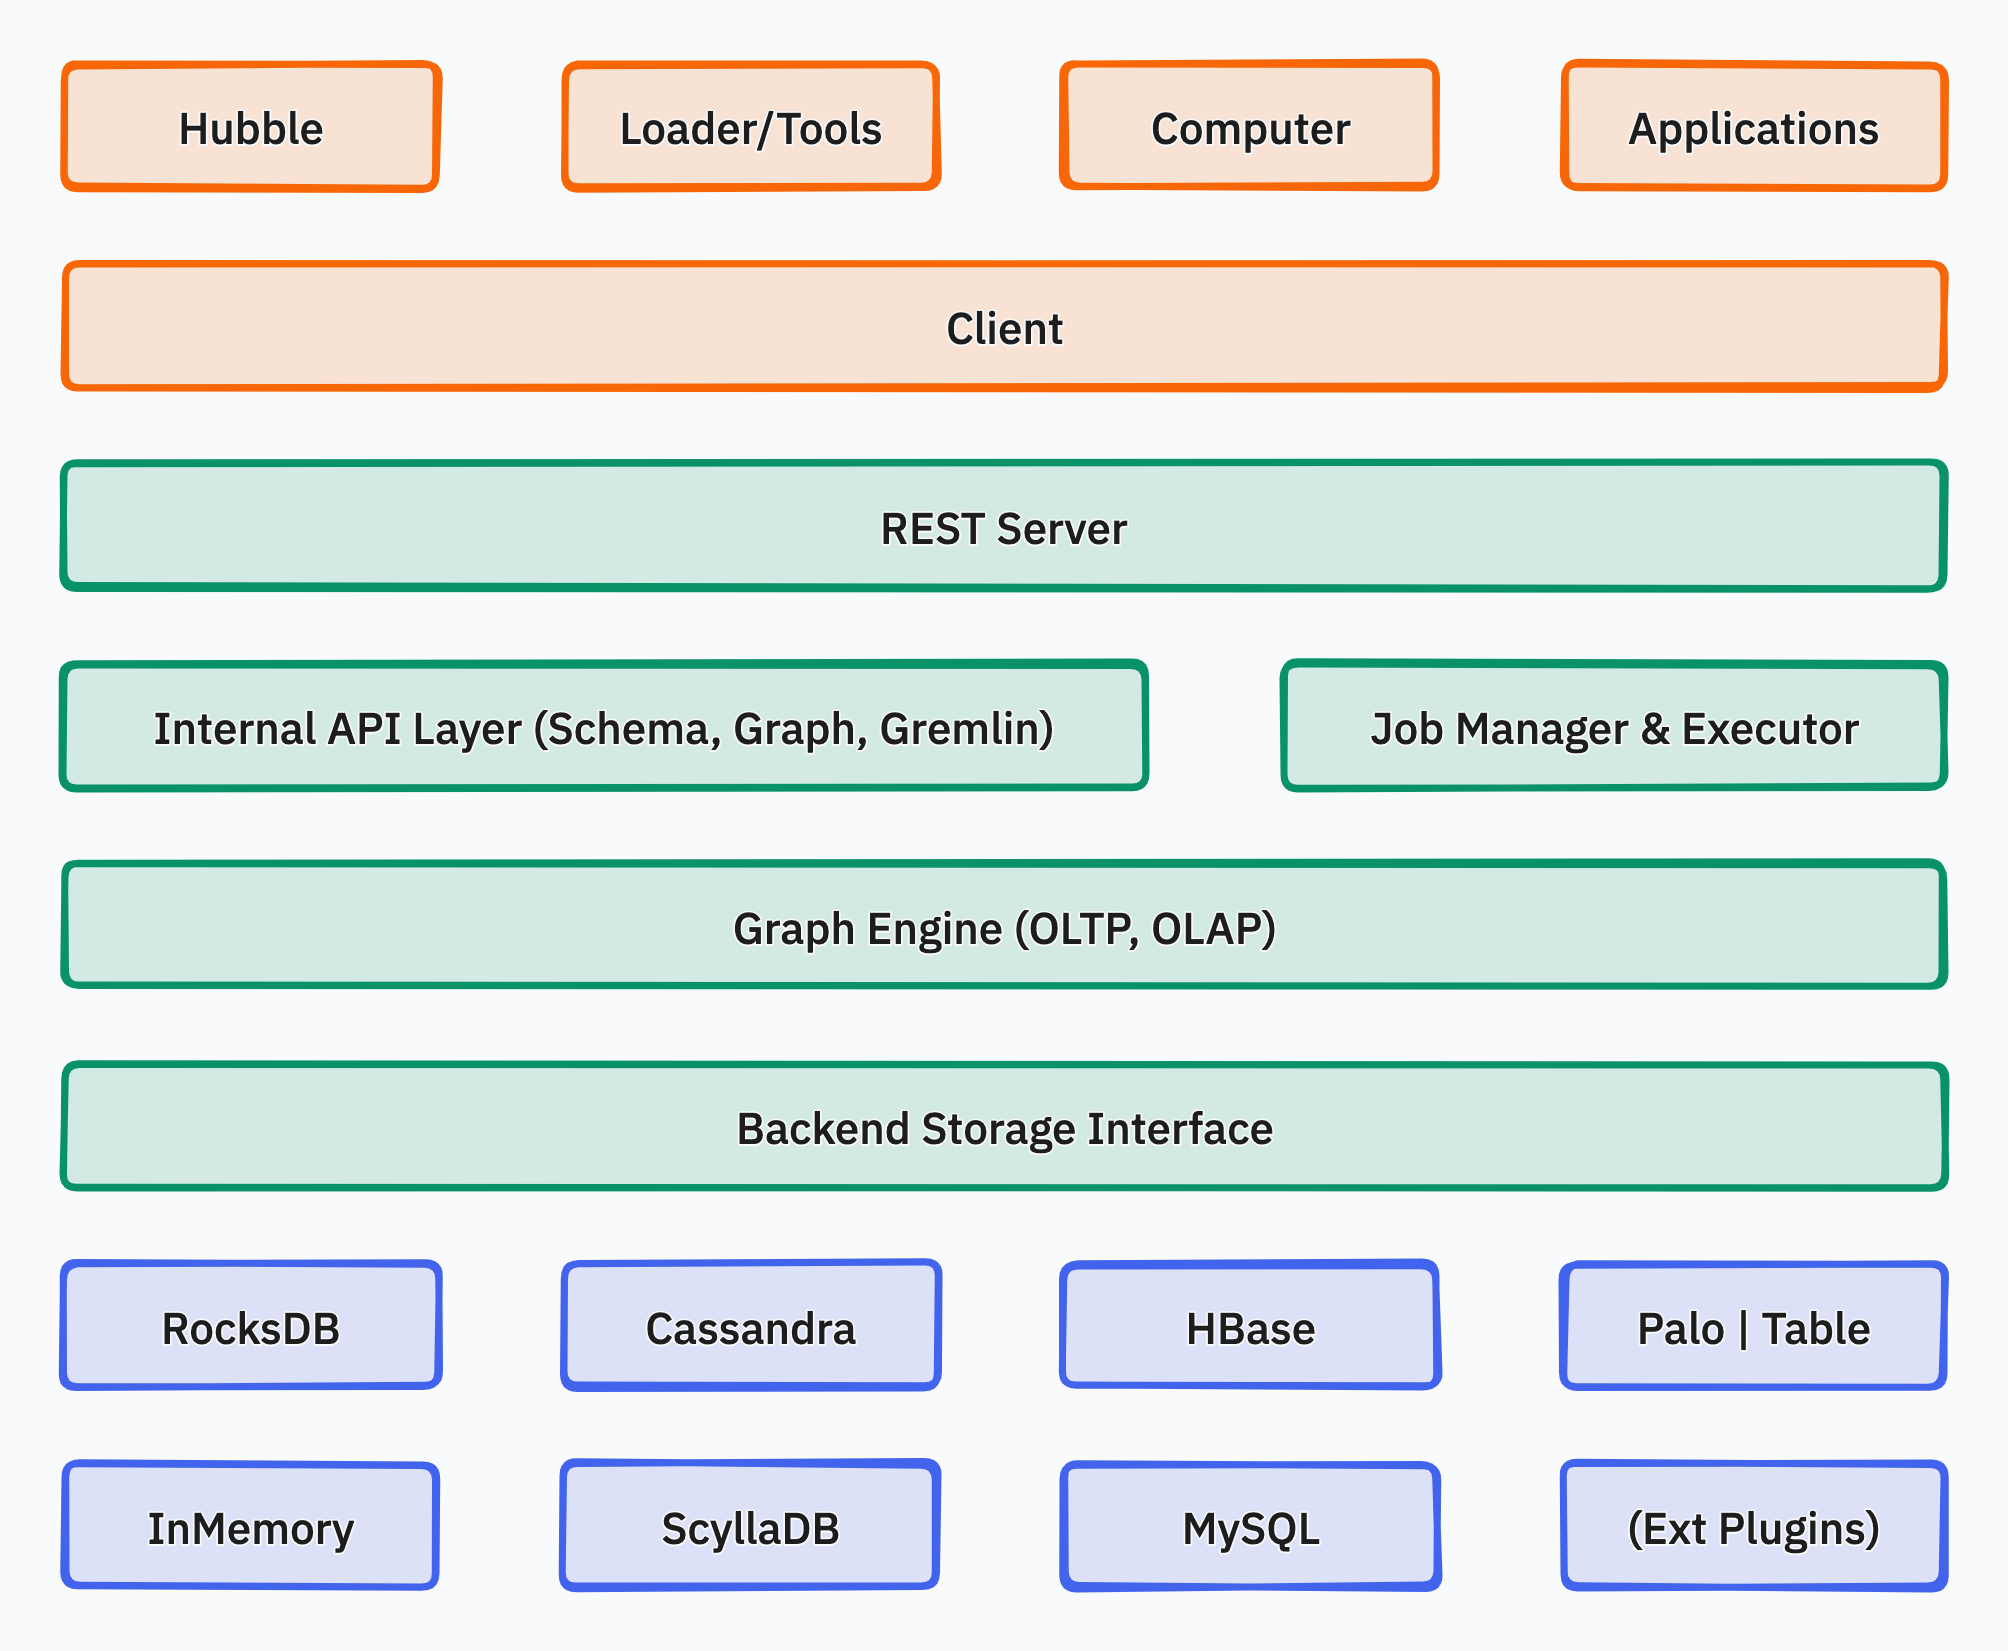
HugeGraph consists of three layers of functionality: the application layer, the graph engine layer, and the storage layer.
- Application Layer:
- Hubble: A one-stop visual analysis platform that covers the entire process from data modeling to rapid data import, online and offline analysis, and unified graph management, realizing wizard-style operations for the entire graph application process.
- Loader: A data import component that can transform data from multiple data sources into graph vertices and edges and batch import them into the graph database.
- Tools: Command-line tools for deploying, managing, and backing up/restoring data in HugeGraph.
- Computer: A distributed graph processing system (OLAP), which is an implementation of Pregel and can run on Kubernetes.
- Client: Client SDKs encapsulate the core operations for connecting to HugeGraph Server, managing schemas, reading and writing graph data, and running queries. HugeGraph currently provides Java, Python, and Go clients, while a Rust client is under development.
- Graph Engine Layer:
- REST Server: Provides a RESTful API for querying graph/schema information, supports the Gremlin and Cypher query languages, and offers APIs for service monitoring and operations.
- Graph Engine: Supports both OLTP and OLAP graph computation types, with OLTP implementing the Apache TinkerPop3 framework.
- Backend Interface: Implements the storage of graph data to the backend.
- Storage Layer:
- Storage Backend: Version 1.7.0 supports RocksDB, HStore, HBase, and Memory. Custom backends can be added through plugins.
6.2 - HugeGraph Design Concepts
1. Property Graph
There are two common graph data representation models, namely the RDF (Resource Description Framework) model and the Property Graph (Property Graph) model. Both RDF and Property Graph are the most basic and well-known graph representation modes, and both can represent entity-relationship modeling of various graphs. RDF is a W3C standard, while Property Graph is an industry standard and is widely supported by graph database vendors. HugeGraph currently uses Property Graph.
The storage concept model corresponding to HugeGraph is also designed with reference to Property Graph. For specific examples, see the figure below: ( This figure is outdated for the old version design, please ignore it and update it later )
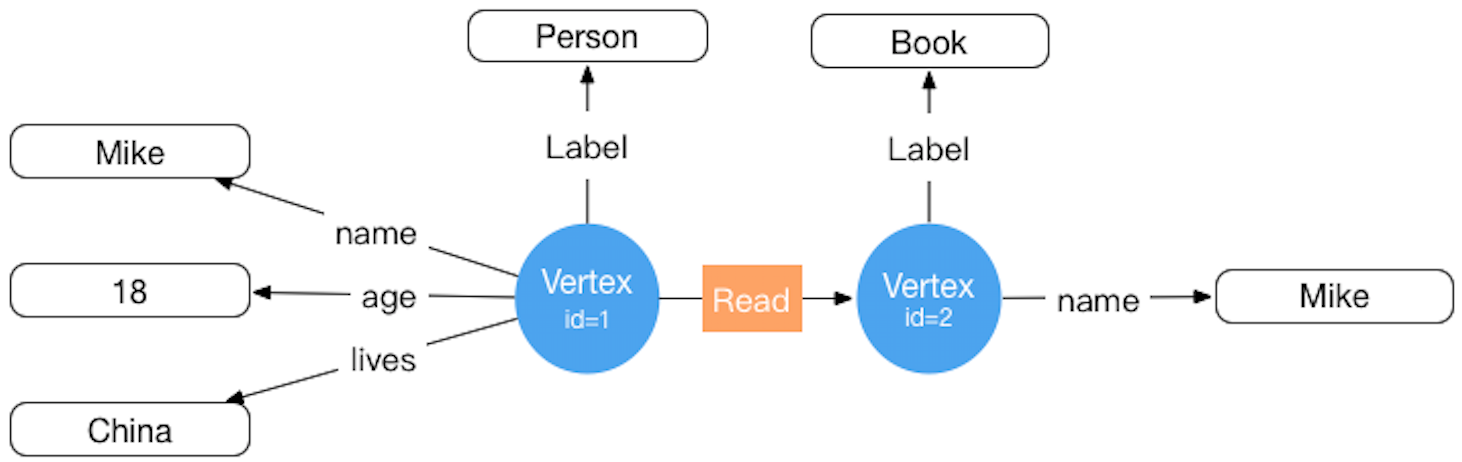
Inside HugeGraph, each vertex/edge is identified by a unique VertexId/EdgeId, and the attributes are stored inside the corresponding vertex/edge. The relationship/mapping between vertices is stored through edges.
When the vertex attribute value is stored by edge pointer, if you want to update a vertex-specific attribute value, you can directly write it by overwriting. The disadvantage is that the VertexId is redundantly stored; if you want to update the attribute of the relationship, you need to use the read-and-modify method , read all attributes first, modify some attributes, and then write to the storage system, the update efficiency is low. According to experience, there are more requirements for modifying vertex attributes, but less for edge attributes. For example, calculations such as PageRank and Graph Cluster require frequent modification of vertex attribute values.
2. Graph Partition Scheme
For distributed graph databases, there are two partition storage methods for graphs: Edge Cut and Vertex Cut, as shown in the following figure. When using the Edge Cut method to store graphs, any vertex will only appear on one machine, while edges may be distributed on different machines. This storage method may lead to multiple storage of edges. When using the Vertex Cut method to store graphs, any edge will only appear on one machine, and each same point may be distributed to different machines. This storage method may result in multiple storage of vertices.
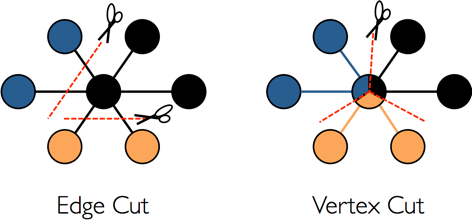
The EdgeCut partition scheme can support high-performance insert and update operations, while the VertexCut partition scheme is more suitable for static graph query analysis, so EdgeCut is suitable for OLTP graph query, and VertexCut is more suitable for OLAP graph query. HugeGraph currently adopts the partition scheme of EdgeCut.
3. VertexId Strategy
Vertex of HugeGraph supports three ID strategies. Different VertexLabels in the same graph database can use different Id strategies. Currently, the Id strategies supported by HugeGraph are:
- Automatic generation (AUTOMATIC): Use the Snowflake algorithm to automatically generate a globally unique Id, Long type;
- Primary Key (PRIMARY_KEY): Generate Id through VertexLabel+PrimaryKeyValues, String type;
- Custom (CUSTOMIZE_STRING|CUSTOMIZE_NUMBER): User-defined Id, which is divided into two types: String and Long, and you need to ensure the uniqueness of the Id yourself;
The default Id policy is AUTOMATIC, if the user calls the primaryKeys() method and sets the correct PrimaryKeys, the PRIMARY_KEY policy is automatically enabled. After enabling the PRIMARY_KEY strategy, HugeGraph can implement data deduplication based on PrimaryKeys.
- AUTOMATIC ID Policy
- PRIMARY_KEY ID policy
- CUSTOMIZE_STRING ID Policy
- CUSTOMIZE_NUMBER ID Policy
If users need Vertex deduplication, there are three options:
- Adopt PRIMARY_KEY strategy, automatic overwriting, suitable for batch insertion of large amount of data, users cannot know whether overwriting has occurred
- Adopt AUTOMATIC strategy, read-and-modify, suitable for small data insertion, users can clearly know whether overwriting occurs
- Using the CUSTOMIZE_STRING or CUSTOMIZE_NUMBER strategy, the user guarantees the uniqueness
4. EdgeId policy
The EdgeId of HugeGraph is composed of srcVertexId + edgeLabel + sortKey + tgtVertexId. Among them sortKey is an important concept of HugeGraph.
There are two reasons for adding Edge sortKeyas the unique ID of Edge:
- If there are multiple edges of the same Label between two vertices, they can be sortKeydistinguished by
- For SuperNode nodes, it can be sortKeysorted and truncated by.
Since EdgeId is composed of srcVertexId + edgeLabel + sortKey + tgtVertexId, HugeGraph will automatically overwrite when the same Edge is inserted
multiple times to achieve deduplication. It should be noted that the properties of Edge will also be overwritten in the batch insert mode.
In addition, because HugeGraph’s EdgeId adopts an automatic deduplication strategy, HugeGraph considers that there is only one edge in the case of self-loop (a vertex has an edge pointing to itself). The graph has two edges.
The edges of HugeGraph only support directed edges, and undirected edges can be realized by creating two edges, Out and In.
5. HugeGraph transaction overview
TinkerPop transaction overview
A TinkerPop transaction refers to a unit of work that performs operations on the database. A set of operations within a transaction either succeeds or all fail. For a detailed introduction, please refer to the official documentation of TinkerPop: http://tinkerpop.apache.org/docs/current/reference/#transactions:http://tinkerpop.apache.org/docs/current/reference/#transactions
TinkerPop transaction overview
- open open transaction
- commit commit transaction
- rollback rollback transaction
- close closes the transaction
TinkerPop transaction specification
- The transaction must be explicitly committed before it can take effect (the modification operation can only be seen by the query in this transaction if it is not committed)
- A transaction must be opened before it can be committed or rolled back
- If the transaction setting is automatically turned on, there is no need to explicitly turn it on (the default method), if it is set to be turned on manually, it must be turned on explicitly
- When the transaction is closed, you can set three modes: automatic commit, automatic rollback (default mode), manual (explicit shutdown is prohibited), etc.
- The transaction must be closed after committing or rolling back
- The transaction must be open after the query
- Transactions (non-threaded tx) must be thread-isolated, and multi-threaded operations on the same transaction do not affect each other
For more transaction specification use cases, see: Transaction Test
HugeGraph transaction implementation
- All operations in a transaction either succeed or fail
- A transaction can only read what has been committed by another transaction (Read committed)
- All uncommitted operations can be queried in this transaction, including:
- Adding a vertex can query the vertex
- Delete a vertex to filter out the vertex
- Deleting a vertex can filter out the related edges of the vertex
- Adding an edge can query the edge
- Delete edge can filter out the edge
- Adding/modifying (vertex, edge) attributes can take effect when querying
- Delete (vertex, edge) attributes can take effect at query time
- All uncommitted operations become invalid after the transaction is rolled back, including:
- Adding and deleting vertices and edges
- Addition/modification, deletion of attributes
Example: One transaction cannot read another transaction’s uncommitted content
Principle of transaction realization
- The server internally realizes isolation by binding transactions to threads (ThreadLocal)
- The uncommitted content of this transaction overwrites the old data in chronological order for this transaction to query the latest version of data
- The bottom layer relies on the back-end database to ensure transaction atomicity (for example, the batch interface of Cassandra/RocksDB guarantees atomicity)
Notice
The RESTful API does not expose the transaction interface for the time being
TinkerPop API allows open transactions, which are automatically closed when the request is completed (Gremlin Server forces close)
6.3 - HugeGraph Plugin mechanism and plug-in extension process
Background
- HugeGraph is not only open source and open, but also simple and easy to use. General users can easily add plug-in extension functions without changing the source code.
- HugeGraph supports a variety of built-in storage backends, and also allows users to extend custom backends without changing the existing source code.
- HugeGraph supports full-text search. The full-text search function involves word segmentation in various languages. Currently, there are 8 built-in Chinese word breakers, and it also allows users to expand custom word breakers without changing the existing source code.
Scalable dimension
Currently, the plug-in method provides extensions in the following dimensions:
- backend storage
- serializer
- Custom configuration items
- tokenizer
Plug-in implementation mechanism
- HugeGraph provides a plug-in interface HugeGraphPlugin, which supports plug-in through the Java SPI mechanism
- HugeGraph provides four extension registration functions: registerOptions(), registerBackend(), registerSerializer(),registerAnalyzer()
- The plug-in implementer implements the corresponding Options, Backend, Serializer or Analyzer interface
- The plug-in implementer implements register()the method of the HugeGraphPlugin interface, registers the specific implementation class listed in the above point 3 in this method, and packs it into a jar package
- The plug-in user puts the jar package in the HugeGraph Server installation directory plugins, modifies the relevant configuration items to the plug-in custom value, and restarts to take effect
Plug-in implementation process example
1 Create a new maven project
1.1 Name the project name: hugegraph-plugin-demo
1.2 Add hugegraph-core Jar package dependencies
The details of maven pom.xml are as follows:
2 Realize extended functions
2.1 Extending a custom backend
2.1.1 Implement the interface BackendStoreProvider
- Realizable interfaces:
org.apache.hugegraph.backend.store.BackendStoreProvider - Or inherit an abstract class:
org.apache.hugegraph.backend.store.AbstractBackendStoreProvider
Take the RocksDB backend RocksDBStoreProvider as an example:
2.1.2 Implement interface BackendStore
The BackendStore interface is defined as follows:
2.1.3 Extending custom serializers
The serializer must inherit the abstract class: org.apache.hugegraph.backend.serializer.AbstractSerializer
( implements GraphSerializer, SchemaSerializer) The main interface is defined as follows:
2.1.4 Extend custom configuration items
When adding a custom backend, it may be necessary to add new configuration items. The implementation process mainly includes:
- Add a configuration item container class and implement the interface
org.apache.hugegraph.config.OptionHolder - Provide a singleton method
public static OptionHolder instance(), and call the method when the object is initializedOptionHolder.registerOptions() - Add configuration item declaration, single-value configuration item type is
ConfigOption, multi-value configuration item type isConfigListOption
Take the RocksDB configuration item definition as an example:
2.2 Extend custom tokenizer
The tokenizer needs to implement the interface org.apache.hugegraph.analyzer.Analyzer, take implementing a SpaceAnalyzer space tokenizer as an example.
3. Implement the plug-in interface and register it
The plug-in registration entry is HugeGraphPlugin.register(), the custom plug-in must implement this interface method, and register the extension
items defined above inside it. The interface org.apache.hugegraph.plugin.HugeGraphPlugin is defined as follows:
And HugeGraphPlugin provides 4 static methods for registering extensions:
- registerOptions(String name, String classPath): register configuration items
- registerBackend(String name, String classPath): register backend (BackendStoreProvider)
- registerSerializer(String name, String classPath): register serializer
- registerAnalyzer(String name, String classPath): register tokenizer
The following is an example of registering the SpaceAnalyzer tokenizer:
4. Configure SPI entry
- Make sure the services directory exists: hugegraph-plugin-demo/resources/META-INF/services
- Create a text file in the services directory: org.apache.hugegraph.plugin.HugeGraphPlugin
- The content of the file is as follows: org.apache.hugegraph.plugin.DemoPlugin
5. Make Jar package
Through maven packaging, execute the command in the project directory mvn package, and a Jar package file will be generated in the
target directory. Copy the Jar package to the plugins directory when using it, and restart the service to take effect.
6.4 - HugeGraph Toolchain Local Testing Guide
This guide helps developers run HugeGraph toolchain tests locally.
1. Core Concepts
1.1 Core Dependency: HugeGraph Server
Integration and functional tests of the toolchain depend on HugeGraph Server, including Client, Loader, Hubble, Spark Connector, Tools, and other components.
1.2 Test Types
- Unit Tests: Test individual functions/methods, no external dependencies required
- API Tests (ApiTestSuite): Test API interfaces, requires running HugeGraph Server
- Functional Tests (FuncTestSuite): End-to-end tests, require complete system environment
2. Environment Setup
2.1 System Requirements
- Operating System: Linux / macOS (Windows use WSL2)
- JDK: >= 11, configure
JAVA_HOME - Maven: >= 3.6
- Python: >= 3.11 (only required for Hubble tests)
2.2 Clone Code
3. Deploy Test Environment
Deployment Options
- Script Deployment: Specify a Server commit to reproduce the server version used by CI
- Docker Deployment: Suitable for quick checks; if tests fail, first verify compatibility between the image and Toolchain
For detailed installation instructions, refer to Community Documentation
3.1 Script Deployment
Parameter Description
$COMMIT_ID: Specify Server source code Git Commit ID$DB_DATABASE/$DB_PASS: MySQL database name and password for Loader JDBC tests
Deployment Steps
1. Install HugeGraph Server
- The script starts HTTP and HTTPS instances on ports 8080 and 8443 and configures
admin/paauthentication. - Ensure both ports are available before running it.
2. Install Optional Dependencies
3. Health Check
3.2 Docker Deployment
Note: Docker images may have version lag, use script deployment if encountering compatibility issues
Quick Start
docker-compose Configuration (Optional)
Complete configuration example including Server, MySQL, Hadoop services (requires Docker Compose V2):
Hadoop Configuration Mounts
Create a ./config folder in the same directory as docker-compose.yml to mount Hadoop configuration files. You can skip this step if HDFS testing is not required.
📁 ./config/core-site.xml content:
📁 ./config/hdfs-site.xml content:
Docker Operations
4. Run Tests
Test process for each tool:
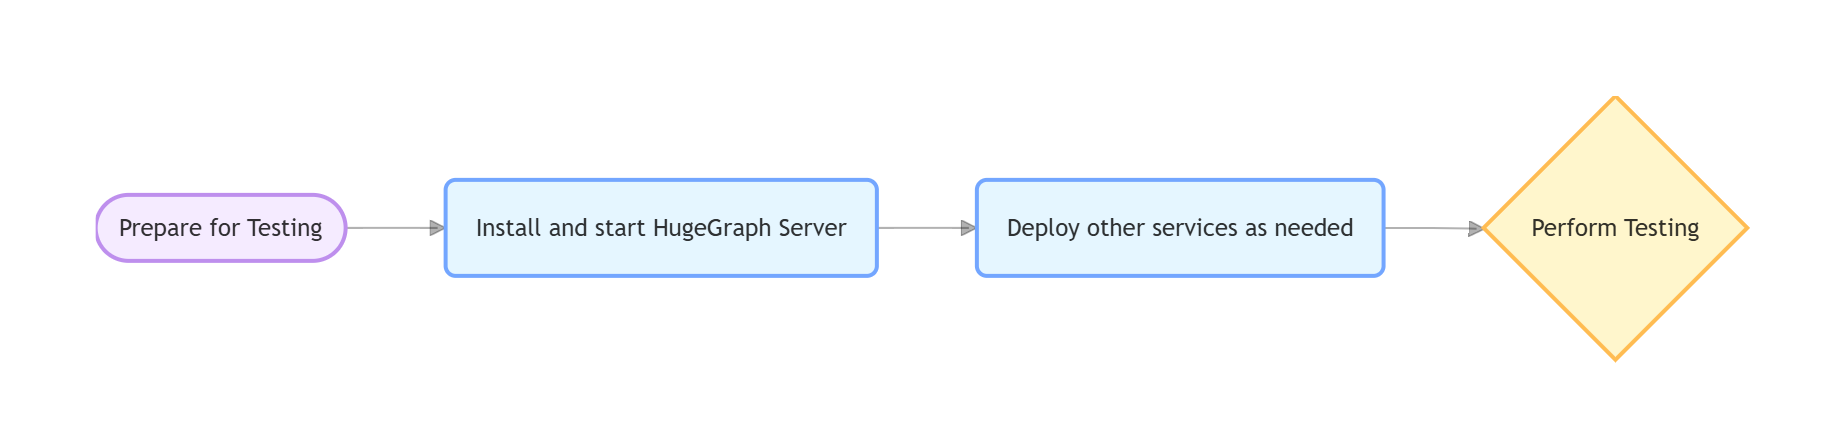
4.1 hugegraph-client
Compile
Dependent Services
Start HugeGraph Server (refer to Section 3)
Server Authentication Configuration
ApiTest requires authentication. No additional configuration is needed when using the script in Section 3.1. For a manually deployed Server, the authentication settings and test credentials must match the test code.
Run Tests
Check Server log if tests fail:
logs/hugegraph-server.log
4.2 hugegraph-loader
Compile
Dependent Services
- Required: HugeGraph Server
- Optional: Hadoop (HDFS tests), MySQL (JDBC tests)
Run Tests
4.3 hugegraph-hubble
Compile
Dependent Services
1. Start Server (refer to Section 3)
2. Python Environment
3. Build and Verify
Run Tests
4.4 hugegraph-spark-connector
Compile
Run Tests
4.5 hugegraph-tools
Compile
Run Tests
5. Common Issues
Service Connection Issues
If Server, MySQL, or Hadoop cannot be reached:
- Confirm services are running (Server must be on port 8080)
- Check port usage:
lsof -i:8080 - Docker check:
docker compose psanddocker compose logs
Configuration Issues
If files cannot be found or parameters are invalid:
- Check environment variables:
echo $COMMIT_ID - Script permissions:
chmod +x hugegraph-*/assembly/travis/*.sh
HDFS Test Failures
- Confirm NameNode/DataNode running normally
- Check Hadoop logs
- Verify HDFS connection:
hdfs dfsadmin -report
JDBC Test Failures
- Confirm MySQL running normally
- Verify database connection:
mysql -u root -p$DB_PASS - Check MySQL logs
6. References
- HugeGraph GitHub Repository: https://github.com/apache/hugegraph
- HugeGraph Toolchain GitHub Repository: https://github.com/apache/hugegraph-toolchain
- HugeGraph Server Documentation: https://hugegraph.apache.org/docs/quickstart/hugegraph/hugegraph-server/
- CI Configuration:
.github/workflows/*-ci.yml - Dependency Installation Scripts:
hugegraph-*/assembly/travis/
6.5 - Backup and Restore
Description
Backup and Restore are functions of backup map and restore map. The data backed up and restored includes metadata (schema) and graph data (vertex and edge).
Backup
Export the metadata and graph data of a graph in the HugeGraph system in JSON format.
Restore
Re-import the data in JSON format exported by Backup to a graph in the HugeGraph system.
Restore has two modes:
- In Restoring mode, the metadata and graph data exported by Backup are restored to the HugeGraph system intact. It can be used for graph backup and recovery, and the general target graph is a new graph (without metadata and graph data). for example:
- System upgrade, first back up the map, then upgrade the system, and finally restore the map to the new system
- Graph migration, from a HugeGraph system, use the Backup function to export the graph, and then use the Restore function to import the graph into another HugeGraph system
- In the Merging mode, the metadata and graph data exported by Backup are imported into another graph that already has metadata or graph data. During the process, the ID of the metadata may change, and the IDs of vertices and edges will also change accordingly.
- Can be used to merge graphs
Instructions
You can use hugegraph-tools to backup and restore the graph.
Backup
This command backs up all the metadata and graph data of the hugegraph graph of http://127.0.0.1 to the data directory.
Backup works fine in all three graph modes
Restore
Restore has two modes: RESTORING and MERGING. Before backup, you must first set the graph mode according to your needs.
Step 1: View and set graph mode
This command is used to view the current graph mode, including: NONE, RESTORING, MERGING.
This command is used to set the graph mode. Before Restore, it can be set to RESTORING or MERGING mode. In the example, it is set to RESTORING.
Step 2: Restore data
This command re-imports all metadata and graph data in the data directory to the hugegraph graph at http://127.0.0.1.
Step 3: Restoring Graph Mode
This command is used to restore the graph mode to NONE.
So far, a complete graph backup and graph recovery process is over.
help
For detailed usage of backup and restore commands, please refer to the hugegraph-tools documentation.
API description for Backup/Restore usage and implementation
Backup
Backup uses the corresponding list(GET) API export of metadata and graph data, and no new API is added.
Restore
Restore uses the corresponding create(POST) API imports for metadata and graph data, and does not add new APIs.
There are two different modes for Restore: Restoring and Merging. In addition, there is a regular mode of NONE (default), the differences are as follows:
- In None mode, the writing of metadata and graph data is normal, please refer to the function description. special:
- ID is not allowed when metadata (schema) is created
- Graph data (vertex) is not allowed to specify an ID when the id strategy is Automatic
- Restoring mode, restoring to a new graph, in particular:
- ID is allowed to be specified when metadata (schema) is created
- Graph data (vertex) allows specifying an ID when the id strategy is Automatic
- Merging mode, merging into a graph with existing metadata and graph data, in particular:
- ID is not allowed when metadata (schema) is created
- Graph data (vertex) allows specifying an ID when the id strategy is Automatic
Normally, the graph mode is None. When you need to restore the graph, you need to temporarily change the graph mode to Restoring mode or Merging mode as needed, and when the Restore is completed, restore the graph mode to None.
The implemented RESTful API for setting graph mode is as follows:
View the schema of a graph. This operation requires administrator privileges
Method & Url
Response Status
Response Body
Legal graph modes include: NONE, RESTORING, MERGING
Set the mode of a graph. ““This operation requires administrator privileges**
Method & Url
Request Body
Legal graph modes include: NONE, RESTORING, MERGING
Response Status
Response Body
6.6 - FAQ
How to choose the back-end storage? RocksDB or distributed storage?
HugeGraph supports multiple deployment modes. Choose based on your data scale and scenario:
- Standalone Mode: Server + RocksDB, suitable for development/testing and small to medium-scale data (≤ 2 TB)
- Distributed Mode: HugeGraph-PD + HugeGraph-Store (HStore), for deployments that require horizontal scaling and multiple replicas, supporting data scales up to 1 PB
Version 1.7.0 supports RocksDB, HStore, HBase, and Memory. Legacy backends such as Cassandra, ScyllaDB, MySQL, and PostgreSQL require version 1.5.x or earlier.
Prompt when starting the service:
xxx (core dumped) xxxFirst confirm that the JDK version is Java 11 or later. HugeGraph 1.7.0 no longer supports Java 8.
The service is started successfully, but there is a prompt similar to “Unable to connect to the backend or the connection is not open” when operating the graph
Persistent local backends such as RocksDB and HBase must be initialized with
init-storebefore their first startup. HStore is managed by PD and Store and does not use this script.Do all backends need to be executed before use init-store, and can the serialization options be filled in at will?
Memory and HStore do not use
init-store; persistent local backends such as RocksDB and HBase must be initialized before first use. The serializer must match the backend—for example, RocksDB usesbinary.Execution
init-storeerror:Exception in thread "main" java.lang.UnsatisfiedLinkError: /tmp/librocksdbjni3226083071221514754.so: /usr/lib64/libstdc++.so.6: version `GLIBCXX_3.4.10' not found (required by /tmp/librocksdbjni3226083071221514754.so)RocksDB requires gcc 4.3.0 (GLIBCXX_3.4.10) and above
The
bindirectory containsstart-hugegraph.sh,start-restserver.shandstart-gremlinserver.sh. These scripts seem to be related to startup. Which one should be used?Current release packages retain only
start-hugegraph.shas the Server startup script. GremlinServer and the REST Server run in the same process.Two graphs are configured, the names are
hugegraphandhugegraph1, and the command to start the service isstart-hugegraph.sh. Is only the hugegraph graph opened?The script name is unrelated to the graph name. To load multiple local graphs from the
graphsdirectory, setgraph.load_from_local_config=trueinrest-server.properties; its default value in the source code isfalse.After the service starts successfully, garbled characters are returned when using
curlto query all verticesThe batch vertices/edges returned by the server are compressed (gzip), and can be redirected to
gunzipfor decompression (curl http://example | gunzip), or can be sent with thepostmanofFirefoxor therestletplug-in of Chrome browser. request, the response data will be decompressed automatically.When using the vertex Id to query the vertex through the
RESTful API, it returns empty, but the vertex does existCheck the type of the vertex ID. If it is a string type, the “id” part of the API URL needs to be enclosed in double quotes, while for numeric types, it is not necessary to enclose the ID in quotes.
Vertex Id has been double quoted as required, but querying the vertex via the RESTful API still returns empty
Check whether the vertex id contains
+,space,/,?,%,&, and=reserved characters of theseURLs. If they exist, they need to be encoded. The following table gives the coded values:Timeout when querying vertices or edges of a certain category (
query by label)Since the amount of data belonging to a certain label may be relatively large, please add a limit limit.
It is possible to operate the graph through the
RESTful API, but when sendingGremlinstatements, an error is reported:Request Failed(500)It may be that the configuration of
GremlinServeris wrong, check whether thehostandportofgremlin-server.yamlmatch thegremlinserver.urlofrest-server.properties, if they do not match, modify them, and then Restart the service.When using
Loaderto import data, aSocket Timeoutexception occurs, and thenLoaderis interruptedContinuously importing data will put too much pressure on the
Server, which will cause some requests to time out. The pressure onServercan be appropriately relieved by adjusting the parameters ofLoader(such as: number of retries, retry interval, error tolerance, etc.), and reduce the frequency of this problem.How to delete all data from a graph
An administrator can call
DELETE /graphspaces/{graphspace}/graphs/{graph}/clear. The request must include theconfirm_messagerequired by the source code; see the Graph API for the exact format. This operation removes schemas, vertices, edges, and indexes.The database has been cleared and
init-storehas been executed, but when trying to add a schema, the prompt “xxx has existed” appeared.There is a cache in the
HugeGraphServer, and it is necessary to restart theServerwhen the database is cleared, otherwise the residual cache will be inconsistent.An error is reported during the process of inserting vertices or edges:
Id max length is 128, but got xxx {yyy}orBig id max length is 32768, but got xxxIn order to ensure query performance, the current backend storage limits the length of the id column. The vertex id cannot exceed 128 bytes, the edge id cannot exceed 32768 bytes, and the index id cannot exceed 128 bytes.
Is there support for nested attributes, and if not, are there any alternatives?
Nested attributes are currently not supported. Alternative: Nested attributes can be taken out as individual vertices and connected with edges.
Can an
EdgeLabelconnect multiple pairs ofVertexLabel, such as “investment” relationship, which can be “individual” investing in “enterprise”, or “enterprise” investing in “enterprise”?An
EdgeLabeldoes not support connecting multiple pairs ofVertexLabels, users need to split theEdgeLabelinto finer details, such as: “personal investment”, “enterprise investment”.Prompt
HTTP 415 Unsupported Media Typewhen sending a request throughRestAPIContent-Type: application/jsonneeds to be specified in the request header
Other issues can be searched in the issue area of the corresponding project, such as Server-Issues / Loader Issues
6.7 - Security Report
Reporting New Security Problems with Apache HugeGraph
Adhering to the specifications of ASF, the HugeGraph community maintains a highly proactive and open attitude towards addressing security issues in the remediation projects.
We strongly recommend that users first report such issues to our dedicated security email list, with detailed procedures specified in the ASF SEC code of conduct.
Please note that the security email group is reserved for reporting undisclosed security vulnerabilities and following up on the vulnerability resolution process.
Regular software Bug/Error reports should be directed to Github Issue/Discussion or the HugeGraph-Dev email group. Emails sent to the security list that are unrelated to security issues will be ignored.
The independent security email (group) address is: security@hugegraph.apache.org
The general process for handling security vulnerabilities is as follows:
- The reporter privately reports the vulnerability to the Apache HugeGraph SEC email group (including as much information as possible, such as reproducible versions, relevant descriptions, reproduction methods, and the scope of impact)
- The HugeGraph project security team collaborates privately with the reporter to discuss the vulnerability resolution (after preliminary confirmation, a
CVEnumber can be requested for registration) - The project creates a new version of the software package affected by the vulnerability to provide a fix
- At an appropriate time, a general description of the vulnerability and how to apply the fix will be publicly disclosed (in compliance with ASF standards, the announcement should not disclose sensitive information such as reproduction details)
- Official CVE release and related procedures follow the ASF-SEC page
Known Security Vulnerabilities (CVEs)
HugeGraph main project (Server/PD/Store)
- CVE-2024-27348: HugeGraph-Server - Command execution in gremlin
- CVE-2024-27349: HugeGraph-Server - Bypass whitelist in Auth mode
HugeGraph-Toolchain project (Hubble/Loader/Client/Tools/..)
- CVE-2024-27347: HugeGraph-Hubble - SSRF in Hubble connection page
7 - Query Languages
HugeGraph supports Gremlin and Cypher. This section mainly covers Gremlin; see the Cypher API for the Cypher HTTP interface.
7.1 - HugeGraph Gremlin
Overview
HugeGraph supports Gremlin, a graph traversal query language of Apache TinkerPop3. While SQL is a query language for relational databases, Gremlin is a general-purpose query language for graph databases. Gremlin can be used to create entities (Vertex and Edge) of a graph, modify the properties of entities, delete entities, as well as perform graph queries.
Gremlin can be used to create entities (Vertex and Edge) of a graph, modify the properties of entities, and delete entities. More importantly, it can be used to perform graph querying and analysis operations.
TinkerPop Features
HugeGraph implements the TinkerPop framework, but not all TinkerPop features are implemented.
The table below lists the support status of various TinkerPop features in HugeGraph:
Graph Features
| Name | Description | Support |
|---|---|---|
| Computer | Determines if the {@code Graph} implementation supports {@link GraphComputer} based processing | false |
| Transactions | Determines if the {@code Graph} implementations supports transactions. | true |
| Persistence | Determines if the {@code Graph} implementation supports persisting it’s contents natively to disk.This feature does not refer to every graph’s ability to write to disk via the Gremlin IO packages(.e.g. GraphML), unless the graph natively persists to disk via those options somehow. For example,TinkerGraph does not support this feature as it is a pure in-sideEffects graph. | true |
| ThreadedTransactions | Determines if the {@code Graph} implementation supports threaded transactions which allow a transaction be executed across multiple threads via {@link Transaction#createThreadedTx()}. | false |
| ConcurrentAccess | Determines if the {@code Graph} implementation supports more than one connection to the same instance at the same time. For example, Neo4j embedded does not support this feature because concurrent access to the same database files by multiple instances is not possible. However, Neo4j HA could support this feature as each new {@code Graph} instance coordinates with the Neo4j cluster allowing multiple instances to operate on the same database. | false |
Vertex Features
| Name | Description | Support |
|---|---|---|
| UserSuppliedIds | Determines if an {@link Element} can have a user defined identifier. Implementation that do not support this feature will be expected to auto-generate unique identifiers. In other words, if the {@link Graph} allows {@code graph.addVertex(id,x)} to work and thus set the identifier of the newly added {@link Vertex} to the value of {@code x} then this feature should return true. In this case, {@code x} is assumed to be an identifier data type that the {@link Graph} will accept. | false |
| NumericIds | Determines if an {@link Element} has numeric identifiers as their internal representation. In other words,if the value returned from {@link Element#id()} is a numeric value then this method should be return {@code true}. Note that this feature is most generally used for determining the appropriate tests to execute in the Gremlin Test Suite. | false |
| StringIds | Determines if an {@link Element} has string identifiers as their internal representation. In other words, if the value returned from {@link Element#id()} is a string value then this method should be return {@code true}. Note that this feature is most generally used for determining the appropriate tests to execute in the Gremlin Test Suite. | false |
| UuidIds | Determines if an {@link Element} has UUID identifiers as their internal representation. In other words,if the value returned from {@link Element#id()} is a {@link UUID} value then this method should be return {@code true}.Note that this feature is most generally used for determining the appropriate tests to execute in the Gremlin Test Suite. | false |
| CustomIds | Determines if an {@link Element} has a specific custom object as their internal representation.In other words, if the value returned from {@link Element#id()} is a type defined by the graph implementations, such as OrientDB’s {@code Rid}, then this method should be return {@code true}.Note that this feature is most generally used for determining the appropriate tests to execute in the Gremlin Test Suite. | false |
| AnyIds | Determines if an {@link Element} any Java object is a suitable identifier. TinkerGraph is a good example of a {@link Graph} that can support this feature, as it can use any {@link Object} as a value for the identifier. Note that this feature is most generally used for determining the appropriate tests to execute in the Gremlin Test Suite. This setting should only return {@code true} if {@link #supportsUserSuppliedIds()} is {@code true}. | false |
| AddProperty | Determines if an {@link Element} allows properties to be added. This feature is set independently from supporting “data types” and refers to support of calls to {@link Element#property(String, Object)}. | true |
| RemoveProperty | Determines if an {@link Element} allows properties to be removed. | true |
| AddVertices | Determines if a {@link Vertex} can be added to the {@code Graph}. | true |
| MultiProperties | Determines if a {@link Vertex} can support multiple properties with the same key. | false |
| DuplicateMultiProperties | Determines if a {@link Vertex} can support non-unique values on the same key. For this value to be {@code true}, then {@link #supportsMetaProperties()} must also return true. By default this method, just returns what {@link #supportsMultiProperties()} returns. | false |
| MetaProperties | Determines if a {@link Vertex} can support properties on vertex properties. It is assumed that a graph will support all the same data types for meta-properties that are supported for regular properties. | false |
| RemoveVertices | Determines if a {@link Vertex} can be removed from the {@code Graph}. | true |
Edge Features
| Name | Description | Support |
|---|---|---|
| UserSuppliedIds | Determines if an {@link Element} can have a user defined identifier. Implementation that do not support this feature will be expected to auto-generate unique identifiers. In other words, if the {@link Graph} allows {@code graph.addVertex(id,x)} to work and thus set the identifier of the newly added {@link Vertex} to the value of {@code x} then this feature should return true. In this case, {@code x} is assumed to be an identifier data type that the {@link Graph} will accept. | false |
| NumericIds | Determines if an {@link Element} has numeric identifiers as their internal representation. In other words,if the value returned from {@link Element#id()} is a numeric value then this method should be return {@code true}. Note that this feature is most generally used for determining the appropriate tests to execute in the Gremlin Test Suite. | false |
| StringIds | Determines if an {@link Element} has string identifiers as their internal representation. In other words, if the value returned from {@link Element#id()} is a string value then this method should be return {@code true}. Note that this feature is most generally used for determining the appropriate tests to execute in the Gremlin Test Suite. | false |
| UuidIds | Determines if an {@link Element} has UUID identifiers as their internal representation. In other words,if the value returned from {@link Element#id()} is a {@link UUID} value then this method should be return {@code true}.Note that this feature is most generally used for determining the appropriate tests to execute in the Gremlin Test Suite. | false |
| CustomIds | Determines if an {@link Element} has a specific custom object as their internal representation.In other words, if the value returned from {@link Element#id()} is a type defined by the graph implementations, such as OrientDB’s {@code Rid}, then this method should be return {@code true}.Note that this feature is most generally used for determining the appropriate tests to execute in the Gremlin Test Suite. | false |
| AnyIds | Determines if an {@link Element} any Java object is a suitable identifier. TinkerGraph is a good example of a {@link Graph} that can support this feature, as it can use any {@link Object} as a value for the identifier. Note that this feature is most generally used for determining the appropriate tests to execute in the Gremlin Test Suite. This setting should only return {@code true} if {@link #supportsUserSuppliedIds()} is {@code true}. | false |
| AddProperty | Determines if an {@link Element} allows properties to be added. This feature is set independently from supporting “data types” and refers to support of calls to {@link Element#property(String, Object)}. | true |
| RemoveProperty | Determines if an {@link Element} allows properties to be removed. | true |
| AddEdges | Determines if an {@link Edge} can be added to a {@code Vertex}. | true |
| RemoveEdges | Determines if an {@link Edge} can be removed from a {@code Vertex}. | true |
Data Type Features
| Name | Description | Support |
|---|---|---|
| BooleanValues | true | |
| ByteValues | true | |
| DoubleValues | true | |
| FloatValues | true | |
| IntegerValues | true | |
| LongValues | true | |
| MapValues | Supports setting of a {@code Map} value. The assumption is that the {@code Map} can contain arbitrary serializable values that may or may not be defined as a feature itself | false |
| MixedListValues | Supports setting of a {@code List} value. The assumption is that the {@code List} can contain arbitrary serializable values that may or may not be defined as a feature itself. As this{@code List} is “mixed” it does not need to contain objects of the same type. | false |
| BooleanArrayValues | false | |
| ByteArrayValues | true | |
| DoubleArrayValues | false | |
| FloatArrayValues | false | |
| IntegerArrayValues | false | |
| LongArrayValues | false | |
| SerializableValues | false | |
| StringArrayValues | false | |
| StringValues | true | |
| UniformListValues | Supports setting of a {@code List} value. The assumption is that the {@code List} can contain arbitrary serializable values that may or may not be defined as a feature itself. As this{@code List} is “uniform” it must contain objects of the same type. | false |
Gremlin Steps
HugeGraph supports all steps of Gremlin. For complete reference information about Gremlin, please refer to the Gremlin official website.
| Step | Description | Documentation |
|---|---|---|
| addE | Add an edge between two vertices. | addE step |
| addV | add vertices to graph. | addV step |
| and | Make sure all traversals return values. | and step |
| as | Step modulator for assigning variables to the step’s output. | as step |
| by | Step Modulators used in conjunction with group and order. | by step |
| coalesce | Returns the first traversal that returns a result. | coalesce step |
| constant | Returns a constant value. Used in conjunction with coalesce. | constant step |
| count | Returns a count from the traversal. | count step |
| dedup | Returns values with duplicates removed. | dedup step |
| drop | Discards a value (vertex/edge). | drop step |
| fold | Acts as a barrier for computing aggregated values from results. | fold step |
| group | Groups values based on specified labels. | group step |
| has | Used to filter properties, vertices, and edges. Supports hasLabel, hasId, hasNot, and has variants. | has step |
| inject | Injects values into the stream. | inject step |
| is | Used to filter by a Boolean expression. | is step |
| limit | Used to limit the number of items in a traversal. | limit step |
| local | Locally wraps a part of a traversal, similar to a subquery. | local step |
| not | Used to generate the negation result of a filter. | not step |
| optional | Returns the result of a specified traversal if it generates any results, otherwise returns the calling element. | optional step |
| or | Ensures that at least one traversal returns a value. | or step |
| order | Returns results in the specified order. | order step |
| path | Returns the full path of the traversal. | path step |
| project | Projects properties as a map. | project step |
| properties | Returns properties with specified labels. | properties step |
| range | Filters based on a specified range of values. | range step |
| repeat | Repeats a step a specified number of times. Used for looping. | repeat step |
| sample | Used to sample results returned by the traversal. | sample step |
| select | Used to project the results returned by the traversal. | select step |
| store | This step is used fo.r non-blocking aggregation of results returned by traversal | store step |
| tree | Aggregate the paths in vertices into a tree. | tree step |
| unfold | Unfolds an iterator as a step. | unfold step |
| union | Merge the results returned by multiple traversals. | union step |
| V | These are the steps required for traversing between vertices and edges: V, E, out, in, both, outE, inE, bothE, outV, inV, bothV, and otherV. | order step |
| where | Used to filter the results returned by a traversal. Supports eq, neq, lt, lte, gt, gte, and between operators. | where step |
7.2 - HugeGraph Examples
1 Overview
This example uses the TitanDB Getting Started guide as a template to demonstrate how to use HugeGraph. By comparing HugeGraph and TitanDB, you can understand the differences between them.
1.1 Similarities and Differences between HugeGraph and TitanDB
Both HugeGraph and TitanDB are graph databases based on the Apache TinkerPop3 framework. They both support the Gremlin graph query language and share many similarities in terms of usage and interfaces. However, HugeGraph is a completely new design and development, characterized by its clear code structure, richer features, and more user-friendly interfaces.
Compared to TitanDB, HugeGraph’s main features are as follows:
- HugeGraph currently offers a comprehensive suite of tools, including HugeGraph-API, HugeGraph-Client, HugeGraph-Loader, HugeGraph-Studio, and HugeGraph-Spark. These components facilitate system integration, data loading, visual graph querying, Spark connectivity, and other functionalities.
- HugeGraph incorporates the concepts of Server and Client, allowing third-party systems to connect via multiple methods such as JAR references, clients, and APIs. In contrast, TitanDB only supports connections via JAR references.
- HugeGraph requires explicit schema definition, and all insertions and queries must pass strict schema validation. Implicit schema creation is not supported at the moment.
- HugeGraph makes full use of the characteristics of the underlying storage system to achieve efficient data access, whereas TitanDB ignores the differences of the backend with a unified Kv structure.
- HugeGraph’s update operations can be performed on-demand (e.g., updating a specific attribute), offering better performance. TitanDB uses a read-and-update approach for updates.
- Both VertexId and EdgeId in HugeGraph support concatenation, allowing for automatic deduplication and better query performance. In TitanDB, all IDs are auto-generated and require indexing for queries.
1.2 Character Relationship Graph
This example uses the Property Graph Model to describe the relationships between characters in Greek mythology, also known as the character relationship graph. The specific relationships are shown in the diagram below.
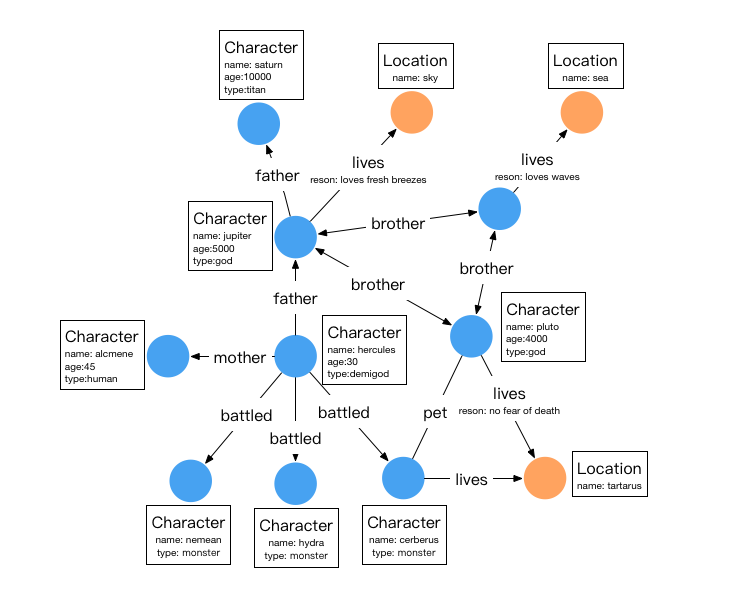
In the diagram, circular nodes represent entities (Vertices), arrows represent relationships (Edges), and the content in the boxes represents attributes.
There are two types of vertices in this graph: characters and locations, as shown in the table below:
| Name | Type | Attributes |
|---|---|---|
| character | vertex | name,age,type |
| location | vertex | name |
There are six types of relationships: father, mother, brother, battled, lives, and pet. The details of these relationships are as follows:
| Name | Type | Source Vertex Label | Target Vertex Label | Attributes |
|---|---|---|---|---|
| father | edge | character | character | - |
| mother | edge | character | character | - |
| brother | edge | character | character | - |
| pet | edge | character | character | - |
| lives | edge | character | location | reason |
In HugeGraph, each edge label can only act on one pair of source and target vertex labels. In other words, if a relationship called “father” is defined in the graph to connect character to character, then “father” cannot be used to connect to other vertex labels.
Therefore, in this example, the original TitanDB’s monster, god, human, and demigod are all represented using the same vertex label: character in HugeGraph, with an additional type attribute to indicate the type of character. The edge labels remain consistent with the original TitanDB. Of course, to satisfy the edge label constraints, adjustments can be made to the name of the edge label.
2 Graph Schema and Data Ingest Examples
HugeGraph requires explicit schema creation, which involves creating PropertyKeys, VertexLabels, and EdgeLabels in sequence. If indexing is needed, IndexLabels must also be created.
2.1 Graph Schema
2.2 Graph Data
2.3 Indices
HugeGraph by default automatically generates IDs. However, if a user specifies the primaryKeys field list for a VertexLabel through primaryKeys, the ID strategy for that VertexLabel will automatically switch to the primaryKeys strategy. Once the primaryKeys strategy is enabled, HugeGraph generates VertexId by concatenating vertexLabel+primaryKeys, which allows for automatic deduplication. Additionally, there is no need to create extra indexes to use the properties in primaryKeys for fast querying. For example, both “character” and “location” have the primaryKeys("name") attribute, so without creating additional indexes, vertices can be queried using g.V().hasLabel('character') .has('name','hercules').
3 Graph Traversal Examples
3.1 Traversal Query
1. Find the grandfather of hercules
It can also be done using the repeat method:
2. Find the name of Hercules’s father
3. Find the characters with age > 100
4. Find who are pluto’s cohabitants
5. Find pluto can’t be his own cohabitant
6. Pluto’s Brothers
It is recommended to use HugeGraph-Hubble to execute the above code visually. Additionally, the code can be executed through various other methods such as HugeGraph-Client, HugeGraph-Api, GremlinConsole, and GremlinDriver.
3.2 Summary
HugeGraph currently supports Gremlin syntax, and users can implement various query requirements through Gremlin / REST-API.
8 - PERFORMANCE
8.1 - HugeGraph BenchMark Performance
Note:
The current performance metrics are based on an earlier version. The latest version has significant improvements in both performance and functionality. We encourage you to refer to the most recent release featuring autonomous distributed storage and enhanced computational push down capabilities. Alternatively, you may wait for the community to update the data with these enhancements.
1 Test environment
1.1 Hardware information
| CPU | Memory | 网卡 | 磁盘 |
|---|---|---|---|
| 48 Intel(R) Xeon(R) CPU E5-2650 v4 @ 2.20GHz | 128G | 10000Mbps | 750GB SSD |
1.2 Software information
1.2.1 Test cases
Testing is done using the graphdb-benchmark, a benchmark suite for graph databases. This benchmark suite mainly consists of four types of tests:
- Massive Insertion, which involves batch insertion of vertices and edges, with a certain number of vertices or edges being submitted at once.
- Single Insertion, which involves the immediate insertion of each vertex or edge, one at a time.
- Query, which mainly includes the basic query operations of the graph database:
- Find Neighbors, which queries the neighbors of all vertices.
- Find Adjacent Nodes, which queries the adjacent vertices of all edges.
- Find the Shortest Path, which queries the shortest path from the first vertex to 100 random vertices.
- Clustering, which is a community detection algorithm based on the Louvain Method.
1.2.2 Test dataset
Tests are conducted using both synthetic and real data.
MIW, SIW, and QW use SNAP datasets:
CW uses synthetic data generated by the LFR-Benchmark generator.
The size of the datasets used in this test is not mentioned.
| Name | Number of Vertices | Number of Edges | File Size |
|---|---|---|---|
| email-enron.txt | 36,691 | 367,661 | 4MB |
| com-youtube.ungraph.txt | 1,157,806 | 2,987,624 | 38.7MB |
| amazon0601.txt | 403,393 | 3,387,388 | 47.9MB |
| com-lj.ungraph.txt | 3997961 | 34681189 | 479MB |
1.3 Service configuration
HugeGraph version: 0.5.6, RestServer and Gremlin Server and backends are on the same server
- RocksDB version: rocksdbjni-5.8.6
Titan version: 0.5.4, using thrift+Cassandra mode
- Cassandra version: cassandra-3.10, commit-log and data use SSD together
Neo4j version: 2.0.1
The Titan version adapted by graphdb-benchmark is 0.5.4.
2 Test results
2.1 Batch insertion performance
| Backend | email-enron(30w) | amazon0601(300w) | com-youtube.ungraph(300w) | com-lj.ungraph(3000w) |
|---|---|---|---|---|
| HugeGraph | 0.629 | 5.711 | 5.243 | 67.033 |
| Titan | 10.15 | 108.569 | 150.266 | 1217.944 |
| Neo4j | 3.884 | 18.938 | 24.890 | 281.537 |
Instructions
- The data scale is in the table header in terms of edges
- The data in the table is the time for batch insertion, in seconds
- For example, HugeGraph(RocksDB) spent 5.711 seconds to insert 3 million edges of the amazon0601 dataset.
Conclusion
- The performance of batch insertion: HugeGraph(RocksDB) > Neo4j > Titan(thrift+Cassandra)
2.2 Traversal performance
2.2.1 Explanation of terms
- FN(Find Neighbor): Traverse all vertices, find the adjacent edges based on each vertex, and use the edges and vertices to find the other vertices adjacent to the original vertex.
- FA(Find Adjacent): Traverse all edges, get the source vertex and target vertex based on each edge.
2.2.2 FN performance
| Backend | email-enron(3.6w) | amazon0601(40w) | com-youtube.ungraph(120w) | com-lj.ungraph(400w) |
|---|---|---|---|---|
| HugeGraph | 4.072 | 45.118 | 66.006 | 609.083 |
| Titan | 8.084 | 92.507 | 184.543 | 1099.371 |
| Neo4j | 2.424 | 10.537 | 11.609 | 106.919 |
Instructions
- The data in the table header “()” represents the data scale, in terms of vertices.
- The data in the table represents the time spent traversing vertices in seconds.
- For example, HugeGraph uses the RocksDB backend to traverse all vertices in amazon0601, and search for adjacent edges and another vertex, which takes a total of 45.118 seconds.
2.2.3 FA performance
| Backend | email-enron(30w) | amazon0601(300w) | com-youtube.ungraph(300w) | com-lj.ungraph(3000w) |
|---|---|---|---|---|
| HugeGraph | 1.540 | 10.764 | 11.243 | 151.271 |
| Titan | 7.361 | 93.344 | 169.218 | 1085.235 |
| Neo4j | 1.673 | 4.775 | 4.284 | 40.507 |
Explanation
- The data size in the header “()” is based on the number of vertices.
- The data in the table is the time it takes to traverse the vertices in seconds.
- For example, HugeGraph with RocksDB backend traverses all vertices in the amazon0601 dataset, and it looks up adjacent edges and other vertices, taking a total of 45.118 seconds.
Conclusion
- Traversal performance: Neo4j > HugeGraph(RocksDB) > Titan(thrift+Cassandra)
2.3 Performance of Common Graph Analysis Methods in HugeGraph
Terminology Explanation
- FS (Find Shortest Path): finding the shortest path between two vertices
- K-neighbor: all vertices that can be reached by traversing K hops (including 1, 2, 3…(K-1) hops) from the starting vertex
- K-out: all vertices that can be reached by traversing exactly K out-edges from the starting vertex.
FS performance
| Backend | email-enron(30w) | amazon0601(300w) | com-youtube.ungraph(300w) | com-lj.ungraph(3000w) |
|---|---|---|---|---|
| HugeGraph | 0.494 | 0.103 | 3.364 | 8.155 |
| Titan | 11.818 | 0.239 | 377.709 | 575.678 |
| Neo4j | 1.719 | 1.800 | 1.956 | 8.530 |
Explanation
- The data in the header “()” represents the data scale in terms of edges
- The data in the table is the time it takes to find the shortest path from the first vertex to 100 randomly selected vertices in seconds
- For example, HugeGraph using the RocksDB backend to find the shortest path from the first vertex to 100 randomly selected vertices in the amazon0601 graph took a total of 0.103s.
Conclusion
- In scenarios with small data size or few vertex relationships, HugeGraph outperforms Neo4j and Titan.
- As the data size increases and the degree of vertex association increases, the performance of HugeGraph and Neo4j tends to be similar, both far exceeding Titan.
K-neighbor Performance
| Vertex | Depth | Degree 1 | Degree 2 | Degree 3 | Degree 4 | Degree 5 | Degree 6 |
|---|---|---|---|---|---|---|---|
| v1 | Time | 0.031s | 0.033s | 0.048s | 0.500s | 11.27s | OOM |
| v111 | Time | 0.027s | 0.034s | 0.115s | 1.36s | OOM | – |
| v1111 | Time | 0.039s | 0.027s | 0.052s | 0.511s | 10.96s | OOM |
Explanation
- HugeGraph-Server’s JVM memory is set to 32GB and may experience OOM when the data is too large.
K-out performance
| Vertex | Depth | 1st Degree | 2nd Degree | 3rd Degree | 4th Degree | 5th Degree | 6th Degree |
|---|---|---|---|---|---|---|---|
| v1 | Time | 0.054s | 0.057s | 0.109s | 0.526s | 3.77s | OOM |
| Degree | 10 | 133 | 2453 | 50,830 | 1,128,688 | ||
| v111 | Time | 0.032s | 0.042s | 0.136s | 1.25s | 20.62s | OOM |
| Degree | 10 | 211 | 4944 | 113150 | 2,629,970 | ||
| v1111 | Time | 0.039s | 0.045s | 0.053s | 1.10s | 2.92s | OOM |
| Degree | 10 | 140 | 2555 | 50825 | 1,070,230 |
Explanation
- The JVM memory of HugeGraph-Server is set to 32GB, and OOM may occur when the data is too large.
Conclusion
- In the FS scenario, HugeGraph outperforms Neo4j and Titan in terms of performance.
- In the K-neighbor and K-out scenarios, HugeGraph can achieve results returned within seconds within 5 degrees.
2.4 Comprehensive Performance Test - CW
| Database | Size 1000 | Size 5000 | Size 10000 | Size 20000 |
|---|---|---|---|---|
| HugeGraph(core) | 20.804 | 242.099 | 744.780 | 1700.547 |
| Titan | 45.790 | 820.633 | 2652.235 | 9568.623 |
| Neo4j | 5.913 | 50.267 | 142.354 | 460.880 |
Explanation
- The “scale” is based on the number of vertices.
- The data in the table is the time required to complete community discovery in seconds. For example, if HugeGraph uses the RocksDB backend and operates on a dataset of 10,000 vertices, and the community aggregation is no longer changing, it takes 744.780 seconds.
- The CW test is a comprehensive evaluation of CRUD operations.
- In this test, HugeGraph, like Titan, did not use the client and directly operated on the core.
Conclusion
- Performance of community detection algorithm: Neo4j > HugeGraph > Titan
8.2 - HugeGraph-API Performance
The HugeGraph API performance test mainly tests HugeGraph-Server’s ability to concurrently process RESTful API requests, including:
- Single insertion of vertices/edges
- Batch insertion of vertices/edges
- Vertex/Edge Queries
For the performance test of the RESTful API of each release version of HugeGraph, please refer to:
Updates coming soon, stay tuned!
8.2.1 - v0.5.6 Stand-alone(RocksDB)
Note:
The current performance metrics are based on an earlier version. The latest version has significant improvements in both performance and functionality. We encourage you to refer to the most recent release featuring autonomous distributed storage and enhanced computational push down capabilities. Alternatively, you may wait for the community to update the data with these enhancements.
1 Test environment
Compressed machine information:
| CPU | Memory | 网卡 | 磁盘 |
|---|---|---|---|
| 48 Intel(R) Xeon(R) CPU E5-2650 v4 @ 2.20GHz | 128G | 10000Mbps | 750GB SSD,2.7T HDD |
- Information about the machine used to generate loads: configured the same as the machine that is being tested under load.
- Testing tool: Apache JMeter 2.5.1
Note: The load-generating machine and the machine under test are located in the same local network.
2 Test description
2.1 Definition of terms (the unit of time is ms)
- Samples: The total number of threads completed in the current scenario.
- Average: The average response time.
- Median: The statistical median of the response time.
- 90% Line: The response time below which 90% of all threads fall.
- Min: The minimum response time.
- Max: The maximum response time.
- Error: The error rate.
- Throughput: The number of requests processed per unit of time.
- KB/sec: Throughput measured in terms of data transferred per second.
2.2 Underlying storage
RocksDB is used for backend storage, HugeGraph and RocksDB are both started on the same machine, and the configuration files related to the server remain as default except for the modification of the host and port.
3 Summary of performance results
- The speed of inserting a single vertex and edge in HugeGraph is about 1w per second
- The batch insertion speed of vertices and edges is much faster than the single insertion speed
- The concurrency of querying vertices and edges by id can reach more than 13000, and the average delay of requests is less than 50ms
4 Test results and analysis
4.1 batch insertion
4.1.1 Upper limit stress testing
Test methods
The upper limit of stress testing is to continuously increase the concurrency and test whether the server can still provide services normally.
Stress Parameters
Duration: 5 minutes
Maximum insertion speed for vertices:
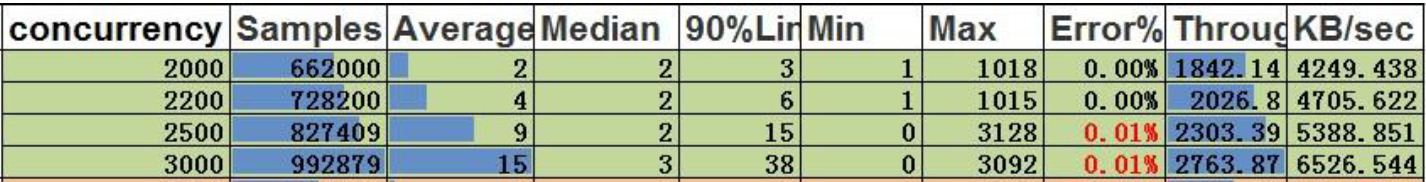
in conclusion:
- With a concurrency of 2200, the throughput for vertices is 2026.8. This means that the system can process data at a rate of 405360 per second (2026.8 * 200).
Maximum insertion speed for edges
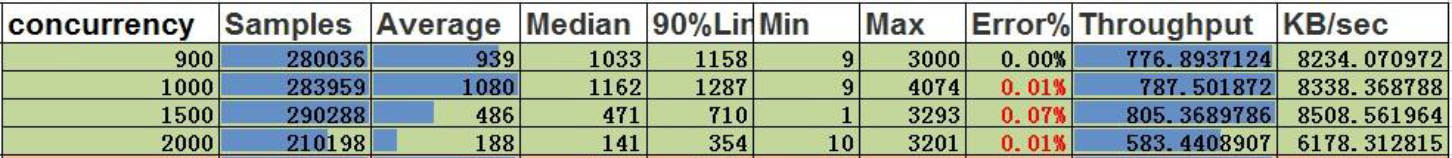
Conclusion:
- With a concurrency of 900, the throughput for edges is 776.9. This means that the system can process data at a rate of 388450 per second (776.9 * 500).
4.2 Single insertion
4.2.1 Stress limit testing
Test Methods
Stress limit testing is a process of continuously increasing the concurrency level to test the upper limit of the server’s ability to provide normal service.
Stress parameters
- Duration: 5 minutes.
- Service exception indicator: Error rate greater than 0.00%.
Single vertex insertion
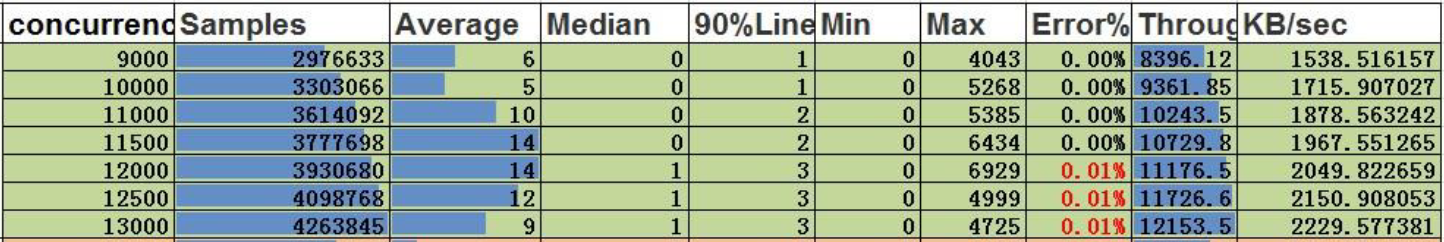
Conclusion:
- With a concurrency of 11500, the throughput is 10730. This means that the system can handle a single concurrent insertion of vertices at a concurrency level of 11500.
Single edge insertion
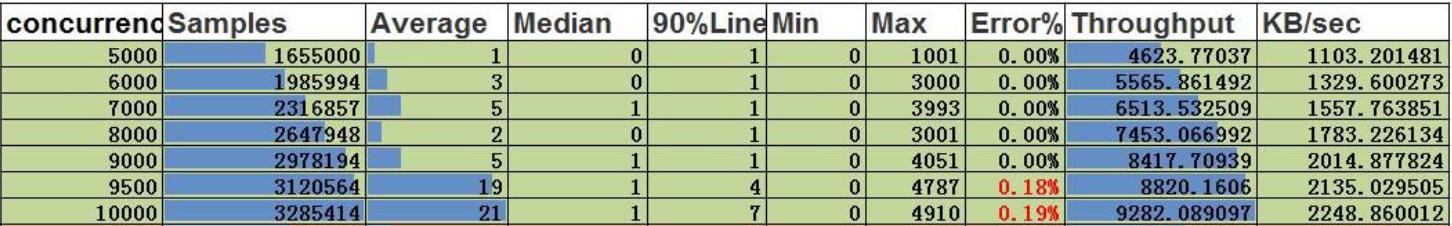
Conclusion:
- With a concurrency of 9000, the throughput is 8418. This means that the system can handle a single concurrent insertion of edges at a concurrency level of 9000.
4.3 Search by ID
4.3.1 Stress test upper limit
Testing method
Continuously increasing the concurrency level to test the upper limit of the server’s ability to provide service under normal conditions.
stress parameters
- Duration: 5 minutes
- Service abnormality indicator: error rate greater than 0.00%
Querying vertices by ID
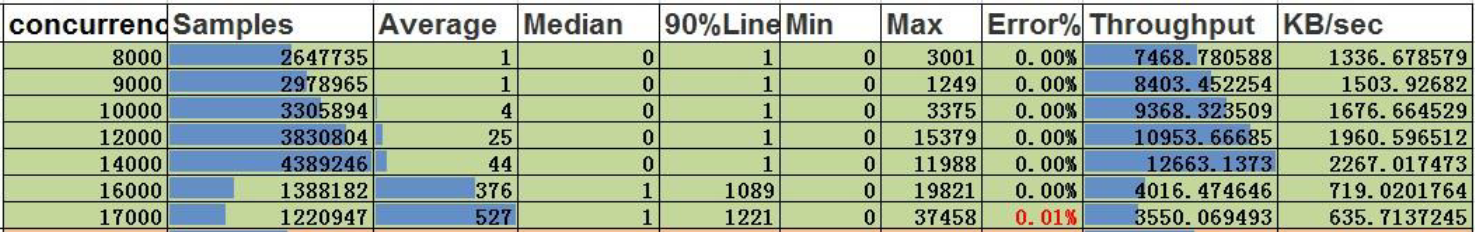
Conclusion:
- Concurrency is 14,000, throughput is 12,663. The concurrency capacity for querying vertices by ID is 14,000, with an average delay of 44ms.
Querying edges by ID
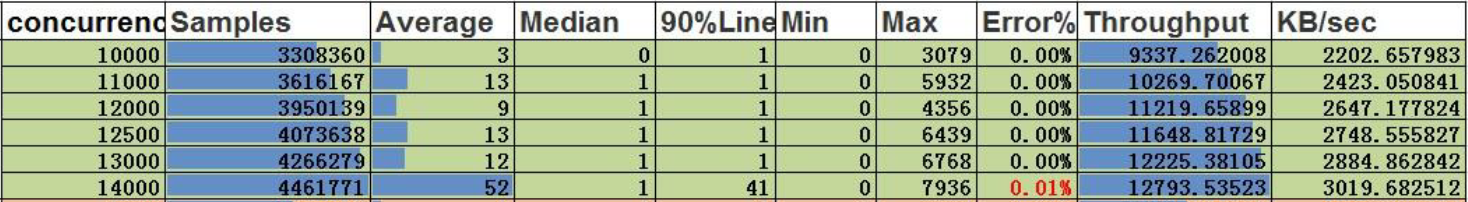
Conclusion:
- Concurrency is 13,000, throughput is 12,225. The concurrency capacity for querying edges by ID is 13,000, with an average delay of 12ms.
8.2.2 - v0.5.6 Cluster(Cassandra)
Note:
The current performance metrics are based on an earlier version. The latest version has significant improvements in both performance and functionality. We encourage you to refer to the most recent release featuring autonomous distributed storage and enhanced computational push down capabilities. Alternatively, you may wait for the community to update the data with these enhancements.
1 Test environment
Compressed machine information
| CPU | Memory | 网卡 | 磁盘 |
|---|---|---|---|
| 48 Intel(R) Xeon(R) CPU E5-2650 v4 @ 2.20GHz | 128G | 10000Mbps | 750GB SSD,2.7T HDD |
- Starting Pressure Machine Information: Configure the same as the compressed machine.
- Testing tool: Apache JMeter 2.5.1.
Note: The machine used to initiate the load and the machine being tested are located in the same data center (or server room)
2 Test Description
2.1 Definition of terms (the unit of time is ms)
- Samples – The total number of threads completed in this scenario.
- Average – The average response time.
- Median – The median response time in statistical terms.
- 90% Line – The response time below which 90% of all threads fall.
- Min – The minimum response time.
- Max – The maximum response time.
- Error – The error rate.
- Throughput – The number of transactions processed per unit of time.
- KB/sec – The throughput measured in terms of data transmitted per second.
2.2 Low-Level Storage
A 15-node Cassandra cluster is used for backend storage. HugeGraph and the Cassandra cluster are located on separate servers. Server-related configuration files are modified only for host and port settings, while the rest remain default.
3 Summary of Performance Results
- The speed of a single vertex and edge insertion in HugeGraph is 9000 and 4500 per second, respectively.
- The speed of bulk vertex and edge insertion is 50,000 and 150,000 per second, respectively, which is much higher than the single insertion speed.
- The concurrency for querying vertices and edges by ID can reach more than 12,000, and the average request delay is less than 70ms.
4 Test Results and Analysis
4.1 Batch Insertion
4.1.1 Pressure Upper Limit Test
Test Method
Continuously increase the concurrency level to test the upper limit of the server’s ability to provide services.
Pressure Parameters
Duration: 5 minutes.
Maximum Insertion Speed of Vertices:
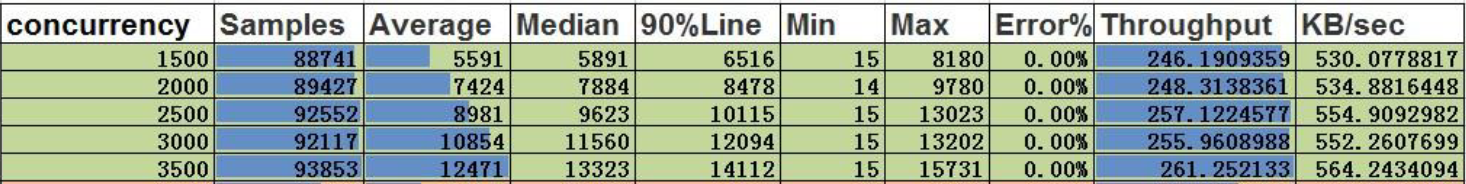
Conclusion:
- At a concurrency level of 3500, the throughput of vertices is 261, and the amount of data processed per second is 52,200 (261 * 200).
Maximum Insertion Speed of Edges:

Conclusion:
- At a concurrency level of 1000, the throughput of edges is 323, and the amount of data processed per second is 161,500 (323 * 500).
4.2 Single Insertion
4.2.1 Pressure Upper Limit Test
Test Method
Continuously increase the concurrency level to test the upper limit of the server’s ability to provide services.
Pressure Parameters
- Duration: 5 minutes.
- Service exception mark: Error rate greater than 0.00%.
Single Insertion of Vertices:
Conclusion:
- At a concurrency level of 9000, the throughput is 8400, and the single-insertion concurrency capability for vertices is 9000.
Single Insertion of Edges:
Conclusion:
- At a concurrency level of 4500, the throughput is 4160, and the single-insertion concurrency capability for edges is 4500.
4.3 Query by ID
4.3.1 Pressure Upper Limit Test
Test Method
Continuously increase the concurrency and test the upper limit of the pressure that the server can still provide services normally.
Pressure Parameters
- Duration: 5 minutes
- Service exception flag: error rate greater than 0.00%
Query by ID for vertices
Conclusion:
- The concurrent capacity of the vertex search by ID is 14500, with a throughput of 13576 and an average delay of 11ms.
Edge search by ID
Conclusion:
- For edge ID-based queries, the server’s concurrent capacity is up to 12,000, with a throughput of 10,688 and an average latency of 63ms.
8.3 - HugeGraph-Loader Performance
Note:
The current performance metrics are based on an earlier version. The latest version has significant improvements in both performance and functionality. We encourage you to refer to the most recent release featuring autonomous distributed storage and enhanced computational push down capabilities. Alternatively, you may wait for the community to update the data with these enhancements.
Use Cases
When the number of graph data to be batch inserted (including vertices and edges) is at the billion level or below, or the total data size is less than TB, the HugeGraph-Loader tool can be used to continuously and quickly import graph data.
Performance
The test uses the edge data of website.
RocksDB single-machine performance (Update: multi-raft + rocksdb cluster is supported now)
- When the label index is turned off, 228k edges/s.
- When the label index is turned on, 153k edges/s.
Cassandra cluster performance
- When label index is turned on by default, 63k edges/s.
8.4 - HugeGraph 0.4.4 Benchmark
1 测试环境
1.1 硬件信息
| CPU | Memory | 网卡 | 磁盘 |
|---|---|---|---|
| 48 Intel(R) Xeon(R) CPU E5-2650 v4 @ 2.20GHz | 128G | 10000Mbps | 750GB SSD |
1.2 软件信息
1.2.1 测试用例
测试使用graphdb-benchmark,一个图数据库测试集。该测试集主要包含4类测试:
Massive Insertion,批量插入顶点和边,一定数量的顶点或边一次性提交
Single Insertion,单条插入,每个顶点或者每条边立即提交
Query,主要是图数据库的基本查询操作:
- Find Neighbors,查询所有顶点的邻居
- Find Adjacent Nodes,查询所有边的邻接顶点
- Find Shortest Path,查询第一个顶点到100个随机顶点的最短路径
Clustering,基于Louvain Method的社区发现算法
1.2.2 测试数据集
测试使用人造数据和真实数据
MIW、SIW和QW使用SNAP数据集
CW使用LFR-Benchmark generator生成的人造数据
本测试用到的数据集规模
| 名称 | vertex数目 | edge数目 | 文件大小 |
|---|---|---|---|
| email-enron.txt | 36,691 | 367,661 | 4MB |
| com-youtube.ungraph.txt | 1,157,806 | 2,987,624 | 38.7MB |
| amazon0601.txt | 403,393 | 3,387,388 | 47.9MB |
1.3 服务配置
- HugeGraph版本:0.4.4,RestServer和Gremlin Server和backends都在同一台服务器上
- Cassandra版本:cassandra-3.10,commit-log 和data共用SSD
- RocksDB版本:rocksdbjni-5.8.6
- Titan版本:0.5.4, 使用thrift+Cassandra模式
graphdb-benchmark适配的Titan版本为0.5.4
2 测试结果
2.1 Batch插入性能
| Backend | email-enron(30w) | amazon0601(300w) | com-youtube.ungraph(300w) |
|---|---|---|---|
| Titan | 9.516 | 88.123 | 111.586 |
| RocksDB | 2.345 | 14.076 | 16.636 |
| Cassandra | 11.930 | 108.709 | 101.959 |
| Memory | 3.077 | 15.204 | 13.841 |
说明
- 表头"()“中数据是数据规模,以边为单位
- 表中数据是批量插入的时间,单位是s
- 例如,HugeGraph使用RocksDB插入amazon0601数据集的300w条边,花费14.076s,速度约为21w edges/s
结论
- RocksDB和Memory后端插入性能优于Cassandra
- HugeGraph和Titan同样使用Cassandra作为后端的情况下,插入性能接近
2.2 遍历性能
2.2.1 术语说明
- FN(Find Neighbor), 遍历所有vertex, 根据vertex查邻接edge, 通过edge和vertex查other vertex
- FA(Find Adjacent), 遍历所有edge,根据edge获得source vertex和target vertex
2.2.2 FN性能
| Backend | email-enron(3.6w) | amazon0601(40w) | com-youtube.ungraph(120w) |
|---|---|---|---|
| Titan | 7.724 | 70.935 | 128.884 |
| RocksDB | 8.876 | 65.852 | 63.388 |
| Cassandra | 13.125 | 126.959 | 102.580 |
| Memory | 22.309 | 207.411 | 165.609 |
说明
- 表头”()“中数据是数据规模,以顶点为单位
- 表中数据是遍历顶点花费的时间,单位是s
- 例如,HugeGraph使用RocksDB后端遍历amazon0601的所有顶点,并查找邻接边和另一顶点,总共耗时65.852s
2.2.3 FA性能
| Backend | email-enron(30w) | amazon0601(300w) | com-youtube.ungraph(300w) |
|---|---|---|---|
| Titan | 7.119 | 63.353 | 115.633 |
| RocksDB | 6.032 | 64.526 | 52.721 |
| Cassandra | 9.410 | 102.766 | 94.197 |
| Memory | 12.340 | 195.444 | 140.89 |
说明
- 表头”()“中数据是数据规模,以边为单位
- 表中数据是遍历边花费的时间,单位是s
- 例如,HugeGraph使用RocksDB后端遍历amazon0601的所有边,并查询每条边的两个顶点,总共耗时64.526s
结论
- HugeGraph RocksDB > Titan thrift+Cassandra > HugeGraph Cassandra > HugeGraph Memory
2.3 HugeGraph-图常用分析方法性能
术语说明
- FS(Find Shortest Path), 寻找最短路径
- K-neighbor,从起始vertex出发,通过K跳边能够到达的所有顶点, 包括1, 2, 3…(K-1), K跳边可达vertex
- K-out, 从起始vertex出发,恰好经过K跳out边能够到达的顶点
FS性能
| Backend | email-enron(30w) | amazon0601(300w) | com-youtube.ungraph(300w) |
|---|---|---|---|
| Titan | 11.333 | 0.313 | 376.06 |
| RocksDB | 44.391 | 2.221 | 268.792 |
| Cassandra | 39.845 | 3.337 | 331.113 |
| Memory | 35.638 | 2.059 | 388.987 |
说明
- 表头”()“中数据是数据规模,以边为单位
- 表中数据是找到从第一个顶点出发到达随机选择的100个顶点的最短路径的时间,单位是s
- 例如,HugeGraph使用RocksDB查找第一个顶点到100个随机顶点的最短路径,总共耗时2.059s
结论
- 在数据规模小或者顶点关联关系少的场景下,Titan最短路径性能优于HugeGraph
- 随着数据规模增大且顶点的关联度增高,HugeGraph最短路径性能优于Titan
K-neighbor性能
| 顶点 | 深度 | 一度 | 二度 | 三度 | 四度 | 五度 | 六度 |
|---|---|---|---|---|---|---|---|
| v1 | 时间 | 0.031s | 0.033s | 0.048s | 0.500s | 11.27s | OOM |
| v111 | 时间 | 0.027s | 0.034s | 0.115 | 1.36s | OOM | – |
| v1111 | 时间 | 0.039s | 0.027s | 0.052s | 0.511s | 10.96s | OOM |
说明
- HugeGraph-Server的JVM内存设置为32GB,数据量过大时会出现OOM
K-out性能
| 顶点 | 深度 | 一度 | 二度 | 三度 | 四度 | 五度 | 六度 |
|---|---|---|---|---|---|---|---|
| v1 | 时间 | 0.054s | 0.057s | 0.109s | 0.526s | 3.77s | OOM |
| 度 | 10 | 133 | 2453 | 50,830 | 1,128,688 | ||
| v111 | 时间 | 0.032s | 0.042s | 0.136s | 1.25s | 20.62s | OOM |
| 度 | 10 | 211 | 4944 | 113150 | 2,629,970 | ||
| v1111 | 时间 | 0.039s | 0.045s | 0.053s | 1.10s | 2.92s | OOM |
| 度 | 10 | 140 | 2555 | 50825 | 1,070,230 |
说明
- HugeGraph-Server的JVM内存设置为32GB,数据量过大时会出现OOM
结论
- FS场景,HugeGraph性能优于Titan
- K-neighbor和K-out场景,HugeGraph能够实现在5度范围内秒级返回结果
2.4 图综合性能测试-CW
| 数据库 | 规模1000 | 规模5000 | 规模10000 | 规模20000 |
|---|---|---|---|---|
| Titan | 45.943 | 849.168 | 2737.117 | 9791.46 |
| Memory(core) | 41.077 | 1825.905 | * | * |
| Cassandra(core) | 39.783 | 862.744 | 2423.136 | 6564.191 |
| RocksDB(core) | 33.383 | 199.894 | 763.869 | 1677.813 |
说明
- “规模"以顶点为单位
- 表中数据是社区发现完成需要的时间,单位是s,例如HugeGraph使用RocksDB后端在规模10000的数据集,社区聚合不再变化,需要耗时763.869s
- “*“表示超过10000s未完成
- CW测试是CRUD的综合评估
- 后三者分别是HugeGraph的不同后端,该测试中HugeGraph跟Titan一样,没有通过client,直接对core操作
结论
- HugeGraph在使用Cassandra后端时,性能略优于Titan,随着数据规模的增大,优势越来越明显,数据规模20000时,比Titan快30%
- HugeGraph在使用RocksDB后端时,性能远高于Titan和HugeGraph的Cassandra后端,分别比两者快了6倍和4倍
9 - Contribution Guidelines
Read the contribution process before submitting code or documentation. Separate pages cover committer nominations, mailing-list subscriptions, and release validation. Contributor agreements follow the official ASF ICLA/CCLA process.
9.1 - Contribute to the HugeGraph Community
Choose How to Contribute
You can report problems through GitHub Issues, or contribute code, tests, or documentation. Before starting a substantial change, consider opening an issue that explains its scope to avoid duplicated work.
The following example uses apache/hugegraph. The same process applies to other HugeGraph repositories, but follow each repository’s README.md, AGENTS.md, and CI configuration for its build and test commands.
Prepare the Repository
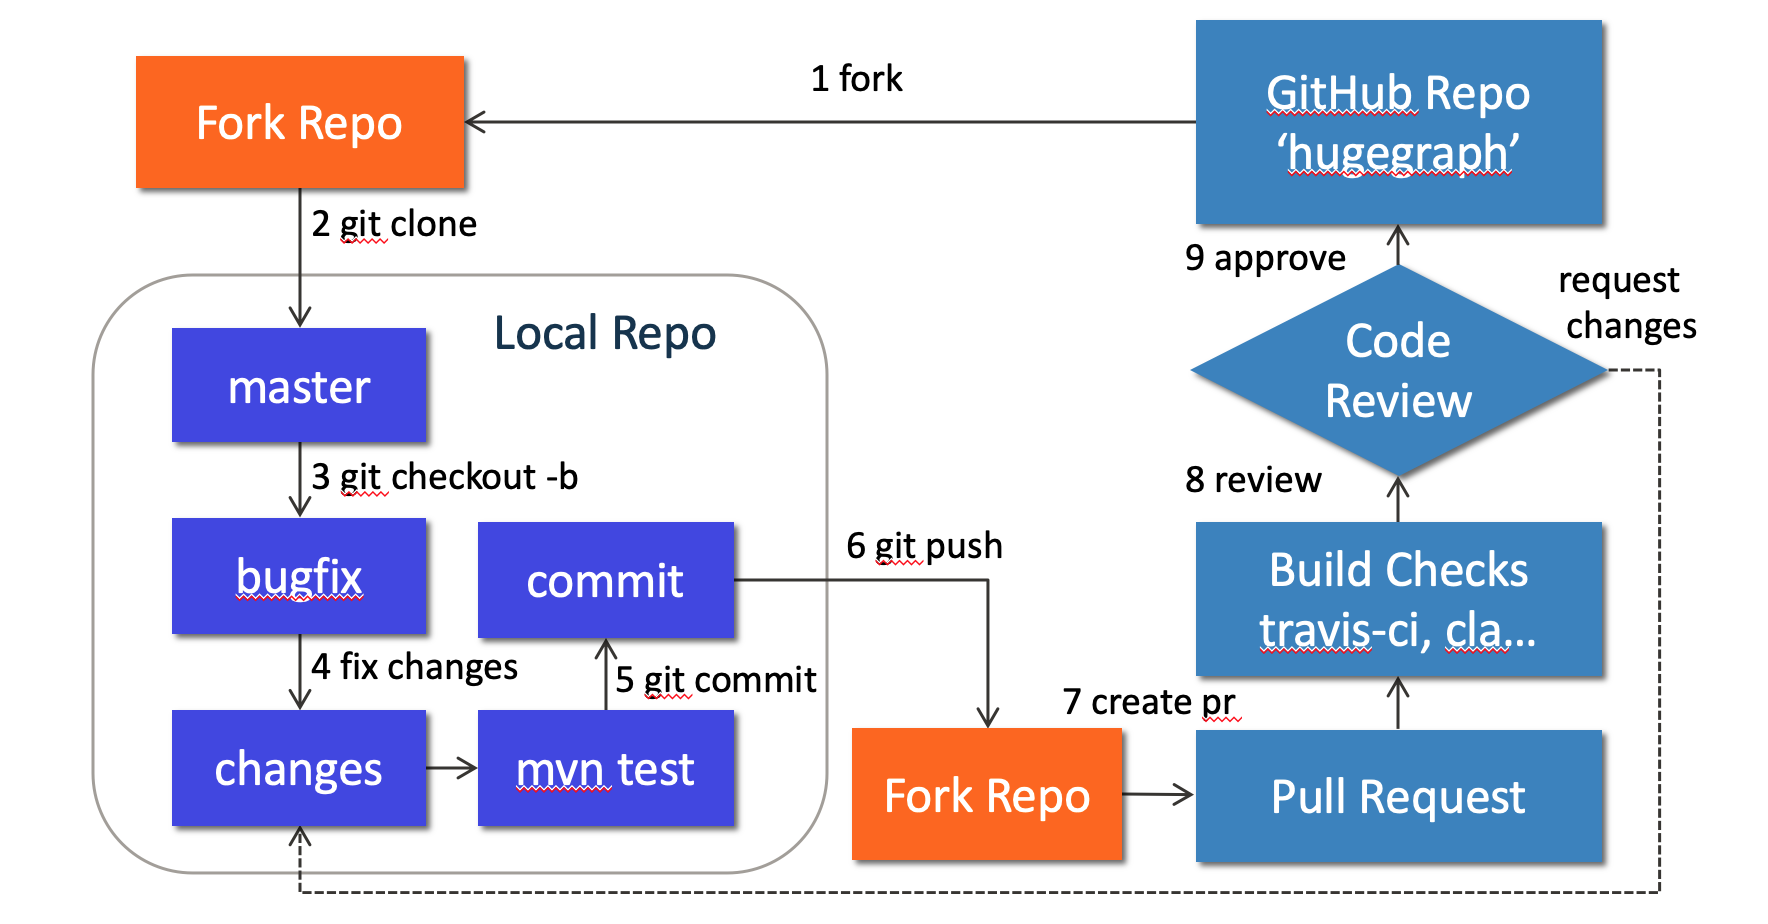
Fork apache/hugegraph on GitHub, then clone your fork:
Do not develop directly on master. Use a separate branch for each change:
Make and Verify Changes
HugeGraph Server code is under hugegraph-server/. For example, the core module is located at:
Run the tests directly related to your change first. Common Server test commands include:
GitHub requires a username and token for Git authentication instead of a username and password. Create a personal access token at https://github.com/settings/tokens:
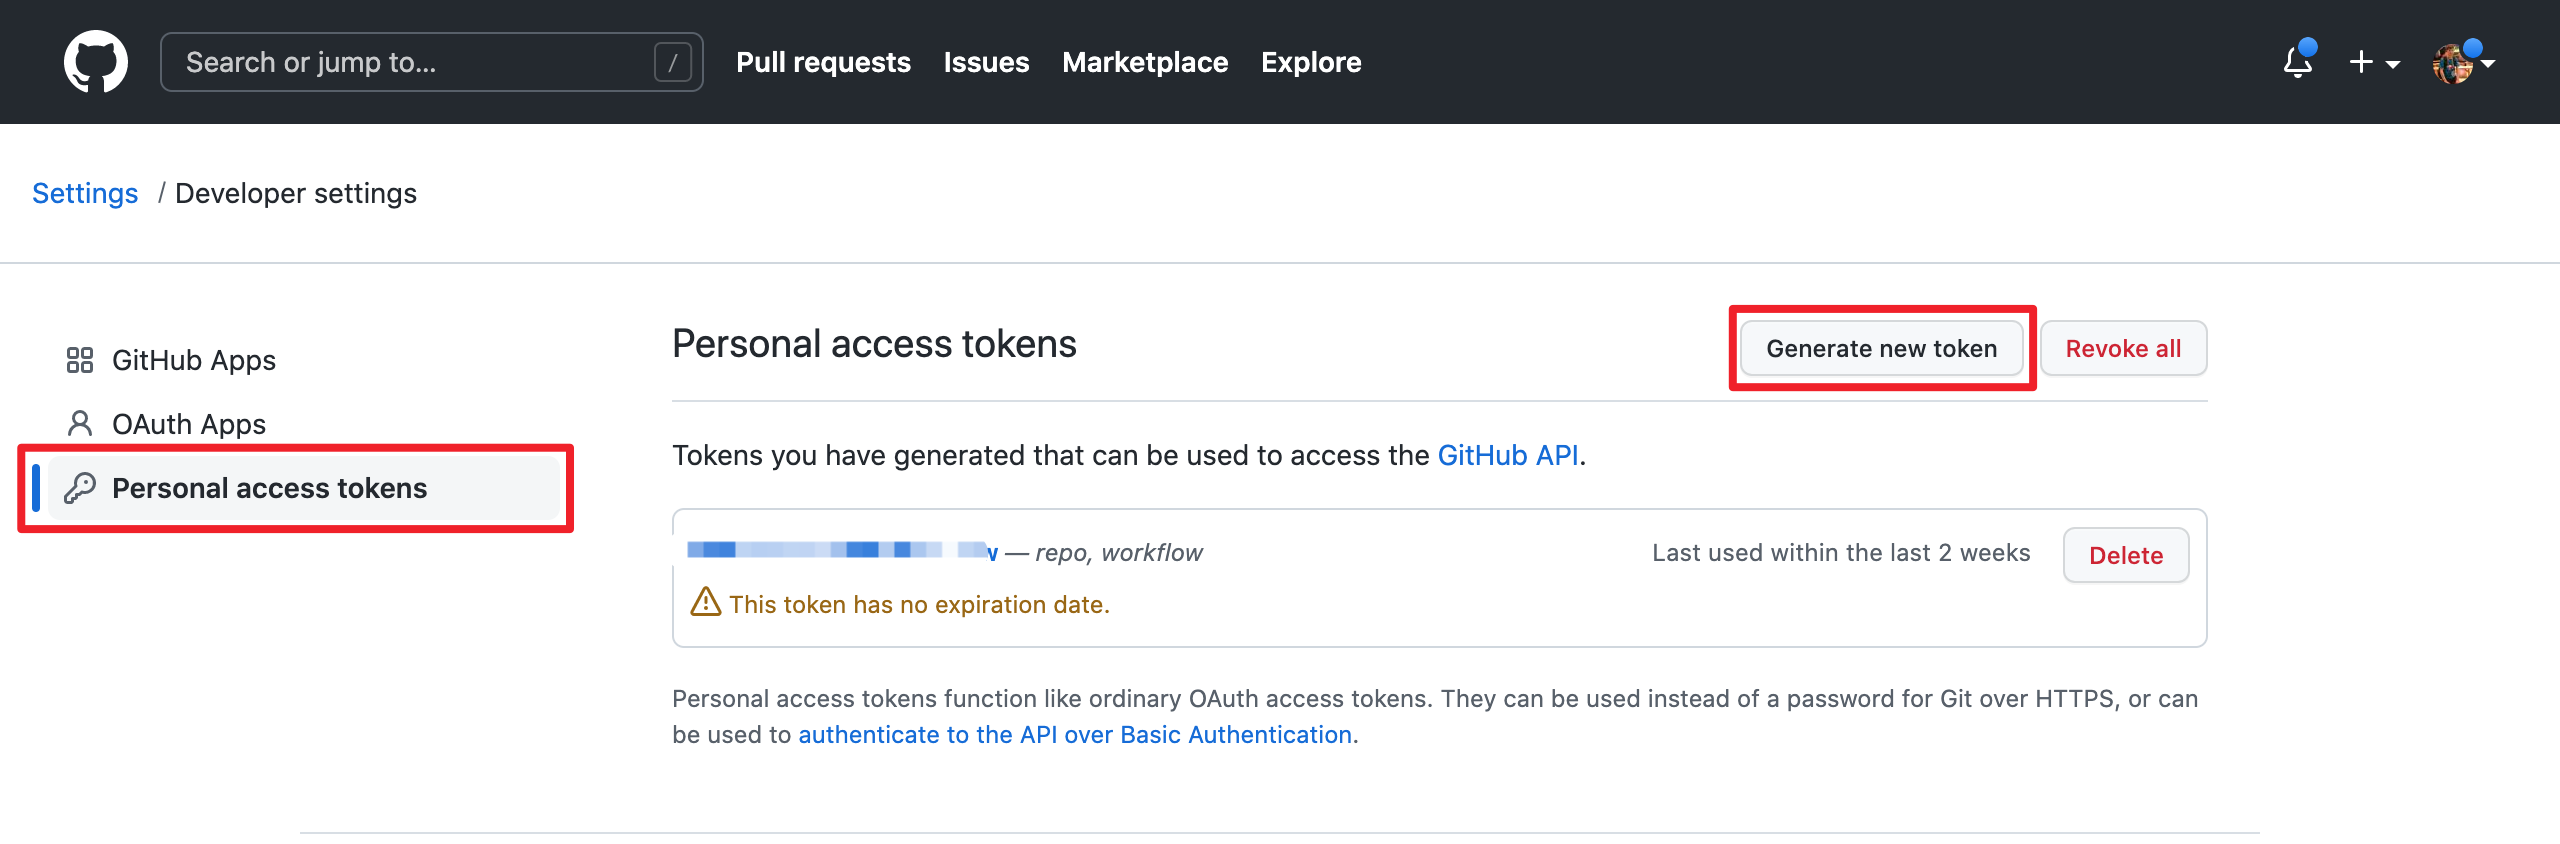
When adding a third-party dependency, also update the license information included in the distribution:
- Add the dependency’s license file to
hugegraph-server/hugegraph-dist/release-docs/licenses/. - Update
hugegraph-server/hugegraph-dist/release-docs/LICENSE. If the dependency includes a NOTICE file, updateNOTICEas well. - Run
hugegraph-server/hugegraph-dist/scripts/dependency/regenerate_known_dependencies.shto update the known-dependency list.
Submit a Pull Request
Make sure the email address used for your commits is associated with your GitHub account. See https://github.com/settings/emails for instructions:
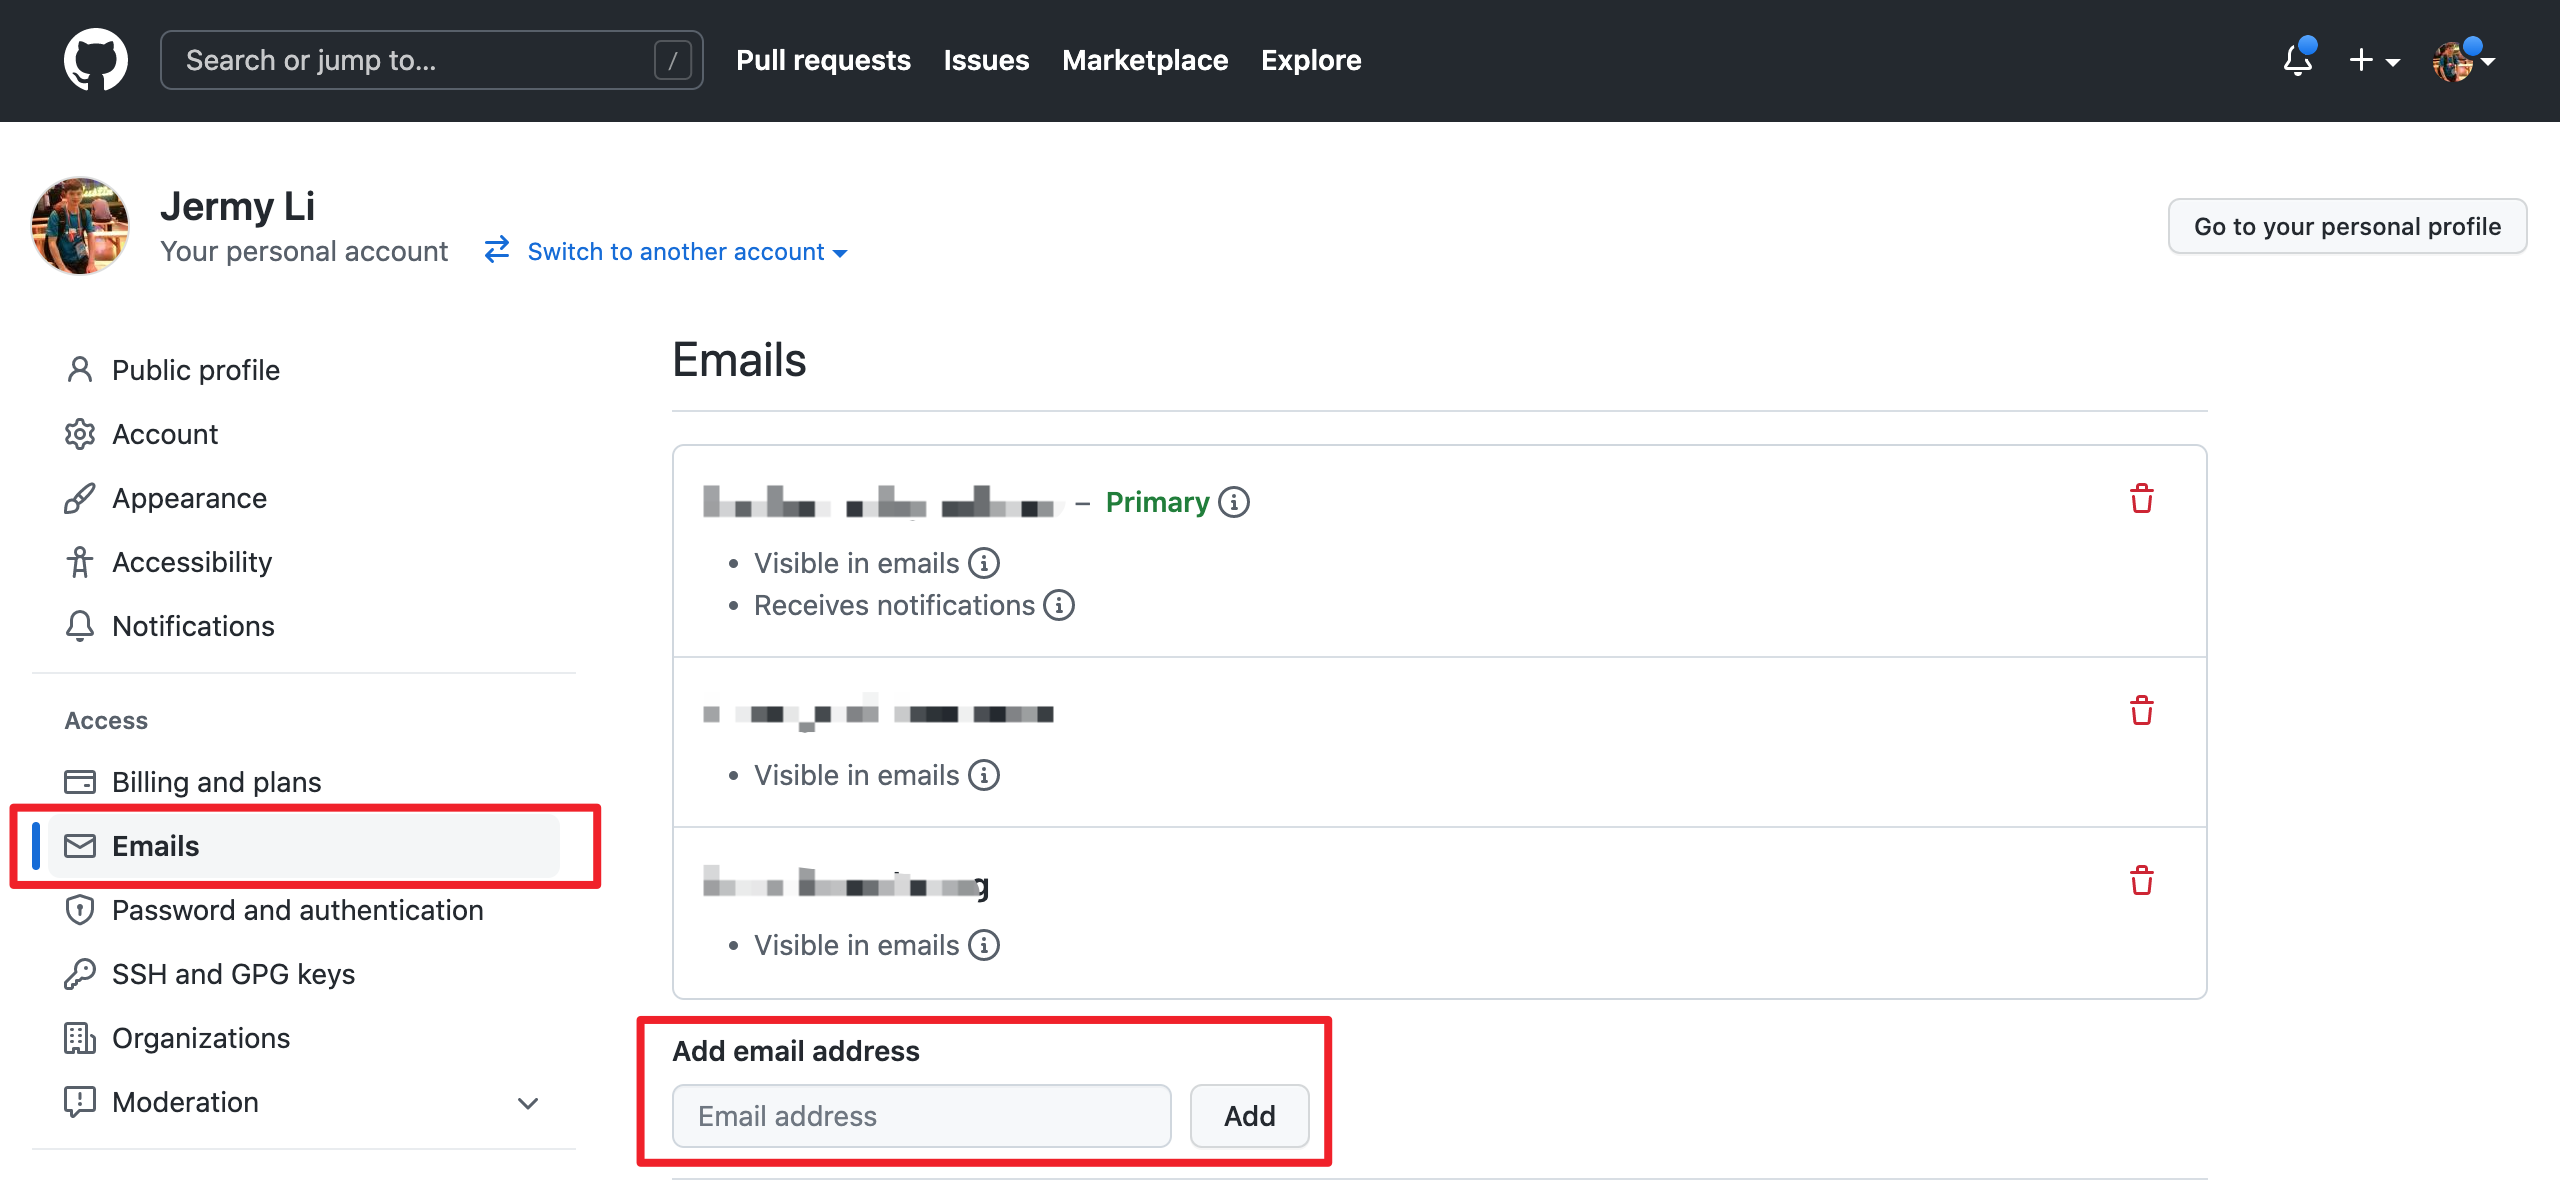
Use the type(module): message format for commit messages, for example:
Then open a pull request from your fork branch to apache/hugegraph:master. Explain the problem, the implementation, and the validation commands you actually ran. Include screenshots for UI changes.
Address Review Feedback
If CI fails or a reviewer requests changes, continue committing and pushing to the same branch. Rebase when you need to synchronize with upstream:
Do not overwrite the remote branch with plain --force. After all CI and review requirements are satisfied, a project maintainer will merge the pull request.
Contributor agreements follow the official ASF process. See the Contributor Agreement.
9.2 - Subscribe to the Community Mailing List
HugeGraph uses dev@hugegraph.apache.org for development and usage discussions. Subscribe before sending messages to the list; messages from non-subscribers may be rejected.
Subscribe
- From the email address you want to subscribe, send a message with any subject and body to dev-subscribe@hugegraph.apache.org.
- Reply directly to the confirmation message.
- After receiving the subscription confirmation, you can send messages to dev@hugegraph.apache.org.
If the confirmation does not arrive, check your spam folder and automatic mail categories. If it is still missing, wait a while and send the subscription message again.
You can browse public messages in the ASF Mailing List Archives without subscribing.
Unsubscribe
- From your subscribed address, send a message to dev-unsubscribe@hugegraph.apache.org.
- Reply directly to the confirmation message from
dev-help@hugegraph.apache.org. - Unsubscription is complete when you receive a message whose subject contains
GOODBYE.
For general ASF mailing-list guidance, see Apache Mailing Lists.
9.3 - Validate Apache Release
Note: this doc will be updated continuously. Use Java 11 for runtime verification. Since version 1.5.0, components other than the client no longer support Java 8.
Graduation note: Apache HugeGraph graduated in January 2026. Official release voting is now completed within the HugeGraph community (PMC binding votes on
dev@hugegraph.apache.org), and no longer requires Incubatorgeneral@incubator.apache.orgapproval.
Verification
When the internal temporary release and packaging work is completed, other community developers ( especially PMC) need to participate in verification based on ASF release policy and checklist references:
- ASF release policy
- Incubator checklist (historical reference) To ensure the “correctness + completeness” of someone’s published version, here requires **everyone ** to participate as much as possible, and then explain which items you have checked in the subsequent email reply.(The following are the core items)
1. prepare
If there is no svn or gpg or wget environment locally, it is recommended to install it first
(windows recommend using WSL2 environment, or at least git-bash), also make sure to install java
(prefer Java 11) and maven software
2. check hash value
First you need to check the file integrity of the source + binary package, Verify by shasum to
ensure that it is consistent with the hash value published on apache/GitHub (Usually sha512), Here
is the same as the last step of 0x02 inspection.
3. check gpg signature
This is to ensure that the published package is uploaded by a reliable person. Assuming tom signs and uploads, others should download A’s public key and then perform signature confirmation.
Related commands:
First confirm the overall integrity/consistency, and then confirm the specific content (key)
4. Check the archive contents
Check the contents of the archive downloaded from preparation work. Divided into two aspects: source code package + binary package, The source code package is stricter, it can be said that the core part (Because it is longer, For a complete list refer to the official Wiki)
A. source package
After decompressing *hugegraph*src.tar.gz, Do the following checks:
- package/folder naming should match the release line (historical releases may still contain
incubating), and no empty files/folders LICENSE+NOTICEexist and the content is normal;DISCLAIMERis required for historical incubating artifacts- does not exist binaries (without LICENSE)
- The source code files all contain the standard
ASF Licenseheader (this could be done with theMaven-MATplugin) - Check whether the
pom.xmlversion number of each parent/child module is consistent (and meet expectations) - Finally, make sure the source code works/compiles correctly
B. binary package
After decompressing xxx-hugegraph.tar.gz, perform the following checks:
- package/folder naming should match the release line (historical releases may still contain
incubating) LICENSEandNOTICEfile exists and the content is normal (DISCLAIMERapplies to historical incubating artifacts)- start server
Note: If a third-party dependency is introduced in the binary package, you need to update the LICENSE and add the third-party dependent LICENSE; if the third-party dependent LICENSE is Apache 2.0, and the corresponding project contains NOTICE, you also need to update Our NOTICE file
5. Check the official website and GitHub and other pages
- Make sure that the official website at least meets apache website check, and no circular links, etc.
- Update download link and release notes updated
- …
Mail Template
After the check & test, you should reply to the mail with the following content: (normal devs & PMC)
and the PMC members should reply with binding, it’s important for summary the valid votes:
9.4 - Setup Server in IDEA (Dev)
NOTE: The following configuration is for reference purposes only, and has been tested on Linux and macOS platforms based on this version.
Background
The Quick Start section provides instructions on how to start and stop HugeGraph-Server using scripts. In this guide, we will explain how to run and debug HugeGraph-Server on the Linux platform using IntelliJ IDEA.
The core steps for local startup are the same as starting with scripts:
- Initialize the database backend by executing the
InitStoreclass to initialize the graph. - Start HugeGraph-Server by executing the
HugeGraphServerclass to load the initialized graph information and start the server.
Before proceeding with the following process, make sure that you have cloned the source code of HugeGraph
and have configured the development environment, such as Java 11 & you could config your local environment
with this config-doc
Steps
1. Copy Configuration Files
To avoid the impact of configuration file changes on Git tracking, it is recommended to copy the required configuration files to a separate folder. Run the following command to copy the files:
Replace path-to-your-directory with the path to the directory where you want to copy the files.
After introducing ToplingDB, developers need to execute the
preload-topling.shscript, which automatically extracts the required dynamic libraries and Web Server static resources into thelibrarydirectory located alongside thebindirectory (the static resources will also be copied to/dev/shm/rocksdb_resource).
2. Configure InitStore to initialize the graph
First, you need to configure the database backend in the configuration files. In this example, we will use RocksDB. Open path-to-your-directory/conf/graphs/hugegraph.properties and configure it as follows:
Next, open the Run/Debug Configurations panel in IntelliJ IDEA and create a new Application configuration. Follow these steps for the configuration:
- Select
hugegraph-distas theUse classpath of module. - Set the
Main classtoorg.apache.hugegraph.cmd.InitStore. - Set the program arguments to
conf/rest-server.properties. Note that the path here is relative to the working directory, so make sure to set the working directory topath-to-your-directory. - ToplingDB requires preloading dynamic libraries via the
LD_PRELOADmechanism. Developers need to set two environment variables:LD_LIBRARY_PATHshould point to thelibrarydirectory extracted bypreload-topling.sh, andLD_PRELOADshould be set tolibjemalloc.so:librocksdbjni-linux64.soto ensure the necessary libraries are correctly loaded at runtime.- LD_LIBRARY_PATH=/path/to/your/library:$LD_LIBRARY_PATH
- LD_PRELOAD=libjemalloc.so:librocksdbjni-linux64.so
If user authentication (authenticator) is configured for HugeGraph-Server in the Java 11 environment, you need to refer to the script configuration in the binary package and add the following VM options:
Otherwise, an error will occur:
Once the configuration is completed, run it. If the execution is successful, the following runtime logs will be displayed:
3. Running HugeGraphServer
Similarly, open the Run/Debug Configurations panel in IntelliJ IDEA and create a new Application configuration. Follow these steps for the configuration:
- Select
hugegraph-distas theUse classpath of module. - Set the
Main classtoorg.apache.hugegraph.dist.HugeGraphServer. - Set the program arguments to
conf/gremlin-server.yaml conf/rest-server.properties. Similarly, note that the path here is relative to the working directory, so make sure to set the working directory topath-to-your-directory.
Similarly, if user authentication (authenticator) is configured for HugeGraph-Server in the Java 11 environment, you need to refer to the script configuration in the binary package and add the following VM options:
Otherwise, an error will occur:
Once the configuration is completed, run it. If you see the following logs, it means that HugeGraphServer has been successfully started:
4. Debugging HugeGraphServer (optional)
After completing the above configuration, you can try debugging HugeGraphServer. Run HugeGraphServer in debug mode and set a breakpoint at the following location:
Then use the RESTful API to request HugeGraphServer:
At this point, you can view detailed variable information in the debugger.
5. Log4j2 Configuration
By default, when running InitStore and HugeGraphServer, the Log4j2 configuration file path read is hugegraph-dist/src/main/resources/log4j2.xml, not path-to-your-directory/conf/log4j2.xml. This configuration file is read when starting HugeGraph-Server using the script.
To avoid maintaining two separate configuration files, you can modify the Log4j2 configuration file path when running and debugging HugeGraph-Server in IntelliJ IDEA:
- Open the previously created
Applicationconfiguration. - Click on
Modify options-Add VM options. - Set the VM options to
-Dlog4j.configurationFile=conf/log4j2.xml.
Possible Issues
1. java: package sun.misc does not exist
The reason may be that cross-compilation is triggered when using Java 11 to compile, causing the symbol of sun.misc.Unsafe used in the project to not be found. There are two possible solutions:
- In IntelliJ IDEA, go to
Preferences/Settingsand find theJava Compilerpanel. Then, disable the--releaseoption (recommended). - Set the Project SDK to 8 (Deprecated soon).
2. java: *.store.raft.rpc.RaftRequests does not exist (RPC Generated Files)
The reason is that the source code didn’t include the RPC-generated files. You could try 2 ways to fix it:
- [CMD]
mvn clean compilein the root directory (Recommend) - [UI] right click on the
hugegraphrepo and selectMaven->Generate Sources and Update Folders. This will rebuild the repo and correctly generate the required files.
3. Unable to Print Location Information (%l) in Log4j2
This is because Log4j2 uses asynchronous loggers. You can refer to the official documentation for configuration details.
References
9.5 - Apache HugeGraph Committer Guide
This document outlines the requirements and process for becoming an Apache Committer. The corresponding ASF official document can be found at: https://community.apache.org/newcommitter.html
Candidate Requirements
- Candidates must adhere to the Apache Code of Conduct.
- PMC members will assess candidates’ interactions with others and contributions through mailing lists, issues, pull requests, and official documentation.
- Considerations for evaluating candidates as potential Committers include:
- Ability to collaborate with community members
- Mentorship capabilities
- Community involvement
- Level of contribution
- Personal skills/abilities
Nomination Process
Discussion → Vote → Invitation → Announcement
Initiate Community Discussion (DISCUSS)
Any (P)PMC member of HugeGraph can initiate a voting discussion. After identifying valuable contributions from a community contributor and obtaining the candidate’s consent, a discussion can be initiated via private@hugegraph.apache.org. The initiator of the discussion should clearly state the candidate’s contributions in the discussion email and provide URLs or other information for confirming the contributions, facilitating discussion and analysis.
Below is a template for HugeGraph emails: (For reference only)
Note: The term
xxxwill be used to refer to the candidate. Typically,xxxrepresents an easily readable name (e.g.,Simon Jay).ASF-INFRA recommends avoiding the use of less readable
IDdirectly as a reference to the person in emails (e.g., avoidsimon321orwh0isSim0n😄).In addition, it is best to choose the “pure text” mode, otherwise the typesetting may be chaotic in the ASF Mailing-list UI
For contribution links in discussion emails, you can use the statistical feature of GitHub Search by entering corresponding keywords as needed. You can also adjust parameters and add new repositories such as repo:apache/incubator-hugegraph-computer. Pay special attention to adjusting the time range (below is a template reference, please adjust the parameters accordingly):
- Number of PR submissions
is:pr author:xxx repo:apache/incubator-hugegraph repo:apache/incubator-hugegraph-doc created:>2023-06-01 updated:<2023-12-25
- Lines of code submissions/changes
- Number of PR submissions associated with issues
linked:issue involves:xxx repo:apache/incubator-hugegraph repo:apache/incubator-hugegraph-doc created:>2023-06-01 updated:<2023-12-25
- Number of PR reviews
type:pr reviewed-by:xxx repo:apache/incubator-hugegraph repo:apache/incubator-hugegraph-doc created:>2023-06-01 updated:<2023-12-25
- Number of merge commits
type:pr author:xxx repo:apache/incubator-hugegraph repo:apache/incubator-hugegraph-doc created:>2023-06-01 updated:<2023-12-25
- Effective lines merged
- Number of issue submissions
type:issue author:xxx repo:apache/incubator-hugegraph repo:apache/incubator-hugegraph-doc created:>2023-06-01 updated:<2023-12-25
- Number of issue fixes
- Based on the number of issue submissions, select those with a closed status.
- Number of issue participations
type:issue involves:xxx repo:apache/incubator-hugegraph repo:apache/incubator-hugegraph-doc created:>2023-06-01 updated:<2023-12-25
- Number of issue comments
type:issue commenter:xxx repo:apache/incubator-hugegraph repo:apache/incubator-hugegraph-doc created:>2023-06-01 updated:<2023-12-25
- Number of PR comments
type:pr commenter:xxx repo:apache/incubator-hugegraph repo:apache/incubator-hugegraph-doc created:>2023-06-01 updated:<2023-12-25
For participation in mailing lists, you can use https://lists.apache.org/list?dev@hugegraph.apache.org:lte=10M:xxx.
Initiate Community Voting Email (VOTE)
If there are no dissenting opinions within the specified time frame of the discussion email, the initiator of the discussion needs to initiate a voting email for the committer election at private@hugegraph.apache.org.
Below is the corresponding email template:
Then, (P)PMC members reply to the email with +1 or -1 to express their opinions. Generally, at least 3 votes of +1 are needed to conclude the vote.
Announcement of Voting Results (RESULT)
After the voting email concludes, the initiator of the vote needs to remind the end of the voting in the email. Additionally, the initiator needs to announce the voting results via email to private@hugegraph.apache.org. The email template can be as follows:
Send Invitation Email to Candidate (INVITE)
After the announcement of the voting results email is sent, the initiator of the vote should send an invitation email to the candidate. The invitation email is addressed to the candidate and cc’d to private@hugegraph.apache.org. The invited candidate must reply to the specified email address to accept or reject the invitation.
Below is a template for reference:
Candidate Accepts Invitation (ACCEPT)
The candidate should reply to the aforementioned email (select reply all) to indicate acceptance of the invitation. Below is a template for the email:
Of course, the candidate may also choose to decline the invitation, in which case there is no template:)
Once the invitation is accepted, the candidate needs to complete the following tasks:
- Subscribe to dev@hugegraph.apache.org, for specific steps/filtering configurations, please refer to the documentation
- Sign the ICLA, follow the steps below↓
ICLA Signing Process
- Download the ICLA
- Open the PDF and fill in the required information. All fields must be filled in English. It is recommended to use a PDF tool to edit and sign.
- Full name: First name followed by last name
- Public name: Optional, defaults to the same as
Full name - Check the box only if you entered names with your family name first
- Postal Address: English address, starting from small to large, including detailed street address
- Country: Country of residence in English
- E-mail: Email address, preferably the same as the one used in the invitation email
- (optional) preferred Apache id(s): Choose an SVN ID that is not listed on the Apache committer page
- (optional) notify project: Apache HugeGraph(incubating)
- Signature: Must be handwritten using a PDF tool
- Date: Format as xxxx-xx-xx
- After signing, rename
icla.pdftoname-pinyin-icla.pdf - Send the following email and attach
name-pinyin-icla.pdfas a reference.
For more details, please refer to https://github.com/apache/hugegraph/issues/1732.
PMC members will await confirmation of the ICLA record from the Apache secretary team. Candidates and PMC members will receive the following email:
Setting Up Apache Account and Development Environment (CONFIG)
After the record is completed, the candidate will receive an email from root@apache.org with the subject Welcome to the Apache Software Foundation. At this point, the candidate needs to follow the steps in the email to set up the Apache account and development environment:
- Reset the password at https://id.apache.org/reset/enter.
- Configure personal information at https://whimsy.apache.org/roster/committer/xxx.
- Associate GitHub account at https://gitbox.apache.org/boxer.
- This step requires configuring GitHub Two-Factor Authentication (2FA).
- The nominating PMC member must add the new Committer to the official list of committers via the Roster page. (Important, otherwise repository permissions will not take effect).
- After this step, the candidate becomes a new Committer and gains write access to the GitHub HugeGraph repository.
- (Optional) The new Committer can apply for free use of JetBrains’ full range of products with their Apache account here.
Announcing via Email (ANNOUNCE)
After the candidate completes the above steps, they will officially become a Committer of HugeGraph. At this point, they need to send an announcement email to dev@hugegraph.apache.org. Below is a template for the email:
Update clutch status information
PMC members responsible for nominations need to download clutch status information and update it. Once effective, it can be viewed on the clutch and projects pages. The process is as follows:
References
- https://community.apache.org/newcommitter.html (ASF official documentation)
- https://infra.apache.org/new-committers-guide.html
- https://www.apache.org/dev/pmc.html#newcommitter
- https://linkis.apache.org/zh-CN/community/how-to-vote-a-committer-pmc
- https://www.apache.org/licenses/contributor-agreements.html#submitting
- https://www.apache.org/licenses/cla-faq.html#printer
- https://linkis.apache.org/zh-CN/community/how-to-sign-apache-icla
- https://github.com/apache/hugegraph/issues/1732 (HugeGraph ICLA related issue)
10 - CHANGELOGS
10.1 - HugeGraph 1.0.0 Release Notes
OLTP API & Client Changes
API Changes
- feat(api): support hot set trace through /exception/trace API.
- feat(api): support query by Cypher language.
- feat(api): support swagger UI to viewing API.
Client Changes
- feat(client) support Cypher query API.
- refact(client): change ’limit’ type from long to int.
- feat(client): server bypass for hbase writing (Beta).
Core & Server
Feature Changes
- feat: support Java 11.
- feat(core): support adamic-adar & resource-allocation algorithms.
- feat(hbase): support hash rowkey & pre-init tables.
- feat(core): support query by Cypher language.
- feat(core): support automatic management and fail-over for cluster role.
- feat(core): support 16 OLAP algorithms, like: LPA, Louvain, PageRank, BetweennessCentrality, RingsDetect.
- feat: prepare for Apache release.
Bug Fix
- fix(core): can’t query edges by multi labels + properties.
- fix(core): occasionally NoSuchMethodError Relations().
- fix(core): limit max depth for cycle detection.
- fix(core): traversal contains Tree step has different result.
- fix edge batch update error.
- fix unexpected task status.
- fix(core): edge cache not clear when update or delete associated vertex.
- fix(mysql): run g.V() is error when it’s MySQL backend.
- fix: close exception and server-info EXPIRED_INTERVAL.
- fix: export ConditionP.
- fix: query by within + Text.contains.
- fix: schema label race condition of addIndexLabel/removeIndexLabel.
- fix: limit admin role can drop graph.
- fix: ProfileApi url check & add build package to ignore file.
- fix: can’t shut down when starting with exception.
- fix: Traversal.graph is empty in StepStrategy.apply() with count().is(0).
- fix: possible extra comma before where statement in MySQL backend.
- fix: JNA UnsatisfiedLinkError for Apple M1.
- fix: start RpcServer NPE & args count of ACTION_CLEARED error & example error.
- fix: rpc server not start.
- fix: User-controlled data in numeric cast & remove word dependency.
- fix: closing iterators on errors for Cassandra & Mysql.
Option Changes
- move
raft.endpointoption from graph scope to server scope.
Other Changes
- refact(core): enhance schema job module.
- refact(raft): improve raft module & test & install snapshot and add peer.
- refact(core): remove early cycle detection & limit max depth.
- cache: fix assert node.next==empty.
- fix apache license conflicts: jnr-posix and jboss-logging.
- chore: add logo in README & remove outdated log4j version.
- refact(core): improve CachedGraphTransaction perf.
- chore: update CI config & support ci robot & add codeQL SEC-check & graph option.
- refact: ignore security check api & fix some bugs & clean code.
- doc: enhance CONTRIBUTING.md & README.md.
- refact: add checkstyle plugin & clean/format the code.
- refact(core): improve decode string empty bytes & avoid array-construct columns in BackendEntry.
- refact(cassandra): translate ipv4 to ipv6 metrics & update cassandra dependency version.
- chore: use .asf.yaml for apache workflow & replace APPLICATION_JSON with TEXT_PLAIN.
- feat: add system schema store.
- refact(rocksdb): update rocksdb version to 6.22 & improve rocksdb code.
- refact: update mysql scope to test & clean protobuf style/configs.
- chore: upgrade Dockerfile server to 0.12.0 & add editorconfig & improve ci.
- chore: upgrade grpc version.
- feat: support updateIfPresent/updateIfAbsent operation.
- chore: modify abnormal logs & upgrade netty-all to 4.1.44.
- refact: upgrade dependencies & adopt new analyzer & clean code.
- chore: improve .gitignore & update ci configs & add RAT/flatten plugin.
- chore(license): add dependencies-check ci & 3rd-party dependency licenses.
- refact: Shutdown log when shutdown process & fix tx leak & enhance the file path.
- refact: rename package to apache & dependency in all modules (Breaking Change).
- chore: add license checker & update antrun plugin & fix building problem in windows.
- feat: support one-step script for apache release v1.0.0 release.
Computer (OLAP)
Algorithm Changes
- feat: implement page-rank algorithm.
- feat: implement wcc algorithm.
- feat: implement degree centrality.
- feat: implement triangle_count algorithm.
- feat: implement rings-detection algorithm.
- feat: implement LPA algorithm.
- feat: implement kcore algorithm.
- feat: implement closeness centrality algorithm.
- feat: implement betweenness centrality algorithm.
- feat: implement cluster coefficient algorithm.
Platform Changes
- feat: init module computer-core & computer-algorithm & etcd dependency.
- feat: add Id as base type of vertex id.
- feat: init Vertex/Edge/Properties & JsonStructGraphOutput.
- feat: load data from hugegraph server.
- feat: init basic combiner, Bsp4Worker, Bsp4Master.
- feat: init sort & transport interface & basic FileInput/Output Stream.
- feat: init computation & ComputerOutput/Driver interface.
- feat: init Partitioner and HashPartitioner
- feat: init Master/WorkerService module.
- feat: init Heap/LoserTree sorting.
- feat: init rpc module.
- feat: init transport server, client, en/decode, flowControl, heartbeat.
- feat: init DataDirManager & PointerCombiner.
- feat: init aggregator module & add copy() and assign() methods to Value class.
- feat: add startAsync and finishAsync on client side, add onStarted and onFinished on server side.
- feat: init store/sort module.
- feat: link managers in worker sending end.
- feat: implement data receiver of worker.
- feat: implement StreamGraphInput and EntryInput.
- feat: add Sender and Receiver to process compute message.
- feat: add seqfile fromat.
- feat: add ComputeManager.
- feat: add computer-k8s and computer-k8s-operator.
- feat: add startup and make docker image code.
- feat: sort different type of message use different combiner.
- feat: add HDFS output format.
- feat: mount config-map and secret to container.
- feat: support java11.
- feat: support partition concurrent compute.
- refact: abstract computer-api from computer-core.
- refact: optimize data receiving.
- fix: release file descriptor after input and compute.
- doc: add operator deploy readme.
- feat: prepare for Apache release.
Toolchain (loader, tools, hubble)
- feat(loader): support use SQL to construct graph.
- feat(loader): support Spark-Loader mode(include jdbc source).
- feat(loader): support Flink-CDC mode.
- fix(loader): fix NPE when loading ORC data.
- fix(loader): fix schema is not cached with Spark/Flink mode.
- fix(loader): fix json deserialize error.
- fix(loader): fix jackson conflicts & missing dependencies.
- feat(hubble): supplementary algorithms UI.
- feat(hubble): support highlighting and hints for Gremlin text.
- feat(hubble): add docker-file for hubble.
- feat(hubble): display packaging log output progress while building.
- fix(hubble): fix port-input placeholder UI.
- feat: prepare for Apache release.
Commons (common,rpc)
- feat: support assert-throws method returning Future.
- feat: add Cnm and Anm to CollectionUtil.
- feat: support custom content-type.
- feat: prepare for Apache release.
Release Details
Please check the release details in each repository:
10.2 - HugeGraph 1.2.0 Release Notes
Java version statement
In the future, we will gradually upgrade the java version, Java 11 -> Java 17 -> Java 21.
- hugegraph, hugegraph-toolchain, hugegraph-commons consider use Java 11, also compatible with Java 8 now.
- hugegraph-computer required to use Java 11, not compatible with Java 8 now!
v1.2.0 may be the last major version compatible with Java 8, compatibility with Java 8 will totally end in v1.5 when PD/Store merged into master branch (Except for the java-client).
hugegraph
API Changes
- feat(api&core): in oltp apis, add statistics info and support full info about vertices and edges (#2262)
- feat(api): support embedded arthas agent in hugegraph-server (#2278,#2337)
- feat(api): support metric API Prometheus format & add statistic metric api (#2286)
- feat(api-core): support label & property filtering for both edge and vertex & support kout dfs mode (#2295)
- feat(api): support recording slow query log (#2327)
Feature Changes
- feat: support task auto manage by server role state machine (#2130)
- feat: support parallel compress snapshot (#2136)
- feat: use an enhanced CypherAPI to refactor it (#2143)
- feat(perf): support JMH benchmark in HG-test module (#2238)
- feat: optimising adjacency edge queries (#2242)
- Feat: IP white list (#2299)
- feat(cassandra): adapt cassandra from 3.11.12 to 4.0.10 (#2300)
- feat: support Cassandra with docker-compose in server (#2307)
- feat(core): support batch+parallel edges traverse (#2312)
- feat: adapt Dockerfile for new project structur (#2344)
- feat(server):swagger support auth for standardAuth mode by (#2360)
- feat(core): add IntMapByDynamicHash V1 implement (#2377)
Bug Fix
- fix: transfer add_peer/remove_peer command to leader (#2112)
- fix query dirty edges of a vertex with cache (#2166)
- fix exception of vertex-drop with index (#2181)
- fix: remove dup ‘From’ in filterExpiredResultFromFromBackend (#2207)
- fix: jdbc ssl mode parameter redundant (#2224)
- fix: error when start gremlin-console with sample script (#2231)
- fix(core): support order by id (#2233)
- fix: update ssl_mode value (#2235)
- fix: optimizing ClassNotFoundException error message for MYSQL (#2246)
- fix: asf invalid notification scheme ‘discussions_status’ (#2247)
- fix: asf invalid notification scheme ‘discussions_comment’ (#2250)
- fix: incorrect use of ‘NO_LIMIT’ variable (#2253)
- fix(core): close flat mapper iterator after usage (#2281)
- fix(dist): avoid var PRELOAD cover environmnet vars (#2302)
- fix: base-ref/head-ref missed in dependency-review on master (#2308)
- fix(core): handle schema Cache expandCapacity concurrent problem (#2332)
- fix: in wait-storage.sh, always wait for storage with default rocksdb (#2333)
- fix(api): refactor/downgrade record logic for slow log (#2347)
- fix(api): clean some code for release (#2348)
- fix: remove redirect-to-master from synchronous Gremlin API (#2356)
- fix HBase PrefixFilter bug (#2364)
- chore: fix curl failed to request https urls (#2378)
- fix(api): correct the vertex id in the edge-existence api (#2380)
- fix: github action build docker image failed during the release 1.2 process (#2386)
- fix: TinkerPop unit test lack some lables (#2387)
Option Changes
- feat(dist): support pre-load test graph data in docker container (#2241)
Other Changes
- refact: use standard UTF-8 charset & enhance CI configs (#2095)
- move validate release to hugegraph-doc (#2109)
- refact: use a slim way to build docker image on latest code & support zgc (#2118)
- chore: remove stage-repo in pom due to release done & update mail rule (#2128)
- doc: update issue template & README file (#2131)
- chore: cmn algorithm optimization (#2134)
- add github token for license check comment (#2139)
- chore: disable PR up-to-date in branch (#2150)
- refact(core): remove lock of globalMasterInfo to optimize perf (#2151)
- chore: async remove left index shouldn’t effect query (#2199)
- refact(rocksdb): clean & reformat some code (#2200)
- refact(core): optimized batch removal of remaining indices consumed by a single consumer (#2203)
- add com.janeluo.ikkanalyzer dependency to core model (#2206)
- refact(core): early stop unnecessary loops in edge cache (#2211)
- doc: update README & add QR code (#2218)
- chore: update .asf.yaml for mail rule (#2221)
- chore: improve the UI & content in README (#2227)
- chore: add pr template (#2234)
- doc: modify ASF and remove meaningless CLA (#2237)
- chore(dist): replace wget to curl to download swagger-ui (#2277)
- Update StandardStateMachineCallback.java (#2290)
- doc: update README about start server with example graph (#2315)
- README.md tiny improve (#2320)
- doc: README.md tiny improve (#2331)
- refact: adjust project structure for merge PD & Store[Breaking Change] (#2338)
- chore: disable raft test in normal PR due to timeout problem (#2349)
- chore(ci): add stage profile settings (#2361)
- refact(api): update common 1.2 & fix jersey client code problem (#2365)
- chore: move server info into GlobalMasterInfo (#2370)
- chore: reset hugegraph version to 1.2.0 (#2382)
hugegraph-computer
Feature Changes
- feat: implement fast-failover for MessageRecvManager and DataClientManager (#243)
- feat: implement parallel send data in load graph step (#248)
- feat(k8s): init operator project & add webhook (#259, #263)
- feat(core): support load vertex/edge snapshot (#269)
- feat(k8s): Add MinIO as internal(default) storage (#272)
- feat(algorithm): support random walk in computer (#274, #280)
- feat: use ‘foreground’ delete policy to cancel k8s job (#290)
Bug Fix
- fix: superstep not take effect (#237)
- fix(k8s): modify inconsistent apiGroups (#270)
- fix(algorithm): record loop is not copied (#276)
- refact(core): adaptor for common 1.2 & fix a string of possible CI problem (#286)
- fix: remove okhttp1 due to conflicts risk (#294)
- fix(core): io.grpc.grpc-core dependency conflic (#296)
Option Changes
- feat(core): isolate namespace for different input data source (#252)
- refact(core): support auth config for computer task (#265)
Other Changes
- remove apache stage repo & update notification rule (#232)
- chore: fix empty license file (#233)
- chore: enhance mailbox settings & enable require ci (#235)
- fix: typo errors in start-computer.sh (#238)
- [Feature-241] Add PULL_REQUEST_TEMPLATE (#242, #257)
- chore: change etcd url only for ci (#245)
- doc: update readme & add QR code (#249)
- doc(k8s): add building note for missing classes (#254)
- chore: reduce mail to dev list (#255)
- add: dependency-review (#266)
- chore: correct incorrect comment (#268)
- refactor(api): ListValue.getFirst() replaces ListValue.get(0) (#282)
- Improve: Passing workerId to WorkerStat & Skip wait worker close if master executes failed (#292)
- chore: add check dependencies (#293)
- chore(license): update license for 1.2.0 (#299)
hugegraph-toolchain
API Changes
- feat(client): support edgeExistence api (#544)
- refact(client): update tests for new OLTP traverser APIs (#550)
Feature Changes
- feat(spark): support spark-sink connector for loader (#497)
- feat(loader): support kafka as datasource (#506)
- feat(client): support go client for hugegraph (#514)
- feat(loader): support docker for loader (#530)
- feat: update common version and remove jersey code (#538)
Bug Fix
- fix: convert numbers to strings (#465)
- fix: hugegraph-spark-loader shell string length limit (#469)
- fix: spark loader meet Exception: Class is not registered (#470)
- fix: spark loader Task not serializable (#471)
- fix: spark with loader has dependency conflicts (#480)
- fix: spark-loader example schema and struct mismatch (#504)
- fix(loader): error log (#499)
- fix: checkstyle && add suppressions.xml (#500)
- fix(loader): resolve error in loader script (#510)
- fix: base-ref/head-ref missed in dependency-check-ci on branch push (#516, #551)
- fix yarn network connection on linux/arm64 arch (#519)
- fix(hubble): drop-down box could not display all options (#535)
- fix(hubble): build with node and yarn (#543)
- fix(loader): loader options (#548)
- fix(hubble): parent override children dep version (#549)
- fix: exclude okhttp1 which has different groupID with okhttp3 (#555)
- fix: github action build docker image failed (#556, #557)
- fix: build error with npm not exist & tiny improve (#558)
Option Changes
- set default data when create graph (#447)
Other Changes
- chore: remove apache stage repo & update mail rule (#433, #474, #479)
- refact: clean extra store file in all modules (#434)
- chore: use fixed node.js version 16 to avoid ci problem (#437, #441)
- chore(hubble): use latest code in Dockerfile (#440)
- chore: remove maven plugin for docker build (#443)
- chore: improve spark parallel (#450)
- doc: fix build status badge link (#455)
- chore: keep hadoop-hdfs-client and hadoop-common version consistent (#457)
- doc: add basic contact info & QR code in README (#462, #475)
- chore: disable PR up-to-date in branch (#473)
- chore: auto add pr auto label by path (#466, #528)
- chore: unify the dependencies versions of the entire project (#478)
- chore(deps): bump async, semver, word-wrap, browserify-sign in hubble-fe (#484, #491, #494, #529)
- chore: add pr template (#498)
- doc(hubble): add docker-compose to start with server (#522)
- chore(ci): add stage profile settings (#536)
- chore(client): increase the api num as the latest server commit + 10 (#546)
- chore(spark): install hugegraph from source (#552)
- doc: adjust docker related desc in readme (#559)
- chore(license): update license for 1.2 (#560, #561)
hugegraph-commons
Feature Changes
- feat(common): replace jersey dependencies with OkHttp (Breaking Change) (#133)
Bug Fix
- fix(common): handle spring-boot2/jersey dependency conflicts (#131)
- fix: Assert.assertThrows() should check result of exceptionConsumer (#135)
- fix(common): json param convert (#137)
Other Changes
- refact(common): add more construction methods for convenient (#132)
- add: dependency-review (#134)
- refact(common): rename jsonutil to avoid conflicts with server (#136)
- doc: update README for release (#138)
- update licence (#139)
Release Details
Please check the release details in each repository:
10.3 - HugeGraph 1.3.0 Release Notes
Operating Environment / Version Description
- consider using Java 11 in
hugegraph/toolchain/commons, also compatible with Java 8 now. hugegraph-computerrequired to use Java 11, not compatible with Java 8!- Using Java8 may loss some security ensured, we recommend using Java 11 in production env with AuthSystem enabled.
1.3.0 is the last major version compatible with Java 8, compatibility with Java 8 will end in
next release(1.5.0) when PD/Store merged into
master branch (Except for the java-client).
PS: In the future, we will gradually upgrade the java version from Java 11 -> Java 17 -> Java 21.
hugegraph
In this version, we have fixed some SEC-related issues. If used in an online service or exposed to the public, please upgrade to the latest version and enable authorization authentication
API Changes
- feat(api): optimize adjacent-edges query (#2408)
Feature Changes
- feat: support docker use the auth when starting (#2403)
- feat: added the OpenTelemetry trace support (#2477)
Bug Fix
- fix(core): task restore interrupt problem on restart server (#2401)
- fix(server): reinitialize the progress to set up graph auth friendly (#2411)
- fix(chore): remove zgc in dockerfile for ARM env (#2421)
- fix(server): make CacheManager constructor private to satisfy the singleton pattern (#2432)
- fix(server): unify the license headers (#2438)
- fix: format and clean code in dist and example modules (#2441)
- fix: format and clean code in core module (#2440)
- fix: format and clean code in modules (#2439)
- fix(server): clean up the code (#2456)
- fix(server): remove extra blank lines (#2459)
- fix(server): add tip for gremlin api NPE with an empty query (#2467)
- fix(server): fix the metric name when promthus collects hugegraph metric, see issue (#2462)
- fix(server):
serverStartederror when execute gremlin example (#2473) - fix(auth): enhance the URL check (#2422)
Option Changes
- refact(server): enhance the storage path in RocksDB & clean code (#2491)
Other Changes
- chore: add a license link (#2398)
- doc: enhance NOTICE info to keep it clear (#2409)
- chore(server): update swagger info for default server profile (#2423)
- fix(server): unify license header for protobuf file (#2448)
- chore: improve license header checker confs and pre-check header when validating (#2445)
- chore: unify to call SchemaLabel.getLabelId() (#2458)
- chore: refine the hg-style.xml specification (#2457)
- chore: Add a newline formatting configuration and a comment for warning (#2464)
- chore(server): clear context after req done (#2470)
hugegraph-toolchain
API Changes
Feature Changes
- fix(loader): update shade plugin for spark loader (#566)
- fix(hubble): yarn install timeout in arm64 (#583)
- fix(loader): support file name with prefix for hdfs source (#571)
- feat(hubble): warp the exception info in HugeClientUtil (#589)
Bug Fix
- fix: concurrency issue causing file overwrite due to identical filenames (#572)
Option Changes
- feat(client): support user defined OKHTTPClient configs (#590)
Other Changes
- doc: update copyright date(year) in NOTICE (#567)
- chore(deps): bump ip from 1.1.5 to 1.1.9 in /hugegraph-hubble/hubble-fe (#580)
- refactor(hubble): enhance maven front plugin (#568)
- chore(deps): bump es5-ext from 0.10.53 to 0.10.63 in /hugegraph-hubble/hubble-fe (#582)
- chore(hubble): Enhance code style in hubble (#592)
- chore: upgrade version to 1.3.0 (#596)
- chore(ci): update profile commit id for 1.3 (#597)
hugegraph-commons
Feature Changes
- feat: support user defined RestClientConfig/HTTPClient params (#140)
Bug Fix
Other Changes
- chore: disable clean flatten for deploy (#141)
hugegraph-ai
This is the first release version of hugegraph-ai, it contains a variety of features, including an initialized Python client, knowledge graph construction capabilities through LLM, and the integration of RAG based on HugeGraph.
It also adds significant functionalities on python-client such as variable APIs, auth, metric, traverser, and task APIs, as well as interactive and visual demo creation with Gradio. In addition to these features, the release addresses several bugs and issues, ensuring a more stable and error-free user experience. Maintenance tasks such as dependency updates, project structure improvements, and the addition of basic CI further enhance the project’s robustness and developer workflow.
This release encapsulates the collaborative efforts of the HugeGraph community, with contributions from various members, ensuring the project’s continuous growth and improvement.
Feature Changes
- feat: initialize hugegraph python client (#5)
- feat(llm): knowledge graph construction by llm (#7)
- feat: initialize rag based on HugeGraph (#20)
- feat(client): add variables api and test (#24)
- feat: add llm wenxinyiyan & config util & spo_triple_extract (#27)
- feat: add auth&metric&traverser&task api and ut (#28)
- feat: refactor construct knowledge graph task (#29)
- feat: Introduce gradio for creating interactive and visual demo (#30)
Bug Fix
- fix: invalid GitHub label (#3)
- fix: import error (#13)
- fix: function getEdgeByPage(): the generated query url does not include the parameter page (#15)
- fix: issue template (#23)
- fix: base-ref/head-ref missed in dependency-check-ci on branch push (#25)
Other Changes
- chore: add asf.yaml and ISSUE_TEMPLATE (#1)
- Bump urllib3 from 2.0.3 to 2.0.7 in /hugegraph-python (#8)
- chore: create .gitignore file for py (#9)
- refact: improve project structure & add some basic CI (#17)
- chore: Update LICENSE and NOTICE (#31)
- chore: add release scripts (#33)
- chore: change file chmod 755 (#34)
Release Details
Please check the release details/contributor in each repository:
10.4 - HugeGraph 1.5.0 Release Notes
WIP: This doc is under construction, please wait for the final version (BETA)
Operating Environment / Version Description
- From
hugegraphversion 1.5.0 and later, related components only support Java11.
PS: In the future, HugeGraph components will evolve through versions of Java 11 -> Java 17 -> Java 21.
hugegraph
This version introduces many new features and optimizations, particularly support for the new distributed backend HStore(Raft + RocksDB).
API Changes
- BREAKING CHANGE: Support “parent & child”
EdgeLabeltype #2662
Feature Changes
- Integrate
pd-grpc,pd-common, andpd-client#2498 - Integrate
store-grpc,store-common, andstore-client#2476 - Integrate
store-rocksdbsubmodule #2513 - Integrate
pd-coreinto HugeGraph #2478 - Integrate
pd-serviceinto HugeGraph #2528 - Integrate
pd-distinto HugeGraph and add core tests, client tests, and REST tests for PD #2532 - Integrate
server-hstoreinto HugeGraph #2534 - Integrate
store-coresubmodule #2548 - Integrate
store-nodesubmodule #2537 - Support new backend Hstore #2560
- Support Docker deployment for PD and Store #2573
- Add a tool method
encode#2647 - Add basic
MiniClustermodule for distributed system testing #2615 - Support disabling RocksDB auto-compaction via configuration #2586
Bug Fixes
- Switch RocksDB backend to memory when executing Gremlin examples #2518
- Avoid overriding backend config in Gremlin example scripts #2519
- Update resource references #2522
- Randomly generate default values #2568
- Update build artifact path for Docker deployment #2590
- Ensure thread safety for range attributes in PD #2641
- Correct server Docker copy source path #2637
- Fix JRaft Timer Metrics bug in Hstore #2602
- Enable JRaft MaxBodySize configuration #2633
Option Changes
- Mark old raft configs as deprecated #2661
- Enlarge bytes write limit and remove
bigparameter when encoding/decoding string ID length #2622
Other Changes
- Add Swagger-UI LICENSE files #2495
- Translate CJK comments and punctuations to English across multiple modules #2536, #2623, #2645
- Introduce
install-distmodule in root #2552 - Enable up-to-date checks for UI (CI) #2609
- Minor improvements for POM properties #2574
- Migrate HugeGraph Commons #2628
- Tar source and binary packages for HugeGraph with PD-Store #2594
- Refactor: Enhance cache invalidation of the partition → leader shard in
ClientCache#2588 - Refactor: Remove redundant properties in
LogMetaandPartitionMeta#2598
hugegraph-toolchain
API Changes
- Support “parent & child”
EdgeLabeltype #624
Feature Changes
- Support English interface & add a script/doc for it in Hubble #631
Bug Fixes
- Serialize source and target label for non-father EdgeLabel #628
- Encode/decode Chinese error after building Hubble package #627
- Configure IPv4 to fix timeout of
yarn installin Hubble #636 - Remove debugging output to speed up the frontend construction in Hubble #638
Other Changes
- Bump
expressfrom 4.18.2 to 4.19.2 in Hubble Frontend #598 - Make IDEA support IssueNavigationLink #600
- Update
yarn.lockfor Hubble #605 - Introduce
editorconfig-maven-pluginfor verifying code style defined in.editorconfig#614 - Upgrade distribution version to 1.5.0 #639
Documentation Changes
- Clarify the contributing guidelines #604
- Enhance the README file for Hubble #613
- Update README style referring to the server’s style #615
hugegraph-ai
API Changes
- Added local LLM API and version API. #41, #44
- Implemented new API and optimized code structure. #63
- Support for graphspace and refactored all APIs. #67
Feature Changes
- Added openai’s apibase configuration and asynchronous methods in RAG web demo. #41, #58
- Support for multi reranker and enhanced UI. #73
- Node embedding, node classify, and graph classify with models based on DGL. #83
- Graph learning algorithm implementation (10+). #102
- Support for any openai-style API (standard). #95
Bug Fixes
- Fixed fusiform_similarity test in traverser for server 1.3.0. #37
- Avoid generating config twice and corrected e_cache type. #56, #117
- Fixed null value detection on vid attributes. #115
- Handled profile regenerate error. #98
Option Changes
- Added auth for fastapi and gradio. #70
- Support for multiple property types and importing graph from the entire doc. #84
Other Changes
- Reformatted documentation and updated README. #36, #81
- Introduced a black for code format in GitHub actions. #47
- Updated dependencies and environment preparations. #45, #65
- Enhanced user-friendly README. #82
hugegraph-computer
Feature Changes
Bug Fixes
- Fix: base-ref/head-ref Missed in Dependency-Review on Schedule Push #304
Option Changes
- Refactor(core): StringEncoding #300
Other Changes
- Improve(algorithm): Random Walk Vertex Inactive #301
- Upgrade Version to 1.3.0 #305
- Doc(readme): Clarify the Contributing Guidelines #306
- Doc(readme): Add Hyperlink to Apache 2.0 #308
- Migrate Project to Computer Directory #310
- Update for Release 1.5 #317
- Fix Path When Exporting Source Package #319
Release Details
Please check the release details/contributor in each repository:
10.5 - HugeGraph 1.7.0 Release Notes
WIP: This doc is under construction, please wait for the final version (BETA)
Operating Environment / Version Description
For 1.7.0 version hugegraph, related components only support Java11.
hugegraph
API Changes
- BREAKING CHANGE: Disable legacy backends include MySQL/PG/c*(.etc) #2746
- BREAKING CHANGE: Release version 1.7.0 [server + pd + store] #2889
Feature Changes
- Support MemoryManagement for graph query framework #2649
- LoginAPI support token_expire field #2754
- Add option for task role election #2843
- Optimize perf by avoid boxing long #2861
- StringId hold bytes to avoid decode/encode #2862
- Add PerfExample5 and PerfExample6 #2860
- RocksDBStore remove redundant checkOpened() call #2863
- Add path filter #2898
- Init serena memory system & add memories #2902
Bug Fixes
- Filter dynamice path(PUT/GET/DELETE) with params cause OOM #2569
- JRaft Histogram Metrics Value NaN #2631
- Update server image desc #2702
- Kneigbor-api has unmatched edge type with server #2699
- Add license for swagger-ui & reset use stage to false in ci yml #2706
- Fix build pd-store arm image #2744
- Fix graph server cache notifier mechanism #2729
- Tx leak when stopping the graph server #2791
- Ensure backend is initialized in gremlin script #2824
- Fix some potential lock & type cast issues #2895
- Fix npe in getVersion #2897
- Fix the support for graphsapi in rocksdb and add testing for graphsapi #2900
- Remove graph path in auth api path #2899
- Migrate to LTS jdk11 in all Dockerfile #2901
- Remove the judgment for java8 compatibility in the init-store #2905
- Add missing license and remove binary license.txt & fix tinkerpop ci & remove duplicate module #2910
Option Changes
- Remove some outdated configuration #2678
Other Changes
- Update outdated docs for release 1.5.0 #2690
- Fix licenses and remove empty files #2692
- Update repo artifacts references #2695
- Adjust release fury version #2698
- Fix the JSON license issue #2697
- Add debug info for tp test #2688
- Enhance words in README #2734
- Add collaborators in asf config #2741
- Adjust the related filters of sofa-bolt #2735
- Reopen discussion in .asf.yml config #2751
- Fix typo in README #2806
- Centralize version management in project #2797
- Update notice year #2826
- Improve maven Reproducible Builds → upgrade plugins #2874
- Enhance docker instruction with auth opened graph #2881
- Remove the package existing in java8 #2792
- Revise Docker usage instructions in README #2882
- Add DeepWiki badge to README #2883
- Update guidance for store module #2894
- Update test commands and improve documentation clarity #2893
- Bump rocksdb version from 7.2.2 to 8.10.2 #2896
hugegraph-toolchain
API Changes
- Support graphspace #633
Feature Changes
- Support jdbc date type & sync .editorconfig #648
- Add a useSSL option for mysql #650
- Patch for father sub edge #654
- Improve user experience for user script #666
- Support concurrent readers, short-id & Graphsrc #683
- Init serena onboarding & project memory files #692
Bug Fixes
- Typo word in display #655
- Patch up missing classes and methods for hubble #657
- Adjust Client to 1.7.0 server #689
- Remove json license for release 1.7.0 #698
Other Changes
- Update hugegraph source commit id #640
- Add collaborators in asf config #656
- Update pom for version-1.7.0 #681
- Add DeepWiki badge to README #684
- Adjust APIs to compatible with 1.7.0 server #685
- Adjust LoadContext to 1.7.0 version #687
- Migrate to LTS jdk11 in all Dockerfile #691
- Update copyright year in NOTICE file #697
hugegraph-computer
Feature Changes
- Migration Vermeer to hugegraph-computer #316
- Make startChan’s size configurable #328
- Assign WorkerGroup via worker configuration #332
- Support task priority based scheduling #336
- Avoid 800k #340
Bug Fixes
- Fix docker file build #341
Other Changes
- Update release version to 1.5.0 #318
- Update go depends module & fix headers #321
- Update go version to 1.23 #322
- Add collaborator in .asf.yaml #323
- Update the Go version in docker image #333
- Add DeepWiki badge to README #337
- Bump project version to 1.7.0 (RELEASE) #338
- Update copyright year in NOTICE file #342
hugegraph-ai
API Changes
- Support choose template in api #135
- Add post method for paths-api #162
- Support switch graph in api & add some query configs #184
- Text2gremlin api #258
- Support switching prompt EN/CN #269
- BREAKING CHANGE: Update keyword extraction method #282
Feature Changes
- Added the process of text2gql in graphrag V1.0 #105
- Use pydantic-settings for config management #122
- Timely execute vid embedding & enhance some HTTP logic #141
- Use retry from tenacity #143
- Modify the summary info and enhance the request logic #147
- Automatic backup graph data timely #151
- Add a button to backup data & count together #153
- Extract topk_per_keyword & topk_return_results to .env #154
- Modify clear buttons #156
- Support intent recognition V1 #159
- Change vid embedding x:yy to yy & use multi-thread #158
- Support mathjax in rag query block V1 #157
- Use poetry to manage the dependencies #149
- Return schema.groovy first when backup graph data #161
- Merge all logs into one file #171
- Use uv for the CI action #175
- Use EN prompt for keywords extraction #174
- Support litellm LLM provider #178
- Improve graph extraction default prompt #187
- Replace vid by full vertexes info #189
- Support asynchronous streaming generation in rag block by using async_generator and asyncio.wait #190
- Generalize the regex extraction func #194
- Create quick_start.md #196
- Support Docker & K8s deployment way #195
- Multi-stage building in Dockerfile #199
- Support graph checking before updating vid embedding #205
- Disable text2gql by default #216
- Use 4.1-mini and 0.01 temperature by default #214
- Enhance the multi configs for LLM #212
- Textbox to Code #217
- Replace the IP + Port with URL #209
- Update gradio’s version #235
- Use asyncio to get embeddings #215
- Change QPS -> RPM for timer decorator #241
- Support batch embedding #238
- Using nuitka to provide a binary/perf way for the service #242
- Use uv instead poetry #226
- Basic compatible in text2gremlin generation #261
- Enhance config path handling and add project root validation #262
- Add vermeer python client for graph computing #263
- Use uv in client & ml modules & adapter the CI #257
- Use uv to manage pkgs & update README #272
- Limit the deps version to handle critical init problems #279
- Support semi-automated prompt generation #281
- Support semi-automated generated graph schema #274
- Unify all modules with uv #287
- Add GitHub Actions for auto upstream sync and update SEALData subsample logic #289
- Add a basic LLM/AI coding instruction file #290
- Add rules for AI coding guideline - V1.0 #293
- Replace QianFan by OpenAI-compatible format #285
- Optimize vector index with asyncio embedding #264
- Refactor embedding parallelization to preserve order #295
- Support storing vector data for a graph instance by model type/name #265
- Add AGENTS.md as new document standard #299
- Add Fixed Workflow Execution Engine: Flow, Node, and Scheduler Architecture #302
- Support vector db layer V1.0 #304
Bug Fixes
- Limit the length of log & improve the format #121
- Pylint in ml #125
- Critical bug with pylint usage #131
- Multi vid k-neighbor query only return the data of first vid #132
- Replace getenv usage to settings #133
- Correct header writing errors #140
- Update prompt to fit prefix cache #137
- Extract_graph_data use wrong method #145
- Use empty str for llm config #155
- Update gremlin generate prompt to apply fuzzy match #163
- Enable fastapi auto reload function #164
- Fix tiny bugs & optimize reranker layout #202
- Enable tasks concurrency configs in Gradio #188
- Align regex extraction of json to json format of prompt #211
- Fix documentation sample code error #219
- Failed to remove vectors when updating vid embedding #243
- Skip empty chunk in LLM steaming mode #245
- Ollama batch embedding bug #250
- Fix Dockerfile to add pyproject.toml anchor file #266
- Add missing ‘properties’ in gremlin prompt formatting #298
- Fixed cgraph version #305
- Ollama embedding API usage and config param #306
Option Changes
- Remove enable_gql logic in api & rag block #148
Other Changes
- Update README for python-client/SDK #150
- Enable pip cache #142
- Enable discussion & change merge way #201
- Synchronization with official documentation #273
- Fix grammar errors #275
- Improve README clarity and deployment instructions #276
- Add docker-compose deployment and improve container networking instructions #280
- Update docker compose command #283
- Reduce third-party library log output #244
- Update README with improved setup instructions #294
- Add collaborators in asf config #182
Release Details
Please check the release details/contributor in each repository:
11 - Apache Contributor Agreements
Apache Contributor Agreements
HugeGraph uses the standard Apache Software Foundation (ASF) contributor agreements. It no longer uses a project-specific CLA or the GitHub CLA Assistant workflow.
Routine, small contributions are submitted under Section 5 of the Apache License 2.0. Before becoming a committer, or when making a substantial contribution, you must sign the ASF Individual Contributor License Agreement (ICLA). If a company owns the intellectual property in your contribution, a Corporate Contributor License Agreement (CCLA) may also be required; a CCLA does not replace your individual ICLA.
Refer to the official ASF pages for the agreement text, completion instructions, and submission process:
After reading and signing the agreement as instructed, send the completed file as a standalone attachment to secretary@apache.org. Do not send it to the HugeGraph developer mailing list or commit it to a GitHub repository.