This is the multi-page printable view of this section. .
Quick Start
- 1: HugeGraph (OLTP)
- 2: HugeGraph ToolChain
- 3: HugeGraph-AI
- 3.1: HugeGraph-LLM
- 3.2: HugeGraph-ML
- 3.3: HugeGraph-LLM Workflow
- 3.4: Configuration Reference
- 3.5: HugeGraph-LLM REST API
- 4: HugeGraph Computing (OLAP)
- 5: HugeGraph Client
Choose the quick-start guide for Server, Toolchain, graph computing, or HugeGraph-AI according to your needs. Each component is released independently, so check the runtime requirements and version of the corresponding repository before installation.
1 - HugeGraph (OLTP)
🚀 Best practice: Prioritize using DeepWiki intelligent documents
To address the issue of outdated static documents, we provide DeepWiki with real-time updates and more comprehensive content. It is equivalent to an expert with the latest knowledge of the project, which is very suitable for all developers to read and consult before starting the project.
👉 Strongly recommend visiting and having a conversation with: incubator-hugegraph
1.1 - HugeGraph Server Quick Start
1 HugeGraph Server Overview
apache/hugegraph is the main repository for the HugeGraph graph database. Its top-level modules include hugegraph-server, hugegraph-pd, and hugegraph-store. This page describes the hugegraph-server module and the service it runs.
The hugegraph-server module contains hugegraph-core, hugegraph-api, hugegraph-dist, and storage adapters. Core implements the property graph model, transactions, and TinkerPop interfaces. API provides the HTTP service and delegates client requests to Core. Graph data is stored in RocksDB (the default standalone backend), HStore (distributed), or HBase.
⚠️ Version note: This page follows HugeGraph 1.7.0 through the
masterbranch and covers only RocksDB, HStore, and HBase. For other legacy backends and their configuration, see the HugeGraph 1.5.x documentation.
Naming:
HugeGraphmeans the overall project or main repository,hugegraph-serveris the Server module in that repository, andHugeGraphServeris the Java class for the service process. This page uses “Server service” for a running graph database service.
2 Dependency for Building/Running
2.1 Install Java 11 (JDK 11)
The hugegraph-server module in HugeGraph 1.7.0 is compiled with Java 11. Running and building it from source require Java 11 or later.
Before continuing, run java -version to confirm your JDK version.
Java 8 is no longer supported starting from 1.7.0.
3 Deploy
There are four ways to deploy the Server service:
- Method 1: Use Docker container (Convenient for Test/Dev)
- Method 2: Download the binary tarball
- Method 3: Source code compilation
- Method 4: One-click deployment
Do not expose Gremlin, Cypher, or other query endpoints directly to the public Internet. In production, enable authentication and authorization, restrict network access, and retain audit logs. See the Security Guide for deployment guidance.
3.1 Use Docker container (Convenient for Test/Dev)
You can refer to the Docker deployment guide.
You can use docker run -itd --name=server -p 8080:8080 -e PASSWORD=xxx hugegraph/hugegraph:1.7.0 to quickly start a Server instance using the RocksDB backend.
Optional:
- You can use
docker exec -it server bashto enter the container for troubleshooting or other maintenance operations. - You can use
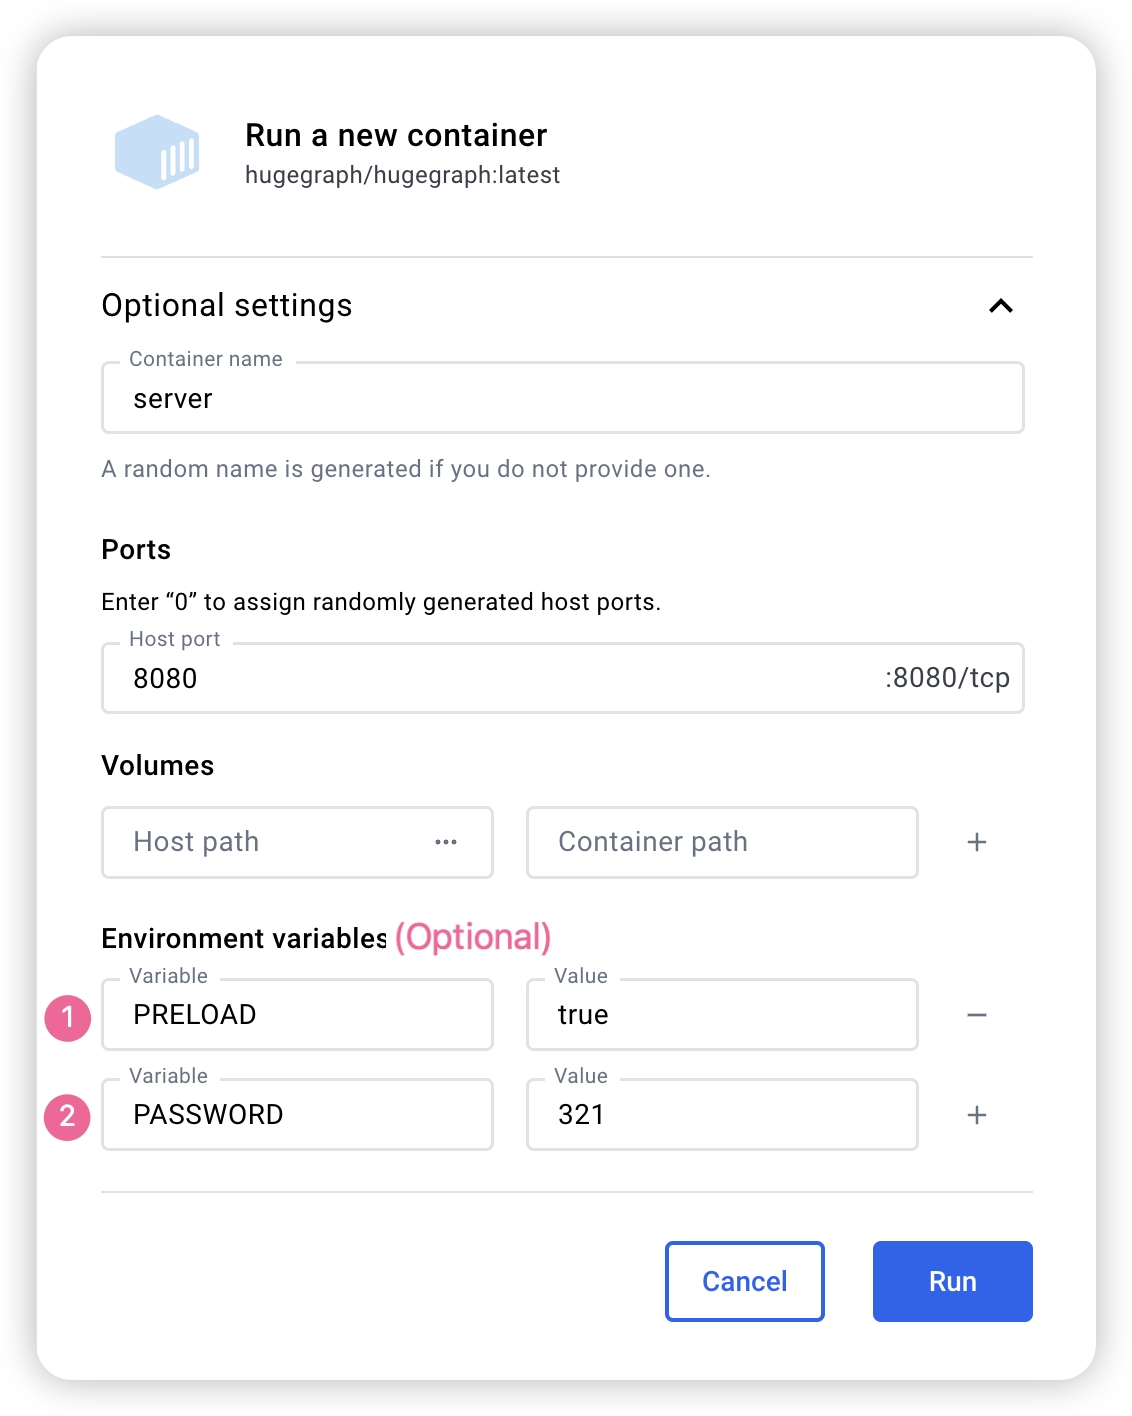
docker run -itd --name=server -p 8080:8080 -e PRELOAD="true" hugegraph/hugegraph:1.7.0to preload a built-in sample graph at startup. You can verify it through theRESTful API. See 5.1.4 for details. - You can use
-e PASSWORD=xxxto enable authentication mode and set the admin password. See Config Authentication for details.
If you use Docker Desktop, you can set the options as follows:
Note: The Docker Compose files use bridge networking (
hg-net) and work on Linux and Mac (Docker Desktop). For the 3-node distributed cluster on Mac (Docker Desktop), allocate at least 12 GB of memory (Settings → Resources → Memory). On Linux, Docker uses host memory directly.
If you want a single, unified setup for multiple HugeGraph services, you can use docker compose.
Two compose files are available in the docker/ directory:
- Single-node quickstart (pre-built images):
docker/docker-compose.yml - Single-node dev build (build from source):
docker/docker-compose.dev.yml
To enable authentication, add PASSWORD=xxx to the service environment in the compose file or pass -e PASSWORD=xxx to docker run.
See docker/README.md for the full setup guide.
Note:
HugeGraph Docker images are provided as a convenient way to start HugeGraph quickly, but they are not official ASF distribution artifacts. You can find more details in the ASF Release Distribution Policy.
We recommend using a release tag (such as
1.7.0or1.x.0) for stable deployments. Use thelatesttag only if you want the newest features still under development.
3.2 Download the binary tarball
You could download the binary tarball from the download page of the ASF site like this:
3.3 Source code compilation
Please ensure that the wget/curl commands are installed before compiling the source code
Download HugeGraph source code in either of the following 2 ways (so as the other HugeGraph repos/modules):
- download the stable/release version from the ASF site
- clone the unstable/latest version by GitBox(ASF) or GitHub
Compile and generate tarball
A successful build includes the following line:
After a successful build, the generated distribution is the *hugegraph-*.tar.gz file in the repository root.
3.4 One-click deployment (Outdated)
HugeGraph-Tools provides a one-click deployment command that downloads, extracts, configures, and starts the Server service and HugeGraph-Hubble. These tools are included in the HugeGraph-Toolchain distribution.
Of course, you should download the tarball of HugeGraph-Toolchain first.
note:
${version}is the version, The latest version can refer to Download Page, or click the link to download directly from the Download page
The general entry script for HugeGraph-Tools is bin/hugegraph, Users can use the help command to view its usage, here only the commands for one-click deployment are introduced.
{hugegraph-version} is the Server service and HugeGraphStudio version; see conf/version-mapping.yaml for supported mappings. {install-path} is the installation directory, while {download-path-prefix} optionally overrides the tarball download location. For example, deploy version 0.6 with bin/hugegraph deploy -v 0.6 -p services.
4 Config
If you need to quickly start HugeGraph just for testing, then you only need to modify a few configuration items (see next section). For detailed configuration introduction, please refer to configuration document and introduction to configuration items
5 Startup
5.1 Use a startup script to startup
Startup is divided into “first startup” and “non-first startup”. On the first startup, you need to initialize the backend database before starting the service.
If the service was stopped manually, or needs to be started again for any other reason, you can usually start it directly because the backend database is persistent.
When HugeGraphServer starts, it connects to the backend storage and checks its version information. If the backend has not been initialized, or if it was initialized with an incompatible version (for example, old-version data), HugeGraphServer will fail to start and report an error.
If you need to access HugeGraphServer externally, modify the restserver.url configuration item in rest-server.properties (the default is http://127.0.0.1:8080) and change it to the machine name or IP address.
Since the configuration (hugegraph.properties) and startup steps required by various backends are slightly different, the following will introduce the configuration and startup of each backend one by one.
Note: Configure Server Authentication before starting HugeGraphServer if you need Auth mode (especially for production or public network environments).
5.1.1 Distributed Storage (HStore)
Distributed storage is a new feature introduced after HugeGraph 1.5.0, which implements distributed data storage and computation based on HugeGraph-PD and HugeGraph-Store components.
To use the distributed storage engine, you need to deploy HugeGraph-PD and HugeGraph-Store first. See HugeGraph-PD Quick Start and HugeGraph-Store Quick Start.
After ensuring that both PD and Store services are started, modify the hugegraph.properties configuration of HugeGraph-Server:
Then enable PD discovery in rest-server.properties (required for every HugeGraph-Server node):
If configuring multiple HugeGraph-Server nodes, you need to modify the rest-server.properties configuration file for each node, for example:
Node 1 (Master node):
Node 2 (Worker node):
Also, you need to modify the port configuration in gremlin-server.yaml for each node:
Node 1:
Node 2:
Initialize the database:
Start the Server:
The startup sequence for using the distributed storage engine is:
- Start HugeGraph-PD
- Start HugeGraph-Store
- Initialize the database (only for the first time)
- Start HugeGraph-Server
Verify that the service is started properly:
The sequence to stop the services should be the reverse of the startup sequence:
- Stop HugeGraph-Server
- Stop HugeGraph-Store
- Stop HugeGraph-PD
Docker Distributed Cluster
Run the full distributed cluster (3 PD + 3 Store + 3 Server) with Docker Compose:
Services communicate via container hostnames on the hg-net bridge network. Configuration is injected via environment variables:
Verify the cluster:
To view runtime logs for any container use docker logs <container-name> (e.g. docker logs hg-pd0).
See docker/README.md for the full environment variable reference, port table, and troubleshooting guide.
5.1.2 RocksDB / ToplingDB
RocksDB is an embedded database that does not require manual installation and deployment. GCC version >= 4.3.0 (GLIBCXX_3.4.10) is required. If not, GCC needs to be upgraded in advance
Update hugegraph.properties
Initialize the database (required on the first startup, or a new configuration was manually added under ‘conf/graphs/’)
Start server
ToplingDB (Beta): As a high-performance alternative to RocksDB, please refer to the configuration guide: ToplingDB Quick Start
5.1.3 HBase
users need to install HBase by themselves, requiring version 2.0 or above,download link
Update hugegraph.properties
Initialize the database (required on the first startup, or a new configuration was manually added under ‘conf/graphs/’)
Start server
5.1.4 Create an example graph when startup
Pass the -p true argument when starting the script to enable preload, which creates a sample graph.
And use the RESTful API to request HugeGraphServer and get the following result:
This indicates the successful creation of the sample graph.
5.2 Use Docker to startup
In 3.1 Use Docker container, we introduced how to deploy hugegraph-server with Docker. You can also switch storage backends or preload a sample graph by setting the corresponding parameters.
5.2.1 Create an example graph when starting a server
Set the environment variable PRELOAD=true when starting Docker so that sample data is loaded during startup.
Use
docker runUse
docker run -itd --name=server -p 8080:8080 -e PRELOAD=true hugegraph/hugegraph:1.7.0Use
docker-composeCreate a
docker-compose.ymlfile like the following and setPRELOAD=truein the environment.example.groovyis a predefined script used to preload sample data. If needed, you can mount a newexample.groovyscript to change the preload data.Use
docker-compose up -dto start the container.
And use the RESTful API to request HugeGraphServer and get the following result:
This indicates that the sample graph was created successfully.
6. Access server
6.1 Service startup status check
Use jps to see a service process
curl request RESTfulAPI
Return 200, which means the server starts normally.
6.2 Request Server
The RESTful API of HugeGraphServer includes various types of resources, typically including graph, schema, gremlin, traverser and task.
graphcontainsvertices、edgesschemacontainsvertexlabels、propertykeys、edgelabels、indexlabelsgremlincontains variousGremlinstatements, such asg.v(), which can be executed synchronously or asynchronouslytraversercontains various advanced queries including shortest paths, intersections, N-step reachable neighbors, etc.taskcontains query and delete with asynchronous tasks
6.2.1 Get vertices and its related properties in hugegraph
explanation
Since there are many vertices and edges in the graph, for list-type requests, such as getting all vertices, getting all edges, etc., the server will compress the data and return it, so when use curl, you get a bunch of garbled characters, you can redirect to gunzip for decompression. It is recommended to use the Chrome browser + Restlet plugin to send HTTP requests for testing.
The current default configuration of HugeGraphServer can only be accessed locally, and the configuration can be modified so that it can be accessed on other machines.
response body:
For the detailed API, please refer to RESTful-API
You can also visit localhost:8080/swagger-ui/index.html to check the API.
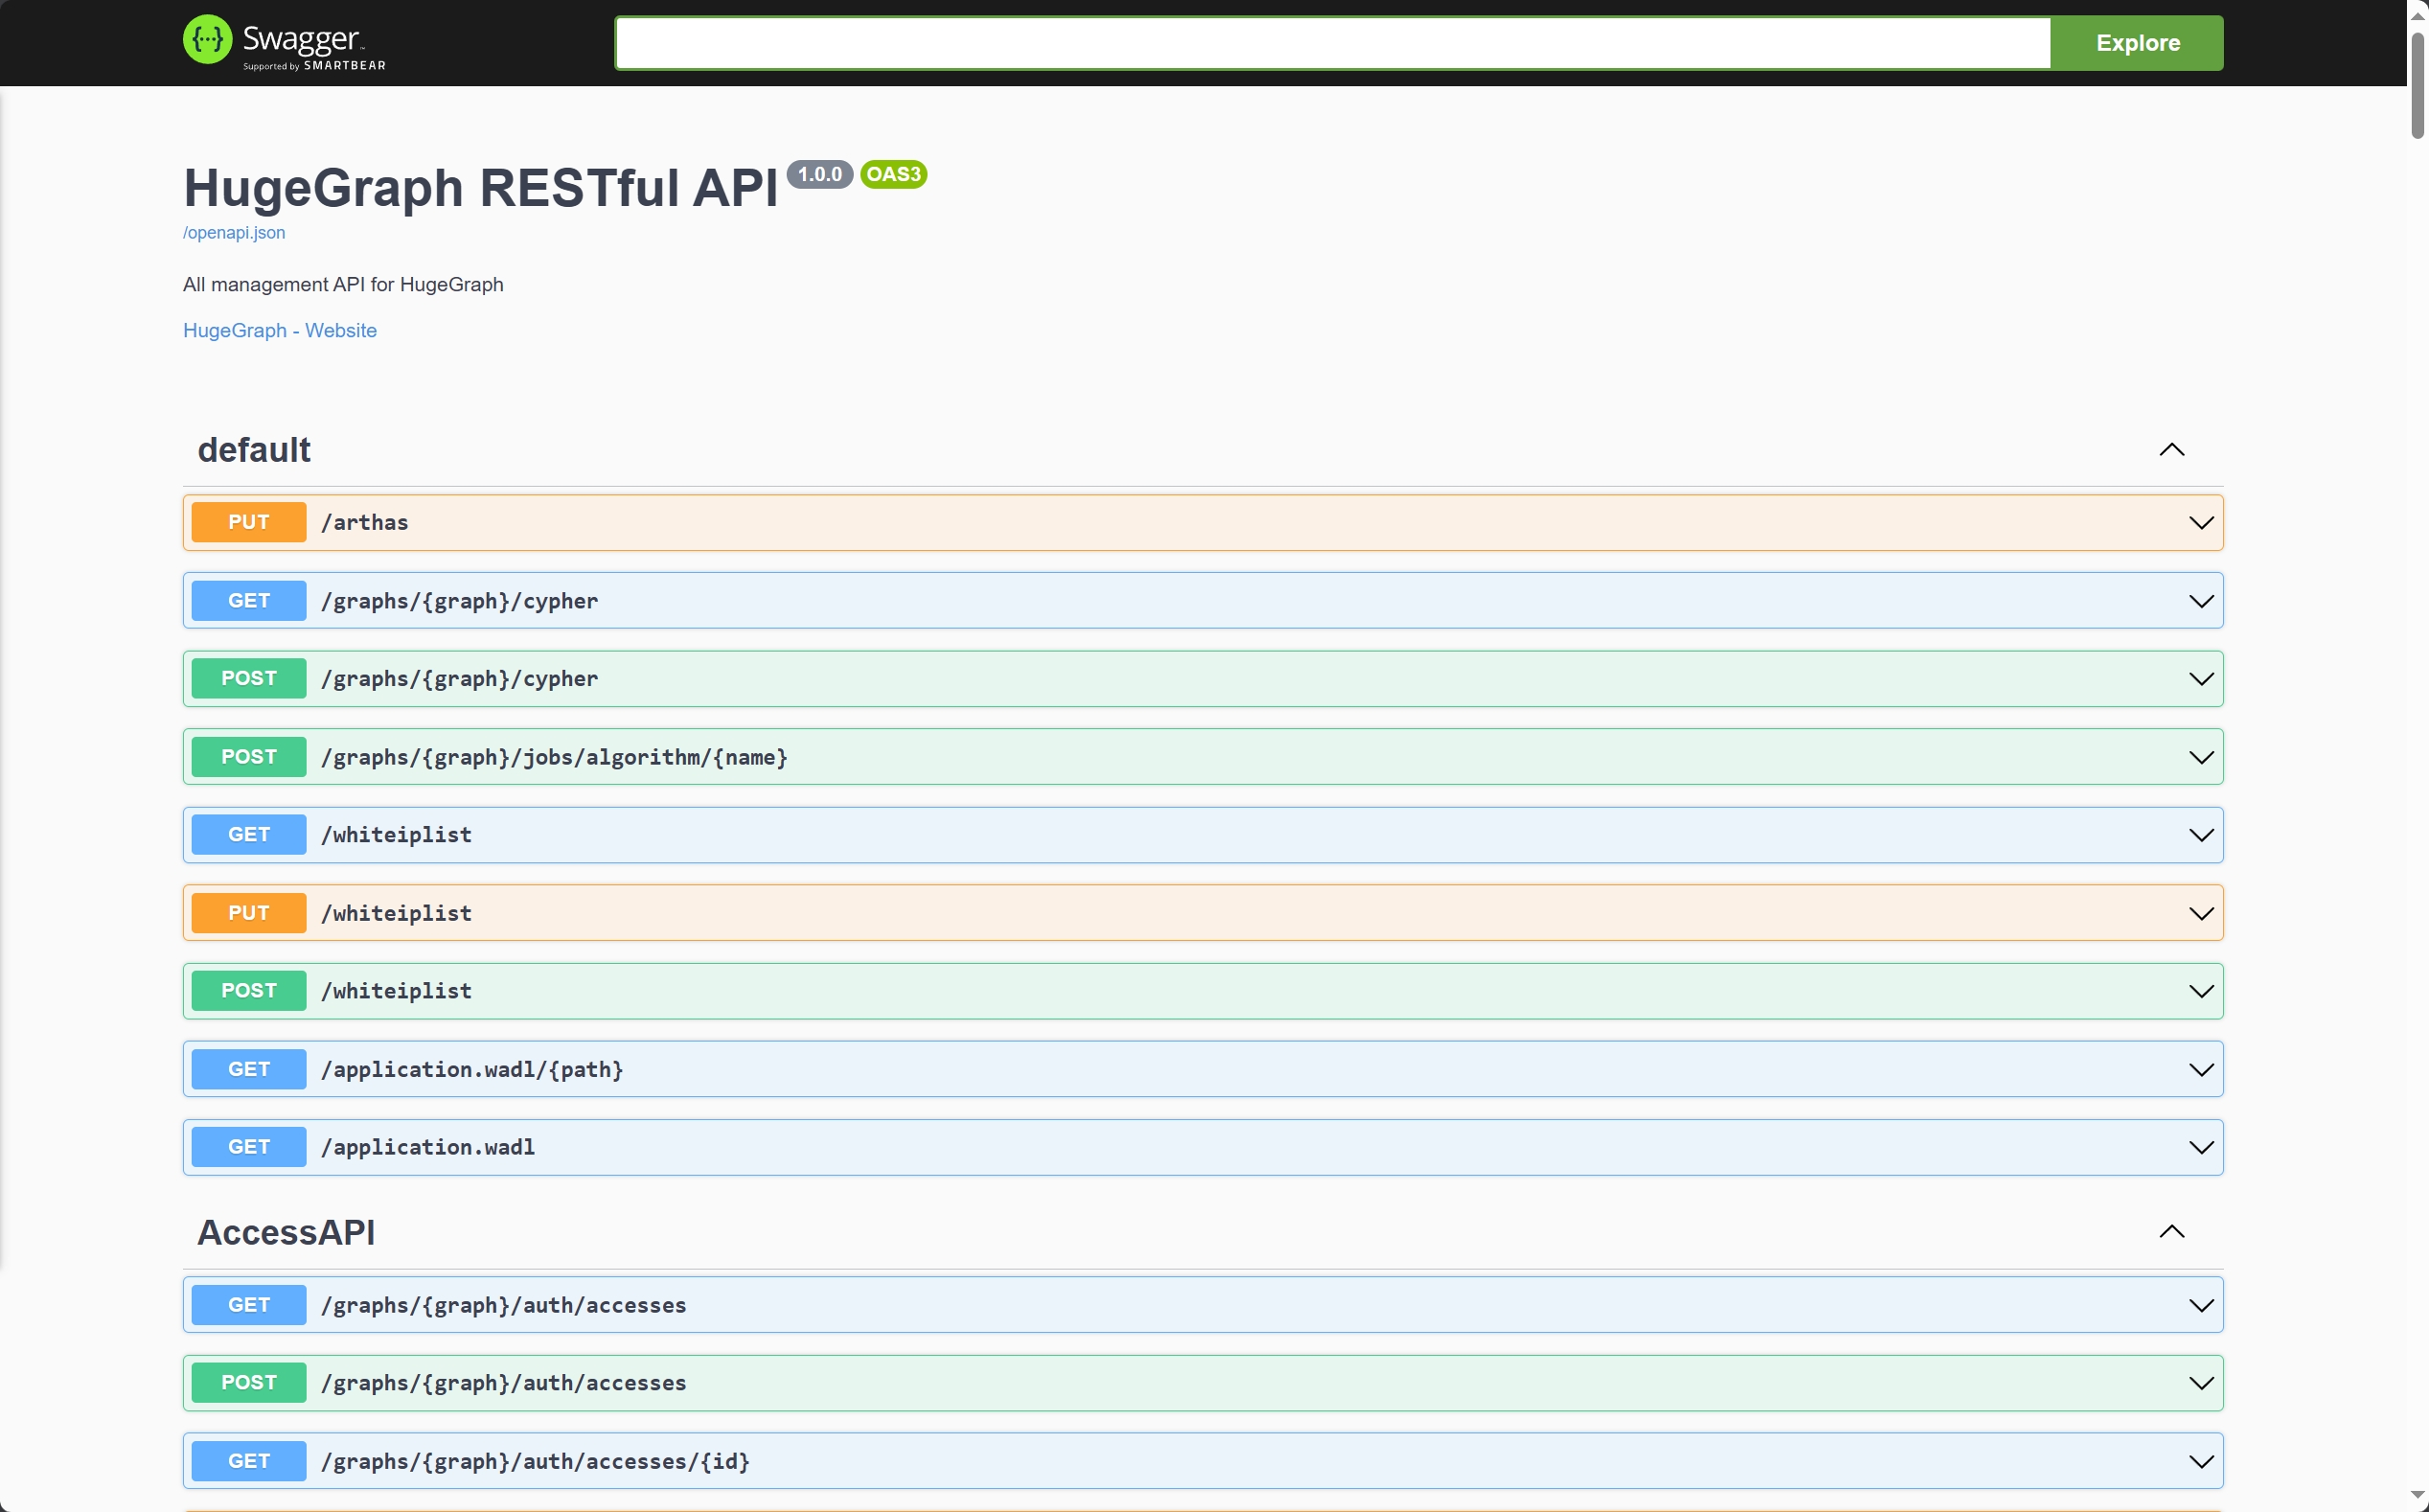
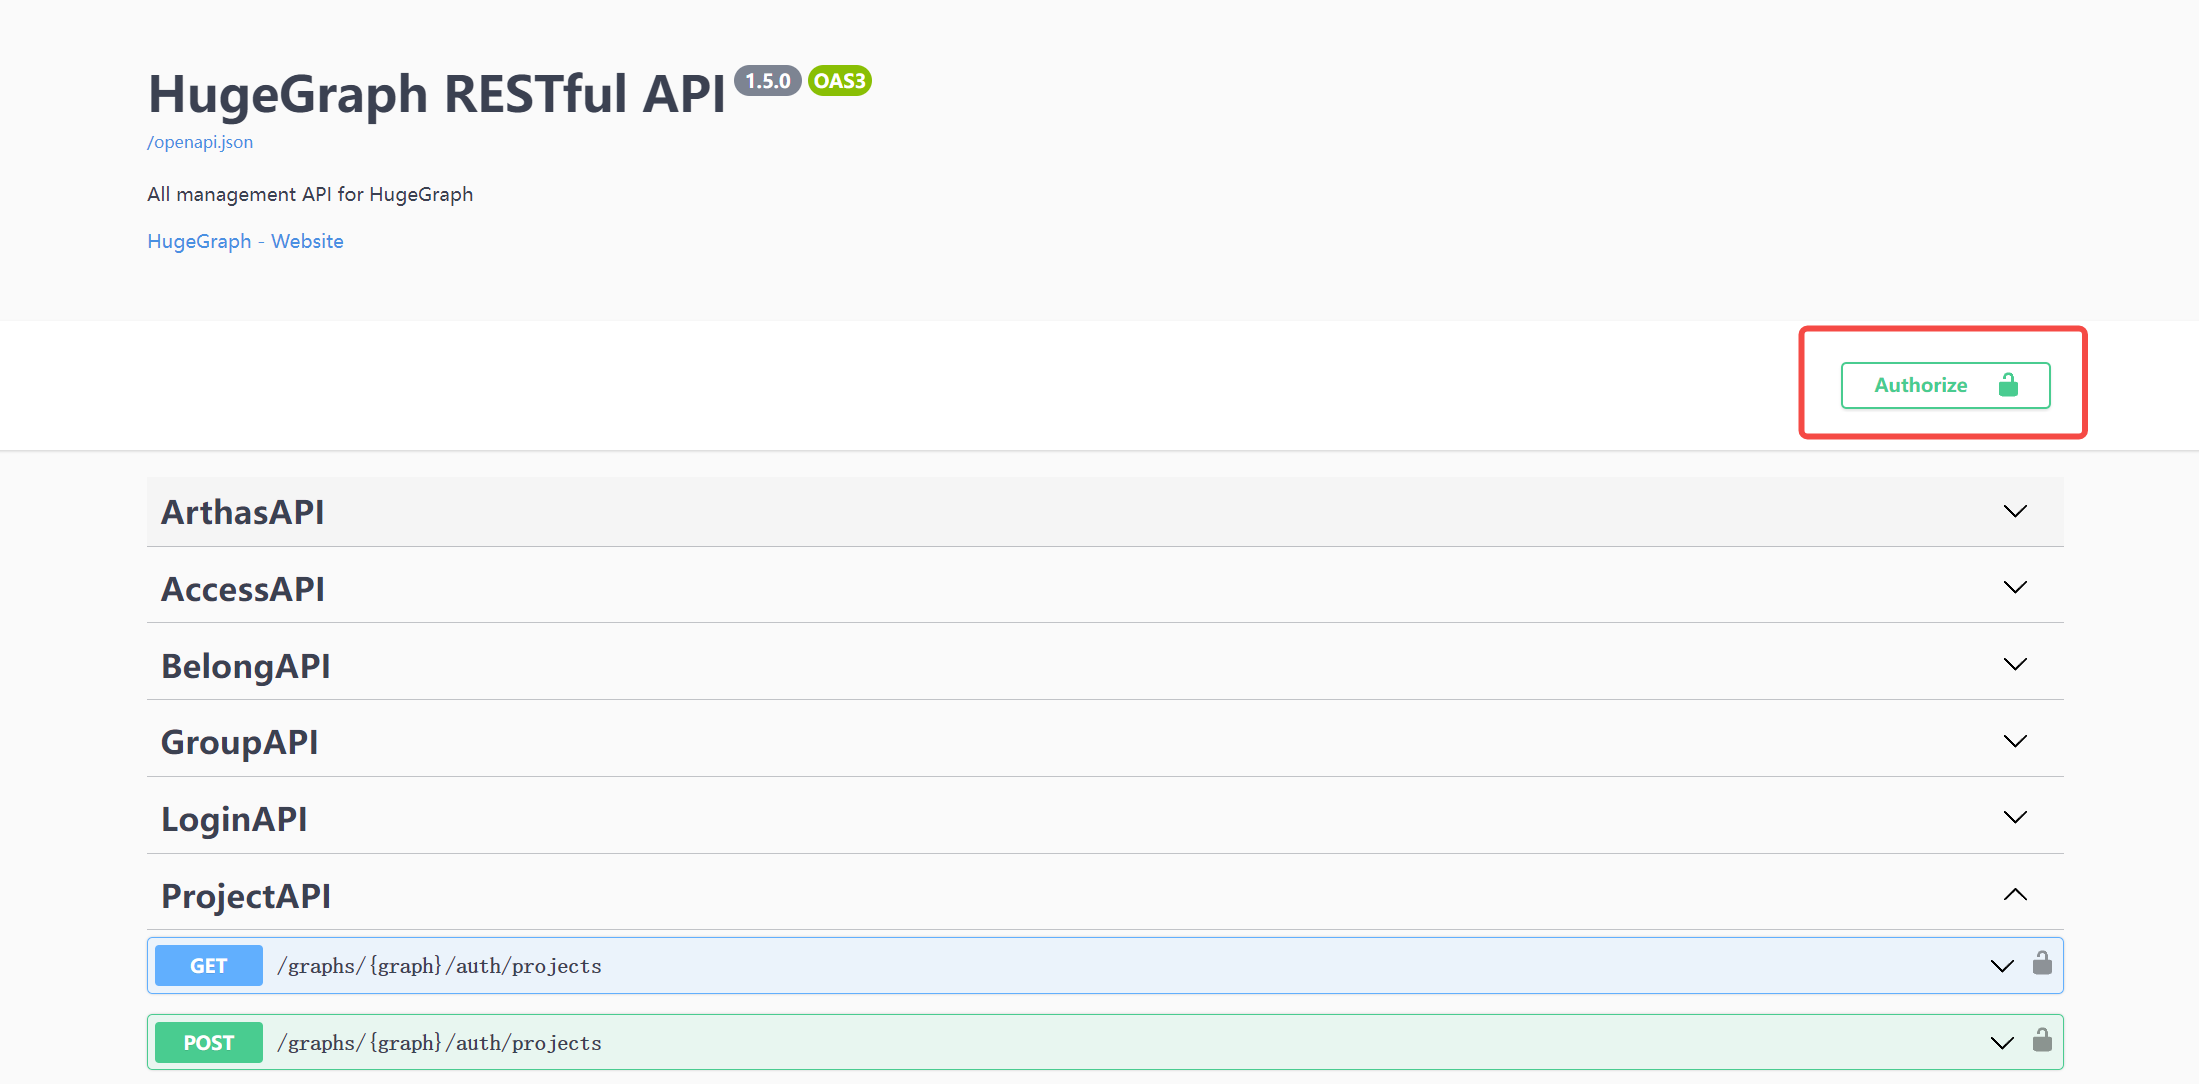
When using Swagger UI to debug the API provided by HugeGraph, if HugeGraph Server turns on authentication mode, you can enter authentication information on the Swagger page.
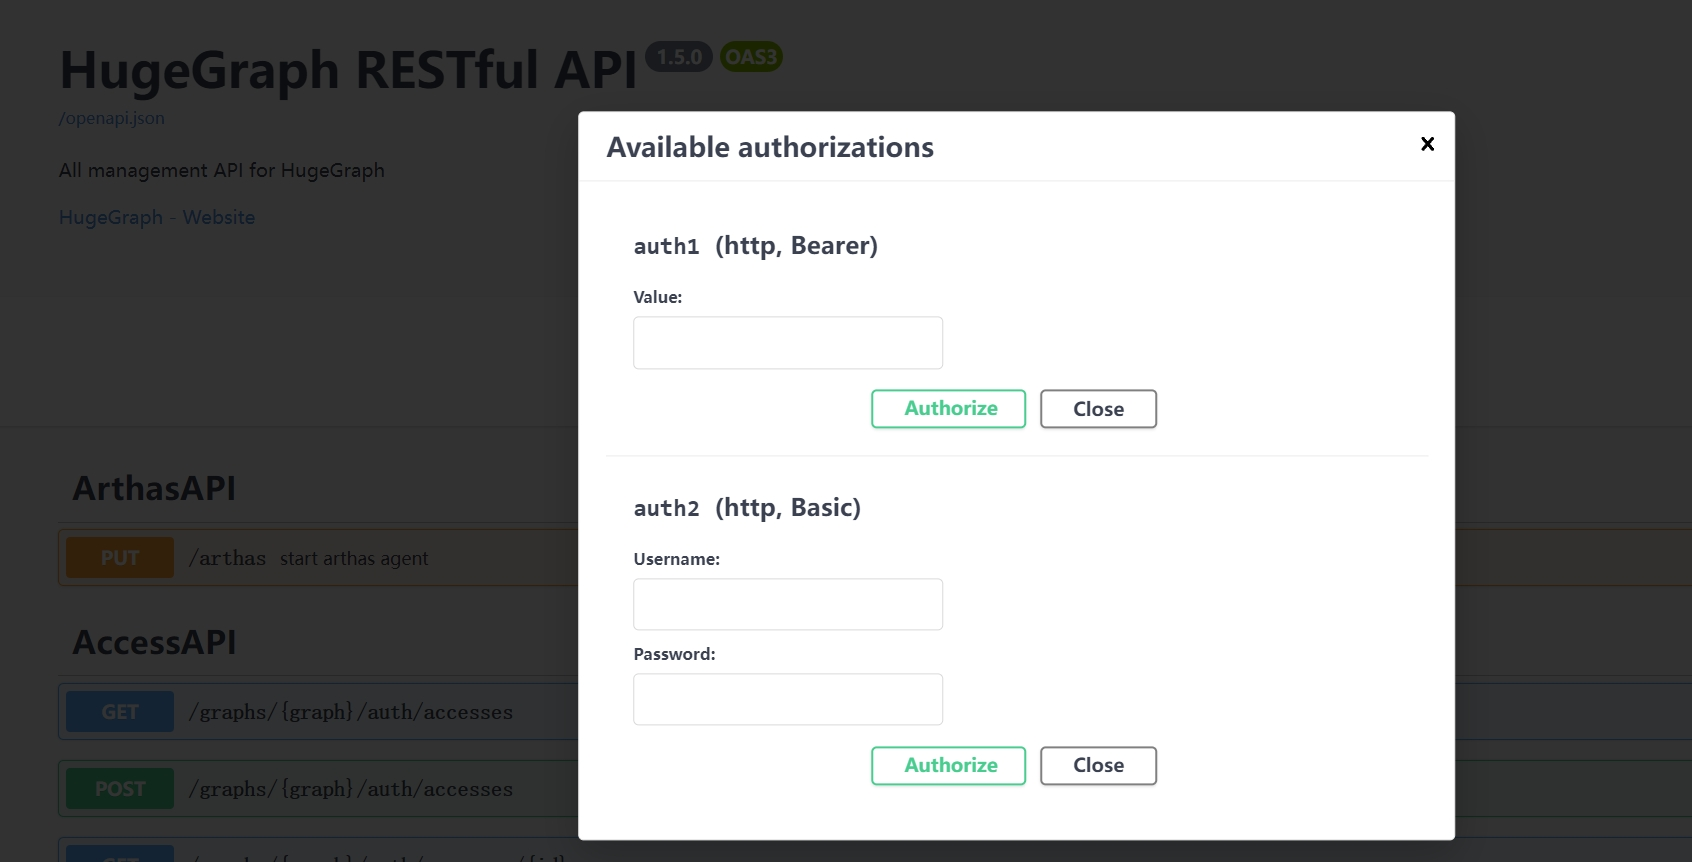
Currently, HugeGraph supports setting authentication information in two forms: Basic and Bearer.
7 Stop Server
8 Debug Server with IntelliJ IDEA
Please refer to Setup Server in IDEA
1.2 - HugeGraph-PD Quick Start
1 HugeGraph-PD Overview
HugeGraph-PD (Placement Driver) is the metadata management component of HugeGraph’s distributed version, responsible for managing the distribution of graph data and coordinating storage nodes. It plays a central role in distributed HugeGraph, maintaining cluster status and coordinating HugeGraph-Store storage nodes.
2 Prerequisites
2.1 Requirements
- Operating System: Linux or macOS (Windows has not been fully tested)
- Java version: ≥ 11
- Maven version: ≥ 3.5.0
3 Deployment
There are two ways to deploy the HugeGraph-PD component:
- Method 1: Download the tar package
- Method 2: Compile from source
3.1 Download the tar package
Download the latest version of HugeGraph-PD from the Apache HugeGraph official download page:
3.2 Compile from source
3.3 Docker Deployment
The HugeGraph-PD Docker image is available on Docker Hub as hugegraph/pd.
Note: The following steps assume you have already cloned or pulled the HugeGraph main repository locally, or at least have its
docker/directory available.
Use the docker compose setup to deploy the complete 3-node cluster (PD + Store + Server):
To run a single PD node via docker run, configuration is provided via environment variables:
Environment variable reference:
| Variable | Required | Default | Description |
|---|---|---|---|
HG_PD_GRPC_HOST | Yes | — | This node’s hostname/IP for gRPC (e.g. pd0 in Docker, 192.168.1.10 on bare metal) |
HG_PD_RAFT_ADDRESS | Yes | — | This node’s Raft address (e.g. pd0:8610) |
HG_PD_RAFT_PEERS_LIST | Yes | — | All PD peers (e.g. pd0:8610,pd1:8610,pd2:8610) |
HG_PD_INITIAL_STORE_LIST | Yes | — | Expected store gRPC addresses (e.g. store0:8500,store1:8500,store2:8500) |
HG_PD_GRPC_PORT | No | 8686 | gRPC server port |
HG_PD_REST_PORT | No | 8620 | REST API port |
HG_PD_DATA_PATH | No | /hugegraph-pd/pd_data | Metadata storage path |
HG_PD_INITIAL_STORE_COUNT | No | 1 | Minimum stores required for cluster availability |
Note: In Docker bridge networking, use container hostnames (e.g.
pd0) forHG_PD_GRPC_HOSTandHG_PD_RAFT_ADDRESSinstead of IP addresses.
Deprecated aliases:
GRPC_HOST,RAFT_ADDRESS,RAFT_PEERS,PD_INITIAL_STORE_LISTstill work but log a deprecation warning. Use theHG_PD_*names for new deployments.
To view runtime logs for a running PD container use docker logs <container-name> (e.g. docker logs hg-pd0).
See docker/README.md for the full cluster setup guide.
4 Configuration
The main configuration file for PD is conf/application.yml. Here are the key configuration items:
For multi-node deployment, you need to modify the port and address configurations for each node to ensure proper communication between nodes.
5 Start and Stop
5.1 Start PD
In the PD installation directory, execute:
The startup script supports a -d flag to control daemon mode:
-d true(default): run as a background daemon; the script returns immediately.-d false: run in foreground — the scriptexecs Java, so the container/supervisor process IS Java. Use this when running under Docker or a process supervisor (systemd, supervisord) so crashes are detected and the service is restarted automatically.
After successful startup, you can see logs similar to the following in logs/hugegraph-pd-stdout.log:
5.2 Stop PD
In the PD installation directory, execute:
6 Verification
Confirm that the PD service is running properly:
If it returns {"status":"UP"}, it indicates that the PD service has been successfully started.
You can also verify Store node status through the PD API:
If the response shows state as Up, the corresponding Store node is running normally. The example below shows a single Store node. In a healthy 3-node deployment, the storeId list should contain three IDs, and stateCountMap.Up, numOfService, and numOfNormalService should all be 3.
1.3 - HugeGraph-Store Quick Start
1 HugeGraph-Store Overview
HugeGraph-Store is the storage node component of HugeGraph’s distributed version, responsible for actually storing and managing graph data. It works in conjunction with HugeGraph-PD to form HugeGraph’s distributed storage engine, providing high availability and horizontal scalability.
2 Prerequisites
2.1 Requirements
- Operating System: Linux or macOS (Windows has not been fully tested)
- Java version: ≥ 11
- Maven version: ≥ 3.5.0
- Deploy HugeGraph-PD first for multi-node deployment
3 Deployment
There are two ways to deploy the HugeGraph-Store component:
- Method 1: Download the tar package
- Method 2: Compile from source
3.1 Download the tar package
Download the latest version of HugeGraph-Store from the Apache HugeGraph official download page:
3.2 Compile from source
3.3 Docker Deployment
The HugeGraph-Store Docker image is available on Docker Hub as hugegraph/store.
Note: The following steps assume you have already cloned or pulled the HugeGraph main repository locally, or at least have its
docker/directory available.
Use the compose file to deploy the complete 3-node cluster (PD + Store + Server):
To run a single Store node via docker run:
Environment variable reference:
| Variable | Required | Default | Description |
|---|---|---|---|
HG_STORE_PD_ADDRESS | Yes | — | PD gRPC addresses (e.g. pd0:8686,pd1:8686,pd2:8686) |
HG_STORE_GRPC_HOST | Yes | — | This node’s hostname/IP for gRPC (e.g. store0) |
HG_STORE_RAFT_ADDRESS | Yes | — | This node’s Raft address (e.g. store0:8510) |
HG_STORE_GRPC_PORT | No | 8500 | gRPC server port |
HG_STORE_REST_PORT | No | 8520 | REST API port |
HG_STORE_DATA_PATH | No | /hugegraph-store/storage | Data storage path |
Note: In Docker bridge networking, use container hostnames (e.g.
store0) forHG_STORE_GRPC_HOSTinstead of IP addresses.
Deprecated aliases:
PD_ADDRESS,GRPC_HOST,RAFT_ADDRESSstill work but log a deprecation warning. Use theHG_STORE_*names for new deployments.
4 Configuration
The main configuration file for Store is conf/application.yml. Here are the key configuration items:
For multi-node deployment, you need to modify the following configurations for each Store node:
grpc.port(RPC port) for each noderaft.address(Raft protocol port) for each nodeserver.port(REST port) for each nodeapp.data-path(data storage path) for each node
5 Start and Stop
5.1 Start Store
Ensure that the PD service is already started, then in the Store installation directory, execute:
The startup script supports a -d flag to control daemon mode:
-d true(default): run as a background daemon; the script returns immediately.-d false: run in foreground — the scriptexecs Java, so the container/supervisor process IS Java. Use this when running under Docker or a process supervisor (systemd, supervisord) so crashes are detected and the service is restarted automatically.
After successful startup, you can see logs similar to the following in logs/hugegraph-store-server.log:
5.2 Stop Store
In the Store installation directory, execute:
6 Multi-Node Deployment Example
Below is a configuration example for a three-node deployment:
6.1 Three-Node Configuration Reference
- 3 PD nodes
- raft ports: 8610, 8611, 8612
- rpc ports: 8686, 8687, 8688
- rest ports: 8620, 8621, 8622
- 3 Store nodes
- raft ports: 8510, 8511, 8512
- rpc ports: 8500, 8501, 8502
- rest ports: 8520, 8521, 8522
6.2 Store Node Configuration
For the three Store nodes, the main configuration differences are as follows:
Node A:
Node B:
Node C:
All nodes should point to the same PD cluster:
6.3 Docker Distributed Cluster Configuration
The distributed Store cluster definition is included in docker/docker-compose-3pd-3store-3server.yml. Each Store node gets its own hostname and environment variables:
Store nodes start only after all PD nodes pass healthchecks (/v1/health), enforced via depends_on: condition: service_healthy.
To view runtime logs for a running Store container use docker logs <container-name> (e.g. docker logs hg-store0).
See docker/README.md for the full setup guide.
7 Verify Store Service
Confirm that the Store service is running properly:
If it returns {"status":"UP"}, it indicates that the Store service has been successfully started.
You can also check Store node status through the PD API:
If Store is configured successfully, the response should include status information for the current node, and state: "Up" means the node is running normally.
The example below shows a single Store node. If all three nodes are configured correctly and running, the storeId list should contain three IDs, and stateCountMap.Up, numOfService, and numOfNormalService should all be 3.
2 - HugeGraph ToolChain
HugeGraph Toolchain includes the Java and Go clients, Loader, Hubble, Tools, and Spark Connector. See the documents in this section for each module’s features and usage.
Testing Guide: For running toolchain tests locally, please refer to HugeGraph Toolchain Local Testing Guide
DeepWiki provides real-time updated project documentation with more comprehensive and accurate content, suitable for quickly understanding the latest project information.
Source repository: apache/hugegraph-toolchain
2.1 - HugeGraph-Hubble Quick Start
1 HugeGraph-Hubble Overview
⚠️ Security notice: As of the 1.7.0 release, Hubble does not provide Auth/Login protection. This feature is planned for the 1.8.0 release. Do not expose Hubble to the public Internet or untrusted networks; restrict access with IP/port allowlists and HTTPS.
Testing Guide: For running HugeGraph-Hubble tests locally, please refer to HugeGraph Toolchain Local Testing Guide
HugeGraph-Hubble is HugeGraph’s web management interface. It manages graph connections and schemas, imports data, runs Gremlin queries, and visualizes query results.
The platform mainly includes the following modules:
Graph Management
Graph Management creates and maintains connections, switches between graphs, and provides access, editing, deletion, and query operations.
Metadata Modeling
Metadata Modeling manages PropertyKeys, VertexLabels, EdgeLabels, and IndexLabels. It provides list and graph views and supports reusing metadata across graphs.
Graph Analysis
Graph Analysis runs Gremlin and path queries and displays results as a graph, table, or JSON. It also keeps execution history and saved statements, and exports query results as JSON.
Task Management
Task Management displays background tasks such as asynchronous Gremlin jobs and index creation or rebuilding.
Data Import
The data import page is intended for small-scale trials. For bulk or production imports, use HugeGraph Loader.
The data import page guides you through creating a task, uploading files, and mapping fields. Multiple import tasks can run in parallel, with resumable uploads and error retries.
2 Deploy
There are three ways to deploy hugegraph-hubble
- Use Docker (Convenient for Test/Dev)
- Download the Toolchain binary package
- Source code compilation
2.1 Use docker (Convenient for Test/Dev)
Special Note: If you are starting
hubblewith Docker, andhubbleand the server are on the same host. When configuring the hostname for the graph on the Hubble web page, please do not directly set it tolocalhost/127.0.0.1. This will refer to thehubblecontainer internally rather than the host machine, resulting in a connection failure to the server.If
hubbleandserveris in the same docker network, we recommend using thecontainer_name(in our example, it isserver) as the hostname, and8080as the port. Or you can use the host IP as the hostname, and the port is configured by the host for the server.
We can use docker run -itd --name=hubble -p 8088:8088 hugegraph/hubble:1.5.0 to quick start hubble.
Alternatively, you can use Docker Compose to start hubble. Additionally, if hubble and the graph is in the same Docker network, you can access the graph using the container name of the graph, eliminating the need for the host machine’s IP address.
Use docker-compose up -d,docker-compose.yml is following:
Note:
The docker image of hugegraph-hubble is a convenience release to start hugegraph-hubble quickly, but not official distribution artifacts. You can find more details from ASF Release Distribution Policy.
Recommend to use
release tag(like1.5.0) for the stable version. Uselatesttag to experience the newest functions in development.
2.2 Download the Toolchain binary package
hubble is in the toolchain project. First, download the binary tar tarball
Run hubble
After startup, open http://<host>:8088. Run bin/stop-hubble.sh to stop the service.
2.3 Source code compilation
Hubble’s build uses frontend-maven-plugin in hugegraph-hubble/hubble-dist/pom.xml to install Node.js 18.20.8 and Yarn 1.22.21, so neither tool needs to be installed beforehand.
Download the toolchain source code.
Compile hubble. It depends on the loader and client, so you need to build these dependencies in advance during the compilation process (you can skip this step later).
Run hubble
3 Platform Workflows
The module usage process of the platform is as follows:
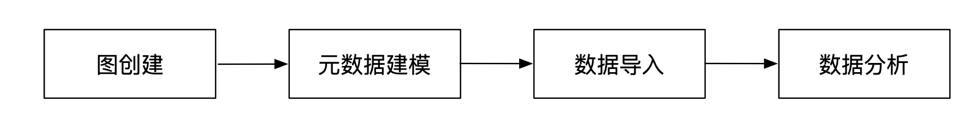
4 Platform Instructions
4.1 Graph Management
4.1.1 Graph creation
Under the graph management module, click [Create graph], and realize the connection of multiple graphs by filling in the graph ID, graph name, host name, port number, username, and password information.
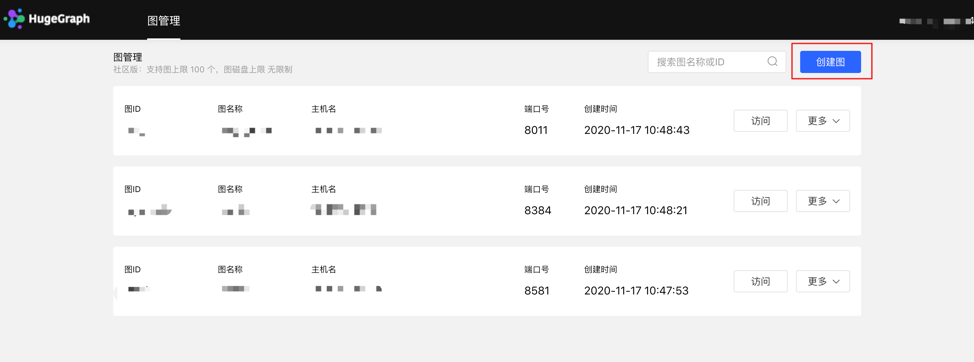
Create graph by filling in the content as follows:
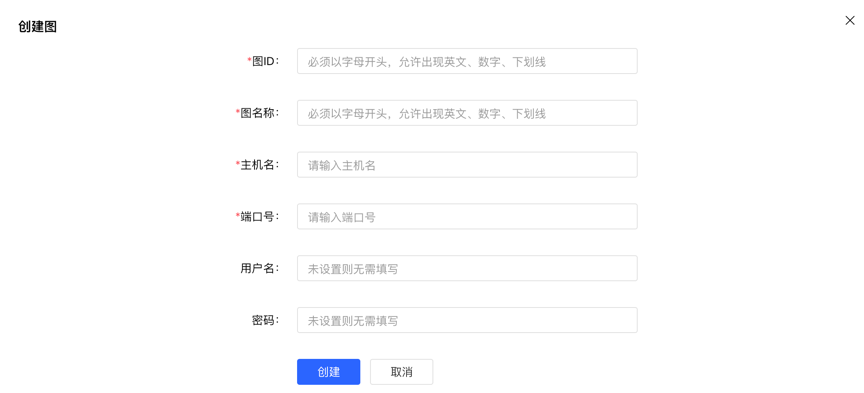
Special Note: If you are starting
hubblewith Docker, andhubbleand the server are on the same host. When configuring the hostname for the graph on the Hubble web page, please do not directly set it tolocalhost/127.0.0.1. Ifhubbleandserveris in the same docker network, we recommend using thecontainer_name(in our example, it isgraph) as the hostname, and8080as the port. Or you can use the host IP as the hostname, and the port is configured by the host for the server.
4.1.2 Graph Access
Realize the information access to the graph space. After entering, you can perform operations such as multidimensional query analysis, metadata management, data import, and algorithm analysis of the graph.
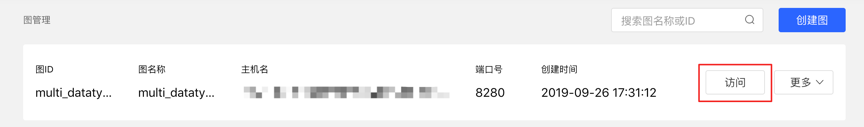
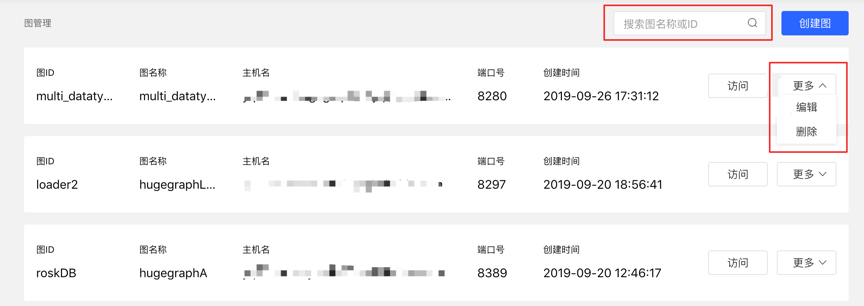
4.1.3 Graph management
- Users can achieve unified management of graphs through overview, search, and information editing and deletion of single graphs.
- Search range: You can search for the graph name and ID.
4.2 Metadata Modeling (list + graph mode)
4.2.1 Module entry
Left navigation:
4.2.2 Property type
4.2.2.1 Create type
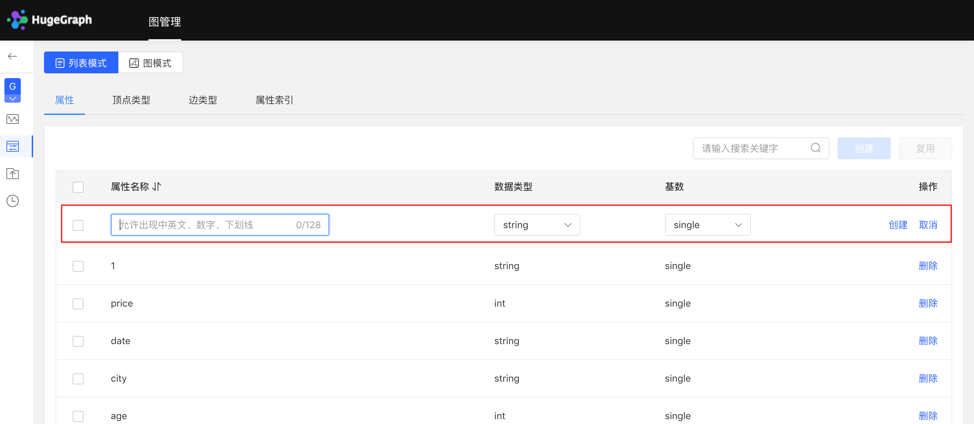
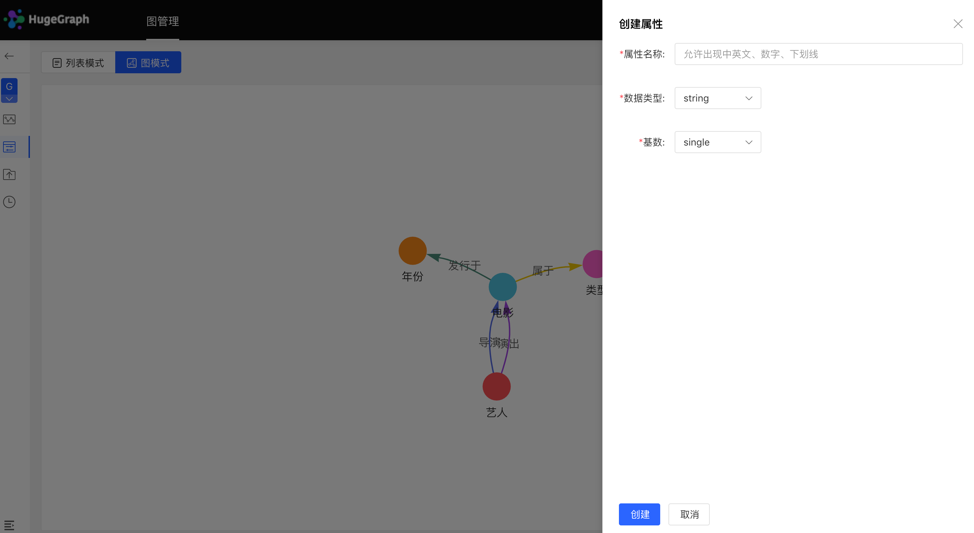
- Fill in or select the attribute name, data type, and cardinality to complete the creation of the attribute.
- Created attributes can be used as attributes of vertex type and edge type.
List mode:
Graph mode:
4.2.2.2 Reuse
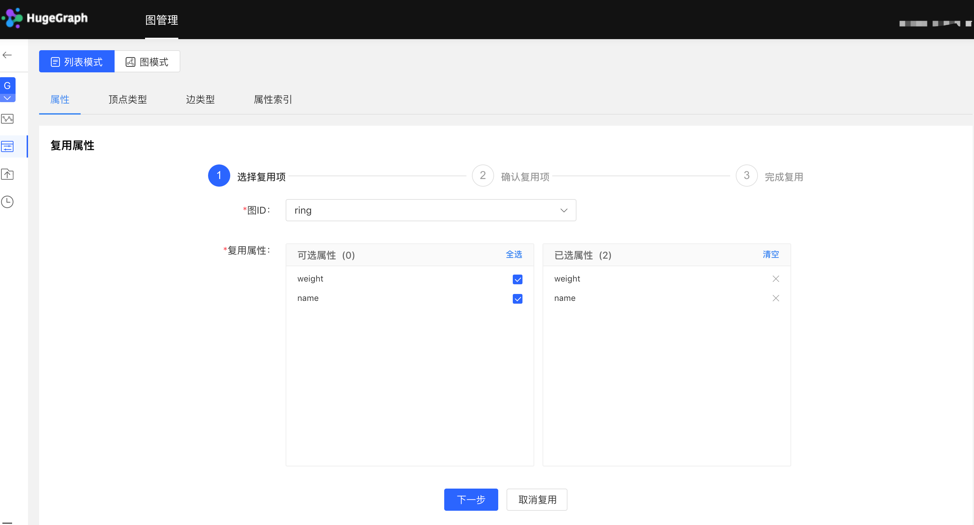
- The platform provides the [Reuse] function, which can directly reuse the metadata of other graphs.
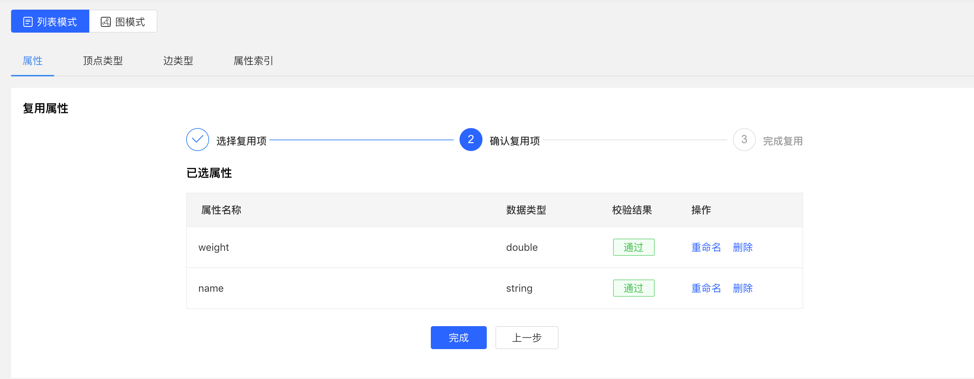
- Select the graph ID that needs to be reused, and continue to select the attributes that need to be reused. After that, the platform will check whether there is a conflict. After passing, the metadata can be reused.
Select reuse items:
Check reuse items:
4.2.2.3 Management
- You can delete a single item or delete it in batches in the attribute list.
4.2.3 Vertex type
4.2.3.1 Create type
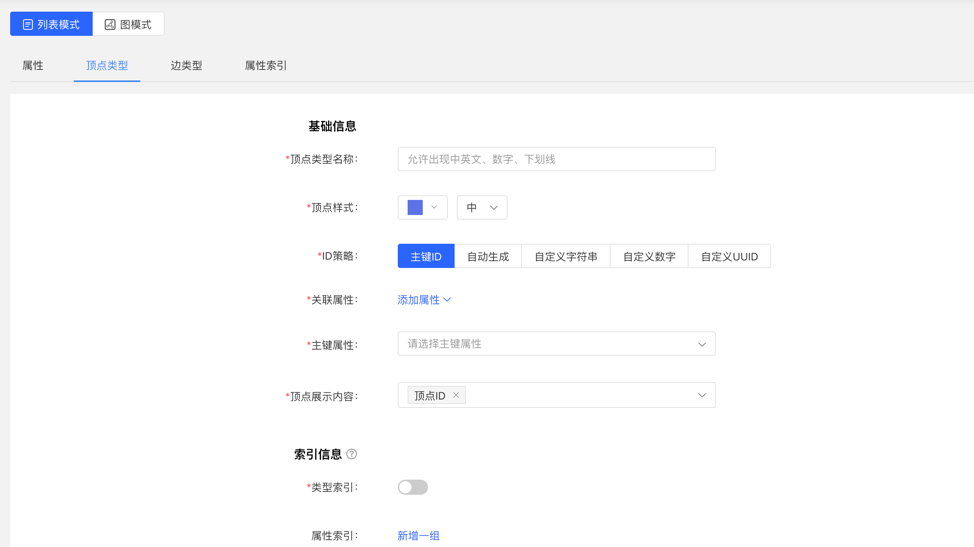
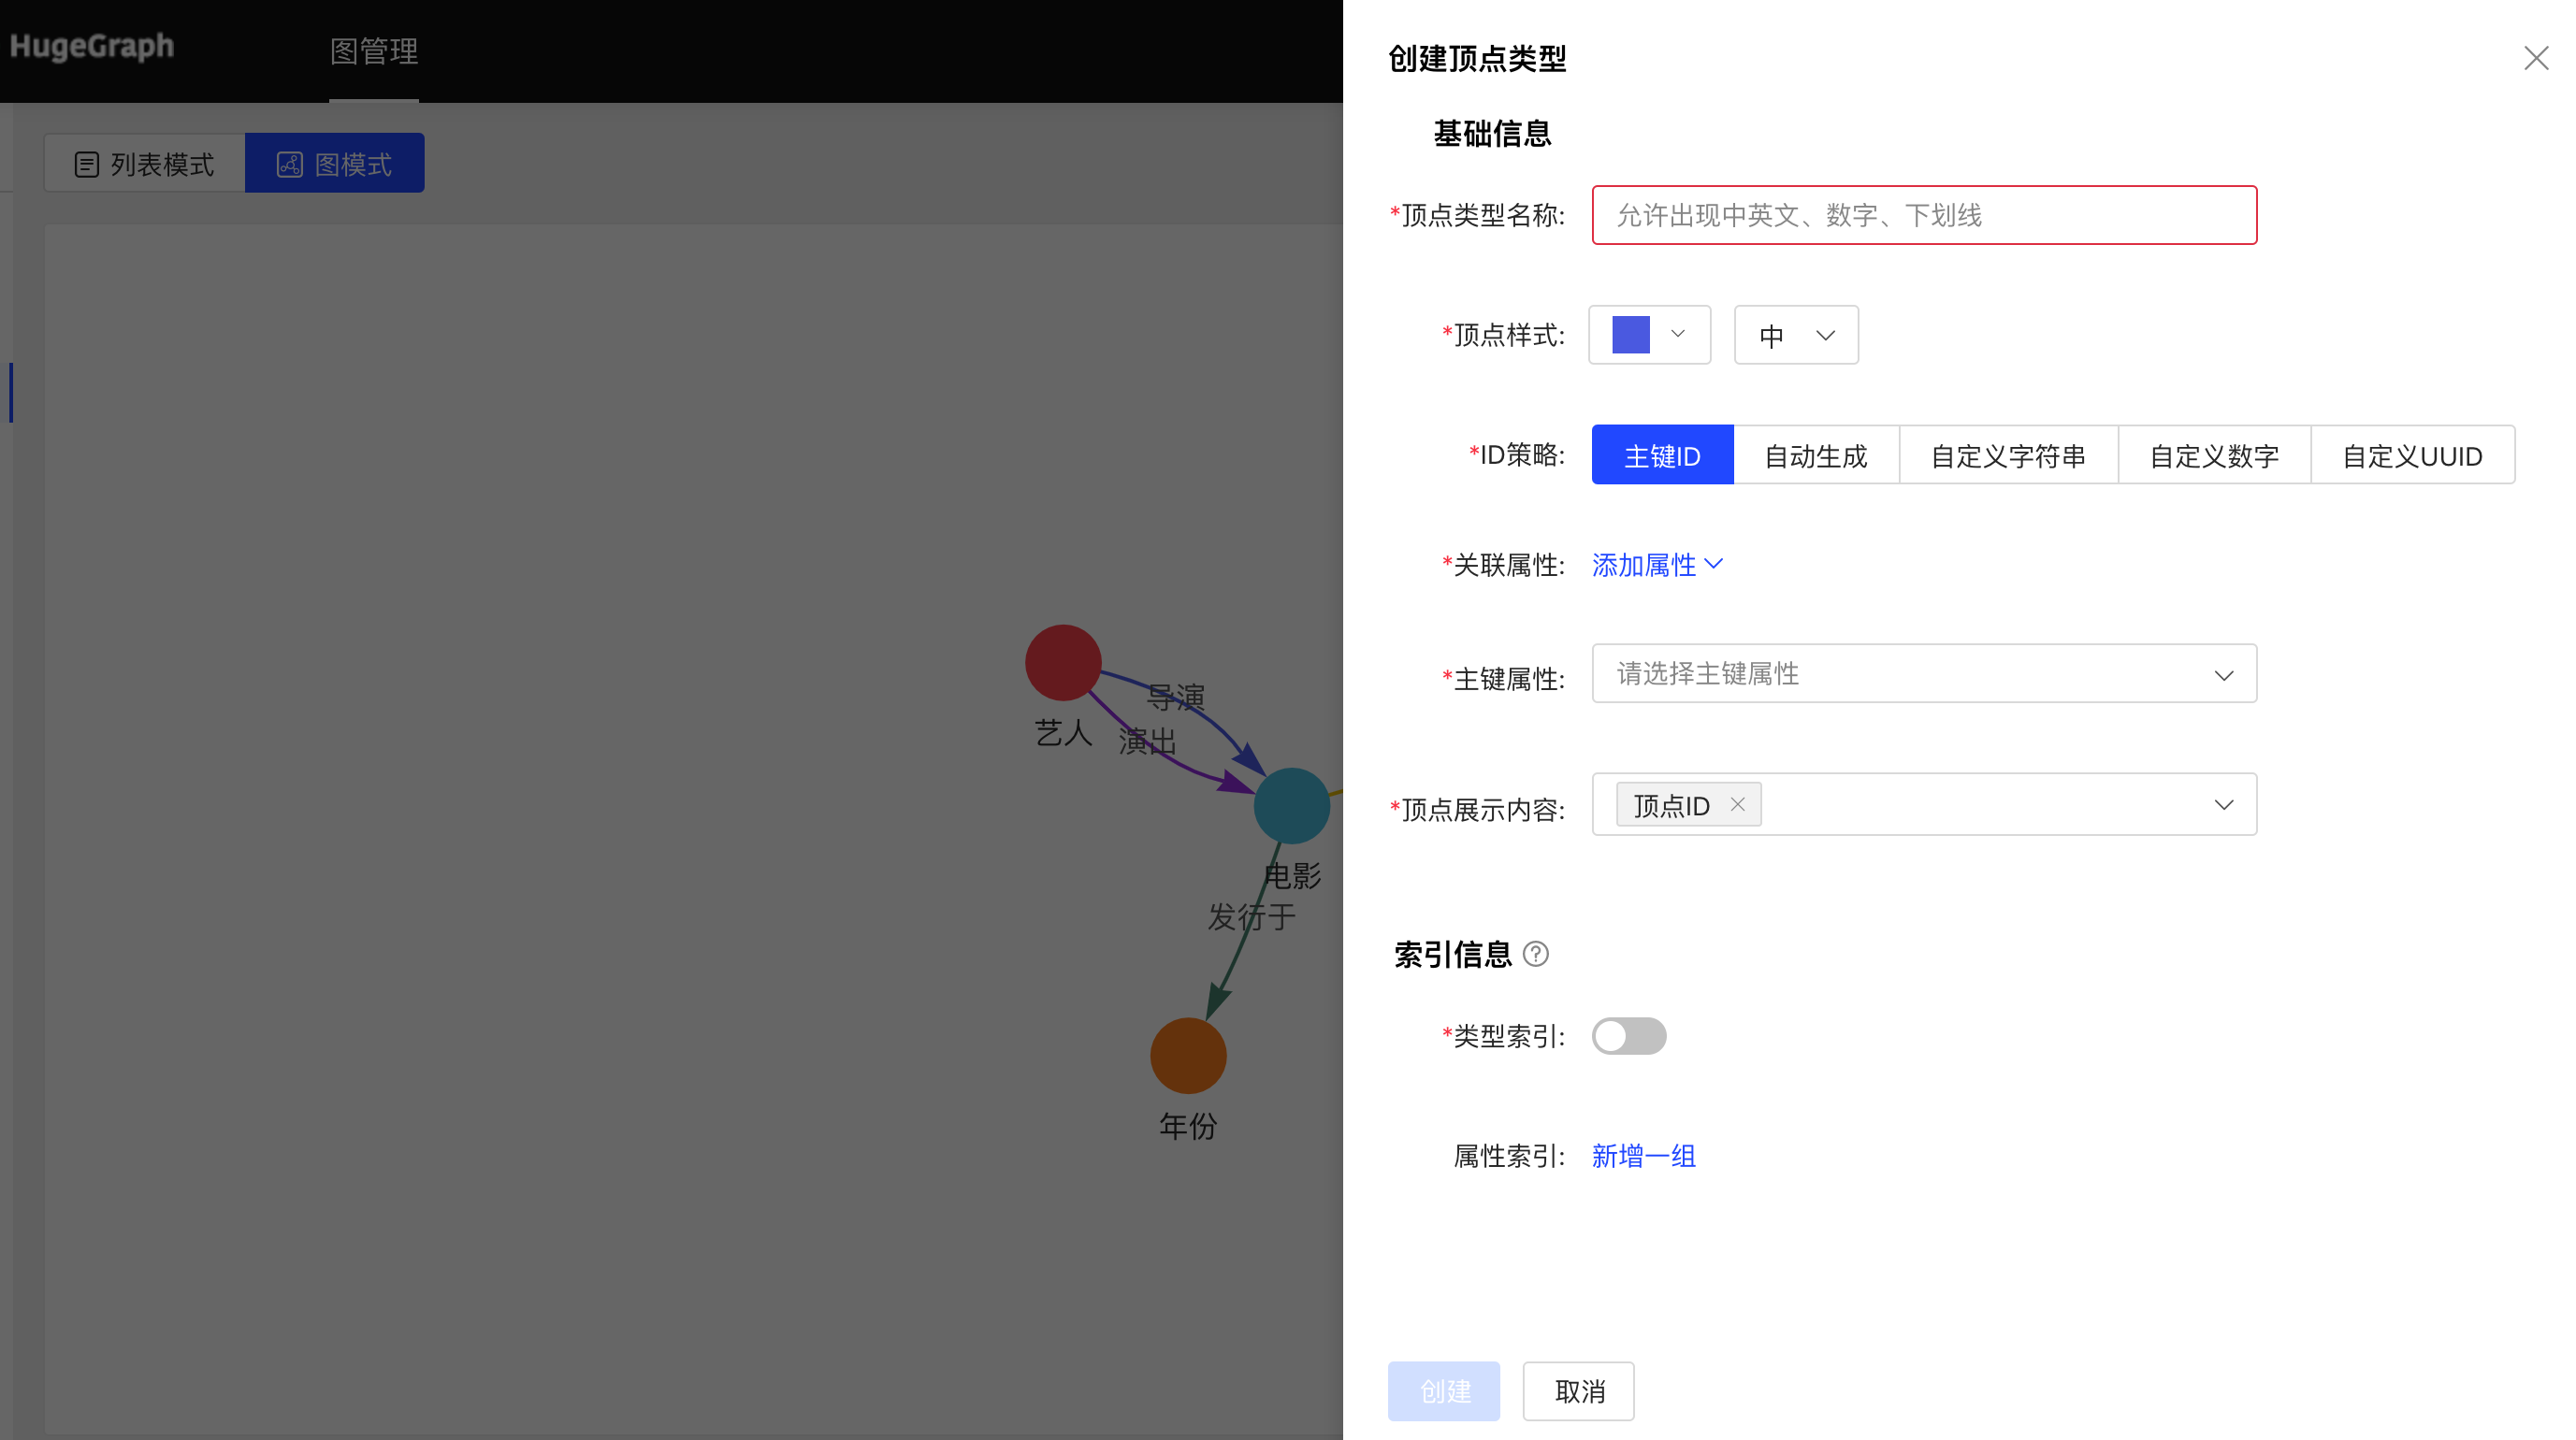
- Fill in or select the vertex type name, ID strategy, association attribute, primary key attribute, vertex style, content displayed below the vertex in the query result, and index information: including whether to create a type index, and the specific content of the attribute index, complete the vertex Type creation.
List mode:
Graph mode:
4.2.3.2 Reuse
- The multiplexing of vertex types will reuse the attributes and attribute indexes associated with this type together.
- The reuse method is similar to the property reuse, see 3.2.2.2.
4.2.3.3 Administration
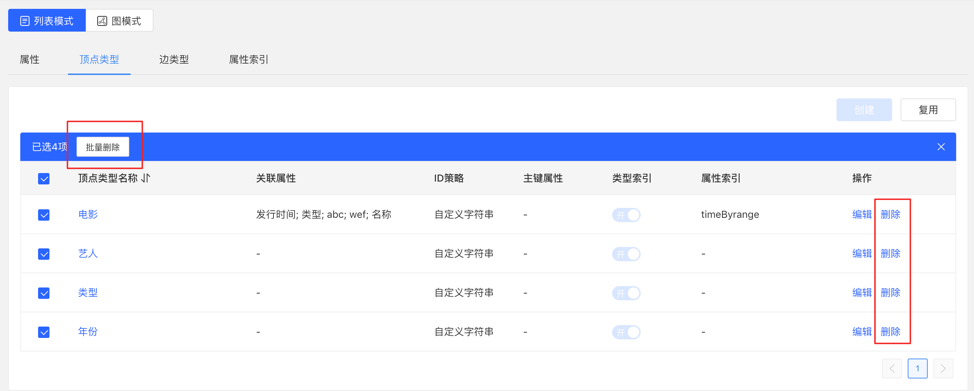
Editing operations are available. The vertex style, association type, vertex display content, and attribute index can be edited, and the rest cannot be edited.
You can delete a single item or delete it in batches.
4.2.4 Edge Types
4.2.4.1 Create
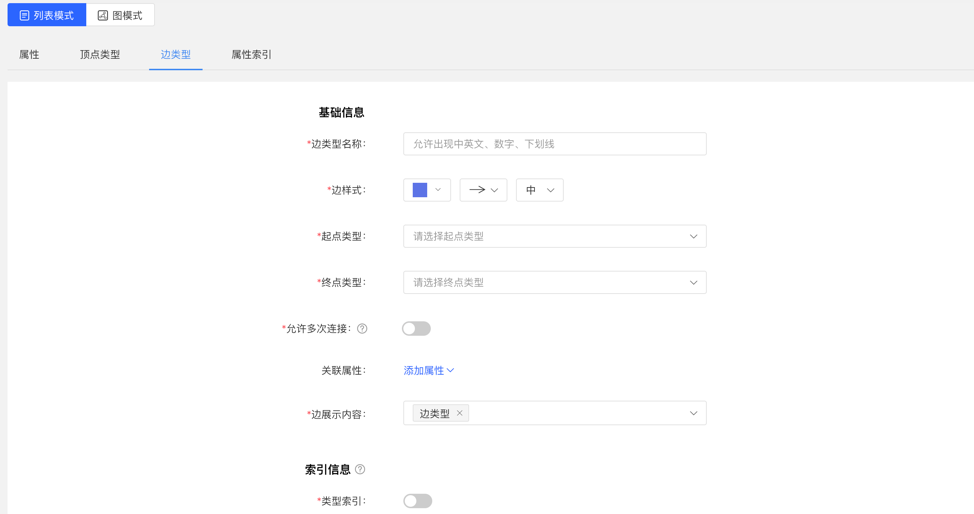
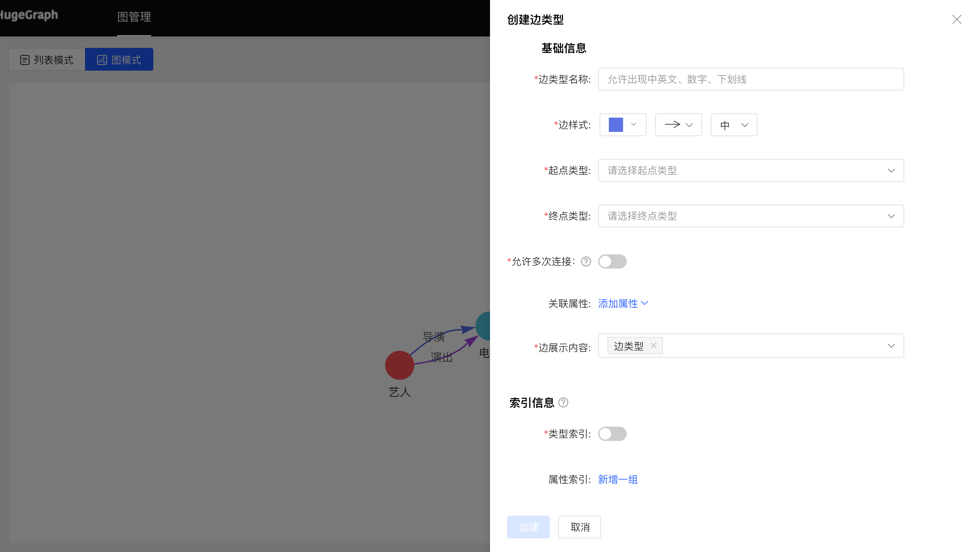
- Fill in or select the edge type name, start point type, end point type, associated attributes, whether to allow multiple connections, edge style, content displayed below the edge in the query result, and index information: including whether to create a type index, and attribute index The specific content, complete the creation of the edge type.
List mode:
Graph mode:
4.2.4.2 Reuse
- The reuse of the edge type will reuse the start point type, end point type, associated attribute and attribute index of this type.
- The reuse method is similar to the property reuse, see 3.2.2.2.
4.2.4.3 Administration
- Editing operations are available. Edge styles, associated attributes, edge display content, and attribute indexes can be edited, and the rest cannot be edited, the same as the vertex type.
- You can delete a single item or delete it in batches.
4.2.5 Index Types
Displays vertex and edge indices for vertex types and edge types.
4.3 Data Import
Note:currently, we recommend to use hugegraph-loader to import data formally. The built-in import of
hubbleis used for testing and getting started.
The usage process of data import is as follows:

4.3.1 Module entrance
Left navigation:
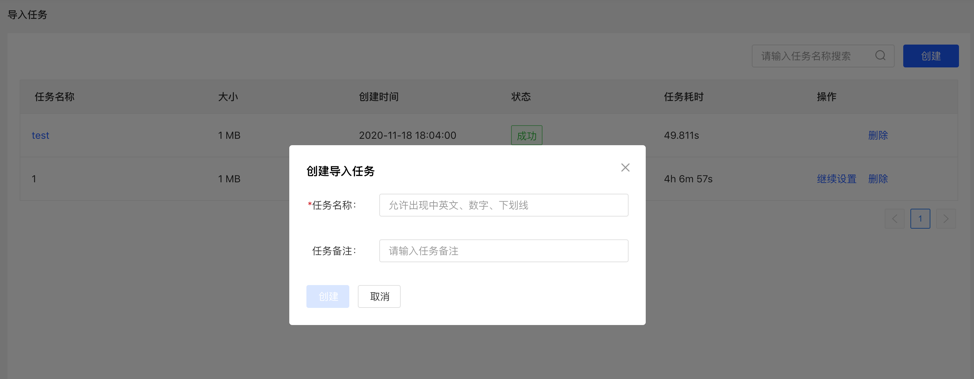
4.3.2 Create task
- Fill in the task name and remarks (optional) to create an import task.
- Multiple import tasks can be created and imported in parallel.
4.3.3 Uploading files
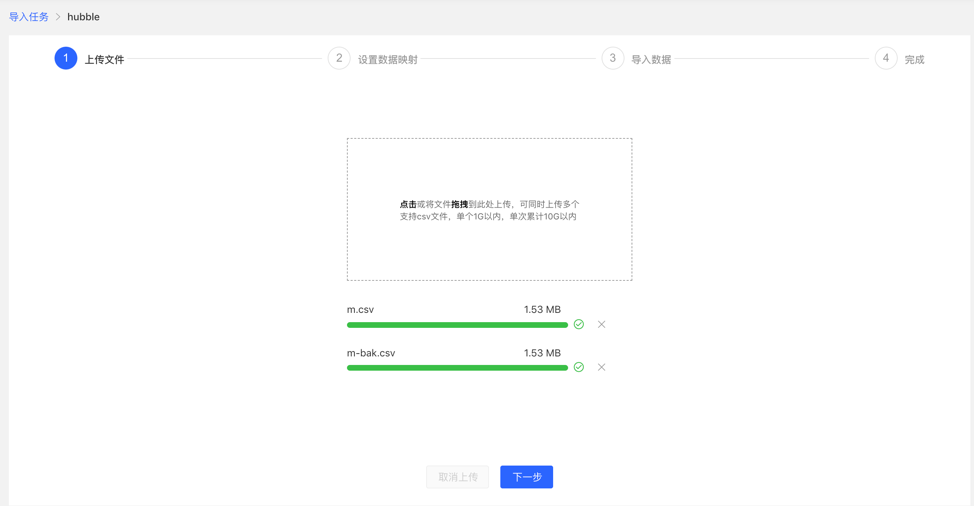
- Upload the file that needs to be composed. The currently supported format is CSV, which will be updated continuously in the future.
- Multiple files can be uploaded at the same time.
4.3.4 Setting up data mapping
Set up data mapping for uploaded files, including file settings and type settings
File settings: Check or fill in whether to include the header, separator, encoding format and other settings of the file itself, all set the default values, no need to fill in manually
Type setting:
Vertex map and edge map:
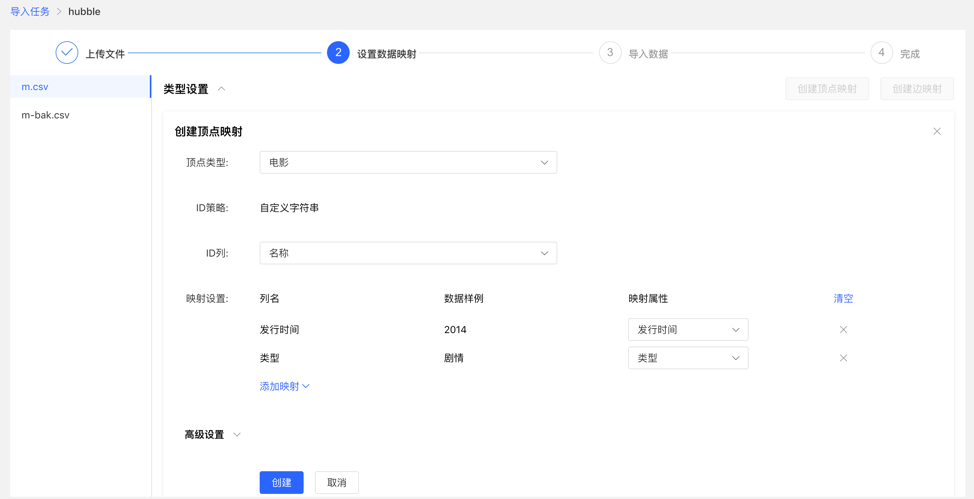
【Vertex Type】: Select the vertex type, and upload the column data in the file for its ID mapping;
【Edge Type】: Select the edge type and map the column data of the uploaded file to the ID column of its start point type and end point type;
Mapping settings: upload the column data in the file for the attribute mapping of the selected vertex type. Here, if the attribute name is the same as the header name of the file, the mapping attribute can be automatically matched, and there is no need to manually fill in the selection.
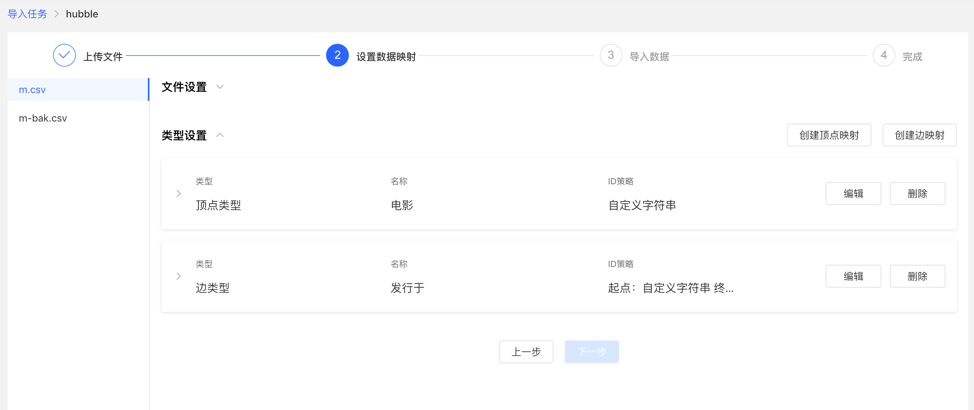
After completing the setting, the setting list will be displayed before proceeding to the next step. It supports the operations of adding, editing and deleting mappings.
Fill in the settings map:
Mapping list:
4.3.5 Import data
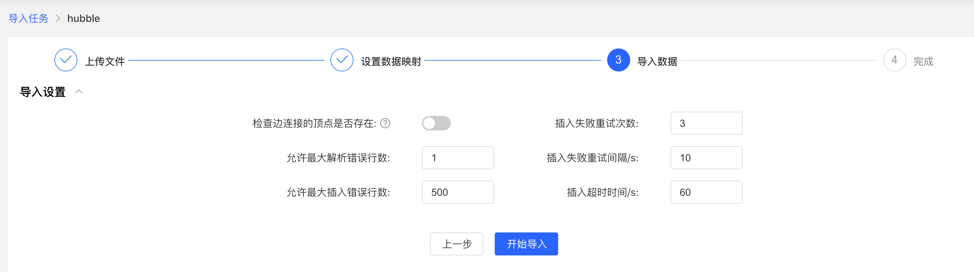
Before importing, you need to fill in the import setting parameters. After filling in, you can start importing data into the gallery.
- Import settings
- The import setting parameter items are as shown in the figure below, all set the default value, no need to fill in manually
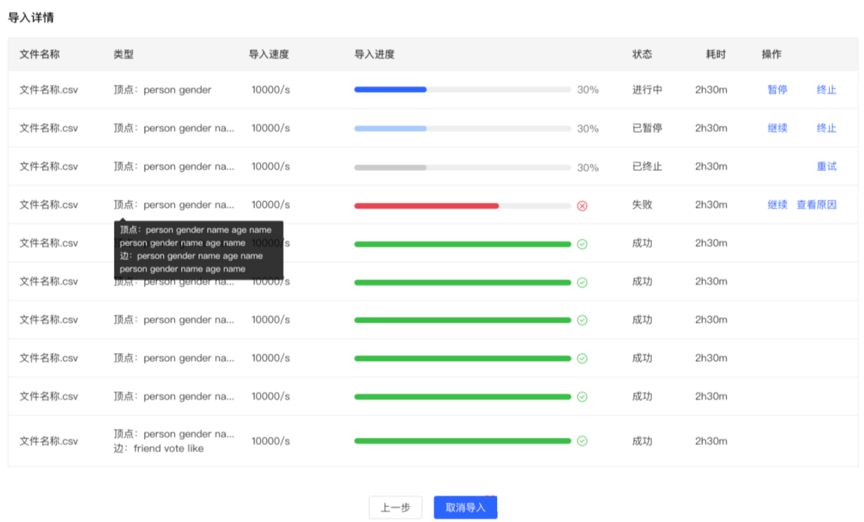
- Import details
- Click Start Import to start the file import task
- The import details provide the mapping type, import speed, import progress, time-consuming and the specific status of the current task set for each uploaded file, and can pause, resume, stop and other operations for each task
- If the import fails, you can view the specific reason
4.4 Data Analysis
4.4.1 Module entry
Left navigation:
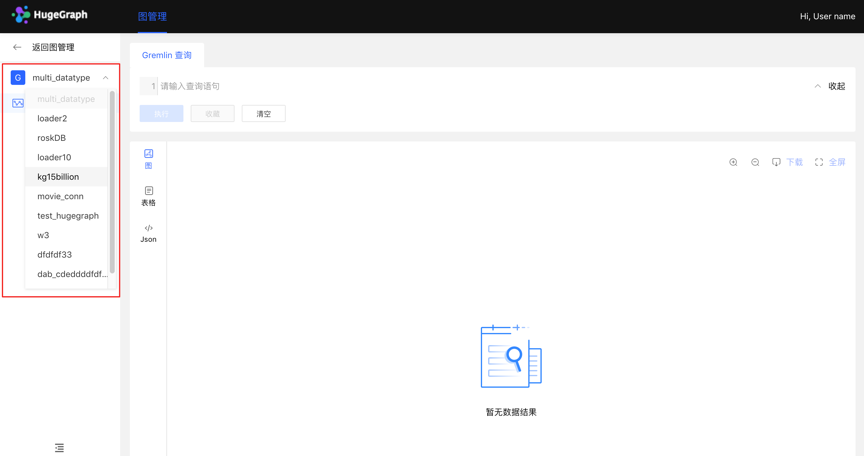
4.4.2 Multi-graphs switching
By switching the entrance on the left, flexibly switch the operation space of multiple graphs
4.4.3 Graph Analysis and Processing
HugeGraph supports Gremlin, a graph traversal query language of Apache TinkerPop3. Gremlin is a general graph database query language. By entering Gremlin statements and clicking execute, you can perform query and analysis operations on graph data, and create and delete vertices/edges. vertex/edge attribute modification, etc.
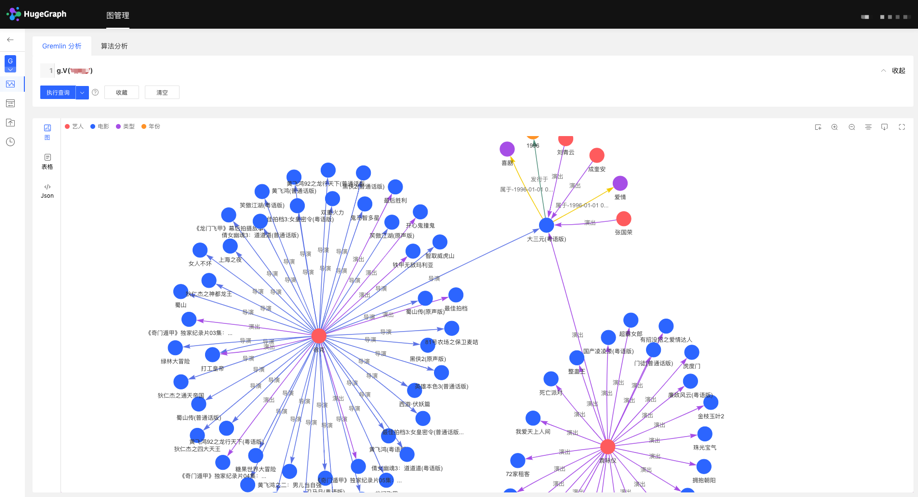
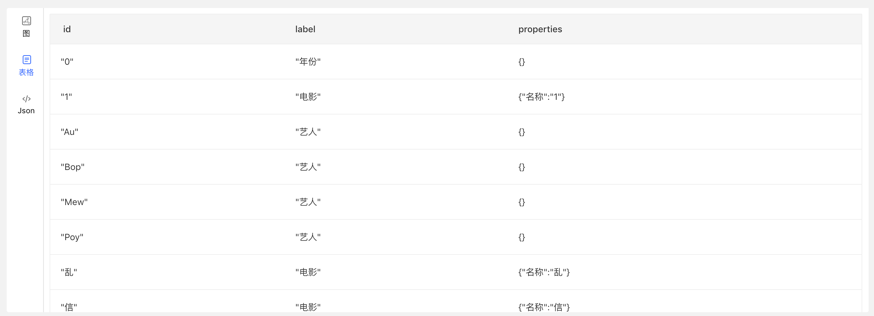
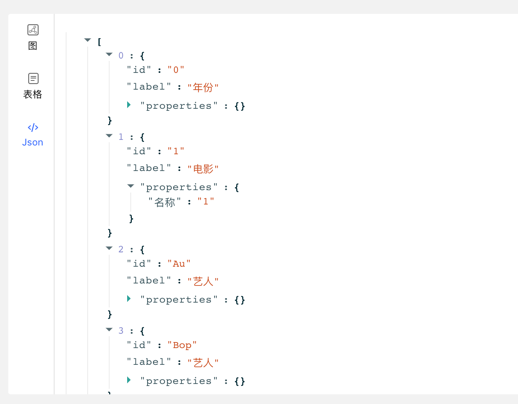
After Gremlin query, below is the graph result display area, which provides 3 kinds of graph result display modes: [Graph Mode], [Table Mode], [Json Mode].
⚠️ SEC Reminder: Hubble allows the direct input and execution of native Gremlin query statements on the web interface, which grants users relatively high operational privileges. Please avoid exposing the Hubble service to public network environments. It is recommended to ensure that the graph database server has enabled the Authentication System (Auth) combined with an IP Whitelist for strict permission control when in use, preventing unauthorized access or malware execution risks.
Support zoom, center, full screen, export and other operations.
【Picture Mode】
【Table mode】
【Json mode】
4.4.4 Data Details
Click the vertex/edge entity to view the data details of the vertex/edge, including vertex/edge type, vertex ID, attribute and corresponding value, expand the information display dimension of the graph, and improve the usability.
4.4.5 Multidimensional Path Query of Graph Results
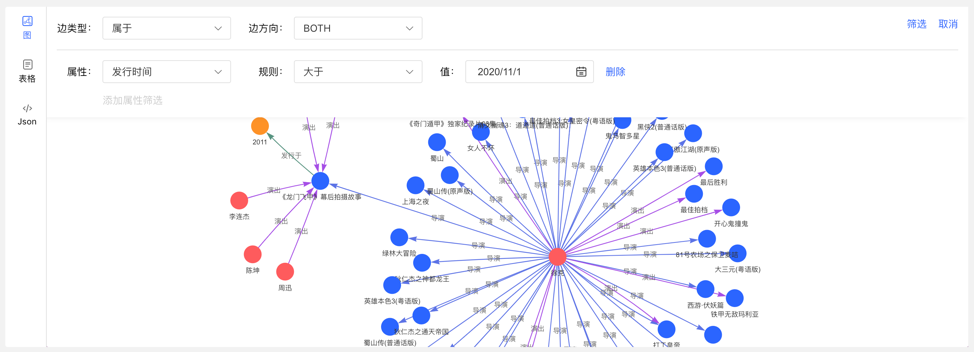
In addition to the global query, an in-depth customized query and hidden operations can be performed for the vertices in the query result to realize customized mining of graph results.
Right-click a vertex, and the menu entry of the vertex appears, which can be displayed, inquired, hidden, etc.
- Expand: Click to display the vertices associated with the selected point.
- Query: By selecting the edge type and edge direction associated with the selected point, and then selecting its attributes and corresponding filtering rules under this condition, a customized path display can be realized.
- Hide: When clicked, hides the selected point and its associated edges.
Double-clicking a vertex also displays the vertex associated with the selected point.
4.4.6 Add vertex/edge
4.4.6.1 Added vertex
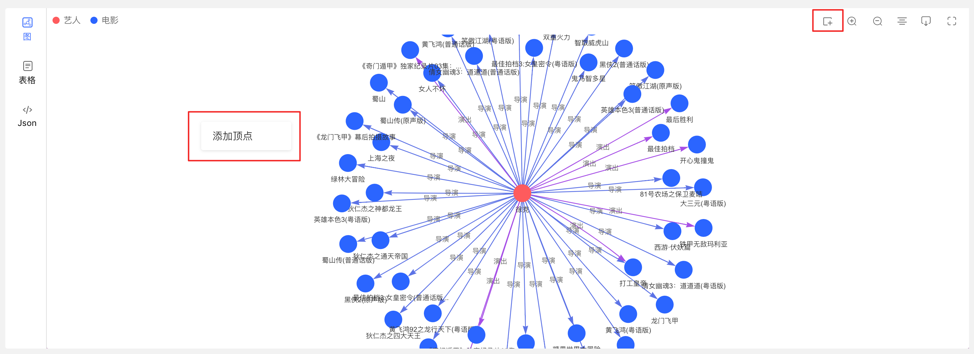
In the graph area, two entries can be used to dynamically add vertices, as follows:
- Click on the graph area panel, the Add Vertex entry appears
- Click the first icon in the action bar in the upper right corner
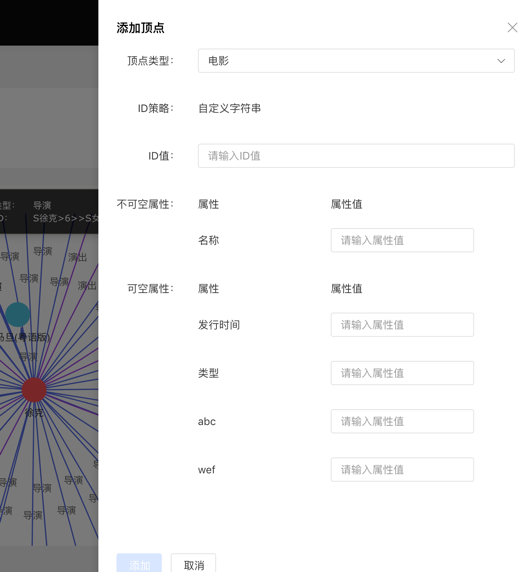
Complete the addition of vertices by selecting or filling in the vertex type, ID value, and attribute information.
The entry is as follows:
Add the vertex content as follows:
4.4.6.2 Add edge
Right-click a vertex in the graph result to add the outgoing or incoming edge of that point.
4.4.7 Execute the query of records and favorites
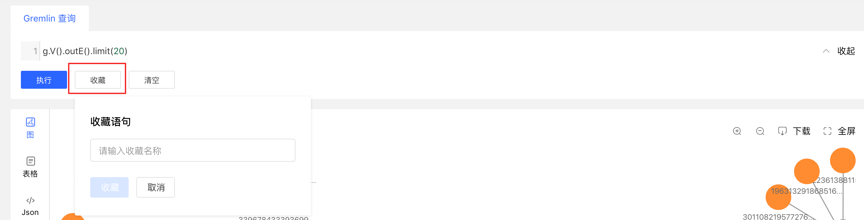
- Record each query record at the bottom of the graph area, including: query time, execution type, content, status, time-consuming, as well as [collection] and [load] operations, to achieve a comprehensive record of graph execution, with traces to follow, and Can quickly load and reuse execution content
- Provides the function of collecting sentences, which can be used to collect frequently used sentences, which is convenient for fast calling of high-frequency sentences.
4.5 Task Management
4.5.1 Module entry
Left navigation:
4.5.2 Task Management
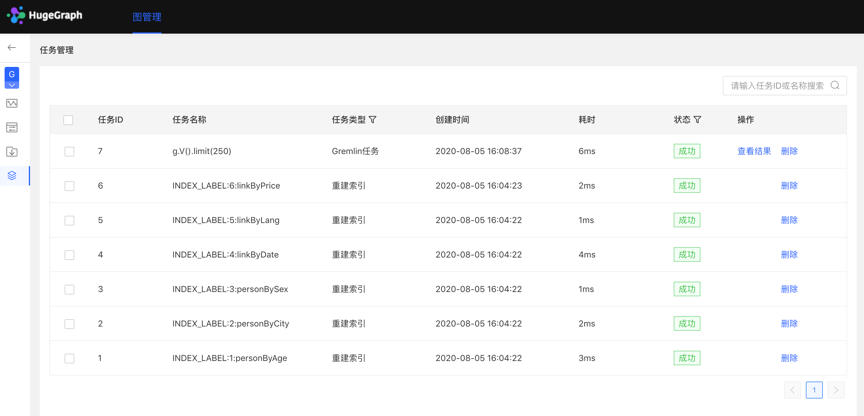
- Provide unified management and result viewing of asynchronous tasks. There are 4 types of asynchronous tasks, namely:
- gremlin: Gremlin tasks
- algorithm: OLAP algorithm task
- remove_schema: remove metadata
- rebuild_index: rebuild the index
- The list displays the asynchronous task information of the current graph, including task ID, task name, task type, creation time, time-consuming, status, operation, and realizes the management of asynchronous tasks.
- Support filtering by task type and status
- Support searching for task ID and task name
- Asynchronous tasks can be deleted or deleted in batches
4.5.3 Gremlin asynchronous tasks
- Create a task
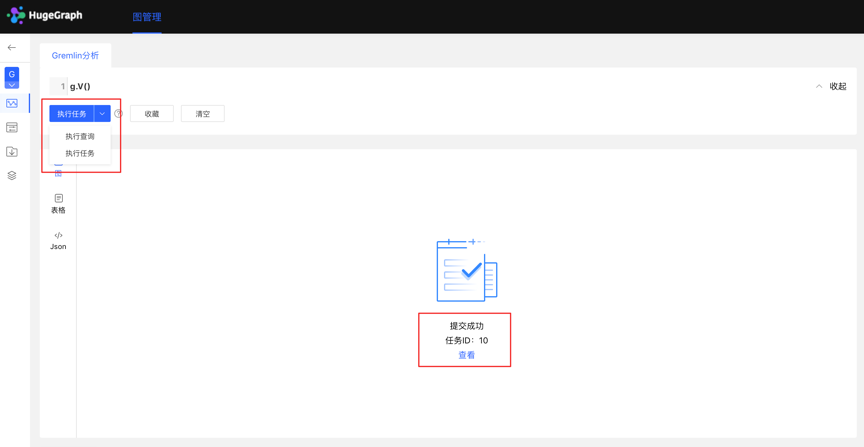
- The data analysis module currently supports two Gremlin operations, Gremlin query and Gremlin task; if the user switches to the Gremlin task, after clicking execute, an asynchronous task will be created in the asynchronous task center;
- Task submission
- After the task is submitted successfully, the graph area returns the submission result and task ID
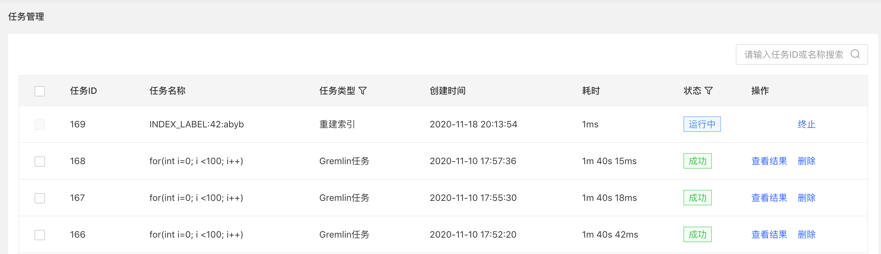
- Mission details
- Provide [View] entry, you can jump to the task details to view the specific execution of the current task After jumping to the task center, the currently executing task line will be displayed directly
Click to view the entry to jump to the task management list, as follows:
- View the results
- The results are displayed in the form of JSON
4.5.4 OLAP algorithm tasks
There is no visual OLAP algorithm execution on Hubble. You can call the RESTful API to perform OLAP algorithm tasks, find the corresponding tasks by ID in the task management, and view the progress and results.
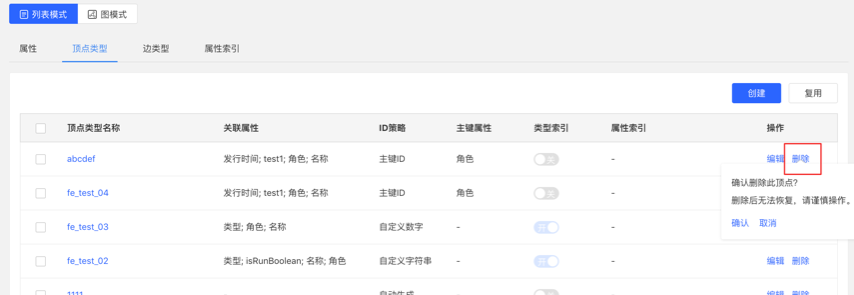
4.5.5 Delete metadata, rebuild index
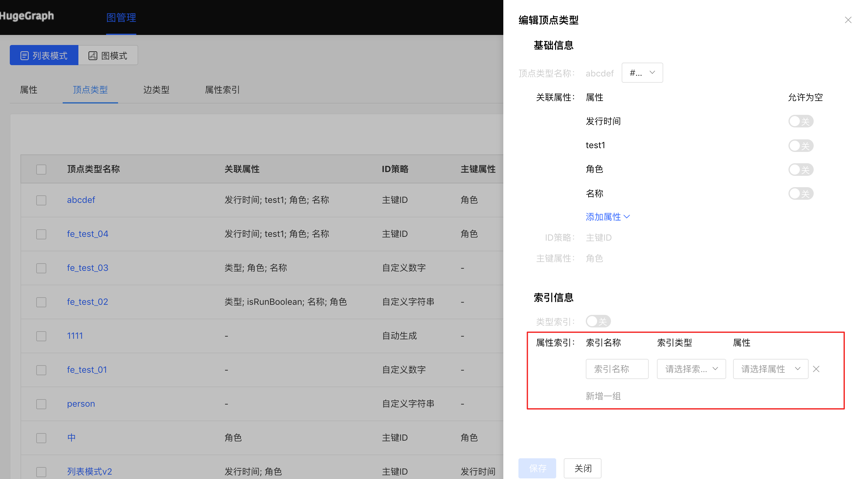
- Create a task
- In the metadata modeling module, when deleting metadata, an asynchronous task for deleting metadata can be created
- When editing an existing vertex/edge type operation, when adding an index, an asynchronous task of creating an index can be created
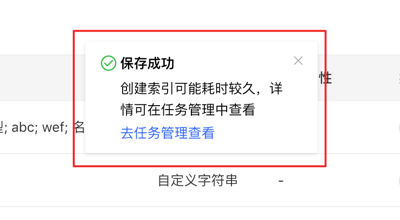
- Task details
- After confirming/saving, you can jump to the task center to view the details of the current task
5 Configuration
HugeGraph-Hubble can be configured through the conf/hugegraph-hubble.properties file.
5.1 Server Configuration
| Configuration Item | Default Value | Description |
|---|---|---|
hubble.host | 0.0.0.0 | The address that Hubble service binds to |
hubble.port | 8088 | The port that Hubble service listens on |
5.2 Server and PD
| Configuration | Default | Description |
|---|---|---|
pd.enabled | false | Whether to discover services through PD; keep false for a standalone Server |
server.direct_url | http://127.0.0.1:8080 | Server address used when pd.enabled=false |
pd.peers | 127.0.0.1:8686 | PD node address |
pd.server | 127.0.0.1:8620 | PD service address |
route.type | NODE_PORT | Service routing mode: NODE_PORT, DDS, or BOTH |
5.3 Gremlin Query Limits
These settings control query result limits to prevent memory issues:
| Configuration Item | Default Value | Description |
|---|---|---|
gremlin.suffix_limit | 250 | Maximum query suffix length |
gremlin.vertex_degree_limit | 100 | Maximum vertex degree to display |
gremlin.edges_total_limit | 500 | Maximum number of edges returned |
gremlin.batch_query_ids | 100 | ID batch query size |
2.2 - HugeGraph-Loader Quick Start
1 HugeGraph-Loader Overview
HugeGraph-Loader is the data import component of HugeGraph, which can convert data from various data sources into graph vertices and edges and import them into the graph database in batches.
Currently supported data sources include:
- Local disk file or directory, supports TEXT, CSV and JSON format files, supports compressed files
- HDFS file or directory supports compressed files
- Mainstream relational databases, such as MySQL, PostgreSQL, Oracle, SQL Server
Local disk files and HDFS files support resumable uploads.
It will be explained in detail below.
Note: HugeGraph-Loader requires HugeGraph Server service, please refer to HugeGraph-Server Quick Start to download and start Server
Testing Guide: For running HugeGraph-Loader tests locally, please refer to HugeGraph Toolchain Local Testing Guide
2 Get HugeGraph-Loader
HugeGraph-Loader is available in the following three ways:
- Use docker image (Convenient for Test/Dev)
- Download the compiled tarball
- Clone source code then compile and install
2.1 Use Docker image (Convenient for Test/Dev)
We can deploy the loader service using docker run -itd --name loader hugegraph/loader:1.5.0. For the data that needs to be loaded, it can be copied into the loader container either by mounting -v /path/to/data/file:/loader/file or by using docker cp.
Alternatively, to start the loader using docker-compose, the command is docker-compose up -d. An example of the docker-compose.yml is as follows:
The specific data loading process can be referenced under 4.5 User Docker to load data
Note:
The docker image of hugegraph-loader is a convenience release to start hugegraph-loader quickly, but not official distribution artifacts. You can find more details from ASF Release Distribution Policy.
Recommend to use
release tag(like1.5.0) for the stable version. Uselatesttag to experience the newest functions in development.
2.2 Download the compiled archive
Download the latest version of the HugeGraph-Toolchain release package:
2.3 Clone source code to compile and install
Clone the latest version of HugeGraph-Loader source package:
Due to the license limitation of the Oracle OJDBC, you need to manually install ojdbc to the local maven repository.
Visit the Oracle jdbc downloads page. Select Oracle Database 12c Release 2 (12.2.0.1) drivers, as shown in the following figure.
After opening the link, select “ojdbc8.jar”.
Install ojdbc8 to the local maven repository, enter the directory where ojdbc8.jar is located, and execute the following command.
Compile and generate tar package:
3 How to use
The basic process of using HugeGraph-Loader is divided into the following steps:
- Write graph schema
- Prepare data files
- Write input source map files
- Execute command import
3.1 Construct graph schema
This step is the modeling process. Users need to have a clear idea of their existing data and the graph model they want to create, and then write the schema to build the graph model.
For example, if you want to create a graph with two types of vertices and two types of edges, the vertices are “people” and “software”, the edges are “people know people” and “people create software”, and these vertices and edges have some attributes, For example, the vertex “person” has: “name”, “age” and other attributes, “Software” includes: “name”, “sale price” and other attributes; side “knowledge” includes: “date” attribute and so on.
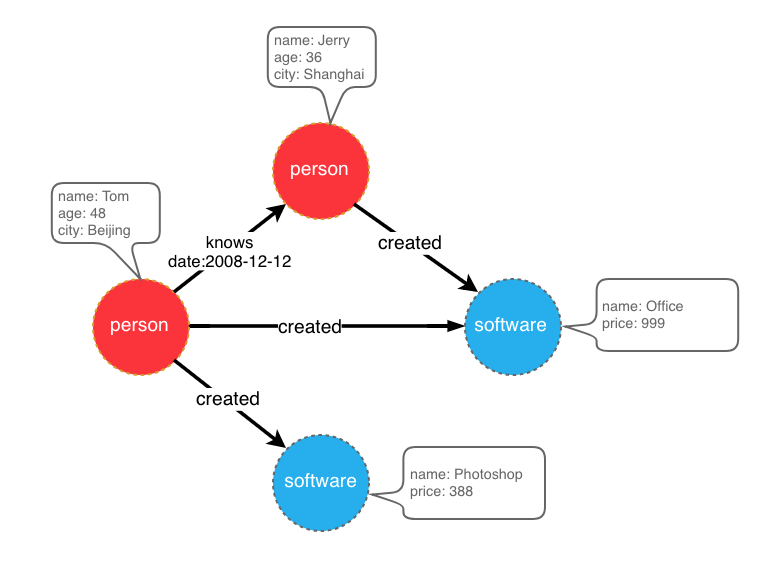
graph model example
After designing the graph model, we can use groovy to write the definition of schema and save it to a file, here named schema.groovy.
Please refer to the corresponding section in hugegraph-client for the detailed description of the schema.
3.2 Prepare data
The data sources currently supported by HugeGraph-Loader include:
- local disk file or directory
- HDFS file or directory
- Partial relational database
- Kafka topic
3.2.1 Data source structure
3.2.1.1 Local disk file or directory
The user can specify a local disk file as the data source. If the data is scattered in multiple files, a certain directory is also supported as the data source, but multiple directories are not supported as the data source for the time being.
For example, my data is scattered in multiple files, part-0, part-1 … part-n. To perform the import, it must be ensured that they are placed in one directory. Then in the loader’s mapping file, specify path as the directory.
Supported file formats include:
- TEXT
- CSV
- JSON
TEXT is a text file with custom delimiters, the first line is usually the header, and the name of each column is recorded, and no header line is allowed (specified in the mapping file). Each remaining row represents a record, which will be converted into a vertex/edge; each column of the row corresponds to a field, which will be converted into the id, label or attribute of the vertex/edge;
An example is as follows:
CSV is a TEXT file with commas , as delimiters. When a column value itself contains a comma, the column value needs to be enclosed in double quotes, for example:
The JSON file requires that each line is a JSON string, and the format of each line needs to be consistent.
3.2.1.2 HDFS file or directory
Users can also specify HDFS files or directories as data sources, all of the above requirements for local disk files or directories apply here. In addition, since HDFS usually stores compressed files, loader also provides support for compressed files, and local disk file or directory also supports compressed files.
Currently supported compressed file types include: GZIP, BZ2, XZ, LZMA, SNAPPY_RAW, SNAPPY_FRAMED, Z, DEFLATE, LZ4_BLOCK, LZ4_FRAMED, ORC, and PARQUET.
3.2.1.3 Mainstream relational database
The loader also supports some relational databases as data sources, and currently supports MySQL, PostgreSQL, Oracle, and SQL Server.
However, the requirements for the table structure are relatively strict at present. If association query needs to be done during the import process, such a table structure is not allowed. The associated query means: after reading a row of the table, it is found that the value of a certain column cannot be used directly (such as a foreign key), and you need to do another query to determine the true value of the column.
For example, Suppose there are three tables, person, software and created
If the id strategy of person or software is specified as PRIMARY_KEY when modeling (schema), choose name as the primary key (note: this is the concept of vertex-label in hugegraph), when importing edge data, the source vertex and target need to be spliced out. For the id of the vertex, you must go to the person/software table with p_id/s_id to find the corresponding name. In the case of the schema that requires additional query, the loader does not support it temporarily. In this case, the following two methods can be used instead:
- The id strategy of person and software is still specified as PRIMARY_KEY, but the id column of the person table and software table is used as the primary key attribute of the vertex, so that the id can be generated by directly splicing p_id and s_id with the label of the vertex when importing an edge;
- Specify the id policy of person and software as CUSTOMIZE, and then directly use the id column of the person table and the software table as the vertex id, so that p_id and s_id can be used directly when importing edges;
The key point is to make the edge use p_id and s_id directly, don’t check it again.
3.2.2 Prepare vertex and edge data
3.2.2.1 Vertex Data
The vertex data file consists of data line by line. Generally, each line is used as a vertex, and each column is used as a vertex attribute. The following description uses CSV format as an example.
- person vertex data (the data itself does not contain a header)
- software vertex data (the data itself contains the header)
3.2.2.2 Edge data
The edge data file consists of data line by line. Generally, each line is used as an edge. Some columns are used as the IDs of the source and target vertices, and other columns are used as edge attributes. The following uses JSON format as an example.
- knows edge data
- created edge data
3.3 Write data source mapping file
3.3.1 Mapping file overview
The mapping file of the input source is used to describe how to establish the mapping relationship between the input source data and the vertex type/edge type of the graph. It is organized in JSON format and consists of multiple mapping blocks, each of which is responsible for mapping an input source. Mapped to vertices and edges.
Specifically, each mapping block contains an input source and multiple vertex mapping and edge mapping blocks, and the input source block corresponds to the local disk file or directory, HDFS file or directory and relational database are responsible for describing the basic information of the data source, such as where the data is, what format, what is the delimiter, etc. The vertex map/edge map is bound to the input source, which columns of the input source can be selected, which columns are used as ids, which columns are used as attributes, and what attributes are mapped to each column, the values of the columns are mapped to what values of attributes, and so on.
In the simplest terms, each mapping block describes: where is the file to be imported, which type of vertices/edges each line of the file is to be used as which columns of the file need to be imported, and the corresponding vertices/edges of these columns. what properties, etc.
Note: The format of the mapping file before version 0.11.0 and the format after 0.11.0 has changed greatly. For the convenience of expression, the mapping file (format) before 0.11.0 is called version 1.0, and the version after 0.11.0 is version 2.0. And unless otherwise specified, the “map file” refers to version 2.0.
Two versions of the mapping file are given directly here (the above graph model and data file are described)
The 1.0 version of the mapping file is centered on the vertex and edge, and sets the input source; while the 2.0 version is centered on the input source, and sets the vertex and edge mapping. Some input sources (such as a file) can generate both vertices and edges. If you write in the 1.0 format, you need to write an input block in each of the vertex and edge mapping blocks. The two input blocks are exactly the same; and the 2.0 version only needs to write input once. Therefore, compared with version 1.0, version 2.0 can save some repetitive writing of input.
In the bin directory of hugegraph-loader-{version}, there is a script tool mapping-convert.sh that can directly convert the mapping file of version 1.0 to version 2.0. The usage is as follows:
A struct-v2.json will be generated in the same directory as struct.json.
3.3.2 Input Source
Input sources are currently divided into five categories: FILE, HDFS, JDBC, KAFKA and GRAPH, which are distinguished by the type node. We call them local file input sources, HDFS input sources, JDBC input sources, KAFKA input sources and GRAPH input source, which are described below.
3.3.2.1 Local file input source
- id: The id of the input source. This field is used to support some internal functions. It is not required (it will be automatically generated if it is not filled in). It is strongly recommended to write it, which is very helpful for debugging;
- skip: whether to skip the input source, because the JSON file cannot add comments, if you do not want to import an input source during a certain import, but do not want to delete the configuration of the input source, you can set it to true to skip it, the default is false, not required;
- input: input source map block, composite structure
- type: an input source type, file or FILE must be filled;
- path: the path of the local file or directory, the absolute path or the relative path relative to the mapping file, it is recommended to use the absolute path, required;
- file_filter: filter files with compound conditions from
path, compound structure, currently only supports configuration extensions, represented by child nodeextensions, the default is “*”, which means to keep all files; - format: the format of the local file, the optional values are CSV, TEXT and JSON, which must be uppercase and required;
- header: the column name of each column of the file, if not specified, the first line of the data file will be used as the header; when the file itself has a header and the header is specified, the first line of the file will be treated as a normal data line; JSON The file does not need to specify a header, optional;
- delimiter: The column delimiter of the file line, the default is comma
","as the delimiter, theJSONfile does not need to be specified, optional; - charset: the encoded character set of the file, the default is
UTF-8, optional; - date_format: custom date format, the default value is yyyy-MM-dd HH:mm:ss, optional; if the date is presented in the form of a timestamp, this item must be written as
timestamp(fixed writing); - time_zone: Set which time zone the date data is in, the default value is
GMT+8, optional; - skipped_line: The line to be skipped, compound structure, currently only the regular expression of the line to be skipped can be configured, described by the child node
regex, no line is skipped by default, optional; - compression: The compression format of the file, the optional values are NONE, GZIP, BZ2, XZ, LZMA, SNAPPY_RAW, SNAPPY_FRAMED, Z, DEFLATE, LZ4_BLOCK, LZ4_FRAMED, ORC and PARQUET, the default is NONE, which means a non-compressed file, optional;
- list_format: When a column of the file (non-JSON) is a collection structure (the Cardinality of the PropertyKey in the corresponding figure is Set or List), you can use this item to set the start character, separator, and end character of the column, compound structure :
- start_symbol: The start character of the collection structure column (the default value is
[, JSON format currently does not support specification) - elem_delimiter: the delimiter of the collection structure column (the default value is
|, JSON format currently only supports native,delimiter) - end_symbol: the end character of the collection structure column (the default value is
], the JSON format does not currently support specification)
- start_symbol: The start character of the collection structure column (the default value is
3.3.2.2 HDFS input source
The nodes and meanings of the above local file input source are basically applicable here. Only the different and unique nodes of the HDFS input source are listed below.
- type: input source type, must fill in hdfs or HDFS, required;
- path: the path of the HDFS file or directory, it must be the absolute path of HDFS, required;
- core_site_path: the path of the core-site.xml file of the HDFS cluster, the key point is to specify the address of the NameNode (
fs.default.name) and the implementation of the file system (fs.hdfs.impl);
3.3.2.3 JDBC input source
As mentioned above, it supports multiple relational databases, but because their mapping structures are very similar, they are collectively referred to as JDBC input sources, and then use the vendor node to distinguish different databases.
- type: input source type, must fill in jdbc or JDBC, required;
- vendor: database type, optional options are [MySQL, PostgreSQL, Oracle, SQLServer], case-insensitive, required;
- driver: the type of driver used by jdbc, required;
- url: the url of the database that jdbc wants to connect to, required;
- database: the name of the database to be connected, required;
- schema: The name of the schema to be connected, different databases have different requirements, and the details are explained below;
- table: the name of the table to be connected, at least one of
tableorcustom_sqlis required; - custom_sql: custom SQL statement, at least one of
tableorcustom_sqlis required; - username: username to connect to the database, required;
- password: password for connecting to the database, required;
- batch_size: The size of one page when obtaining table data by page, the default is 500, optional;
MYSQL
| Node | Fixed value or common value |
|---|---|
| vendor | MYSQL |
| driver | com.mysql.cj.jdbc.Driver |
| url | jdbc:mysql://127.0.0.1:3306 |
schema: nullable, if filled in, it must be the same as the value of database
POSTGRESQL
| Node | Fixed value or common value |
|---|---|
| vendor | POSTGRESQL |
| driver | org.postgresql.Driver |
| url | jdbc:postgresql://127.0.0.1:5432 |
schema: nullable, default is “public”
ORACLE
| Node | Fixed value or common value |
|---|---|
| vendor | ORACLE |
| driver | oracle.jdbc.driver.OracleDriver |
| url | jdbc:oracle:thin:@127.0.0.1:1521 |
schema: nullable, the default value is the same as the username
SQLSERVER
| Node | Fixed value or common value |
|---|---|
| vendor | SQLSERVER |
| driver | com.microsoft.sqlserver.jdbc.SQLServerDriver |
| url | jdbc:sqlserver://127.0.0.1:1433 |
schema: required
3.3.2.4 Kafka input source
- type: input source type,
kafkaorKAFKA, required; - bootstrap_server: set the list of kafka bootstrap servers;
- topic: the topic to subscribe to;
- group: group of Kafka consumers;
- from_beginning: set whether to read from the beginning;
- format: format of the local file, options are CSV, TEXT and JSON, must be uppercase, required;
- header: column name of each column of the file, if not specified, the first line of the data file will be used as the header; when the file itself has a header and the header is specified, the first line of the file will be treated as an ordinary data line; JSON files do not need to specify the header, optional;
- delimiter: delimiter of the file line, default is comma “,” as delimiter, JSON files do not need to specify, optional;
- charset: encoding charset of the file, default is UTF-8, optional;
- date_format: customized date format, default value is yyyy-MM-dd HH:mm:ss, optional; if the date is presented in the form of timestamp, this item must be written as timestamp (fixed);
- extra_date_formats: a customized list of another date formats, empty by default, optional; each item in the list is an alternate date format to the date_format specified date format;
- time_zone: set which time zone the date data is in, default is GMT+8, optional;
- skipped_line: the line you want to skip, composite structure, currently can only configure the regular expression of the line to be skipped, described by the child node regex, the default is not to skip any line, optional;
- early_stop: the record pulled from Kafka broker at a certain time is empty, stop the task, default is false, only for debugging, optional;
3.3.2.5 GRAPH input Source
- type: Data source type; must be filled in as
graphorGRAPH(required); - graphspace: Source graphSpace name; default is
DEFAULT; - graph: Source graph name (required);
- username: HugeGraph username;
- password: HugeGraph password;
- selected_vertices: Filtering rules for vertices to be synchronized;
- ignored_vertices: Filtering rules for vertices to be ignored;
- selected_edges: Filtering rules for edges to be synchronized;
- ignored_edges: Filtering rules for edges to be ignored;
- pd-peers: HugeGraph-PD node addresses;
- meta-endpoints: Meta service endpoints of the source cluster;
- cluster: Source cluster name;
- batch_size: Batch size for reading data from the source graph; default is 500;
3.3.3 Vertex and Edge Mapping
The nodes of vertex and edge mapping (a key in the JSON file) have a lot of the same parts. The same parts are introduced first, and then the unique nodes of vertex map and edge map are introduced respectively.
Nodes of the same section
- label:
labelto which the vertex/edge data to be imported belongs, required; - field_mapping: Map the column name of the input source column to the attribute name of the vertex/edge, optional;
- value_mapping: map the data value of the input source to the attribute value of the vertex/edge, optional;
- selected: select some columns to insert, other unselected ones are not inserted, cannot exist at the same time as
ignored, optional; - ignored: ignore some columns so that they do not participate in insertion, cannot exist at the same time as
selected, optional; - null_values: You can specify some strings to represent null values, such as “NULL”. If the vertex/edge attribute corresponding to this column is also a nullable attribute, the value of this attribute will not be set when constructing the vertex/edge, optional ;
- update_strategies: If the data needs to be updated in batches in a specific way, you can specify a specific update strategy for each attribute (see below for details), optional;
- unfold: Whether to unfold the column, each unfolded column will form a row with other columns, which is equivalent to unfolding into multiple rows; for example, the value of a certain column (id column) of the file is
[1,2,3], The values of other columns are18,Beijing. When unfold is set, this row will become 3 rows, namely:1,18,Beijing,2,18,Beijingand3,18, Beijing. Note that this will only expand the column selected as id. Default false, optional;
Update strategy supports 8 types: (requires all uppercase)
- Value accumulation:
SUM - Take the greater of the two numbers/dates:
BIGGER - Take the smaller of two numbers/dates:
SMALLER - Set property takes union:
UNION - Set attribute intersection:
INTERSECTION - List attribute append element:
APPEND - List/Set attribute delete element:
ELIMINATE - Override an existing property:
OVERRIDE
Note: If the newly imported attribute value is empty, the existing old data will be used instead of the empty value. For the effect, please refer to the following example
Note : After adopting the batch update strategy, the number of disk read requests will increase significantly, and the import speed will be several times slower than that of pure write coverage (at this time HDD disk [IOPS](https://en.wikipedia .org/wiki/IOPS) will be the bottleneck, SSD is recommended for speed)
Unique Nodes for Vertex Maps
- id: Specify a column as the id column of the vertex. When the vertex id policy is
CUSTOMIZE, it is required; when the id policy isPRIMARY_KEY, it must be empty;
Unique Nodes for Edge Maps
- source: Select certain columns of the input source as the id column of source vertex. When the id policy of the source vertex is
CUSTOMIZE, a certain column must be specified as the id column of the vertex; when the id policy of the source vertex isWhen PRIMARY_KEY, one or more columns must be specified for splicing the id of the generated vertex, that is, no matter which id strategy is used, this item is required; - target: Specify certain columns as the id columns of target vertex, similar to source, so I won’t repeat them;
- unfold_source: Whether to unfold the source column of the file, the effect is similar to that in the vertex map, and will not be repeated;
- unfold_target: Whether to unfold the target column of the file, the effect is similar to that in the vertex mapping, and will not be repeated;
3.4 Execute command import
After preparing the graph model, data file, and input source mapping relationship file, the data file can be imported into the graph database.
The import process is controlled by commands submitted by the user, and the user can control the specific process of execution through different parameters.
3.4.1 Parameter description
| Parameter | Default value | Required or not | Description |
|---|---|---|---|
-f or --file | Y | Path to configure script | |
-g or --graph | hugegraph | Graph name | |
--graphspace | DEFAULT | Graph space name | |
-s or --schema | Schema file path; optional when the Schema already exists | ||
-h or --host or -i | localhost | Address of HugeGraphServer | |
-p or --port | 8080 | Port number of HugeGraphServer | |
--username | null | When HugeGraphServer enables permission authentication, the username of the current graph | |
--password | null | When HugeGraphServer enables permission authentication, the password of the current graph | |
--create-graph | false | Whether to automatically create the graph if it does not exist | |
--token | null | When HugeGraphServer has enabled authorization authentication, the token of the current graph | |
--protocol | http | Protocol for sending requests to the server, optional http or https | |
--pd-peers | PD service node addresses | ||
--pd-token | Token for accessing PD service | ||
--meta-endpoints | Meta information storage service addresses | ||
--direct | false | Whether to directly connect to HugeGraph-Store | |
--route-type | NODE_PORT | Route selection method (optional values: NODE_PORT / DDS / BOTH) | |
--cluster | hg | Cluster name | |
--trust-store-file | When the request protocol is https, the client’s certificate file path | ||
--trust-store-password | When the request protocol is https, the client certificate password | ||
--clear-all-data | false | Whether to clear the original data on the server before importing data | |
--clear-timeout | 240 | Timeout for clearing the original data on the server before importing data | |
--incremental-mode | false | Whether to use the breakpoint resume mode; only input sources FILE and HDFS support this mode. Enabling this mode allows starting the import from where the last import stopped | |
--failure-mode | false | When failure mode is true, previously failed data will be imported. Generally, the failed data file needs to be manually corrected and edited before re-importing | |
--batch-insert-threads | CPUs | Batch insert thread pool size (CPUs is the number of logical cores available to the current OS) | |
--single-insert-threads | 8 | Size of single insert thread pool | |
--max-conn | 4 * CPUs | The maximum number of HTTP connections between HugeClient and HugeGraphServer; it is recommended to adjust this when adjusting threads | |
--max-conn-per-route | 2 * CPUs | The maximum number of HTTP connections for each route between HugeClient and HugeGraphServer; it is recommended to adjust this item when adjusting threads | |
--batch-size | 500 | The number of data items in each batch when importing data | |
--max-parse-errors | 1 | The maximum number of data parsing errors allowed (per line); the program exits when this value is reached | |
--max-insert-errors | 500 | The maximum number of data insertion errors allowed (per row); the program exits when this value is reached | |
--timeout | 60 | Timeout (seconds) for insert result return | |
--shutdown-timeout | 10 | Waiting time for multithreading to stop (seconds) | |
--retry-times | 3 | Maximum number of retries after a timeout | |
--retry-interval | 10 | Interval before retry (seconds) | |
--check-vertex | false | Whether to check if the vertices connected by the edge exist when inserting the edge | |
--print-progress | true | Whether to print the number of imported items in real time on the console | |
--dry-run | false | Enable this mode to only parse data without importing; usually used for testing | |
--help or -help | false | Print help information | |
--parser-threads or --parallel-count | max(2,CPUs/2) | Number of parallel read pipelines; --parallel-count is deprecated | |
--start-file | 0 | Start file index for partial loading | |
--end-file | -1 | End file index for partial loading | |
--scatter-sources | false | Scatter multiple sources for I/O optimization | |
--cdc-flush-interval | 30000 | The flush interval for Flink CDC | |
--cdc-sink-parallelism | 1 | The sink parallelism for Flink CDC | |
--max-read-errors | 1 | The maximum number of read error lines before exiting | |
--max-read-lines | -1L | The maximum number of read lines, task stops when reached | |
--test-mode | false | Whether the loader works in test mode | |
--use-prefilter | false | Whether to filter vertex in advance | |
--short-id | Mapping customized ID to shorter ID | ||
--vertex-edge-limit | -1L | The maximum number of vertex’s edges | |
--sink-type | true | Sink to different storage type switch | |
--vertex-partitions | 64 | The number of partitions of the HBase vertex table | |
--edge-partitions | 64 | The number of partitions of the HBase edge table | |
--vertex-table-name | HBase vertex table name | ||
--edge-table-name | HBase edge table name | ||
--hbase-zk-quorum | HBase ZooKeeper quorum | ||
--hbase-zk-port | HBase ZooKeeper port | ||
--hbase-zk-parent | HBase ZooKeeper parent | ||
--restore | false | Set graph mode to RESTORING | |
--backend | hstore | The backend store type when creating graph if not exists | |
--serializer | binary | The serializer type when creating graph if not exists | |
--scheduler-type | distributed | The task scheduler type when creating graph if not exists | |
--batch-failure-fallback | true | Whether to fallback to single insert when batch insert fails |
3.4.2 Breakpoint Continuation Mode
Usually, the Loader task takes a long time to execute. If the import interrupt process exits for some reason, and next time you want to continue the import from the interrupted point, this is the scenario of using breakpoint continuation.
The user sets the command line parameter –incremental-mode to true to open the breakpoint resume mode. The key to breakpoint continuation lies in the progress file. When the import process exits, the import progress at the time of exit will be recorded.
Recorded in the progress file, the progress file is located in the ${struct} directory, the file name is like load-progress ${date}, ${struct} is the prefix of the mapping file, and ${date} is the start of the import
moment. For example, for an import task started at 2019-10-10 12:30:30, the mapping file used is struct-example.json, then the path of the progress file is the same as struct-example.json
Sibling struct-example/load-progress 2019-10-10 12:30:30.
Note: The generation of progress files is independent of whether –incremental-mode is turned on or not, and a progress file is generated at the end of each import.
If the data file formats are all legal and the import task is stopped by the user (CTRL + C or kill, kill -9 is not supported), that is to say, if there is no error record, the next import only needs to be set to Continue for the breakpoint.
But if the limit of –max-parse-errors or –max-insert-errors is reached because too much data is invalid or network abnormality is reached, Loader will record these original rows that failed to insert into In the failed file, after the user modifies the data lines in the failed file, set –reload-failure to true to import these “failed files” as input sources (does not affect the normal file import), Of course, if there is still a problem with the modified data line, it will be logged again to the failure file (don’t worry about duplicate lines).
Each vertex map or edge map will generate its own failure file when data insertion fails. The failure file is divided into a parsing failure file (suffix .parse-error) and an insertion failure file (suffix .insert-error).
They are stored in the ${struct}/current directory. For example, there is a vertex mapping person, and an edge mapping knows in the mapping file, each of which has some error lines. When the Loader exits, you will see the following files in the ${struct}/current directory:
- person-b4cd32ab.parse-error: Vertex map person parses wrong data
- person-b4cd32ab.insert-error: Vertex map person inserts wrong data
- knows-eb6b2bac.parse-error: edge map knows parses wrong data
- knows-eb6b2bac.insert-error: edge map knows inserts wrong data
.parse-error and .insert-error do not always exist together. Only lines with parsing errors will have .parse-error files, and only lines with insertion errors will have .insert-error files.
3.4.3 logs directory file description
The log and error data during program execution will be written into the hugegraph-loader.log file.
3.4.4 Execute command
Run bin/hugegraph-loader and pass in parameters
4 Complete example
Given below is an example in the example directory of the hugegraph-loader package. (GitHub address)
4.1 Prepare data
Vertex file: example/file/vertex_person.csv
Vertex file: example/file/vertex_software.txt
Edge file: example/file/edge_knows.json
Edge file: example/file/edge_created.json
4.2 Write schema
4.3 Write the input source mapping file example/file/struct.json
4.4 Command to import
After the import is complete, statistics similar to the following will appear:
4.5 Use Docker to load data
4.5.1 Use docker exec to load data directly
4.5.1.1 Prepare data
If you just want to try out the loader, you can import the built-in example dataset without needing to prepare additional data yourself.
If using custom data, before importing data with the loader, we need to copy the data into the container.
First, following the steps in 4.1–4.3, we can prepare the data and then use docker cp to copy the prepared data into the loader container.
Suppose we’ve prepared the corresponding dataset following the above steps, stored in the hugegraph-dataset folder with the following file structure:
Copy the files into the container.
4.5.1.2 Data loading
Taking the built-in example dataset as an example, we can use the following command to load the data.
If you need to import your custom dataset, you need to modify the paths for -f (data script) and -s (schema) configurations.
You can refer to 3.4.1-Parameter description for the rest of the parameters.
If loading a custom dataset, following the previous example, you would use:
If
loaderandserverare in the same Docker network, you can specify-h {server_container_name}; otherwise, you need to specify the IP of theserverhost (in our example,server_container_nameisserver).
Then we can see the result:
You can also use curl or hubble to observe the import result. Here’s an example using curl:
If you want to check the import result of edges, you can use curl "http://localhost:8080/graphs/hugegraph/graph/edges" | gunzip.
4.5.2 Enter the docker container to load data
Besides using docker exec directly for data import, we can also enter the container for data loading. The basic process is similar to 4.5.1.
Enter the container by docker exec -it loader bash and execute the command:
The results of the execution will be similar to those shown in 4.5.1.
4.6 Import data by spark-loader
The current source uses Spark 3.2.2 and Scala 2.12. Other combinations need independent verification.
The parameters of spark-loader are divided into two parts. Note: Because the abbreviations of
these two-parameter names have overlapping parts, please use the full name of the parameter.
And there is no need to guarantee the order between the two parameters.
- hugegraph parameters (Reference: hugegraph-loader parameter description )
- Spark task submission parameters (Reference: Submitting Applications)
Example:
2.3 - HugeGraph-Tools Quick Start
1 HugeGraph-Tools Overview
HugeGraph-Tools is an automated deployment, management and backup/restore component of HugeGraph.
Testing Guide: For running HugeGraph-Tools tests locally, please refer to HugeGraph Toolchain Local Testing Guide
2 Get HugeGraph-Tools
HugeGraph-Tools is included in the Toolchain distribution. You can download the distribution or build it from source.
- Download the compiled tarball
- Clone source code then compile and install
2.1 Download the compiled archive
Download the latest version of the HugeGraph-Toolchain package:
2.2 Clone source code to compile and install
Please ensure that the wget command is installed before compiling the source code
Download the latest version of the HugeGraph-Tools source package:
Compile and generate tar package:
Generate tar package hugegraph-tools-${version}.tar.gz
3 How to use
3.1 Function overview
After decompression, enter the hugegraph-tools directory, you can use bin/hugegraph or bin/hugegraph help to view the usage information. mainly divided:
- Graph management type, graph-mode-set, graph-mode-get, graph-list, graph-get, graph-clear, graph-create, graph-clone and graph-drop
- Asynchronous task management type, task-list, task-get, task-delete, task-cancel and task-clear
- Gremlin type, gremlin-execute and gremlin-schedule
- Backup/Restore type, backup, restore, migrate, schedule-backup and dump
- Authentication data backup/restore type, auth-backup and auth-restore
- Install deployment type, deploy, clear, start-all and stop-all
3.2 [options]-Global Variable
options is a global variable of HugeGraph-Tools, which can be configured in hugegraph-tools/bin/hugegraph, including:
- –graph,HugeGraph-Tools The name of the graph to operate on, the default value is hugegraph
- –url,The service address of HugeGraph-Server, the default is http://127.0.0.1:8080
- –user,When HugeGraph-Server opens authentication, pass username
- –password,When HugeGraph-Server opens authentication, pass the user’s password
- –timeout,Timeout when connecting to HugeGraph-Server, the default is 30s
- –protocol, connection protocol, either http or https; the default is http
- –trust-store-file,The path of the certificate file, when –url uses https, the truststore file used by HugeGraph-Client, the default is empty, which means using the built-in truststore file conf/hugegraph.truststore of hugegraph-tools
- –trust-store-password,The password of the certificate file, when –url uses https, the password of the truststore used by HugeGraph-Client, the default is empty, representing the password of the built-in truststore file of hugegraph-tools
The above global variables can also be set through environment variables. One way is to use export on the command line to set temporary environment variables, which are valid until the command line is closed
| Global Variable | Environment Variable | Example |
|---|---|---|
| –url | HUGEGRAPH_URL | export HUGEGRAPH_URL=http://127.0.0.1:8080 |
| –graph | HUGEGRAPH_GRAPH | export HUGEGRAPH_GRAPH=hugegraph |
| –user | HUGEGRAPH_USERNAME | export HUGEGRAPH_USERNAME=admin |
| –password | HUGEGRAPH_PASSWORD | export HUGEGRAPH_PASSWORD=test |
| –timeout | HUGEGRAPH_TIMEOUT | export HUGEGRAPH_TIMEOUT=30 |
| –trust-store-file | HUGEGRAPH_TRUST_STORE_FILE | export HUGEGRAPH_TRUST_STORE_FILE=/tmp/trust-store |
| –trust-store-password | HUGEGRAPH_TRUST_STORE_PASSWORD | export HUGEGRAPH_TRUST_STORE_PASSWORD=xxxx |
Another way is to set the environment variable in the bin/hugegraph script:
3.3 Graph Management Type, graph-mode-set, graph-mode-get, graph-list, graph-get, graph-clear, graph-create, graph-clone and graph-drop
- graph-mode-set, set graph restore mode
- –graph-mode or -m, required, specifies the mode to be set, legal values include [NONE, RESTORING, MERGING, LOADING]
- graph-mode-get, get graph restore mode
- graph-list, list all graphs in a HugeGraph-Server
- graph-get, get a graph and its storage backend type
- graph-clear, clear all schema and data of a graph
- –confirm-message or -c, required, delete confirmation information, manual input is required, double confirmation to prevent accidental deletion, “I’m sure to delete all data”, including double quotes
- graph-create, create a new graph with configuration file
- –name or -n, optional, the name of the new graph, default is hugegraph
- –file or -f, required, the path to the graph configuration file
- graph-clone, clone an existing graph
- –name or -n, optional, the name of the cloned graph, default is hugegraph
- –clone-graph-name, optional, the name of the source graph to clone from, default is hugegraph
- graph-drop, drop a graph (different from graph-clear, this completely removes the graph)
- –confirm-message or -c, required, confirmation message “I’m sure to drop the graph”, including double quotes
When you need to restore the backup graph to a new graph, you need to set the graph mode to RESTORING mode; when you need to merge the backup graph into an existing graph, you need to first set the graph mode to MERGING model.
3.4 Asynchronous task management Type,task-list、task-get and task-delete
- task-list,List the asynchronous tasks in a graph, which can be filtered according to the status of the tasks
- –status,Optional, specify the status of the task to view, i.e. filter tasks by status
- –limit,Optional, specify the number of tasks to be obtained, the default is -1, which means to obtain all eligible tasks
- task-get,Get detailed information about an asynchronous task
- –task-id,Required, specifies the ID of the asynchronous task
- task-delete,Delete information about an asynchronous task
- –task-id,Required, specifies the ID of the asynchronous task
- task-cancel,Cancel the execution of an asynchronous task
- –task-id,ID of the asynchronous task to cancel
- task-clear,Clean up completed asynchronous tasks
- –force,Optional. When set, it means to clean up all asynchronous tasks. Unfinished ones are canceled first, and then all asynchronous tasks are cleared. By default, only completed asynchronous tasks are cleaned up
3.5 Gremlin Type,gremlin-execute and gremlin-schedule
⚠️ SEC Reminder: The execution of Gremlin depends on the actual logic of the statements, which may involve scenarios such as large-scale data modification and high-risk system calls with potential implicit hazards. Please use this tool only in secure and trusted network environments. It is imperative to configure and secure HugeGraph-Server with the Authentication System (Auth) and an IP Whitelist to restrict execution requests on the server side. Never hand over the tool or expose the execution entry to unauthorized personnel.
- gremlin-execute, send Gremlin statements to HugeGraph-Server to execute query or modification operations, execute synchronously, and return results after completion
- –file or -f, specify the script file to execute, UTF-8 encoding, mutually exclusive with –script
- –script or -s, specifies the script string to execute, mutually exclusive with –file
- –aliases or -a, Gremlin alias settings, the format is: key1=value1,key2=value2,…
- –bindings or -b, Gremlin binding settings, the format is: key1=value1,key2=value2,…
- –language or -l, the language of the Gremlin script, the default is gremlin-groovy
–file and –script are mutually exclusive, one of them must be set
- gremlin-schedule, send Gremlin statements to HugeGraph-Server to perform query or modification operations, asynchronous execution, and return the asynchronous task id immediately after the task is submitted
- –file or -f, specify the script file to execute, UTF-8 encoding, mutually exclusive with –script
- –script or -s, specifies the script string to execute, mutually exclusive with –file
- –bindings or -b, Gremlin binding settings, the format is: key1=value1,key2=value2,…
- –language or -l, the language of the Gremlin script, the default is gremlin-groovy
–file and –script are mutually exclusive, one of them must be set
3.6 Backup/Restore Type
- backup, back up the schema or data in a certain graph out of the HugeGraph system, and store it on the local disk or HDFS in the form of JSON
- –format, the backup format, optional values include [json, text], the default is json
- –all-properties, whether to back up all properties of vertices/edges, only valid when –format is text, default false
- –label, the type of vertices/edges to be backed up, only valid when –format is text, only valid when backing up vertices or edges
- –properties, properties of vertices/edges to be backed up, separated by commas, only valid when –format is text, valid only when backing up vertices or edges
- –compress, whether to compress data during backup, the default is true
- –directory or -d, the directory to store schema or data, the default is ‘./{graphName}’ for local directory, and ‘{fs.default.name}/{graphName}’ for HDFS
- –huge-types or -t, the data types to be backed up, separated by commas, the optional value is ‘all’ or a combination of one or more [vertex, edge, vertex_label, edge_label, property_key, index_label], ‘all’ Represents all 6 types, namely vertices, edges and all schemas
- –log or -l, specify the log directory, the default is the current directory
- –retry, specify the number of failed retries, the default is 3
- –thread-num or -T, the number of threads to use, default is Math.min(10, Math.max(4, CPUs / 2))
- –split-size or -s, specifies the size of splitting vertices or edges when backing up, the default is 1048576
- -D, use the mode of -Dkey=value to specify dynamic parameters, and specify HDFS configuration items when backing up data to HDFS, for example: -Dfs.default.name=hdfs://localhost:9000
- restore, restore schema or data stored in JSON format to a new graph (RESTORING mode) or merge into an existing graph (MERGING mode)
- –directory or -d, the directory to store schema or data, the default is ‘./{graphName}’ for local directory, and ‘{fs.default.name}/{graphName}’ for HDFS
- –clean, whether to delete the directory specified by –directory after the recovery map is completed, the default is false
- –huge-types or -t, data types to restore, separated by commas, optional value is ‘all’ or a combination of one or more [vertex, edge, vertex_label, edge_label, property_key, index_label], ‘all’ Represents all 6 types, namely vertices, edges and all schemas
- –log or -l, specify the log directory, the default is the current directory
- –retry, specify the number of failed retries, the default is 3
- –thread-num or -T, the number of threads to use, default is Math.min(10, Math.max(4, CPUs / 2))
- -D, use the mode of -Dkey=value to specify dynamic parameters, which are used to specify HDFS configuration items when restoring graphs from HDFS, for example: -Dfs.default.name=hdfs://localhost:9000
restore command can be used only if –format is executed as backup for json
- migrate, migrate the currently connected graph to another HugeGraphServer
- –target-graph, the name of the target graph, the default is hugegraph
- –target-url, the HugeGraphServer where the target graph is located, the default is http://127.0.0.1:8081
- –target-user, the username used to access the target graph
- –target-password, the password to access the target map
- –target-timeout, the timeout for accessing the target map
- –target-trust-store-file, access the truststore file used by the target graph
- –target-trust-store-password, the password to access the truststore used by the target map
- –directory or -d, during the migration process, the directory where the schema or data of the source graph is stored. For a local directory, the default is ‘./{graphName}’; for HDFS, the default is ‘{fs.default.name}/ {graphName}’
- –huge-types or -t, the data types to be migrated, separated by commas, the optional value is ‘all’ or a combination of one or more [vertex, edge, vertex_label, edge_label, property_key, index_label], ‘all’ Represents all 6 types, namely vertices, edges and all schemas
- –log or -l, specify the log directory, the default is the current directory
- –retry, specify the number of failed retries, the default is 3
- –split-size or -s, specify the size of the vertex or edge block when backing up the source graph during the migration process, the default is 1048576
- -D, use the mode of -Dkey=value to specify dynamic parameters, which are used to specify HDFS configuration items when the data needs to be backed up to HDFS during the migration process, for example: -Dfs.default.name=hdfs://localhost: 9000
- –graph-mode or -m, the mode to set the target graph when restoring the source graph to the target graph, legal values include [RESTORING, MERGING]
- –keep-local-data, whether to keep the backup of the source map generated in the process of migrating the map, the default is false, that is, the backup of the source map is not kept after the default migration map ends
- schedule-backup, periodically back up the graph and keep a certain number of the latest backups (currently only supports local file systems)
- –directory or -d, required, specifies the directory of the backup data
- –backup-num, optional, specifies the number of latest backups to save, defaults to 3
- –interval, an optional item, specifies the backup cycle, the format is the same as the Linux crontab format
- dump, export all vertices and edges in the graph, using the
vertex vertex-edge1 vertex-edge2...JSON format by default. To customize the format, implement aFormattersubclass such asCustomFormatterunderhugegraph-tools/src/main/java/org/apache/hugegraph/formatter, then select it when running the command:bin/hugegraph dump -f CustomFormatter- –formatter or -f, specify the formatter to use, the default is JsonFormatter
- –directory or -d, the directory where schema or data is stored, the default is the current directory
- –log or -l, specify the log directory, the default is the current directory
- –retry, specify the number of failed retries, the default is 3
- –split-size or -s, specifies the size of splitting vertices or edges when backing up, the default is 1048576
- -D, use the mode of -Dkey=value to specify dynamic parameters, and specify HDFS configuration items when backing up data to HDFS, for example: -Dfs.default.name=hdfs://localhost:9000
3.7 Authentication data backup/restore type
- auth-backup, backup authentication data to a specified directory
- –types or -t, types of authentication data to back up, separated by commas, optional value is ‘all’ or a combination of one or more [user, group, target, belong, access], ‘all’ represents all 5 types
- –directory or -d, directory to store backup data, defaults to current directory
- –log or -l, specify the log directory, the default is the current directory
- –retry, specify the number of failed retries, the default is 3
- –thread-num or -T, the number of threads to use, default is Math.min(10, Math.max(4, CPUs / 2))
- -D, use the mode of -Dkey=value to specify dynamic parameters, and specify HDFS configuration items when backing up data to HDFS, for example: -Dfs.default.name=hdfs://localhost:9000
- auth-restore, restore authentication data from a specified directory
- –types or -t, types of authentication data to restore, separated by commas, optional value is ‘all’ or a combination of one or more [user, group, target, belong, access], ‘all’ represents all 5 types
- –directory or -d, directory where backup data is stored, defaults to current directory
- –log or -l, specify the log directory, the default is the current directory
- –retry, specify the number of failed retries, the default is 3
- –thread-num or -T, the number of threads to use, default is Math.min(10, Math.max(4, CPUs / 2))
- –strategy, conflict handling strategy, optional values are [stop, ignore], default is stop. stop means stop restoring when encountering conflicts, ignore means ignore conflicts and continue restoring
- –init-password, initial password to set when restoring users, required when restoring user data
- -D, use the mode of -Dkey=value to specify dynamic parameters, which are used to specify HDFS configuration items when restoring data from HDFS, for example: -Dfs.default.name=hdfs://localhost:9000
3.8 Install the deployment type
- deploy, one-click download, install and start HugeGraph-Server and HugeGraph-Studio
- -v, required, specifies the HugeGraph-Server and HugeGraph-Studio version to install
- -p, required, specifies the installed HugeGraph-Server and HugeGraph-Studio directories
- -u, optional, specifies the link to download the HugeGraph-Server and HugeGraph-Studio compressed packages
- clear, clean up HugeGraph-Server and HugeGraph-Studio directories and tarballs
- -p, required, specifies the directory of HugeGraph-Server and HugeGraph-Studio to be cleaned
- start-all, start HugeGraph-Server and HugeGraph-Studio with one click, and start monitoring, automatically pull up the service when the service dies
- -v, required, specifies the installed HugeGraph-Server and HugeGraph-Studio version to start
- -p, required, specifies the directory where HugeGraph-Server and HugeGraph-Studio are installed
- stop-all, close HugeGraph-Server and HugeGraph-Studio with one click
There is an optional parameter -u in the deploy command. When provided, the specified download address will be used instead of the default download address to download the tar package, and the address will be written into the
~/hugegraph-download-url-prefixfile; if no address is specified later When -u and~/hugegraph-download-url-prefixare not specified, the tar package will be downloaded from the address specified by~/hugegraph-download-url-prefix; if there is neither -u nor~/hugegraph-download-url-prefix, it will be downloaded from the default download address
3.9 Specific command parameters
The specific parameters of each subcommand are as follows:
3.10 Specific command example
1. gremlin statement
2. Show task status
3. Set and show graph mode
4. Cleanup Graph
5. Backup Graph
6. Periodic Backup Graph
7. Recovery Graph
8. Graph Migration
2.4 - HugeGraph-Spark-Connector Quick Start
1 HugeGraph-Spark-Connector Overview
HugeGraph-Spark-Connector uses the Spark DataFrame API to write bulk data to HugeGraph. The current implementation provides vertex and edge writers.
2 Environment Requirements
- Java 8+
- Maven 3.6+
- Spark 3.x
- Scala 2.12
3 Building
3.1 Build without executing tests
3.2 Build with default tests
4 Usage
Add the dependency to pom.xml, replacing ${revision} with the release version you use:
4.1 Schema Definition Example
If we have a graph, the schema is defined as follows:
4.2 Vertex Sink (Scala)
4.3 Edge Sink (Scala)
5 Configuration Parameters
5.1 Client Configs
Client Configs are used to configure hugegraph-client.
| Parameter | Default Value | Description |
|---|---|---|
host | localhost | Address of HugeGraphServer |
port | 8080 | Port of HugeGraphServer |
graph | hugegraph | Graph name |
protocol | http | Protocol for sending requests to the server, optional http or https |
username | null | Username of the current graph when HugeGraphServer enables permission authentication |
token | null | Token of the current graph when HugeGraphServer has enabled authorization authentication |
timeout | 60 | Timeout (seconds) for inserting results to return |
max-conn | CPUS * 4 | The maximum number of HTTP connections between HugeClient and HugeGraphServer |
max-conn-per-route | CPUS * 2 | The maximum number of HTTP connections for each route between HugeClient and HugeGraphServer |
trust-store-file | null | The client’s certificate file path when the request protocol is https |
trust-store-token | null | The client’s certificate password when the request protocol is https |
5.2 Graph Data Configs
Graph Data Configs describe how DataFrame columns map to vertices or edges.
| Parameter | Default Value | Description |
|---|---|---|
data-type | Graph data type, must be vertex or edge | |
label | Label to which the vertex/edge data to be imported belongs | |
id | Specify a column as the id column of the vertex. When the vertex id policy is CUSTOMIZE, it is required; when the id policy is PRIMARY_KEY, it must be empty | |
source-name | Select certain columns of the input source as the id column of source vertex. When the id policy of the source vertex is CUSTOMIZE, a certain column must be specified as the id column of the vertex; when the id policy of the source vertex is PRIMARY_KEY, one or more columns must be specified for splicing the id of the generated vertex, that is, no matter which id strategy is used, this item is required | |
target-name | Specify certain columns as the id columns of target vertex, similar to source-name | |
selected-fields | Select some columns to insert, other unselected ones are not inserted, cannot exist at the same time as ignored-fields | |
ignored-fields | Ignore some columns so that they do not participate in insertion, cannot exist at the same time as selected-fields | |
batch-size | 500 | The number of data items in each batch when importing data |
5.3 Common Configs
Common Configs contains some common configurations.
| Parameter | Default Value | Description |
|---|---|---|
delimiter | , | Separator of source-name, target-name, selected-fields or ignored-fields |
6 License
The same as HugeGraph, hugegraph-spark-connector is also licensed under Apache 2.0 License.
3 - HugeGraph-AI
hugegraph-ai provides Python clients for HugeGraph, graph machine learning tools, and LLM tools for knowledge graph construction and GraphRAG applications.
Apache License 2.0 · Ask DeepWiki
Modules
- hugegraph-llm: knowledge graph construction, GraphRAG, and natural-language graph queries.
- hugegraph-ml: reads graph data from HugeGraph and runs graph learning models.
- hugegraph-python-client: a Python SDK for managing schemas and graph data and running Gremlin queries.
- vermeer-python-client: a Python SDK for the Vermeer graph computing service.
The repository uses a uv workspace to manage the LLM and Python client packages. HugeGraph-ML is a path dependency rather than a workspace member.
Requirements
- HugeGraph-LLM: Python 3.10 or 3.11
- HugeGraph-ML and the Python clients: Python 3.10 or later
uv0.7 or later- HugeGraph Server 1.5 or later
Deploy with Docker Compose
The repository includes a Compose file that starts both HugeGraph Server and the RAG service:
Default addresses:
- HugeGraph Server:
http://localhost:8080 - RAG service and Web UI:
http://localhost:8001
Start the RAG Service from Source
uv sync creates .venv at the repository root. Do not create a separate environment under hugegraph-llm, because doing so can bypass the dependencies locked by the workspace.
Install ML Dependencies
Example scripts are under hugegraph-ml/src/hugegraph_ml/examples/.
Next Steps
3.1 - HugeGraph-LLM
HugeGraph-LLM connects graph databases with large language models for knowledge graph construction, GraphRAG, and natural-language graph queries. Its demo service hosts the Gradio UI and FastAPI endpoints in the same process and listens on port 8001 by default.
Requirements
AI-generated project documentation: Ask DeepWiki
- Python 3.10 or 3.11
uv0.7 or later- HugeGraph Server 1.5 or later
Deploy with Docker Compose
Prepare the environment files from the HugeGraph-AI repository root:
After startup, HugeGraph Server is available at http://localhost:8080, and the RAG service and Web UI are available at http://localhost:8001.
Start from Source
Install dependencies through the workspace at the repository root:
To use a custom address and port:
The service stores model, HugeGraph, and login settings in hugegraph-llm/.env. Prompts are stored separately in hugegraph-llm/src/hugegraph_llm/resources/demo/config_prompt.yaml. The configuration code creates missing files with default values.
Main Capabilities
Build RAG Indexes
The first Web UI tab splits text into a chunk vector index, extracts vertices and edges according to a schema, writes the graph to HugeGraph, and updates the vertex vector index. The schema can be inline JSON or the name of an existing graph. Through the REST API, a graph name requires a matching client_config.graph; inline JSON neither connects to HugeGraph nor accepts client_config.
GraphRAG
The query pipeline can combine direct LLM answers, chunk-vector retrieval, and graph retrieval. Graph retrieval first extracts keywords and matches vertices, then attempts Text2Gremlin. If generation or execution fails, it can fall back to predefined graph traversals. Request parameters control result limits, vector distance thresholds, template counts, and reranking.
Text2Gremlin
POST /text2gremlin generates Gremlin from natural language, the graph schema, and optional examples. A custom prompt must retain {query}, {schema}, {example}, and {vertices}.
Models and Vector Backends
Chat, information extraction, and Text2Gremlin can independently use an OpenAI-compatible endpoint, Ollama, or LiteLLM. The embedding model is configured separately. FAISS is the default vector index; Milvus or Qdrant are available after installing the optional dependencies:
See the configuration reference and REST API for details.
Development Checks
3.2 - HugeGraph-ML
HugeGraph-ML reads graph data from HugeGraph and converts it to DGL graphs for tasks such as node embedding, node classification, and graph classification. Model implementations are under hugegraph-ml/src/hugegraph_ml/models/.
Requirements
- Python 3.10 or later
- HugeGraph Server 1.0 or later; 1.5 or later is recommended
uv0.7 or later
Installation
HugeGraph-ML is a path dependency of the root project but is not a uv workspace member. Select the ml extra at the repository root instead of creating another lock file in the subdirectory.
Implemented Models
The current README lists these models:
| Models | Main purpose |
|---|---|
| AGNN, APPNP, ARMA, Cluster-GCN, DAGNN, DeeperGCN, GRAND, JKNet | Node classification |
| BGNN, CARE-GNN | Fraud detection |
| BGRL, DGI, GRACE | Representation learning |
| DiffPool | Graph classification |
| GATNE, P-GNN, SEAL | Link prediction or network embedding |
| C&S | Correction and smoothing of predictions |
The source also includes GIN for graph classification and MLPClassifier for downstream classification. The model count changes between versions; use src/hugegraph_ml/models/ as the authoritative list.
DGI Node Embedding Example
First import DGL’s Cora dataset into HugeGraph:
Read the graph and train DGI:
The complete script is hugegraph-ml/src/hugegraph_ml/examples/dgi_example.py.
GRAND Node Classification Example
The complete script is hugegraph-ml/src/hugegraph_ml/examples/grand_example.py.
Troubleshooting
- Connection failures: check the HugeGraph Server address, port, and credentials.
- Schema mismatches: the examples use
CORA_vertexandCORA_edge; pass the actual labels for your own data. - DGL or PyTorch import failures: rerun
uv sync --extra mlfrom the repository root and confirm that Python comes from the root.venv.
3.3 - HugeGraph-LLM Workflow
This page explains the processing flow in the HugeGraph-LLM Web UI. See HugeGraph-LLM for startup instructions.
1. Build RAG Indexes
The first tab splits documents into a chunk vector index. It also extracts vertices and edges according to a schema, writes them to HugeGraph, and maintains a vertex vector index.
flowchart TD
    A[Input document] --> B[Split text]
    B --> C[Generate chunk vectors]
    C --> D[Write vector index]
    B --> E[LLM extracts vertices and edges from schema]
    E --> F[Write to HugeGraph]
    F --> G[Update vertex vector index]
Common operations are Import into Vector, Extract Graph Data, Load into GraphDB, and Update Vid Embedding. The page can also inspect or clear chunk indexes, vertex indexes, and graph data. Clearing removes existing data, so first confirm that the current graph and indexes are not still used by other queries.
2. GraphRAG Queries
The second tab can answer directly with the LLM, use only chunk-vector retrieval, use only graph retrieval, or combine graph and vector retrieval.
flowchart TD
    Q[Question] --> V[Query chunk vector index]
    Q --> K[Extract keywords]
    K --> M[Match graph vertices]
    M --> T[Generate and execute Gremlin]
    T -->|Failure| B[Fallback to BFS graph traversal]
    T --> R[Prepare graph results]
    B --> R
    V --> S[Merge and rerank]
    R --> S
    S --> A[Generate answer]
Graph retrieval first matches HugeGraph vertices exactly by keyword and then uses vector similarity if no exact match exists. The matched vertices are passed to Text2Gremlin. If generation or execution fails, the pipeline can fall back to a predefined traversal.
Template Num controls how many examples Text2Gremlin uses. A value less than or equal to zero supplies no templates; a positive value retrieves that many similar examples.
3. Text2Gremlin
The third tab reads the graph schema, retrieves similar natural-language and Gremlin examples, fills the prompt with the question, schema, examples, and matched vertices, then generates Gremlin and optionally executes it.
A custom prompt must contain {query}, {schema}, {example}, and {vertices}. The REST API rejects a request if any placeholder is missing.
4. Graph and Administration Tools
Graph Tools runs graph operations directly. Admin Tools provides functions such as log access. When login is enabled, the UI and APIs require USER_TOKEN; the log endpoint additionally requires a separately configured, secure ADMIN_TOKEN.
5. Prompt Language
Set LANGUAGE=EN or LANGUAGE=CN in hugegraph-llm/.env, then restart the service. This selects the language of built-in prompts; it does not translate input documents and is not a field in the /rag request body.
6. REST Calls
The Web UI and REST API use the same pipeline. For application integration, use /rag, /rag/graph, /graph/extract, and /text2gremlin; see the REST API for request formats.
3.4 - Configuration Reference
HugeGraph-LLM reads runtime settings from hugegraph-llm/.env. Prompts are stored separately in hugegraph-llm/src/hugegraph_llm/resources/demo/config_prompt.yaml and are not written to .env.
Create or update the files from configuration-class defaults with:
.env contains keys and passwords. Do not commit it to version control.
Basic Options
| Setting | Default | Description |
|---|---|---|
LANGUAGE | EN | Prompt language: EN or CN |
CHAT_LLM_TYPE | openai | Answer model: openai, litellm, or ollama/local |
EXTRACT_LLM_TYPE | openai | Information extraction model; same choices as above |
TEXT2GQL_LLM_TYPE | openai | Text2Gremlin model; same choices as above |
EMBEDDING_TYPE | openai | Embedding model; same choices as above, or empty |
RERANKER_TYPE | empty | cohere or siliconflow |
KEYWORD_EXTRACT_TYPE | llm | llm, textrank, or hybrid |
WINDOW_SIZE | 3 | TextRank window size, from 1 to 10 |
HYBRID_LLM_WEIGHTS | 0.5 | Weight of LLM results in hybrid mode, from 0 to 1 |
OpenAI-Compatible APIs
Chat, extraction, and Text2Gremlin can use different endpoints, keys, and models.
| Purpose | API base | Key | Model | Default maximum tokens |
|---|---|---|---|---|
| Answer | OPENAI_CHAT_API_BASE | OPENAI_CHAT_API_KEY | OPENAI_CHAT_LANGUAGE_MODEL | OPENAI_CHAT_TOKENS=8192 |
| Extraction | OPENAI_EXTRACT_API_BASE | OPENAI_EXTRACT_API_KEY | OPENAI_EXTRACT_LANGUAGE_MODEL | OPENAI_EXTRACT_TOKENS=256 |
| Text2Gremlin | OPENAI_TEXT2GQL_API_BASE | OPENAI_TEXT2GQL_API_KEY | OPENAI_TEXT2GQL_LANGUAGE_MODEL | OPENAI_TEXT2GQL_TOKENS=4096 |
| Embedding | OPENAI_EMBEDDING_API_BASE | OPENAI_EMBEDDING_API_KEY | OPENAI_EMBEDDING_MODEL | Not applicable |
The default API base is https://api.openai.com/v1. The default language model for all three tasks is gpt-4.1-mini, and the default embedding model is text-embedding-3-small.
OPENAI_BASE_URL and OPENAI_API_KEY provide general fallback values. Embeddings also support OPENAI_EMBEDDING_BASE_URL and OPENAI_EMBEDDING_API_KEY as fallback values.
LiteLLM
| Purpose | API base | Key | Model | Default maximum tokens |
|---|---|---|---|---|
| Answer | LITELLM_CHAT_API_BASE | LITELLM_CHAT_API_KEY | LITELLM_CHAT_LANGUAGE_MODEL | LITELLM_CHAT_TOKENS=8192 |
| Extraction | LITELLM_EXTRACT_API_BASE | LITELLM_EXTRACT_API_KEY | LITELLM_EXTRACT_LANGUAGE_MODEL | LITELLM_EXTRACT_TOKENS=256 |
| Text2Gremlin | LITELLM_TEXT2GQL_API_BASE | LITELLM_TEXT2GQL_API_KEY | LITELLM_TEXT2GQL_LANGUAGE_MODEL | LITELLM_TEXT2GQL_TOKENS=4096 |
| Embedding | LITELLM_EMBEDDING_API_BASE | LITELLM_EMBEDDING_API_KEY | LITELLM_EMBEDDING_MODEL | Not applicable |
The default language model is openai/gpt-4.1-mini, and the default embedding model is openai/text-embedding-3-small. Model names generally use the provider/model form; supported values depend on the LiteLLM service.
Ollama
| Purpose | Host | Port | Model |
|---|---|---|---|
| Answer | OLLAMA_CHAT_HOST | OLLAMA_CHAT_PORT | OLLAMA_CHAT_LANGUAGE_MODEL |
| Extraction | OLLAMA_EXTRACT_HOST | OLLAMA_EXTRACT_PORT | OLLAMA_EXTRACT_LANGUAGE_MODEL |
| Text2Gremlin | OLLAMA_TEXT2GQL_HOST | OLLAMA_TEXT2GQL_PORT | OLLAMA_TEXT2GQL_LANGUAGE_MODEL |
| Embedding | OLLAMA_EMBEDDING_HOST | OLLAMA_EMBEDDING_PORT | OLLAMA_EMBEDDING_MODEL |
The default host is 127.0.0.1 and the default port is 11434. Model names have no defaults; pull the required models in Ollama before use.
Reranking
| Setting | Default | Description |
|---|---|---|
COHERE_BASE_URL | https://api.cohere.com/v1/rerank | Cohere rerank endpoint; CO_API_URL is a fallback |
RERANKER_API_KEY | empty | Cohere or SiliconFlow key |
RERANKER_MODEL | empty | Model name supported by the service |
HugeGraph Connection and Retrieval Limits
| Setting | Default | Description |
|---|---|---|
GRAPH_URL | 127.0.0.1:8080 | HugeGraph address; it is not split into IP and port |
GRAPH_NAME | hugegraph | Graph name |
GRAPH_USER | admin | User name |
GRAPH_PWD | xxx | Password |
GRAPH_SPACE | empty | GraphSpace name |
LIMIT_PROPERTY | False | Whether to limit returned properties; read as a string by the configuration class |
MAX_GRAPH_PATH | 10 | Maximum graph path length |
MAX_GRAPH_ITEMS | 30 | Maximum number of graph retrieval items |
EDGE_LIMIT_PRE_LABEL | 8 | Result limit for each edge label |
VECTOR_DIS_THRESHOLD | 0.9 | Results beyond this vector-distance threshold are ignored |
TOPK_PER_KEYWORD | 1 | Candidates per keyword |
TOPK_RETURN_RESULTS | 20 | Results returned after reranking |
External Vector Databases
The default implementation can use local FAISS. After enabling optional dependencies, the following settings are also available:
| Setting | Default |
|---|---|
QDRANT_HOST | empty |
QDRANT_PORT | 6333 |
QDRANT_API_KEY | empty |
MILVUS_HOST | empty |
MILVUS_PORT | 19530 |
MILVUS_USER | empty |
MILVUS_PASSWORD | empty |
Login and Log API
| Setting | Default | Description |
|---|---|---|
ENABLE_LOGIN | False | Whether to require a Bearer token; read as a string by the configuration class |
USER_TOKEN | 4321 | Token for the Web UI and regular APIs |
ADMIN_TOKEN | xxxx | Administrator token used by /logs |
/logs returns 403 when ADMIN_TOKEN is empty or still set to xxxx. Replace both the user and administrator tokens in production.
Minimal OpenAI Configuration
Configuration Loading
Configuration classes supply code defaults and then apply overrides from .env and the process environment. The Web UI and configuration APIs can update current settings at runtime and write supported fields back to .env. Restart the service after editing .env manually; prompt YAML can be refreshed by the page-loading logic.
Configuration definitions are in:
hugegraph-llm/src/hugegraph_llm/config/llm_config.pyhugegraph-llm/src/hugegraph_llm/config/hugegraph_config.pyhugegraph-llm/src/hugegraph_llm/config/admin_config.pyhugegraph-llm/src/hugegraph_llm/config/prompt_config.py
3.5 - HugeGraph-LLM REST API
The HugeGraph-LLM demo process serves both the Web UI and REST API. The default address is http://localhost:8001:
Authentication
Enable login in .env:
Requests then require a Bearer token:
RAG
POST /rag
Returns one or more answer types according to the switches. When none is explicitly selected, only graph_only is enabled.
The response contains only enabled answer fields:
Other optional parameters include graph_ratio, rerank_method (bleu or reranker), near_neighbor_first, custom_priority_info, and three custom prompt fields.
POST /rag/graph
Runs graph retrieval without generating a final natural-language answer:
graph_recall in the response can contain keywords, match_vids, gremlin, graph_result, and vertex_degree_list. Set get_vertex_only=true to return immediately after vertex matching.
Graph Extraction
POST /graph/extract
An inline schema does not connect to HugeGraph:
texts can be a string or an array of strings. language accepts zh or en; split_type accepts document, paragraph, or sentence.
When schema is an existing graph name, also pass client_config, and make client_config.graph match that name:
A successful response always contains status, result.vertices, result.edges, warnings, and meta.
Text2Gremlin
POST /text2gremlin
output_types can contain:
match_resulttemplate_gremlinraw_gremlintemplate_execution_resultraw_execution_result
If omitted, only template_gremlin is returned by default. An empty array lets the implementation return all outputs. A custom gremlin_prompt must contain {query}, {schema}, {example}, and {vertices}.
Runtime Configuration
POST /config/graph
POST /config/llm and POST /config/embedding
Both endpoints use the same request model. OpenAI or LiteLLM example:
Ollama requests still require the common fields; api_key and api_base can be empty strings:
POST /config/rerank
reranker_type accepts cohere or siliconflow. Cohere also accepts cohere_base_url.
These endpoints change the process’s active configuration and may write values back to .env. client_config in /rag, /rag/graph, and /text2gremlin overrides the HugeGraph connection for one request. The current implementation still changes process-global settings temporarily, so do not issue long-running requests with different connections concurrently.
Logs
POST /logs
This endpoint requires ADMIN_TOKEN in .env to be changed to a secure value. Example request body:
log_file must be a file name under logs/ and cannot contain path separators.
4 - HugeGraph Computing (OLAP)
The HugeGraph-Computer repository contains two OLAP systems: Computer, a distributed BSP framework implemented in Java, and Vermeer, an in-memory graph computing platform implemented in Go.
DeepWiki provides real-time updated project documentation with more comprehensive and accurate content, suitable for quickly understanding the latest project information.
4.1 - HugeGraph-Vermeer Quick Start
1. Overview of Vermeer
1.1 Architecture
Vermeer is a high-performance, memory-first graph computing framework written in Go (start once, execute any task), supporting ultra-fast computation of 15+ OLAP graph algorithms (most tasks complete in seconds to minutes), with master and worker roles. Currently, there is only one master (HA can be added), and there can be multiple workers.
The master is responsible for communication, forwarding, and aggregation, with minimal computation and resource usage. Workers are computation nodes used to store graph data and run computation tasks, consuming a large amount of memory and CPU. The grpc and rest modules handle internal communication and external calls, respectively.
The framework’s runtime configuration can be passed via command-line parameters or specified in configuration files located in the config/ directory. The --env parameter can specify which configuration file to use, e.g., --env=master specifies using master.ini. Note that the master needs to specify the listening port, and the worker needs to specify the listening port and the master’s ip:port.
1.2 Running Method
- Option 1: Docker Compose (Recommended)
Please ensure that docker-compose.yaml exists in your project root directory. If it doesn’t, here is an example:
Modify docker-compose.yaml
- Volume: For example, change both instances of
~/:/go/bin/configto/home/user/config:/go/bin/config(or your own configuration directory). - Subnet: Modify the subnet IP based on your actual situation. Note that the ports each container needs to access are specified in the config file. Please refer to the contents of the project’s
configfolder for details.
Build the Image and Start in the Project Directory (or docker build first, then docker-compose up)
View Logs / Stop / Remove
- Option 2: Start individually via
docker run(Manually create network and assign static IP)
Ensure the CONFIG_DIR has proper read/execute permissions for the Docker process.
Build the image:
Create a custom bridge network (one-time operation):
Run master (adjust CONFIG_DIR to your absolute configuration path, and you can adjust the IP as needed based on your actual situation).
Run worker:
View logs / Stop / Remove:
- Option 3: Build from Source
Build. You can refer Vermeer Readme.
Enter the directory and input ./vermeer --env=master or ./vermeer --env=worker01.
2. Task Creation REST API
2.1 Introduction
This REST API provides all task creation functions, including reading graph data and various computation functions, offering both asynchronous and synchronous return interfaces. The returned content includes information about the created tasks. The overall process of using Vermeer is to first create a task to read the graph data, and after the graph is read, create a computation task to execute the computation. The graph will not be automatically deleted; multiple computation tasks can be run on one graph without repeated reading. If deletion is needed, the delete graph interface can be used. Task statuses can be divided into graph reading task status and computation task status. Generally, the client only needs to know four statuses: created, in progress, completed, and error. The graph status is the basis for determining whether the graph is available. If the graph is being read or the graph status is erroneous, the graph cannot be used to create computation tasks. The delete graph interface is only available when the graph is in the loaded or error status and has no computation tasks.
Available URLs are as follows:
- Asynchronous return interface: POST http://master_ip:port/tasks/create returns only whether the task creation is successful, and the task status needs to be actively queried to determine completion.
- Synchronous return interface: POST http://master_ip:port/tasks/create/sync returns after the task is completed.
2.2 Loading Graph Data
Refer to the Vermeer parameter list document for specific parameters.
Vermeer provides three ways to load data:
- Load from Local Files
You can obtain the dataset in advance, such as the Twitter-2010 dataset. Acquisition method: https://snap.stanford.edu/data/twitter-2010.html The first Twitter-2010.text.gz is sufficient.
Request Example:
- Load from HugeGraph
Request Example:
⚠️ Security Warning: Never store real passwords in configuration files or code. Use environment variables or a secure credential management system instead.
- Load from HDFS
Request Example:
2.3 Output Computation Results
All Vermeer computation tasks support multiple result output methods, which can be customized: local, hdfs, afs, or hugegraph. Add the corresponding parameters under the params parameter when sending the request to take effect. When output.need_statistics is set to 1, it supports outputting statistical information of the computation results, which will be written in the interface task information. The statistical mode operators currently support “count” and “modularity,” but only for community detection algorithms.
Refer to the Vermeer parameter list document for specific parameters.
Request example:
3. Supported Algorithms
3.1 PageRank
The PageRank algorithm, also known as the web ranking algorithm, is a technique used by search engines to calculate the relevance and importance of web pages (nodes) based on their mutual hyperlinks.
- If a web page is linked to by many other web pages, it indicates that the web page is relatively important, and its PageRank value will be relatively high.
- If a web page with a high PageRank value links to other web pages, the PageRank value of the linked web pages will also increase accordingly.
The PageRank algorithm is suitable for scenarios such as web page ranking and identifying key figures in social networks.
Request example:
3.2 WCC (Weakly Connected Components)
The weakly connected components algorithm calculates all connected subgraphs in an undirected graph and outputs the weakly connected subgraph ID to which each vertex belongs, indicating the connectivity between points and distinguishing different connected communities.
Request example:
3.3 LPA (Label Propagation Algorithm)
The label propagation algorithm is a graph clustering algorithm commonly used in social networks to discover potential communities.
Request example:
3.4 Degree Centrality
The degree centrality algorithm calculates the degree centrality value of each node in the graph, supporting both undirected and directed graphs. Degree centrality is an important indicator of node importance; the more edges a node has with other nodes, the higher its degree centrality value, and the more important the node is in the graph. In an undirected graph, degree centrality is calculated based on edge information to count the number of times a node appears, resulting in the degree centrality value of the node. In a directed graph, it is based on the direction of the edges, filtering based on input or output-edge information to count the number of times a node appears, resulting in the in-degree or out-degree value of the node. It indicates the importance of each point, with more important points having higher degrees.
Request example:
3.5 Closeness Centrality
Closeness centrality is used to calculate the inverse of the shortest distance from a node to all other reachable nodes, accumulating and normalizing the value. Closeness centrality can be used to measure the time it takes for information to be transmitted from the node to other nodes. The larger the closeness centrality of a node, the closer its position in the graph is to the center, suitable for scenarios such as identifying key nodes in social networks.
Request example:
3.6 Betweenness Centrality
The betweenness centrality algorithm determines the value of a node as a “bridge” node; the larger the value, the more likely it is to be a necessary path between two points in the graph. Typical examples include mutual followers in social networks. It is suitable for measuring the degree of aggregation around a node in a community.
Request example:
3.7 Triangle Count
The triangle count algorithm calculates the number of triangles passing through each vertex, suitable for calculating the relationships between users and whether the associations form triangles. The more triangles, the higher the degree of association between nodes in the graph, and the tighter the organizational relationship. In social networks, triangles indicate cohesive communities, and identifying triangles helps understand clustering and interconnections among individuals or groups in the network. In financial or transaction networks, the presence of triangles may indicate suspicious or fraudulent activities, and triangle counting can help identify transaction patterns that may require further investigation.
The output result is the Triangle Count corresponding to each vertex, i.e., the number of triangles the vertex is part of.
Note: This algorithm is for undirected graphs and ignores edge directions.
Request example:
3.8 K-Core
The K-Core algorithm marks all vertices with a degree of K, suitable for graph pruning and finding the core part of the graph.
Request example:
3.9 SSSP (Single Source Shortest Path)
The single source the shortest path algorithm calculates the shortest distance from one point to all other points.
Request example:
3.10 KOUT
Starting from a point, get the k-layer nodes of this point.
Request example:
3.11 Louvain
The Louvain algorithm is a community detection algorithm based on modularity. The basic idea is that nodes in the network try to traverse all neighbor community labels and choose the community label that maximizes the modularity increment. After maximizing modularity, each community is regarded as a new node, and the process is repeated until the modularity no longer increases.
The distributed Louvain algorithm implemented on Vermeer is affected by factors such as node order and parallel computation. Due to the random traversal order of the Louvain algorithm, community compression also has a certain randomness, leading to different results in multiple executions. However, the overall trend will not change significantly.
Request example:
3.12 Jaccard Similarity Coefficient
The Jaccard index, also known as the Jaccard similarity coefficient, is used to compare the similarity and diversity between finite sample sets. The larger the Jaccard coefficient value, the higher the similarity of the samples. It is used to calculate the Jaccard similarity coefficient between a given source point and all other points in the graph.
Request example:
3.13 Personalized PageRank
The goal of personalized PageRank is to calculate the relevance of all nodes relative to user u. Starting from the node corresponding to user u, at each node, there is a probability of 1-d to stop walking and start again from u, or a probability of d to continue walking, randomly selecting a node from the nodes pointed to by the current node to walk down. It is used to calculate the personalized PageRank score starting from a given starting point, suitable for scenarios such as social recommendations.
Since the calculation requires using out-degree, load.use_out_degree needs to be set to 1 when reading the graph.
Request example:
3.14 Global Kout
Calculate the k-degree neighbors of all nodes in the graph (excluding themselves and 1~k-1 degree neighbors). Due to the severe memory expansion of the global kout algorithm, k is currently limited to 1 and 2. Additionally, the global kout algorithm supports filtering functions (parameters such as “compute.filter”:“risk_level==1”), and the filtering condition is judged when calculating the k-degree. The final result set includes those that meet the filtering condition. The algorithm’s final output is the number of neighbors that meet the condition.
Request example:
3.15 Clustering Coefficient
The clustering coefficient represents the coefficient of the clustering degree of nodes in a graph. In real networks, especially in specific networks, nodes tend to establish a tightly organized relationship due to relatively high-density connection points. The clustering coefficient algorithm (Cluster Coefficient) is used to calculate the clustering degree of nodes in the graph. This algorithm is for local clustering coefficients. The local clustering coefficient can measure the clustering degree around each node in the graph.
Request example:
3.16 SCC (Strongly Connected Components)
In the mathematical theory of directed graphs, if every vertex of a graph can be reached from any other point in the graph, the graph is said to be strongly connected. The parts of any directed graph that can achieve strong connectivity are called strongly connected components. It indicates the connectivity between points and distinguishes different connected communities.
Request example:
🚧, further updates and improvements will be made at any time. Suggestions and feedback are welcome.
4.2 - HugeGraph-Computer Quick Start
1 HugeGraph-Computer Overview
The HugeGraph-Computer is a distributed graph processing system for HugeGraph (OLAP). It is an implementation of Pregel. It runs on a Kubernetes(K8s) framework.(It focuses on supporting graph data volumes of hundreds of billions to trillions, using disk for sorting and acceleration, which is one of the biggest differences from Vermeer)
Features
- Support distributed MPP graph computing, and integrates with HugeGraph as graph input/output storage.
- Based on the BSP (Bulk Synchronous Parallel) model, an algorithm performs computing through multiple parallel iterations; every iteration is a superstep.
- Auto memory management. The framework will never be OOM(Out of Memory) since it will split some data to disk if it doesn’t have enough memory to hold all the data.
- The part of edges or the messages of super node can be in memory, so you will never lose it.
- You can load the data from HDFS or HugeGraph, or any other system.
- You can output the results to HDFS or HugeGraph, or any other system.
- Easy to develop a new algorithm. You just need to focus on vertex-only processing just like as in a single server, without worrying about message transfer and memory/storage management.
2 Dependency for Building/Running
2.1 Install Java 11 (JDK 11)
Must use ≥ Java 11 to run Computer, and configure by yourself.
Be sure to execute the java -version command to check the jdk version before reading
3 Get Started
3.1 Run PageRank algorithm locally
To run the algorithm with HugeGraph-Computer, you need to install Java 11 or later versions.
You also need to deploy HugeGraph-Server and Etcd.
There are two ways to get HugeGraph-Computer:
- Download the compiled tarball
- Clone source code then compile and package
3.1.1 Download the compiled archive
Download the latest version of the HugeGraph-Computer release package:
3.1.2 Clone source code to compile and package
Clone the latest version of HugeGraph-Computer source package:
Compile and generate tar package:
3.1.3 Start master node
You can use
-cparameter specify the configuration file, more computer config please see:Computer Config Options
3.1.4 Start worker node
3.1.5 Query algorithm results
3.1.5.1 Enable OLAP index query for server
If the OLAP index is not enabled, it needs to be enabled. More reference: modify-graphs-read-mode
3.1.5.2 Query page_rank property value:
3.2 Run PageRank algorithm in Kubernetes
To run an algorithm with HugeGraph-Computer, you need to deploy HugeGraph-Server first
3.2.1 Install HugeGraph-Computer CRD
3.2.2 Show CRD
3.2.3 Install hugegraph-computer-operator&etcd-server
3.2.4 Wait for hugegraph-computer-operator&etcd-server deployment to complete
3.2.5 Submit a job
More computer crd please see: Computer CRD
More computer config please see: Computer Config Options
3.2.6 Show job
3.2.7 Show log of nodes
3.2.8 Show success event of a job
NOTE: it will only be saved for one hour
3.2.9 Query algorithm results
If the output to Hugegraph-Server is consistent with Locally, if output to HDFS, please check the result file in the directory of /hugegraph-computer/results/{jobId} directory.
4. Built-In algorithms document
4.1 Supported algorithms list:
Centrality Algorithm:
- PageRank
- BetweennessCentrality
- ClosenessCentrality
- DegreeCentrality
Community Algorithm:
- ClusteringCoefficient
- Kcore
- Lpa
- TriangleCount
- Wcc
Path Algorithm:
- RingsDetection
- RingsDetectionWithFilter
More algorithms please see: Built-In algorithms
4.2 Algorithm describe
TODO
5 Algorithm development guide
TODO
6 Note
- If some classes under computer-k8s cannot be found, you need to execute
mvn compilein advance to generate corresponding classes.
4.3 - HugeGraph-Computer Configuration Reference
Computer Config Options
The defaults in the tables come from ComputerOptions.java in the computer-api module. When the distribution’s conf/computer.properties explicitly overrides an option, the table shows “code default (packaged: actual value)”. At runtime, values in the configuration file take precedence.
1. Basic Configuration
Core job settings for HugeGraph-Computer.
| config option | default value | description |
|---|---|---|
| hugegraph.url | http://127.0.0.1:8080 | The HugeGraph server URL to load data and write results back. |
| hugegraph.name | hugegraph | The graph name to load data and write results back. |
| hugegraph.username | "" (empty) | The username for HugeGraph authentication (leave empty if authentication is disabled). |
| hugegraph.password | "" (empty) | The password for HugeGraph authentication (leave empty if authentication is disabled). |
| job.id | local_0001 (packaged: local_001) | The job identifier on YARN cluster or K8s cluster. |
| job.namespace | "" (empty) | The job namespace used to separate different data sources. This option is managed by the runtime system. |
| job.workers_count | 1 | The number of workers for one graph algorithm job. In K8s, this option is set by the Operator. |
| job.partitions_count | 1 | The number of partitions for computing one graph algorithm job. |
| job.partitions_thread_nums | 4 | The number of threads for partition parallel compute. |
2. Algorithm Configuration
Algorithm-specific configuration for computation logic.
| config option | default value | description |
|---|---|---|
| algorithm.params_class | ComputerOptions.Null placeholder class | Required. The class used to pass algorithm parameters before the algorithm runs. |
| algorithm.result_class | ComputerOptions.Null placeholder class | The vertex value class used to store computation results. |
| algorithm.message_class | ComputerOptions.Null placeholder class | The message class passed while computing a vertex. |
3. Input Configuration
Configuration for loading input data from HugeGraph or other sources.
3.1 Input Source
| config option | default value | description |
|---|---|---|
| input.source_type | hugegraph-server | The source type to load input data, allowed values: [‘hugegraph-server’, ‘hugegraph-loader’]. The ‘hugegraph-loader’ means use hugegraph-loader to load data from HDFS or file. If using ‘hugegraph-loader’, please configure ‘input.loader_struct_path’ and ‘input.loader_schema_path’. |
| input.loader_struct_path | "" (empty) | The structure path for Loader input. It takes effect only when input.source_type=hugegraph-loader. |
| input.loader_schema_path | "" (empty) | The schema path for Loader input. It takes effect only when input.source_type=hugegraph-loader. |
3.2 Input Splits
| config option | default value | description |
|---|---|---|
| input.split_size | 1048576 (1 MB) | The input split size in bytes. |
| input.split_max_splits | 10000000 | The maximum number of input splits. |
| input.split_page_size | 500 | The page size for streamed load input split data. |
| input.split_fetch_timeout | 300 | The timeout in seconds to fetch input splits. |
3.3 Input Processing
| config option | default value | description |
|---|---|---|
| input.filter_class | org.apache.hugegraph.computer.core.input.filter.DefaultInputFilter | The class to create input-filter object. Input-filter is used to filter vertex edges according to user needs. |
| input.edge_direction | OUT | The direction of edges to load, allowed values: [OUT, IN, BOTH]. When the value is BOTH, edges in both OUT and IN directions will be loaded. |
| input.edge_freq | MULTIPLE | The frequency of edges that can exist between a pair of vertices, allowed values: [SINGLE, SINGLE_PER_LABEL, MULTIPLE]. SINGLE means only one edge can exist between a pair of vertices (identified by sourceId + targetId); SINGLE_PER_LABEL means each edge label can have one edge between a pair of vertices (identified by sourceId + edgeLabel + targetId); MULTIPLE means many edges can exist between a pair of vertices (identified by sourceId + edgeLabel + sortValues + targetId). |
| input.max_edges_in_one_vertex | 200 | The maximum number of adjacent edges allowed to be attached to a vertex. The adjacent edges will be stored and transferred together as a batch unit. |
3.4 Input Performance
| config option | default value | description |
|---|---|---|
| input.send_thread_nums | 4 | The number of threads for parallel sending of vertices or edges. |
4. Snapshot & Storage Configuration
HugeGraph-Computer supports snapshot functionality to save vertex/edge partitions to local storage or MinIO object storage, enabling checkpoint recovery or accelerating repeated computations.
4.1 Basic Snapshot Configuration
| config option | default value | description |
|---|---|---|
| snapshot.write | false | Whether to write snapshots of input vertex/edge partitions. |
| snapshot.load | false | Whether to load from snapshots of vertex/edge partitions. |
| snapshot.name | "" (empty) | User-defined snapshot name to distinguish different snapshots. |
4.2 MinIO Integration (Optional)
MinIO can be used as a distributed object storage backend for snapshots in K8s deployments.
| config option | default value | description |
|---|---|---|
| snapshot.minio_endpoint | "" (empty) | MinIO service endpoint (e.g., http://minio:9000). Required when using MinIO. |
| snapshot.minio_access_key | minioadmin | MinIO access key for authentication. |
| snapshot.minio_secret_key | minioadmin | MinIO secret key for authentication. |
| snapshot.minio_bucket_name | "" (empty) | MinIO bucket name for storing snapshot data. |
Usage Scenarios:
- Checkpoint Recovery: Resume from snapshots after job failures, avoiding data reloading
- Repeated Computations: Load data from snapshots when running the same algorithm multiple times
- A/B Testing: Save multiple snapshot versions of the same dataset to test different algorithm parameters
Example: Local Snapshot (in computer.properties):
Example: MinIO Snapshot (in K8s CRD computerConf):
5. Worker & Master Configuration
Configuration for worker and master computation logic.
5.1 Master Configuration
| config option | default value | description |
|---|---|---|
| master.computation_class | org.apache.hugegraph.computer.core.master.DefaultMasterComputation | Master-computation is computation that can determine whether to continue to the next superstep. It runs at the end of each superstep on the master. |
5.2 Worker Computation
| config option | default value | description |
|---|---|---|
| worker.computation_class | org.apache.hugegraph.computer.core.config.Null | The class to create worker-computation object. Worker-computation is used to compute each vertex in each superstep. |
| worker.combiner_class | org.apache.hugegraph.computer.core.config.Null | Combiner can combine messages into one value for a vertex. For example, PageRank algorithm can combine messages of a vertex to a sum value. |
| worker.partitioner | org.apache.hugegraph.computer.core.graph.partition.HashPartitioner | The partitioner that decides which partition a vertex should be in, and which worker a partition should be in. |
5.3 Worker Combiners
| config option | default value | description |
|---|---|---|
| worker.vertex_properties_combiner_class | org.apache.hugegraph.computer.core.combiner.OverwritePropertiesCombiner | The combiner can combine several properties of the same vertex into one properties at input step. |
| worker.edge_properties_combiner_class | org.apache.hugegraph.computer.core.combiner.OverwritePropertiesCombiner | The combiner can combine several properties of the same edge into one properties at input step. |
5.4 Worker Buffers
| config option | default value | description |
|---|---|---|
| worker.received_buffers_bytes_limit | 104857600 (100 MB) | The limit bytes of buffers of received data. The total size of all buffers can’t exceed this limit. If received buffers reach this limit, they will be merged into a file (spill to disk). |
| worker.write_buffer_capacity | 52428800 (50 MB) | The initial size of write buffer that used to store vertex or message. |
| worker.write_buffer_threshold | 52428800 (50 MB) | The threshold of write buffer. Exceeding it will trigger sorting. The write buffer is used to store vertex or message. |
5.5 Worker Data & Timeouts
| config option | default value | description |
|---|---|---|
| worker.data_dirs | [jobs] | The directories separated by ‘,’ that received vertices and messages can persist into. |
| worker.wait_sort_timeout | 600000 (10 minutes) | The max timeout (in ms) for message-handler to wait for sort-thread to sort one batch of buffers. |
| worker.wait_finish_messages_timeout | 86400000 (24 hours) | The max timeout (in ms) for message-handler to wait for finish-message of all workers. |
6. I/O & Output Configuration
Configuration for output computation results.
6.1 Output Class & Result
| config option | default value | description |
|---|---|---|
| output.output_class | org.apache.hugegraph.computer.core.output.LogOutput | The class to output the computation result of each vertex. Called after iteration computation. |
| output.result_name | value | The value is assigned dynamically by #name() of instance created by WORKER_COMPUTATION_CLASS. |
| output.result_write_type | OLAP_COMMON | The result write-type to output to HugeGraph, allowed values: [OLAP_COMMON, OLAP_SECONDARY, OLAP_RANGE]. |
6.2 Output Behavior
| config option | default value | description |
|---|---|---|
| output.with_adjacent_edges | false | Whether to output the adjacent edges of the vertex. |
| output.with_vertex_properties | false | Whether to output the properties of the vertex. |
| output.with_edge_properties | false | Whether to output the properties of the edge. |
6.3 Batch Output
| config option | default value | description |
|---|---|---|
| output.batch_size | 500 | The batch size of output. |
| output.batch_threads | 1 | The number of threads used for batch output. |
| output.single_threads | 1 | The number of threads used for single output. |
6.4 HDFS Output
| config option | default value | description |
|---|---|---|
| output.hdfs_url | hdfs://127.0.0.1:9000 | The HDFS URL for output. |
| output.hdfs_user | hadoop | The HDFS user for output. |
| output.hdfs_path_prefix | /hugegraph-computer/results | The directory of HDFS output results. |
| output.hdfs_delimiter | , (comma) | The delimiter of HDFS output. |
| output.hdfs_merge_partitions | true | Whether to merge output files of multiple partitions. |
| output.hdfs_replication | 3 | The replication number of HDFS. |
| output.hdfs_core_site_path | "" (empty) | The HDFS core site path. |
| output.hdfs_site_path | "" (empty) | The HDFS site path. |
| output.hdfs_kerberos_enable | false | Whether Kerberos authentication is enabled for HDFS. |
| output.hdfs_kerberos_principal | "" (empty) | The HDFS principal for Kerberos authentication. |
| output.hdfs_kerberos_keytab | "" (empty) | The HDFS keytab file for Kerberos authentication. |
| output.hdfs_krb5_conf | /etc/krb5.conf | Kerberos configuration file path. |
6.5 Retry & Timeout
| config option | default value | description |
|---|---|---|
| output.retry_times | 3 | The retry times when output fails. |
| output.retry_interval | 10 | The retry interval (in seconds) when output fails. |
| output.thread_pool_shutdown_timeout | 60 | The timeout (in seconds) of output thread pool shutdown. |
7. Network & Transport Configuration
Configuration for network communication between workers and master.
7.1 Server Configuration
| config option | default value | description |
|---|---|---|
| transport.server_host | 127.0.0.1 | The hostname or IP that listens for transport data. This option is managed by the runtime system. |
| transport.server_port | 0 | The port that listens for transport data; 0 assigns a random port. This option is managed by the runtime system. |
| transport.server_threads | 4 | The number of transport threads for server. |
7.2 Client Configuration
| config option | default value | description |
|---|---|---|
| transport.client_threads | 4 | The number of transport threads for client. |
| transport.client_connect_timeout | 3000 | The timeout (in ms) of client connect to server. |
7.3 Protocol Configuration
| config option | default value | description |
|---|---|---|
| transport.provider_class | org.apache.hugegraph.computer.core.network.netty.NettyTransportProvider | The transport provider, currently only supports Netty. |
| transport.io_mode | AUTO | The network IO mode, allowed values: [NIO, EPOLL, AUTO]. AUTO means selecting the appropriate mode automatically. |
| transport.tcp_keep_alive | true | Whether to enable TCP keep-alive. |
| transport.transport_epoll_lt | false | Whether to enable EPOLL level-trigger (only effective when io_mode=EPOLL). |
7.4 Buffer Configuration
| config option | default value | description |
|---|---|---|
| transport.send_buffer_size | 0 | The size of socket send-buffer in bytes. 0 means using system default value. |
| transport.receive_buffer_size | 0 | The size of socket receive-buffer in bytes. 0 means using system default value. |
| transport.write_buffer_high_mark | 67108864 (64 MB) | The high water mark for write buffer in bytes. It will trigger sending unavailable if the number of queued bytes > write_buffer_high_mark. |
| transport.write_buffer_low_mark | 33554432 (32 MB) | The low water mark for write buffer in bytes. It will trigger sending available if the number of queued bytes < write_buffer_low_mark. |
7.5 Flow Control
| config option | default value | description |
|---|---|---|
| transport.max_pending_requests | 8 | The max number of client unreceived ACKs. It will trigger sending unavailable if the number of unreceived ACKs >= max_pending_requests. |
| transport.min_pending_requests | 6 | The minimum number of client unreceived ACKs. It will trigger sending available if the number of unreceived ACKs < min_pending_requests. |
| transport.min_ack_interval | 200 | The minimum interval (in ms) of server reply ACK. |
7.6 Timeouts
| config option | default value | description |
|---|---|---|
| transport.close_timeout | 10000 | The timeout (in ms) of close server or close client. |
| transport.sync_request_timeout | 10000 | The timeout (in ms) to wait for response after sending sync-request. |
| transport.finish_session_timeout | 0 | The timeout (in ms) to finish session. 0 means using (transport.sync_request_timeout × transport.max_pending_requests). |
| transport.write_socket_timeout | 3000 | The timeout (in ms) to write data to socket buffer. |
| transport.server_idle_timeout | 360000 (6 minutes) | The max timeout (in ms) of server idle. |
7.7 Heartbeat
| config option | default value | description |
|---|---|---|
| transport.heartbeat_interval | 20000 (20 seconds) | The minimum interval (in ms) between heartbeats on client side. |
| transport.max_timeout_heartbeat_count | 120 | The maximum times of timeout heartbeat on client side. If the number of timeouts waiting for heartbeat response continuously > max_timeout_heartbeat_count, the channel will be closed from client side. |
7.8 Advanced Network Settings
| config option | default value | description |
|---|---|---|
| transport.max_syn_backlog | 511 | The capacity of SYN queue on server side. 0 means using system default value. |
| transport.recv_file_mode | true | Whether to enable receive buffer-file mode. It will receive buffer and write to file from socket using zero-copy if enabled. Note: Requires OS support for zero-copy (e.g., Linux sendfile/splice). |
| transport.network_retries | 3 | The number of retry attempts for network communication if network is unstable. |
8. Storage & Persistence Configuration
Configuration for HGKV (HugeGraph Key-Value) storage engine and value files.
8.1 HGKV Configuration
| config option | default value | description |
|---|---|---|
| hgkv.max_file_size | 2147483648 (2 GB) | The max number of bytes in each HGKV file. |
| hgkv.max_data_block_size | 65536 (64 KB) | The max byte size of HGKV file data block. |
| hgkv.max_merge_files | 10 | The max number of files to merge at one time. |
| hgkv.temp_file_dir | /tmp/hgkv | This folder is used to store temporary files during the file merging process. |
8.2 Value File Configuration
| config option | default value | description |
|---|---|---|
| valuefile.max_segment_size | 1073741824 (1 GB) | The max number of bytes in each segment of value-file. |
9. BSP & Coordination Configuration
Configuration for Bulk Synchronous Parallel (BSP) protocol and etcd coordination.
| config option | default value | description |
|---|---|---|
| bsp.etcd_endpoints | http://localhost:2379 | The etcd endpoints; separate multiple addresses with commas. In K8s deployments, this option is set by the Operator. |
| bsp.max_super_step | 10 (packaged: 2) | The max super step of the algorithm. |
| bsp.register_timeout | 300000 (packaged: 100000) | The max timeout (in ms) to wait for master and workers to register. |
| bsp.wait_workers_timeout | 86400000 (24 hours) | The max timeout (in ms) to wait for workers BSP event. |
| bsp.wait_master_timeout | 86400000 (24 hours) | The max timeout (in ms) to wait for master BSP event. |
| bsp.log_interval | 30000 (30 seconds) | The log interval (in ms) to print the log while waiting for BSP event. |
10. Performance Tuning Configuration
Configuration for performance optimization.
| config option | default value | description |
|---|---|---|
| allocator.max_vertices_per_thread | 10000 | Maximum number of vertices per thread processed in each memory allocator. |
| sort.thread_nums | 4 | The number of threads performing internal sorting. |
11. System Administration Configuration
The following options are managed by the runtime system and should not be overridden in job configurations.
The following configuration items are automatically managed by the K8s Operator, Driver, or runtime system. Manual modification will cause cluster communication failures or job scheduling errors.
| config option | managed by | description |
|---|---|---|
| bsp.etcd_endpoints | K8s Operator | Automatically set to operator’s etcd service address |
| transport.server_host | Runtime | Automatically set to pod/container hostname |
| transport.server_port | Runtime | Automatically assigned random port |
| job.namespace | K8s Operator | Automatically set to job namespace |
| job.id | K8s Operator | Automatically set to job ID from CRD |
| job.workers_count | K8s Operator | Automatically set from CRD workerInstances |
| rpc.server_host | Runtime | RPC server hostname (system-managed) |
| rpc.server_port | Runtime | RPC server port (system-managed) |
| rpc.remote_url | Runtime | RPC remote URL (system-managed) |
Why These Are Forbidden:
- BSP/RPC Configuration: Must match the actual deployed etcd/RPC services. Manual overrides break coordination.
- Job Configuration: Must match K8s CRD specifications. Mismatches cause worker count errors.
- Transport Configuration: Must use actual pod hostnames/ports. Manual values prevent inter-worker communication.
K8s Operator Config Options
NOTE: Option needs to be converted through environment variable settings, e.g. k8s.internal_etcd_url => INTERNAL_ETCD_URL
| config option | default value | description |
|---|---|---|
| k8s.auto_destroy_pod | true | Whether to automatically destroy all pods when the job is completed or failed. |
| k8s.close_reconciler_timeout | 120 | The max timeout (in ms) to close reconciler. |
| k8s.internal_etcd_url | http://127.0.0.1:2379 | The internal etcd URL for operator system. |
| k8s.max_reconcile_retry | 3 | The max retry times of reconcile. |
| k8s.probe_backlog | 50 | The maximum backlog for serving health probes. |
| k8s.probe_port | 9892 | The port that the controller binds to for serving health probes. |
| k8s.ready_check_internal | 1000 | The time interval (ms) of check ready. |
| k8s.ready_timeout | 30000 | The max timeout (in ms) of check ready. |
| k8s.reconciler_count | 10 | The max number of reconciler threads. |
| k8s.resync_period | 600000 | The minimum frequency at which watched resources are reconciled. |
| k8s.timezone | Asia/Shanghai | The timezone of computer job and operator. |
| k8s.watch_namespace | hugegraph-computer-system | The namespace to watch custom resources in. Use ‘*’ to watch all namespaces. |
HugeGraph-Computer CRD
| spec | default value | description | required |
|---|---|---|---|
| algorithmName | The name of algorithm. | true | |
| jobId | The job id. | true | |
| image | The image of algorithm. | true | |
| computerConf | The map of computer config options. | true | |
| workerInstances | The number of worker instances, it will override the ‘job.workers_count’ option. | true | |
| pullPolicy | Always | The pull-policy of image, detail please refer to: https://kubernetes.io/docs/concepts/containers/images/#image-pull-policy | false |
| pullSecrets | The pull-secrets of Image, detail please refer to: https://kubernetes.io/docs/concepts/containers/images/#specifying-imagepullsecrets-on-a-pod | false | |
| masterCpu | The cpu limit of master, the unit can be ’m’ or without unit detail please refer to: https://kubernetes.io/docs/concepts/configuration/manage-resources-containers/#meaning-of-cpu | false | |
| workerCpu | The cpu limit of worker, the unit can be ’m’ or without unit detail please refer to: https://kubernetes.io/docs/concepts/configuration/manage-resources-containers/#meaning-of-cpu | false | |
| masterMemory | The memory limit of master, the unit can be one of Ei、Pi、Ti、Gi、Mi、Ki detail please refer to: https://kubernetes.io/docs/concepts/configuration/manage-resources-containers/#meaning-of-memory | false | |
| workerMemory | The memory limit of worker, the unit can be one of Ei、Pi、Ti、Gi、Mi、Ki detail please refer to: https://kubernetes.io/docs/concepts/configuration/manage-resources-containers/#meaning-of-memory | false | |
| log4jXml | The content of log4j.xml for computer job. | false | |
| jarFile | The jar path of computer algorithm. | false | |
| remoteJarUri | The remote jar uri of computer algorithm, it will overlay algorithm image. | false | |
| jvmOptions | The java startup parameters of computer job. | false | |
| envVars | please refer to: https://kubernetes.io/docs/tasks/inject-data-application/define-interdependent-environment-variables/ | false | |
| envFrom | please refer to: https://kubernetes.io/docs/tasks/inject-data-application/define-environment-variable-container/ | false | |
| masterCommand | bin/start-computer.sh | The run command of master, equivalent to ‘Entrypoint’ field of Docker. | false |
| masterArgs | ["-r master", “-d k8s”] | The run args of master, equivalent to ‘Cmd’ field of Docker. | false |
| workerCommand | bin/start-computer.sh | The run command of worker, equivalent to ‘Entrypoint’ field of Docker. | false |
| workerArgs | ["-r worker", “-d k8s”] | The run args of worker, equivalent to ‘Cmd’ field of Docker. | false |
| volumes | Please refer to: https://kubernetes.io/docs/concepts/storage/volumes/ | false | |
| volumeMounts | Please refer to: https://kubernetes.io/docs/concepts/storage/volumes/ | false | |
| secretPaths | The map of k8s-secret name and mount path. | false | |
| configMapPaths | The map of k8s-configmap name and mount path. | false | |
| podTemplateSpec | Please refer to: https://kubernetes.io/docs/reference/kubernetes-api/workload-resources/pod-template-v1/#PodTemplateSpec | false | |
| securityContext | Please refer to: https://kubernetes.io/docs/tasks/configure-pod-container/security-context/ | false |
KubeDriver Config Options
| config option | default value | description |
|---|---|---|
| k8s.build_image_bash_path | The path of command used to build image. | |
| k8s.enable_internal_algorithm | true | Whether enable internal algorithm. |
| k8s.framework_image_url | hugegraph/hugegraph-computer:latest | The image url of computer framework. |
| k8s.image_repository_password | The password for login image repository. | |
| k8s.image_repository_registry | The address for login image repository. | |
| k8s.image_repository_url | hugegraph/hugegraph-computer | The url of image repository. |
| k8s.image_repository_username | The username for login image repository. | |
| k8s.internal_algorithm | [pageRank] | The name list of all internal algorithm. Note: Algorithm names use camelCase here (e.g., pageRank), but algorithm implementations return underscore_case (e.g., page_rank). |
| k8s.internal_algorithm_image_url | hugegraph/hugegraph-computer:latest | The image url of internal algorithm. |
| k8s.jar_file_dir | /cache/jars/ | The directory where the algorithm jar will be uploaded. |
| k8s.kube_config | ~/.kube/config | The path of k8s config file. |
| k8s.log4j_xml_path | The log4j.xml path for computer job. | |
| k8s.namespace | hugegraph-computer-system | The namespace of hugegraph-computer system. |
| k8s.pull_secret_names | [] | The names of pull-secret for pulling image. |
5 - HugeGraph Client
The Java and Go clients are maintained in the HugeGraph Toolchain repository, while the Python client is maintained in the HugeGraph-AI repository. Their installation methods and APIs differ; see the corresponding pages for details.
5.1 - HugeGraph-Java-Client
1 Overview
HugeGraph Java Client translates Java APIs into REST requests to HugeGraph Server. It supports managing schemas and graph data, executing Gremlin queries, and calling Traverser APIs. See the Client API for detailed interfaces; this page shows how to use the client in a Java project.
For other languages, use the Go Client or the Python Client maintained in the HugeGraph-AI repository.
2 What You Need
- JDK 11 (used by the current CI; the source target remains Java 8)
- Maven 3.6+
3 How To Use
The basic steps to use HugeGraph-Client are as follows:
- Build a new Maven project by IDEA or Eclipse
- Add HugeGraph-Client dependency in a pom file;
- Create an object to invoke the interface of HugeGraph-Client
See the complete example in the following section for the detail.
4 Complete Example
4.1 Build New Maven Project
Using IDEA or Eclipse to create the project:
4.2 Add Hugegraph-Client Dependency In POM
Development versions of the client and server may differ. Check the corresponding release notes for compatibility before upgrading.
4.3 Example
4.3.1 SingleExample
4.3.2 BatchExample
4.4 Run The Example
Before running Example, you need to start the Server. For the startup process, seeHugeGraph-Server Quick Start.
4.5 More Information About Client-API
5.2 - HugeGraph Python Client Quick Start
hugegraph-python-client is the Python SDK for HugeGraph. It manages schemas, reads and writes graph data, and executes Gremlin queries. HugeGraph-LLM and HugeGraph-ML also use this client.
Requirements
- Python 3.9 or later
- An accessible HugeGraph Server
uv(recommended) orpip
Installation
The package is currently published on PyPI as hugegraph-python:
To use the latest repository code, sync the workspace from the root of the HugeGraph-AI repository:
Connect and Write Data
If GraphSpace is disabled in HugeGraph, omit graphspace. When it is enabled, pass the actual space name; the default space is usually DEFAULT.
Common Operations
Query the Schema
Update and Delete Graph Data
The graph API accepts dictionaries containing object properties:
Execute Gremlin
API parameters may change with the HugeGraph REST API version. If an interface is incompatible, first check the REST API documentation for the current server version and the client test cases.
Development Checks
Run formatting and static checks from the root of the HugeGraph-AI repository:
The source code and tests are under hugegraph-python-client/src/pyhugegraph/ and hugegraph-python-client/src/tests/.
5.3 - HugeGraph Go Client Quick Start
HugeGraph Go Client is the Go SDK in the Toolchain repository. It currently provides APIs for version queries, schemas, vertices, edges, and Gremlin.
This module is still under development. Refer to the source code under
hugegraph-client-go/api/v1for the currently available interfaces.
Requirements
- Go 1.19 or later
- An accessible HugeGraph Server; examples use
http://127.0.0.1:8080
Installation
Run the following command in a Go module project:
Initialize the Client
NewCommonClient requires Host to be an IP address. Leave the username and password empty when authentication is disabled. Current server graph resource paths include a graph space; use DEFAULT for the default space. Leaving GraphSpace empty applies only to older servers that still use the /graphs/{graph} path.
The Versions value returned by Version() includes the HugeGraph Server, Core, Gremlin, and REST API versions. The NewDefaultCommonClient() helper in the source connects to the hugegraph graph at 127.0.0.1:8080 with admin/pa authentication. Production code should normally pass an explicit configuration instead.
Available Entry Points
CommonClient currently exposes the following entry points:
| Entry point | Purpose |
|---|---|
Version() | Query the server version |
Schema() | Query the complete schema |
Propertykey | Manage property keys |
VertexLabel | Manage vertex labels |
EdgeLabel | Manage edge labels |
Vertex | Create vertices in single or batch mode and update vertex properties |
Gremlin | Execute Gremlin through GET or POST |
For complete usage, see the tests in each API directory, such as version_test.go and vertexlabel_test.go.