This is the multi-page printable view of this section. .
HugeGraph (OLTP)
🚀 Best practice: Prioritize using DeepWiki intelligent documents
To address the issue of outdated static documents, we provide DeepWiki with real-time updates and more comprehensive content. It is equivalent to an expert with the latest knowledge of the project, which is very suitable for all developers to read and consult before starting the project.
👉 Strongly recommend visiting and having a conversation with: incubator-hugegraph
1 - HugeGraph Server Quick Start
1 HugeGraph Server Overview
apache/hugegraph is the main repository for the HugeGraph graph database. Its top-level modules include hugegraph-server, hugegraph-pd, and hugegraph-store. This page describes the hugegraph-server module and the service it runs.
The hugegraph-server module contains hugegraph-core, hugegraph-api, hugegraph-dist, and storage adapters. Core implements the property graph model, transactions, and TinkerPop interfaces. API provides the HTTP service and delegates client requests to Core. Graph data is stored in RocksDB (the default standalone backend), HStore (distributed), or HBase.
⚠️ Version note: This page follows HugeGraph 1.7.0 through the
masterbranch and covers only RocksDB, HStore, and HBase. For other legacy backends and their configuration, see the HugeGraph 1.5.x documentation.
Naming:
HugeGraphmeans the overall project or main repository,hugegraph-serveris the Server module in that repository, andHugeGraphServeris the Java class for the service process. This page uses “Server service” for a running graph database service.
2 Dependency for Building/Running
2.1 Install Java 11 (JDK 11)
The hugegraph-server module in HugeGraph 1.7.0 is compiled with Java 11. Running and building it from source require Java 11 or later.
Before continuing, run java -version to confirm your JDK version.
Java 8 is no longer supported starting from 1.7.0.
3 Deploy
There are four ways to deploy the Server service:
- Method 1: Use Docker container (Convenient for Test/Dev)
- Method 2: Download the binary tarball
- Method 3: Source code compilation
- Method 4: One-click deployment
Do not expose Gremlin, Cypher, or other query endpoints directly to the public Internet. In production, enable authentication and authorization, restrict network access, and retain audit logs. See the Security Guide for deployment guidance.
3.1 Use Docker container (Convenient for Test/Dev)
You can refer to the Docker deployment guide.
You can use docker run -itd --name=server -p 8080:8080 -e PASSWORD=xxx hugegraph/hugegraph:1.7.0 to quickly start a Server instance using the RocksDB backend.
Optional:
- You can use
docker exec -it server bashto enter the container for troubleshooting or other maintenance operations. - You can use
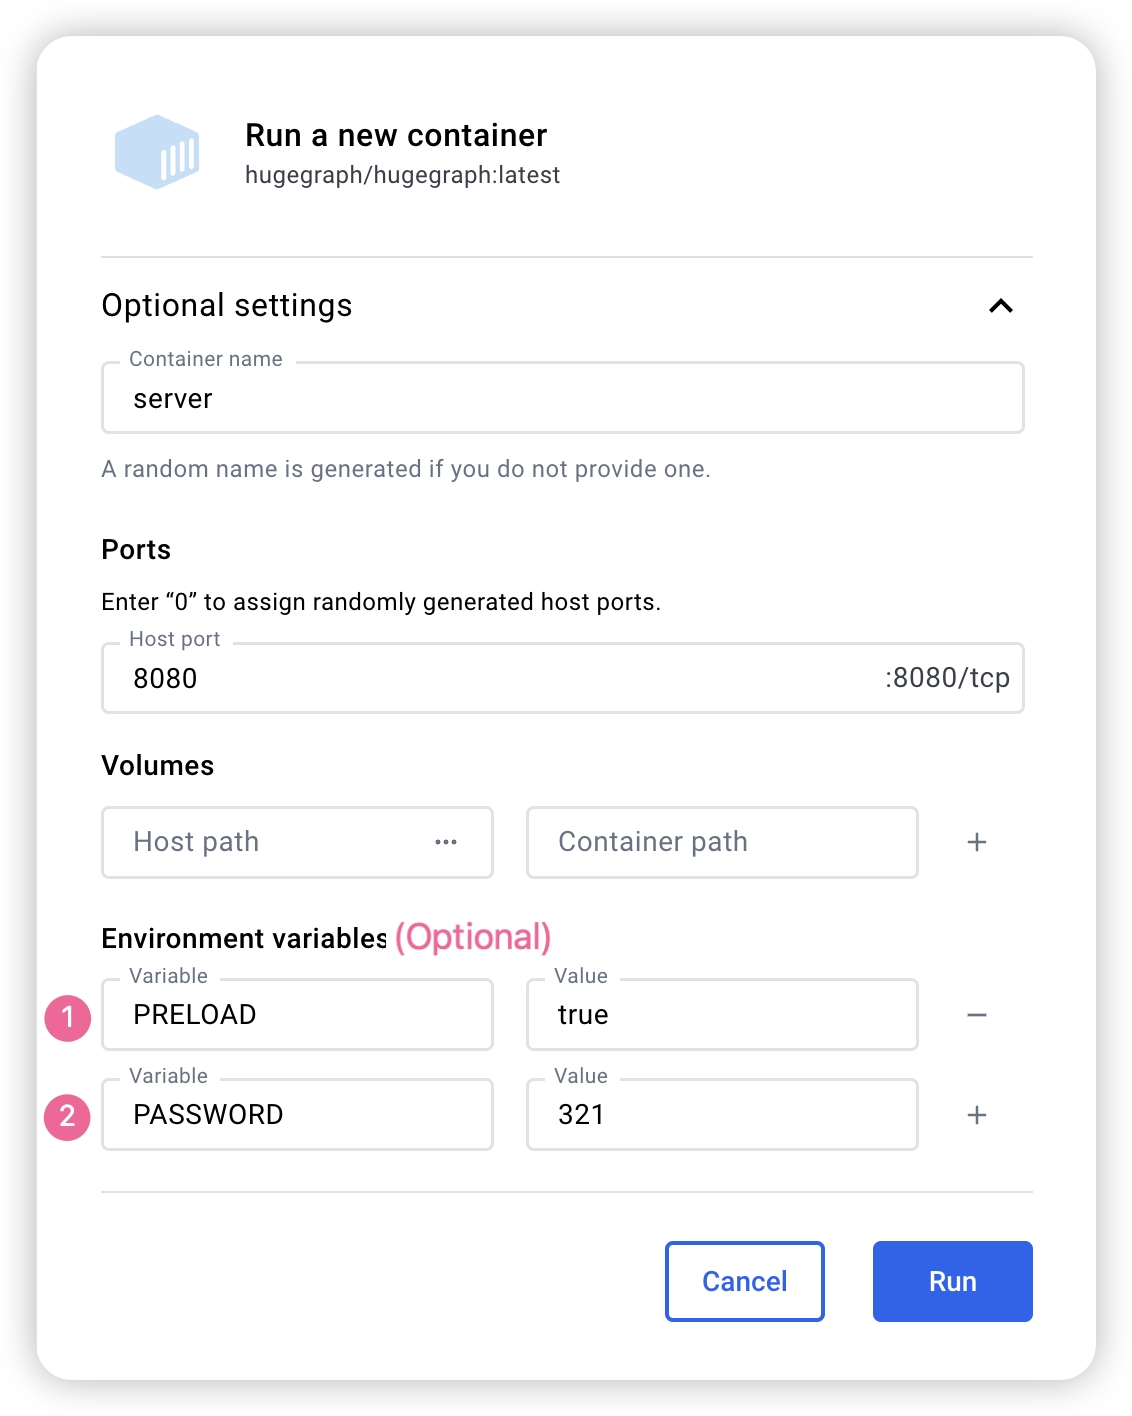
docker run -itd --name=server -p 8080:8080 -e PRELOAD="true" hugegraph/hugegraph:1.7.0to preload a built-in sample graph at startup. You can verify it through theRESTful API. See 5.1.4 for details. - You can use
-e PASSWORD=xxxto enable authentication mode and set the admin password. See Config Authentication for details.
If you use Docker Desktop, you can set the options as follows:
Note: The Docker Compose files use bridge networking (
hg-net) and work on Linux and Mac (Docker Desktop). For the 3-node distributed cluster on Mac (Docker Desktop), allocate at least 12 GB of memory (Settings → Resources → Memory). On Linux, Docker uses host memory directly.
If you want a single, unified setup for multiple HugeGraph services, you can use docker compose.
Two compose files are available in the docker/ directory:
- Single-node quickstart (pre-built images):
docker/docker-compose.yml - Single-node dev build (build from source):
docker/docker-compose.dev.yml
To enable authentication, add PASSWORD=xxx to the service environment in the compose file or pass -e PASSWORD=xxx to docker run.
See docker/README.md for the full setup guide.
Note:
HugeGraph Docker images are provided as a convenient way to start HugeGraph quickly, but they are not official ASF distribution artifacts. You can find more details in the ASF Release Distribution Policy.
We recommend using a release tag (such as
1.7.0or1.x.0) for stable deployments. Use thelatesttag only if you want the newest features still under development.
3.2 Download the binary tarball
You could download the binary tarball from the download page of the ASF site like this:
3.3 Source code compilation
Please ensure that the wget/curl commands are installed before compiling the source code
Download HugeGraph source code in either of the following 2 ways (so as the other HugeGraph repos/modules):
- download the stable/release version from the ASF site
- clone the unstable/latest version by GitBox(ASF) or GitHub
Compile and generate tarball
A successful build includes the following line:
After a successful build, the generated distribution is the *hugegraph-*.tar.gz file in the repository root.
3.4 One-click deployment (Outdated)
HugeGraph-Tools provides a one-click deployment command that downloads, extracts, configures, and starts the Server service and HugeGraph-Hubble. These tools are included in the HugeGraph-Toolchain distribution.
Of course, you should download the tarball of HugeGraph-Toolchain first.
note:
${version}is the version, The latest version can refer to Download Page, or click the link to download directly from the Download page
The general entry script for HugeGraph-Tools is bin/hugegraph, Users can use the help command to view its usage, here only the commands for one-click deployment are introduced.
{hugegraph-version} is the Server service and HugeGraphStudio version; see conf/version-mapping.yaml for supported mappings. {install-path} is the installation directory, while {download-path-prefix} optionally overrides the tarball download location. For example, deploy version 0.6 with bin/hugegraph deploy -v 0.6 -p services.
4 Config
If you need to quickly start HugeGraph just for testing, then you only need to modify a few configuration items (see next section). For detailed configuration introduction, please refer to configuration document and introduction to configuration items
5 Startup
5.1 Use a startup script to startup
Startup is divided into “first startup” and “non-first startup”. On the first startup, you need to initialize the backend database before starting the service.
If the service was stopped manually, or needs to be started again for any other reason, you can usually start it directly because the backend database is persistent.
When HugeGraphServer starts, it connects to the backend storage and checks its version information. If the backend has not been initialized, or if it was initialized with an incompatible version (for example, old-version data), HugeGraphServer will fail to start and report an error.
If you need to access HugeGraphServer externally, modify the restserver.url configuration item in rest-server.properties (the default is http://127.0.0.1:8080) and change it to the machine name or IP address.
Since the configuration (hugegraph.properties) and startup steps required by various backends are slightly different, the following will introduce the configuration and startup of each backend one by one.
Note: Configure Server Authentication before starting HugeGraphServer if you need Auth mode (especially for production or public network environments).
5.1.1 Distributed Storage (HStore)
Distributed storage is a new feature introduced after HugeGraph 1.5.0, which implements distributed data storage and computation based on HugeGraph-PD and HugeGraph-Store components.
To use the distributed storage engine, you need to deploy HugeGraph-PD and HugeGraph-Store first. See HugeGraph-PD Quick Start and HugeGraph-Store Quick Start.
After ensuring that both PD and Store services are started, modify the hugegraph.properties configuration of HugeGraph-Server:
Then enable PD discovery in rest-server.properties (required for every HugeGraph-Server node):
If configuring multiple HugeGraph-Server nodes, you need to modify the rest-server.properties configuration file for each node, for example:
Node 1 (Master node):
Node 2 (Worker node):
Also, you need to modify the port configuration in gremlin-server.yaml for each node:
Node 1:
Node 2:
Initialize the database:
Start the Server:
The startup sequence for using the distributed storage engine is:
- Start HugeGraph-PD
- Start HugeGraph-Store
- Initialize the database (only for the first time)
- Start HugeGraph-Server
Verify that the service is started properly:
The sequence to stop the services should be the reverse of the startup sequence:
- Stop HugeGraph-Server
- Stop HugeGraph-Store
- Stop HugeGraph-PD
Docker Distributed Cluster
Run the full distributed cluster (3 PD + 3 Store + 3 Server) with Docker Compose:
Services communicate via container hostnames on the hg-net bridge network. Configuration is injected via environment variables:
Verify the cluster:
To view runtime logs for any container use docker logs <container-name> (e.g. docker logs hg-pd0).
See docker/README.md for the full environment variable reference, port table, and troubleshooting guide.
5.1.2 RocksDB / ToplingDB
RocksDB is an embedded database that does not require manual installation and deployment. GCC version >= 4.3.0 (GLIBCXX_3.4.10) is required. If not, GCC needs to be upgraded in advance
Update hugegraph.properties
Initialize the database (required on the first startup, or a new configuration was manually added under ‘conf/graphs/’)
Start server
ToplingDB (Beta): As a high-performance alternative to RocksDB, please refer to the configuration guide: ToplingDB Quick Start
5.1.3 HBase
users need to install HBase by themselves, requiring version 2.0 or above,download link
Update hugegraph.properties
Initialize the database (required on the first startup, or a new configuration was manually added under ‘conf/graphs/’)
Start server
5.1.4 Create an example graph when startup
Pass the -p true argument when starting the script to enable preload, which creates a sample graph.
And use the RESTful API to request HugeGraphServer and get the following result:
This indicates the successful creation of the sample graph.
5.2 Use Docker to startup
In 3.1 Use Docker container, we introduced how to deploy hugegraph-server with Docker. You can also switch storage backends or preload a sample graph by setting the corresponding parameters.
5.2.1 Create an example graph when starting a server
Set the environment variable PRELOAD=true when starting Docker so that sample data is loaded during startup.
Use
docker runUse
docker run -itd --name=server -p 8080:8080 -e PRELOAD=true hugegraph/hugegraph:1.7.0Use
docker-composeCreate a
docker-compose.ymlfile like the following and setPRELOAD=truein the environment.example.groovyis a predefined script used to preload sample data. If needed, you can mount a newexample.groovyscript to change the preload data.Use
docker-compose up -dto start the container.
And use the RESTful API to request HugeGraphServer and get the following result:
This indicates that the sample graph was created successfully.
6. Access server
6.1 Service startup status check
Use jps to see a service process
curl request RESTfulAPI
Return 200, which means the server starts normally.
6.2 Request Server
The RESTful API of HugeGraphServer includes various types of resources, typically including graph, schema, gremlin, traverser and task.
graphcontainsvertices、edgesschemacontainsvertexlabels、propertykeys、edgelabels、indexlabelsgremlincontains variousGremlinstatements, such asg.v(), which can be executed synchronously or asynchronouslytraversercontains various advanced queries including shortest paths, intersections, N-step reachable neighbors, etc.taskcontains query and delete with asynchronous tasks
6.2.1 Get vertices and its related properties in hugegraph
explanation
Since there are many vertices and edges in the graph, for list-type requests, such as getting all vertices, getting all edges, etc., the server will compress the data and return it, so when use curl, you get a bunch of garbled characters, you can redirect to gunzip for decompression. It is recommended to use the Chrome browser + Restlet plugin to send HTTP requests for testing.
The current default configuration of HugeGraphServer can only be accessed locally, and the configuration can be modified so that it can be accessed on other machines.
response body:
For the detailed API, please refer to RESTful-API
You can also visit localhost:8080/swagger-ui/index.html to check the API.
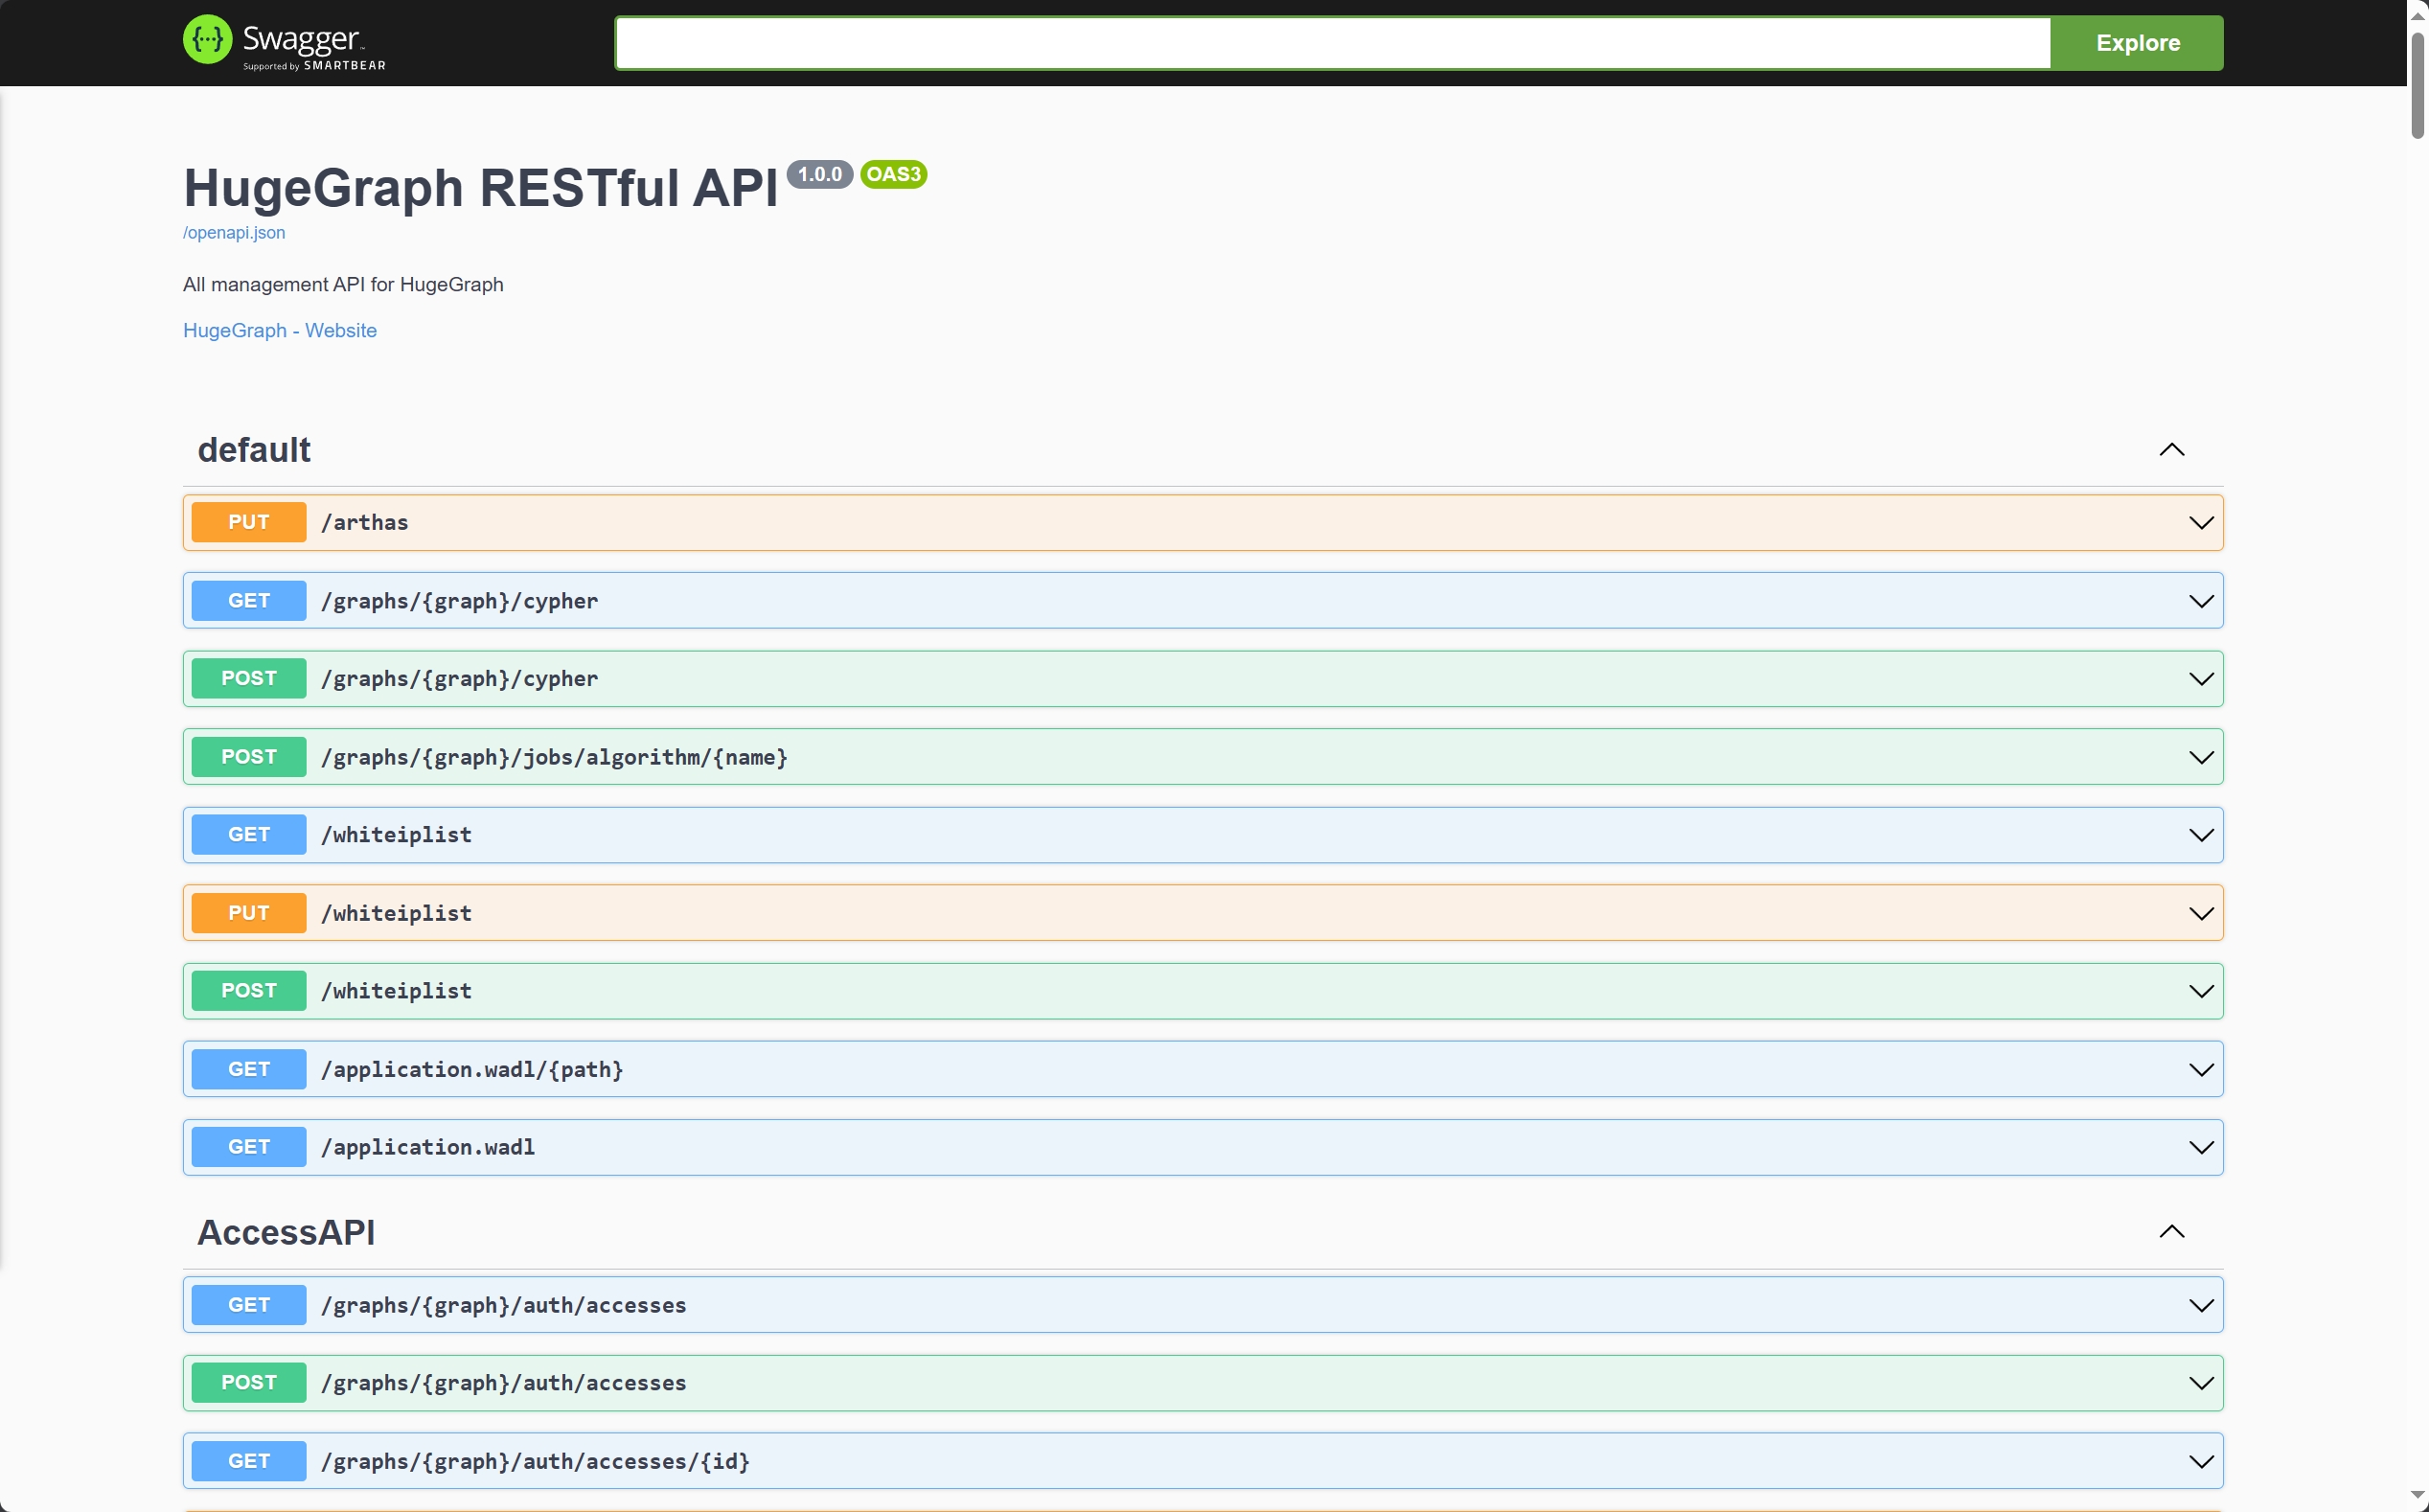
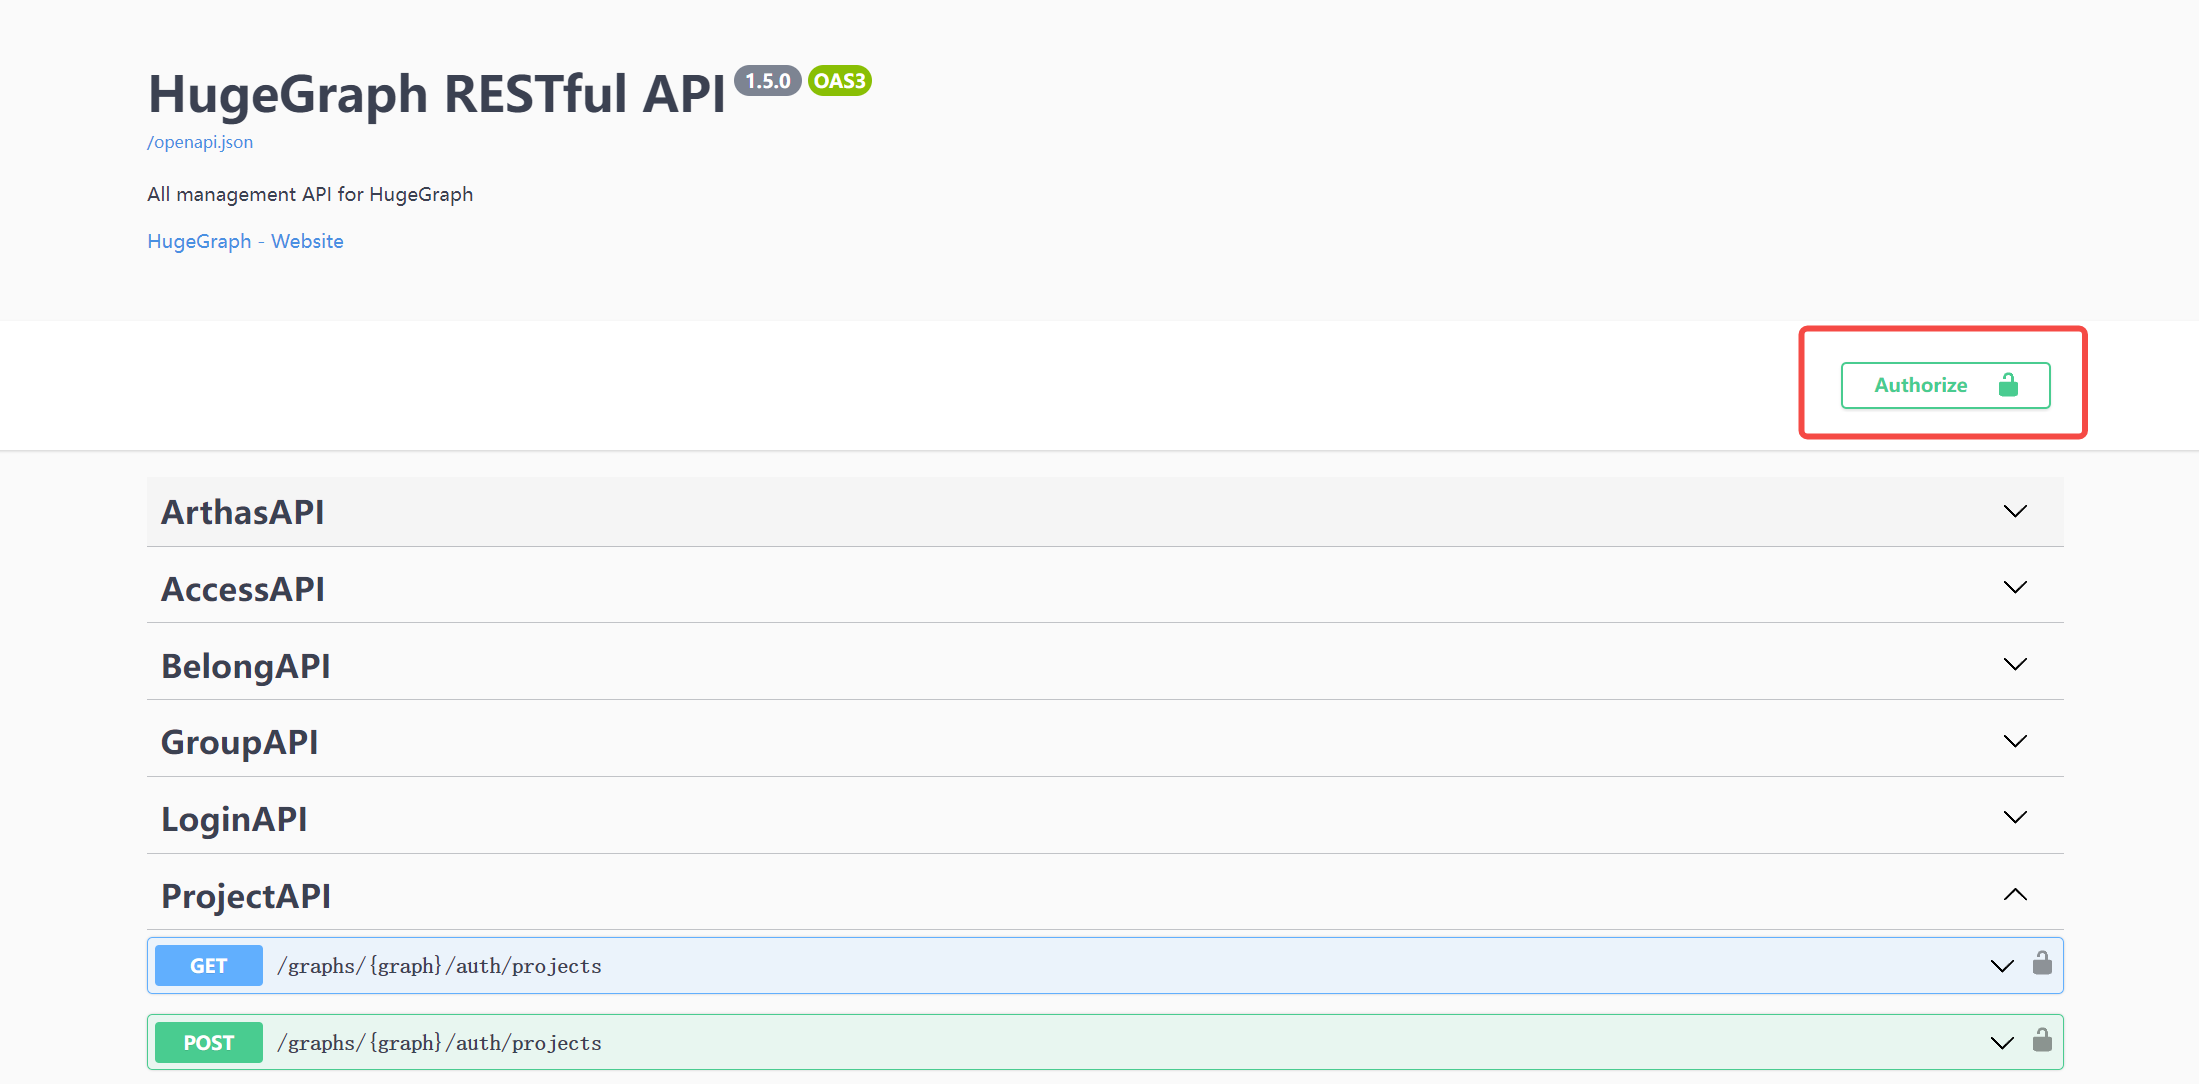
When using Swagger UI to debug the API provided by HugeGraph, if HugeGraph Server turns on authentication mode, you can enter authentication information on the Swagger page.
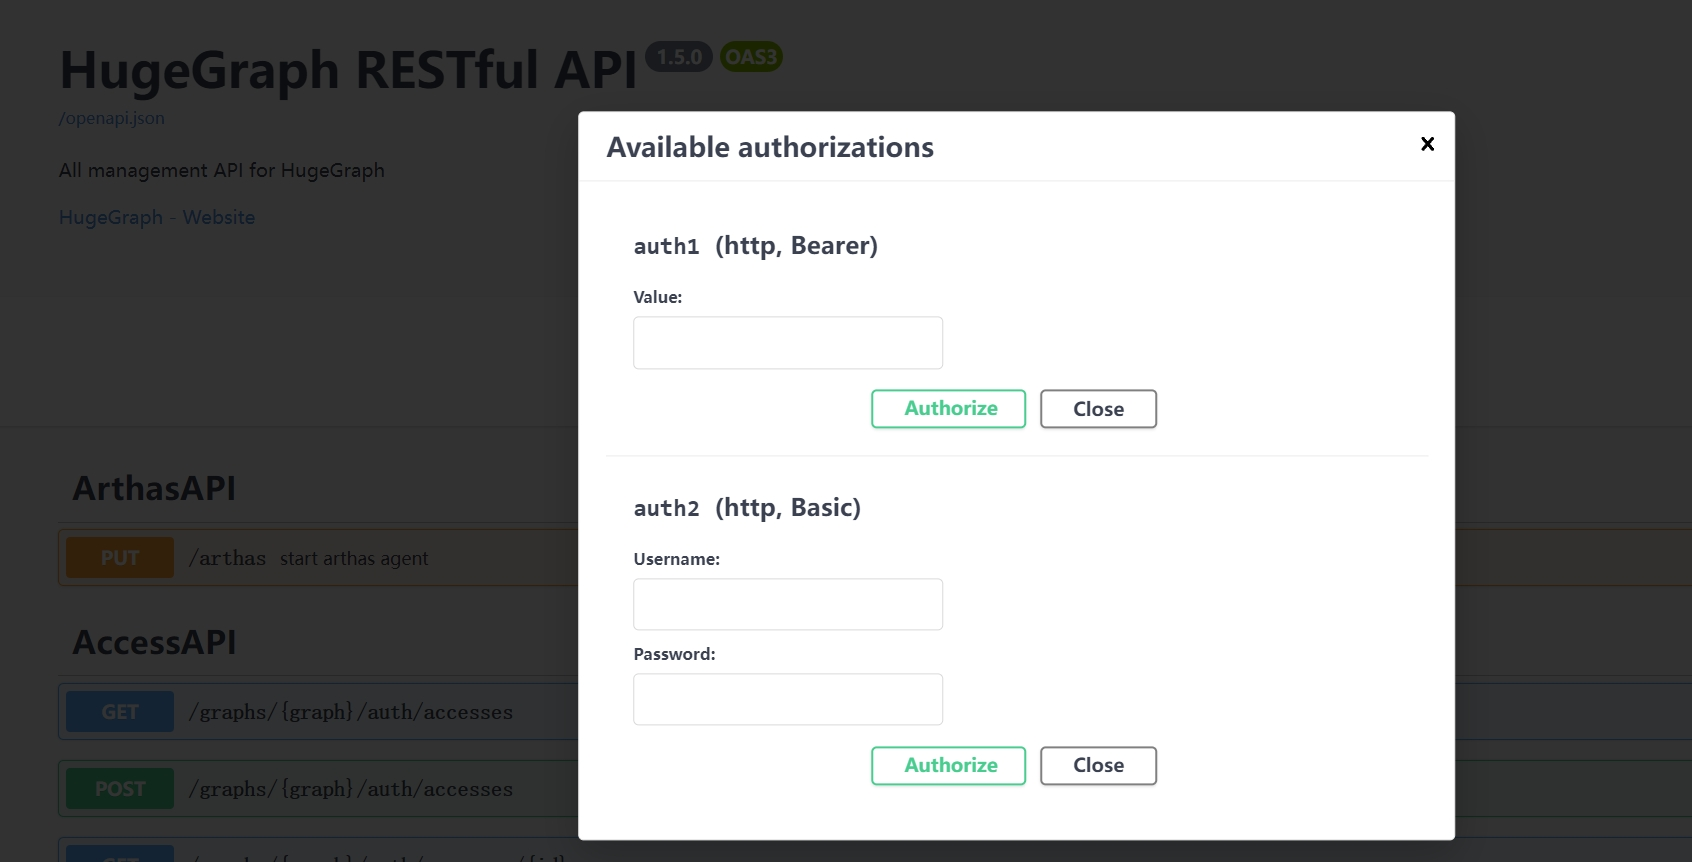
Currently, HugeGraph supports setting authentication information in two forms: Basic and Bearer.
7 Stop Server
8 Debug Server with IntelliJ IDEA
Please refer to Setup Server in IDEA
2 - HugeGraph-PD Quick Start
1 HugeGraph-PD Overview
HugeGraph-PD (Placement Driver) is the metadata management component of HugeGraph’s distributed version, responsible for managing the distribution of graph data and coordinating storage nodes. It plays a central role in distributed HugeGraph, maintaining cluster status and coordinating HugeGraph-Store storage nodes.
2 Prerequisites
2.1 Requirements
- Operating System: Linux or macOS (Windows has not been fully tested)
- Java version: ≥ 11
- Maven version: ≥ 3.5.0
3 Deployment
There are two ways to deploy the HugeGraph-PD component:
- Method 1: Download the tar package
- Method 2: Compile from source
3.1 Download the tar package
Download the latest version of HugeGraph-PD from the Apache HugeGraph official download page:
3.2 Compile from source
3.3 Docker Deployment
The HugeGraph-PD Docker image is available on Docker Hub as hugegraph/pd.
Note: The following steps assume you have already cloned or pulled the HugeGraph main repository locally, or at least have its
docker/directory available.
Use the docker compose setup to deploy the complete 3-node cluster (PD + Store + Server):
To run a single PD node via docker run, configuration is provided via environment variables:
Environment variable reference:
| Variable | Required | Default | Description |
|---|---|---|---|
HG_PD_GRPC_HOST | Yes | — | This node’s hostname/IP for gRPC (e.g. pd0 in Docker, 192.168.1.10 on bare metal) |
HG_PD_RAFT_ADDRESS | Yes | — | This node’s Raft address (e.g. pd0:8610) |
HG_PD_RAFT_PEERS_LIST | Yes | — | All PD peers (e.g. pd0:8610,pd1:8610,pd2:8610) |
HG_PD_INITIAL_STORE_LIST | Yes | — | Expected store gRPC addresses (e.g. store0:8500,store1:8500,store2:8500) |
HG_PD_GRPC_PORT | No | 8686 | gRPC server port |
HG_PD_REST_PORT | No | 8620 | REST API port |
HG_PD_DATA_PATH | No | /hugegraph-pd/pd_data | Metadata storage path |
HG_PD_INITIAL_STORE_COUNT | No | 1 | Minimum stores required for cluster availability |
Note: In Docker bridge networking, use container hostnames (e.g.
pd0) forHG_PD_GRPC_HOSTandHG_PD_RAFT_ADDRESSinstead of IP addresses.
Deprecated aliases:
GRPC_HOST,RAFT_ADDRESS,RAFT_PEERS,PD_INITIAL_STORE_LISTstill work but log a deprecation warning. Use theHG_PD_*names for new deployments.
To view runtime logs for a running PD container use docker logs <container-name> (e.g. docker logs hg-pd0).
See docker/README.md for the full cluster setup guide.
4 Configuration
The main configuration file for PD is conf/application.yml. Here are the key configuration items:
For multi-node deployment, you need to modify the port and address configurations for each node to ensure proper communication between nodes.
5 Start and Stop
5.1 Start PD
In the PD installation directory, execute:
The startup script supports a -d flag to control daemon mode:
-d true(default): run as a background daemon; the script returns immediately.-d false: run in foreground — the scriptexecs Java, so the container/supervisor process IS Java. Use this when running under Docker or a process supervisor (systemd, supervisord) so crashes are detected and the service is restarted automatically.
After successful startup, you can see logs similar to the following in logs/hugegraph-pd-stdout.log:
5.2 Stop PD
In the PD installation directory, execute:
6 Verification
Confirm that the PD service is running properly:
If it returns {"status":"UP"}, it indicates that the PD service has been successfully started.
You can also verify Store node status through the PD API:
If the response shows state as Up, the corresponding Store node is running normally. The example below shows a single Store node. In a healthy 3-node deployment, the storeId list should contain three IDs, and stateCountMap.Up, numOfService, and numOfNormalService should all be 3.
3 - HugeGraph-Store Quick Start
1 HugeGraph-Store Overview
HugeGraph-Store is the storage node component of HugeGraph’s distributed version, responsible for actually storing and managing graph data. It works in conjunction with HugeGraph-PD to form HugeGraph’s distributed storage engine, providing high availability and horizontal scalability.
2 Prerequisites
2.1 Requirements
- Operating System: Linux or macOS (Windows has not been fully tested)
- Java version: ≥ 11
- Maven version: ≥ 3.5.0
- Deploy HugeGraph-PD first for multi-node deployment
3 Deployment
There are two ways to deploy the HugeGraph-Store component:
- Method 1: Download the tar package
- Method 2: Compile from source
3.1 Download the tar package
Download the latest version of HugeGraph-Store from the Apache HugeGraph official download page:
3.2 Compile from source
3.3 Docker Deployment
The HugeGraph-Store Docker image is available on Docker Hub as hugegraph/store.
Note: The following steps assume you have already cloned or pulled the HugeGraph main repository locally, or at least have its
docker/directory available.
Use the compose file to deploy the complete 3-node cluster (PD + Store + Server):
To run a single Store node via docker run:
Environment variable reference:
| Variable | Required | Default | Description |
|---|---|---|---|
HG_STORE_PD_ADDRESS | Yes | — | PD gRPC addresses (e.g. pd0:8686,pd1:8686,pd2:8686) |
HG_STORE_GRPC_HOST | Yes | — | This node’s hostname/IP for gRPC (e.g. store0) |
HG_STORE_RAFT_ADDRESS | Yes | — | This node’s Raft address (e.g. store0:8510) |
HG_STORE_GRPC_PORT | No | 8500 | gRPC server port |
HG_STORE_REST_PORT | No | 8520 | REST API port |
HG_STORE_DATA_PATH | No | /hugegraph-store/storage | Data storage path |
Note: In Docker bridge networking, use container hostnames (e.g.
store0) forHG_STORE_GRPC_HOSTinstead of IP addresses.
Deprecated aliases:
PD_ADDRESS,GRPC_HOST,RAFT_ADDRESSstill work but log a deprecation warning. Use theHG_STORE_*names for new deployments.
4 Configuration
The main configuration file for Store is conf/application.yml. Here are the key configuration items:
For multi-node deployment, you need to modify the following configurations for each Store node:
grpc.port(RPC port) for each noderaft.address(Raft protocol port) for each nodeserver.port(REST port) for each nodeapp.data-path(data storage path) for each node
5 Start and Stop
5.1 Start Store
Ensure that the PD service is already started, then in the Store installation directory, execute:
The startup script supports a -d flag to control daemon mode:
-d true(default): run as a background daemon; the script returns immediately.-d false: run in foreground — the scriptexecs Java, so the container/supervisor process IS Java. Use this when running under Docker or a process supervisor (systemd, supervisord) so crashes are detected and the service is restarted automatically.
After successful startup, you can see logs similar to the following in logs/hugegraph-store-server.log:
5.2 Stop Store
In the Store installation directory, execute:
6 Multi-Node Deployment Example
Below is a configuration example for a three-node deployment:
6.1 Three-Node Configuration Reference
- 3 PD nodes
- raft ports: 8610, 8611, 8612
- rpc ports: 8686, 8687, 8688
- rest ports: 8620, 8621, 8622
- 3 Store nodes
- raft ports: 8510, 8511, 8512
- rpc ports: 8500, 8501, 8502
- rest ports: 8520, 8521, 8522
6.2 Store Node Configuration
For the three Store nodes, the main configuration differences are as follows:
Node A:
Node B:
Node C:
All nodes should point to the same PD cluster:
6.3 Docker Distributed Cluster Configuration
The distributed Store cluster definition is included in docker/docker-compose-3pd-3store-3server.yml. Each Store node gets its own hostname and environment variables:
Store nodes start only after all PD nodes pass healthchecks (/v1/health), enforced via depends_on: condition: service_healthy.
To view runtime logs for a running Store container use docker logs <container-name> (e.g. docker logs hg-store0).
See docker/README.md for the full setup guide.
7 Verify Store Service
Confirm that the Store service is running properly:
If it returns {"status":"UP"}, it indicates that the Store service has been successfully started.
You can also check Store node status through the PD API:
If Store is configured successfully, the response should include status information for the current node, and state: "Up" means the node is running normally.
The example below shows a single Store node. If all three nodes are configured correctly and running, the storeId list should contain three IDs, and stateCountMap.Up, numOfService, and numOfNormalService should all be 3.